Understanding Statistical Measures in Chapter 11
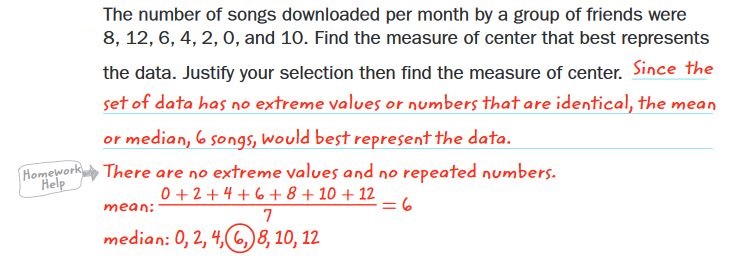
Chapter 11 in most introductory statistics textbooks covers descriptive measures that summarize and describe data sets. These are the foundational tools you use before you ever get to hypothesis testing or regression analysis. If you are working through this chapter, you are likely dealing with central tendency, dispersion, and positional measures. Here is how it actually works when you are trying to get through the problems. Having a reliable answer key matters because these problems compound errors quickly. A mistake in calculating the mean propagates into the variance, which then throws off the standard deviation and every derived value after that. I once spent forty minutes tracking down an error only to realize I had entered one data point wrong into my calculator during the initial setup. The workaround was to recalculate from scratch using a spreadsheet with explicit cell references so I could audit each step independently. The three most common measures of central tendency are the mean, median, and mode. The arithmetic mean is the sum of all observations divided by the count of observations. It is sensitive to outliers. If your data set contains extreme values, the mean shifts toward them, sometimes making it a misleading representation of where the data actually clusters.
The median is the middle value when the data is ordered from smallest to largest. When there is an even number of observations, you average the two middle values. This measure is robust against outliers, which is why it is often preferred for income data or housing prices where a few extreme values can distort the mean significantly. In practice, I have found that many students confuse when to use each measure. The rule of thumb is straightforward: use the mean for symmetric distributions and the median for skewed ones. The mode is simply the most frequently occurring value in a data set. A data set can be unimodal, bimodal, or multimodal. Some data sets have no mode at all if every value appears exactly once. Textbook problems often include a trick question where the data is uniformly distributed, and the correct answer is that there is no mode.
Measures of Dispersion
Range is the simplest measure of spread. It is calculated by subtracting the minimum value from the maximum value. It tells you the total span of the data but gives no information about how values are distributed within that span. Range is highly sensitive to outliers and provides limited insight on its own. Interquartile range, or IQR, is more informative. It measures the spread of the middle fifty percent of the data by subtracting the first quartile (Q1) from the third quartile (Q3). IQR is resistant to outliers because it ignores the extreme ends of the distribution. Most Chapter 11 problems require you to find quartiles before computing IQR, and this is where students commonly make mistakes in ordering and selecting the correct positions. Variance and standard deviation are the most widely used dispersion measures. Variance is the average of the squared deviations from the mean. Sample variance divides by n minus one, while population variance divides by n. The distinction between sample and population is not optional, and using the wrong divisor is one of the most frequent errors on exams. Standard deviation is the square root of variance, which brings the measure back to the original units of the data. This makes standard deviation more interpretable than variance in most practical contexts.
Get the Full Details

Positional Measures and Z-Scores
Percentiles and quartiles tell you the relative standing of a value within a data set. The p-th percentile is the value below which p percent of the observations fall. Quartiles are specific percentiles: Q1 is the 25th percentile, Q2 is the 50th percentile (which equals the median), and Q3 is the 75th percentile. There are several methods for calculating percentile positions, and different textbooks use slightly different formulas. Make sure you know which method your course requires. A z-score measures how many standard deviations a particular value lies from the mean. The formula is z equals x minus mu divided by sigma for a population, or z equals x minus x bar divided by s for a sample. Z-scores allow you to compare values from different data sets that have different units or scales. A z-score of negative 1.5 means the value is one and a half standard deviations below the mean. Values beyond positive or negative two are generally considered unusual in most introductory statistics courses, though this threshold varies by discipline.
Common Pitfalls and Edge Cases
One edge case that catches students off guard involves data sets with repeated values. When finding the median, some students incorrectly exclude duplicates from the count. All values count, including repeats. Another common issue arises when determining quartiles for small data sets. Different methods for locating Q1 and Q3 can produce slightly different results, and none of them is universally designated as correct outside of specific software conventions. I recommend sticking to the method your instructor teaches rather than mixing approaches. Grouped frequency distributions add another layer of complexity. When data is presented in class intervals rather than as raw scores, you must use the midpoint of each interval as a representative value. This introduces approximation error that does not exist with raw data. The computed mean and standard deviation from grouped data will never exactly match the values you would get from the original ungrouped data, and some textbook answers reflect this discrepancy. If your calculated value does not match the answer key exactly, check whether the problem uses grouped data before assuming you made a calculation error.
Working Through Problem Sets
The most effective approach is to work through each problem type systematically. Start with simpler data sets by hand to build familiarity with the mechanics, then move to larger data sets where you would typically use a calculator or statistical software. Organize your work with clear labels for each step. Write down which formula you are using, what each variable represents, and substitute the actual values before computing the result. This habit catches errors before they propagate through multiple steps. When using technology, verify that your device is set to the correct mode for sample versus population calculations. Graphing calculators and spreadsheet software often provide both options, and selecting the wrong one changes the denominator in the standard deviation formula. I learned this after consistently getting answers that were off by a small margin across multiple problem sets. The discrepancy was always caused by the sample versus population setting, never by a calculation error.
Interpreting Results
Getting the correct numerical answer is only part of the task. Most Chapter 11 problems ask you to interpret what the measure means in context. A well-written interpretation references the specific data set, names the measure being used, and explains what the value indicates about the distribution. For example, stating that the standard deviation is three point two centimeters is only useful when you also explain that most observations fall within roughly six centimeters of the mean in a roughly symmetric distribution. Skill's rule, which applies to mound-shaped symmetric distributions, states that approximately sixty-eight percent of data falls within one standard deviation of the mean, ninety-five percent within two standard deviations, and ninety-nine point seven percent within three standard deviations. This rule is frequently tested alongside measures of spread and provides a quick way to assess whether a distribution is approximately normal. It does not apply to skewed or multimodal distributions, and applying it outside its intended scope is another common mistake worth avoiding.
Answer Key Usage Strategy
Use an answer key as a diagnostic tool rather than a verification shortcut. Check your answer after completing each problem type, not after finishing the entire set. When your answer does not match, identify exactly which step diverged rather than simply copying the correct result. The learning happens in the debugging process, not in confirming that you got the right number. Spend more time on the problems you get wrong than on the ones you get right the first time. If your answer key provides only final numbers without showing work, supplement it with worked examples from your textbook or trusted online resources. Many students rely exclusively on their answer key and miss the procedural steps that lead to the result. Understanding the procedure is what prepares you for exam conditions where no answer key is available.
Limitations of Standard Descriptive Measures
Descriptive statistical measures have well-defined boundaries where they break down or become misleading. They summarize only a single data set and cannot establish causal relationships. Two distributions can have identical means and standard deviations while looking completely different from each other. Anscombe's quartet is the classic demonstration of this fact, and it should make you cautious about relying on numerical summaries alone without examining graphical representations of your data. Small data sets produce unstable estimates of standard deviation and variance. With fewer than ten observations, a single outlier can change the standard deviation by fifty percent or more. In these cases, reporting the raw data alongside summary statistics is more honest than presenting measures that give a false impression of precision. When your sample is this small, consider using the interquartile range or reporting the range instead of the standard deviation, since those measures are less affected by individual extreme values in limited data. The answer key for Chapter 11 should serve as a reference point in your study process, not a replacement for working through the calculations yourself. The measures covered here form the basis for nearly every advanced topic in the course, so investing time in understanding them thoroughly now will save significant effort later when you move into probability distributions and inferential statistics.