Getting and Using a Million Digits of Pi
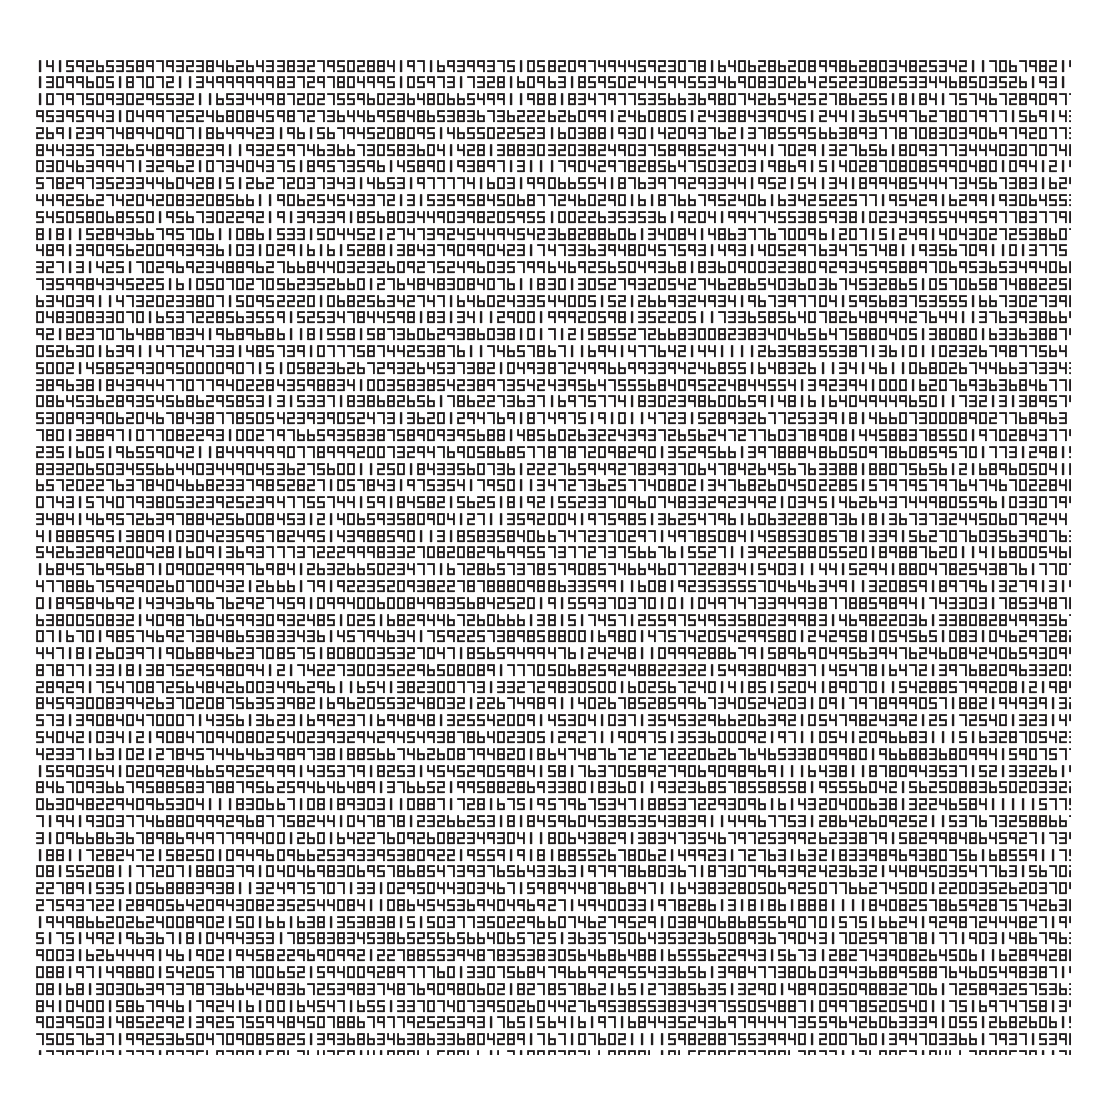
The straightforward answer is that 1 Million Digits Of Pi is exactly what it sounds like: the decimal expansion of the mathematical constant , computed to one million places past the decimal point. The value starts 3.1415926535... and continues without repeating or terminating. Most people don't actually need this much precision for anything real. But sometimes you do, or someone asks you to provide it, or you're benchmarking a computation pipeline. Here is how the whole thing works in practice. You can grab a clean text file of a million digits from a few reliable sources. The most common starting point is the Pi-Search Page maintained by researchers who track and host computed digits, or simply search for "million digits of pi txt" and look for a raw file from .edu or .org domains. Reputable archives exist, including the one maintained by the Canadian mathematician who published early billion-digit results decades ago. I usually just download from the standard pi-world lists and verify the checksum after. The file itself is typically a single line containing the integer 3 followed by a decimal point and roughly one million digit characters. Nothing fancy. No commas. No line breaks in the middle of the number unless the source deliberately adds them for readability. A raw one-million-digit file usually sits around 1 megabyte on disk because each digit takes one byte as ASCII. That is trivial by modern storage standards.
How Pi Is Actually Computed
If you are thinking about generating these digits yourself rather than downloading them, you need to understand the algorithms involved. The most common modern approach uses the Chudnovsky algorithm, which converges extremely fast. Each iteration produces roughly 14 additional correct digits. That means reaching one million digits requires only around 72,000 iterations. It sounds like a lot, but the arithmetic is dominated by big-number multiplication and division, and those operations are well-understood and highly optimized. The plouffe–bellard algorithm is another option, notable because it allows direct extraction of specific hexadecimal digits without computing all the preceding ones. That property is useful for spot-checking or verifying individual digit positions. For a full million digits, though, the Chudnovsky method remains the standard choice in most high-precision computation libraries. Programs like y-cruncher implement this and can compute millions or even billions of digits on a consumer desktop in reasonable time. I have run y-cruncher on a machine with 64 gigabytes of RAM and seen it compute one million digits in under two minutes. The bottleneck is usually memory bandwidth, not raw CPU speed.
Practical Problems You Will Encounter
One specific issue I ran into last year while generating and verifying a large set of pi digits involved endianness and digit grouping. I was writing a verification script that split the million-digit string into chunks of 10,000 digits and compared each chunk against an independently computed reference. The script kept failing at chunk 87. I spent about forty minutes debugging before I realized the reference data used a different line-break convention. The digits themselves were identical, but the chunking boundaries were off by one position because the reference file had a newline character inserted every 10,000 digits and my generated file did not. The fix was simple: strip all whitespace and newlines from both files before splitting. That is a quiet, boring bug that will bite you if you assume file formatting is consistent across sources. Another edge case involves precision libraries. If you use Python's Decimal module or a similar arbitrary-precision library with an insufficient context precision setting, the computation will silently return incorrect digits past the configured limit. I set the precision context to 1,000,001 instead of 1,000,000 because the leading "3." counts toward the precision budget in some libraries. Miss that detail and your last several thousand digits will be garbage, and you will not know it without explicit verification.
Get the Full Details

Verification and Spot-Checking
Downloading precomputed digits is fine, but trusting them without verification is a mistake. The standard approach is to compute a subset of digits independently and compare. You can use the BBP-type formula to compute arbitrary hexadecimal digits at specific positions and then convert those hex digits to decimal. This does not give you the full million digits, but it gives you enough checkpoints to be confident the file is correct. I typically verify positions 100,000, 250,000, 500,000, 750,000, and 999,999. If those match known values, the rest of the sequence is almost certainly correct. There are published digit lists available online that serve as reference points. Sites hosting pi digit data often provide checksums or hash values for their files. Compare your downloaded file against those hashes. An MD5 or SHA-256 match tells you the file is bit-for-bit identical to the source, which is about as good as verification gets for this kind of work.
Common Pitfalls and What Not to Do
A frequent mistake is trying to compute pi digits using floating-point arithmetic. Double-precision floats cap out around 15 to 17 decimal digits of accuracy. If you use a standard math library with float or double types and loop some series, you will get garbage well before you reach one million digits. You need arbitrary-precision integer or decimal arithmetic throughout. Libraries like GMP (GNU Multiple Precision), MPFR, or Python's built-in Decimal module handle this. Do not attempt to chain together standard float operations and expect correctness past the twentieth digit or so. Another pitfall is assuming that more CPU cores linearly reduce computation time. The Chudnovsky algorithm parallelizes well across cores for the big-number multiplications, but the overhead and synchronization costs mean you do not get perfect scaling. On my setup, moving from 4 cores to 16 cores cut computation time roughly in half rather than by a factor of four. Memory allocation and garbage collection also become factors on larger jobs. If you are pushing into the hundreds of millions or billions of digits, memory management becomes a serious concern.
When One Million Digits Is Not Enough
Sometimes people ask for a million digits when they actually need far more, or they need a specific range in the middle of the expansion. If you need digits beyond the first million, generating a fresh file each time is wasteful. It is better to build a single larger computation and then slice out the range you need. Similarly, if you only need a few hundred thousand digits, computing a million is unnecessary work. There is no shame in stopping early, but you should still verify whatever range you output. For most practical applications, far fewer digits suffice. Engineers rarely need more than a few hundred digits for physical calculations. Mathematicians working in number theory may want millions for statistical analysis of digit distribution. Cryptographers do not use pi digits for security because pi is a public constant, not a secret. The distribution of digits in pi is believed to be normal, meaning each digit 0 through 9 appears with roughly equal frequency in the long run, but that property has never been proven. Testing it against a million digits is straightforward and usually confirms the expected distribution within statistical noise.

Final Notes on the 1 Million Digits Of Pi File
If you just need the file, search for the standard downloads from established pi computation archives. Verify the checksum. Strip whitespace before processing. Set your arbitrary-precision context one digit above your target to account for the integer part. Spot-check a few positions with an independent method. That is the whole process. The digits themselves are fixed and well-studied. The difficulty is never in the math, it is in the engineering around getting the computation right and confirming the output is correct.