Why Most Recovery Plans Die in the First 48 Hours
I spent eight years on call for production outages. Some of them were recoveries. Most of them were not recoveries at all—they were fires people lit because nobody knew what they were doing until it burned down. The principles below came from watching bad recoveries and, occasionally, surviving good ones. They are not theoretical. They are what separate a team that regains service from a team that regains service and also loses their job in the process.
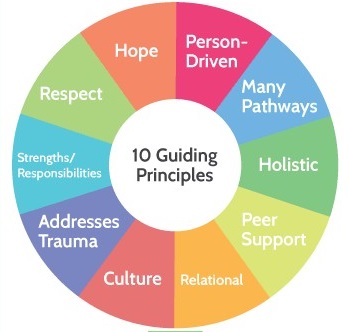
The 10 Guiding Principles Of Recovery Nobody Talks About Until It Is Too Late
Principle 1: Assume You Are Already In A Recovery
The moment you detect an anomaly, treat it as a recovery situation until you prove otherwise. This sounds obvious. It is not. Most people sit on alerts for twenty minutes wondering if it is a false positive while the blast radius doubles. I once watched a team ignore a disk I/O spike because "it might be normal." It was not normal. It was a full RAID rebuild that crushed latency. By the time they escalated, the customer-facing API had timed out across three regions. The fix was not hard. The decision to wait was.
Principle 2: Name The Blast Radius Before You Touch Anything
Before you run a single command, define what is broken, what is still working, and what you are willing to lose. Write it down. A short message in Slack counts. If you do not do this, you will start fixing the wrong thing. There is a reason we use terms like RTO and RPO. They force you to admit what you can tolerate. Most recovery failures happen because nobody admitted how much data loss was acceptable until after the backup restore finished and everyone realized they had restored yesterday's data into today's mess.
Get the Full Details
Principle 3: Stop The Bleeding Before You Treat The Wound
Containment comes first. Isolation. Throttle. Redirect traffic. Disable the feature. Shut off the database connection. Do not attempt root cause analysis while the system is still actively degrading. I remember a rollout where the team tried to debug a memory leak in production while traffic continued spiking. They were rewriting SQL queries in real time. It made everything worse. We isolated the bad service, sent traffic to the fallback, and diagnosed it after the site stabilized. Five minutes of containment would have saved two hours of panic.
Principle 4: One Person Calls The Shots, Everyone Else Executes
Multiple voices during a recovery is how you get conflicting commands. Designate one incident commander before the fire. If you did not pre-designate, volunteer yourself if you are the most experienced person in the room who can stay calm. Not the loudest. The calmest. Once the commander is identified, questions go to them. Answers come from them. This is not about ego. It is about reducing decision latency. Every second spent debating the approach is a second the outage stretches.
Principle 5: Your Runbook Is A Starting Point, Not A Script
Runbooks exist. They are usually outdated. The correct move is to treat them as a rough map and adapt to the actual state of the system. Never follow a runbook blindly. Never abandon one entirely either. I saw a team run through a forty-step disaster recovery runbook line by line during a cascading failure. Step twelve was irrelevant to their situation. Step thirty-seven caused a secondary outage because it assumed a different topology. They would have been faster to ignore the book and think.
Principle 6: Recover In The Smallest Safe Increment
Make one change. Observe. Then make the next. Rolling back a single change is manageable. Rolling back a pile of changes made at 2 AM while exhausted is a nightmare nobody wants to face. This applies to configuration, code, and infrastructure. I once rolled out a batch of ten Kubernetes patches during a recovery window. Half of them were unnecessary. The other half fought each other. We undid everything and started over. Took two hours. It could have been twenty minutes if we had shipped one at a time.
Principle 7: Communicate Up, Down, And Sideways Simultaneously
Leadership needs status. Engineers need technical detail. Customers need acknowledgment. These are three different messages. Send all three. Use different channels if needed. Do not assume one update covers everyone. When I was on call, the worst frustration was silence from management while engineers were swarming. Leadership felt abandoned. The engineering war room felt ignored. A single status page update every fifteen minutes solved both problems.
Principle 8: Assume The Backup Will Not Work Until You Prove It
Backups are a belief system. Regular restores are the evidence. Test your recovery path before you need it. Verify the backup integrity. Check the restore procedure. Confirm the data lands where it should. I encountered a case where the backup was valid, the key was valid, and the restore completed successfully—and the restored database had a corrupted schema due to a migration that ran two days before the backup window. The backup was fine. The data inside it was wrong. Only a schema validation step caught it.

Principle 9: Document The Recovery As It Happens, Not After
Post-incident reports written later are incomplete. Someone forgets a command. Another person misremembers the timeline. The truth decays within hours. Keep a live document open. Log decisions, timestamps, and outcomes as they occur. A timer on a shared doc is enough. I used a simple Google Doc during incidents. One person updated it in real time. The postmortem became a transcription exercise instead of a memory reconstruction exercise. Huge difference in accuracy.
Principle 10: The Recovery Is Not Over When Service Returns
Restoring service is step one. Verifying correctness is step two. Preventing recurrence is step three. Most teams stop at step one and call it a win. That is how the same bug shows up again in three months. After a major recovery, I always require a follow-up window within forty-eight hours. Something always surfaces then. A hidden replication lag. A secondary failure mode. A customer complaint that was queued before the status page update.
What Actually Breaks Under Pressure
People break. Tools break. Assumptions break. The hardest part of recovery is rarely the technology. It is the human layer. Fatigue causes bad judgment. Stress causes tunnel vision. Panic causes irreversible actions. I have seen engineers SSH into production databases and drop tables because the playbooks pointed to the wrong environment variable name. The fix was a typo. The cost was a two-hour outage. This is why checking your target before executing matters more than speed.
When These Principles Fail You
They are not a silver bullet. If your infrastructure has no observability, no redundancy, and no tested backups, no amount of principled recovery will save you. The principles organize chaos. They do not create resilience from nothing. If your team is understaffed and on-call rotation has not been enforced, you will burn out regardless of how well you follow these. Recovery principles assume a team that exists, is reachable, and has authorization to act. If any of those are missing, fix those first.
A Real Edge Case I Dealt With
Once, a DNS propagation delay made it look like a region was fully down when it was actually just unreachable from certain resolvers. We spent forty-five minutes attempting a recovery that was not needed. The blast radius was a misunderstanding caused by relying on internal monitoring exclusively. The workaround was switching to an external health check service and cross-referencing it with internal metrics before escalating. External probes confirmed the region was healthy. Internal tools were seeing stale routes. One source of truth was wrong. The other was right. The recovery was cancelled. Forty-five minutes of our lives we will never get back.
What To Do Today Instead Of Waiting
Write your incident commander designation. Verify your last backup restore. Update your runbook or admit it needs one. Set up external monitoring if you do not have it. These take less time than you think and will save more time than you can imagine. Recovery is not a skill you develop during a crisis. It is a habit you maintain when nothing is on fire. The principles above work only if you have already done the boring work. There is no shortcut around that.