What You're Actually Dealing With
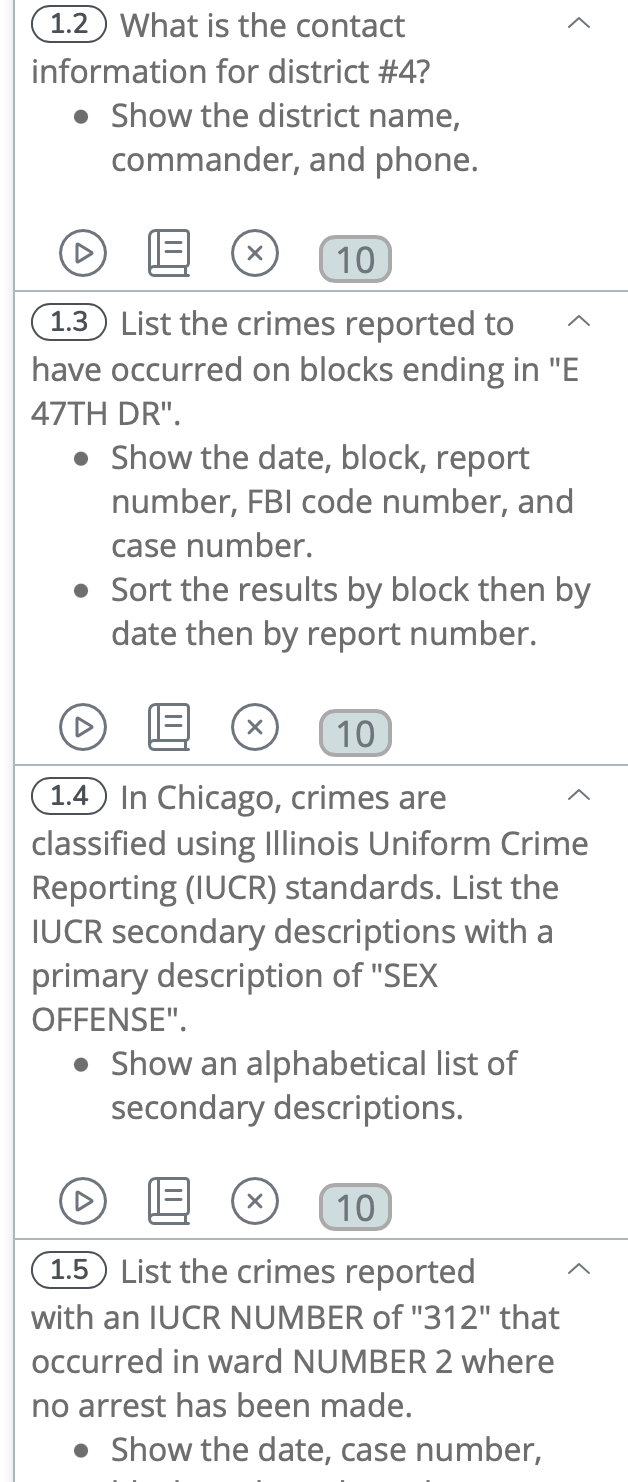
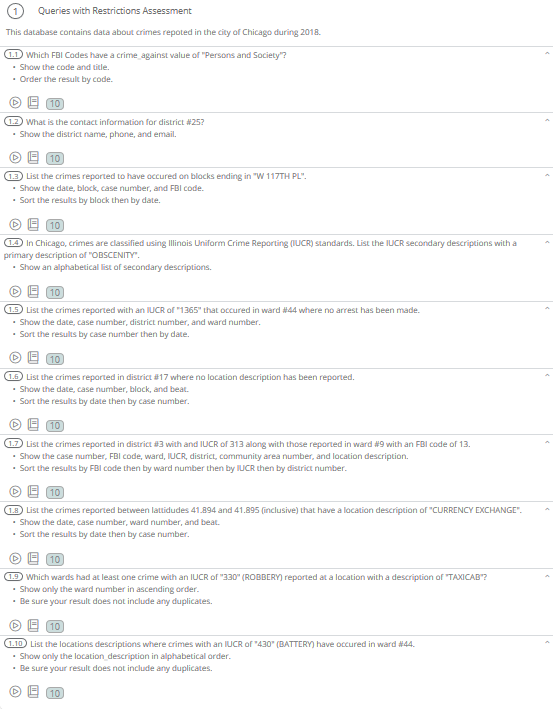
The 1311 Queries With Restrictions Assessment is a timed evaluation you'll encounter if you're applying for backend engineering, data engineering, or platform roles at mid-to-large tech companies. It tests your ability to construct SQL queries that satisfy multiple layered constraints — things like date range filters, joins across five or more tables, aggregation with nested subqueries, and edge cases around NULL handling and duplicate records. I've seen candidates breeze through the first half and then implode on question nine. The tricks aren't in the basic syntax. They're in the details that nobody remembers until they're stuck under a timer.
How the 1311 Queries With Restrictions Assessment Actually Works
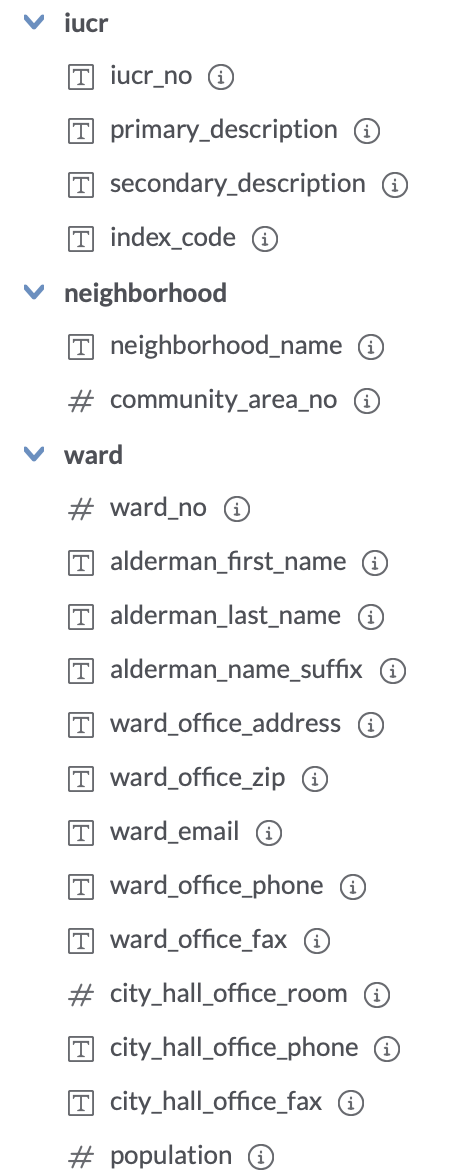
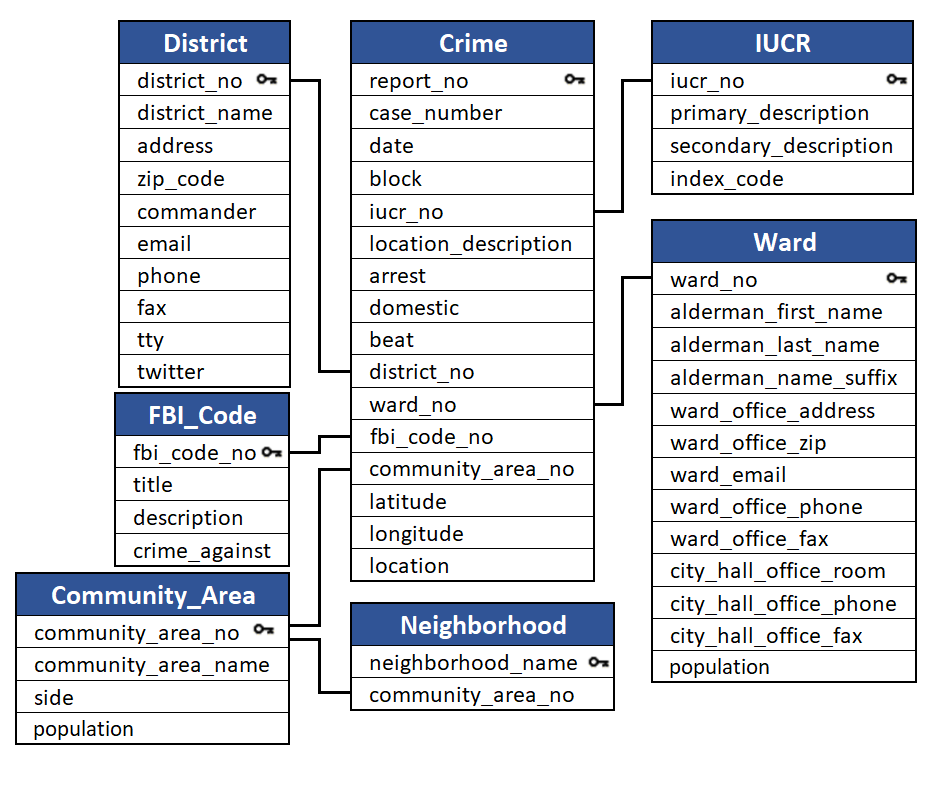
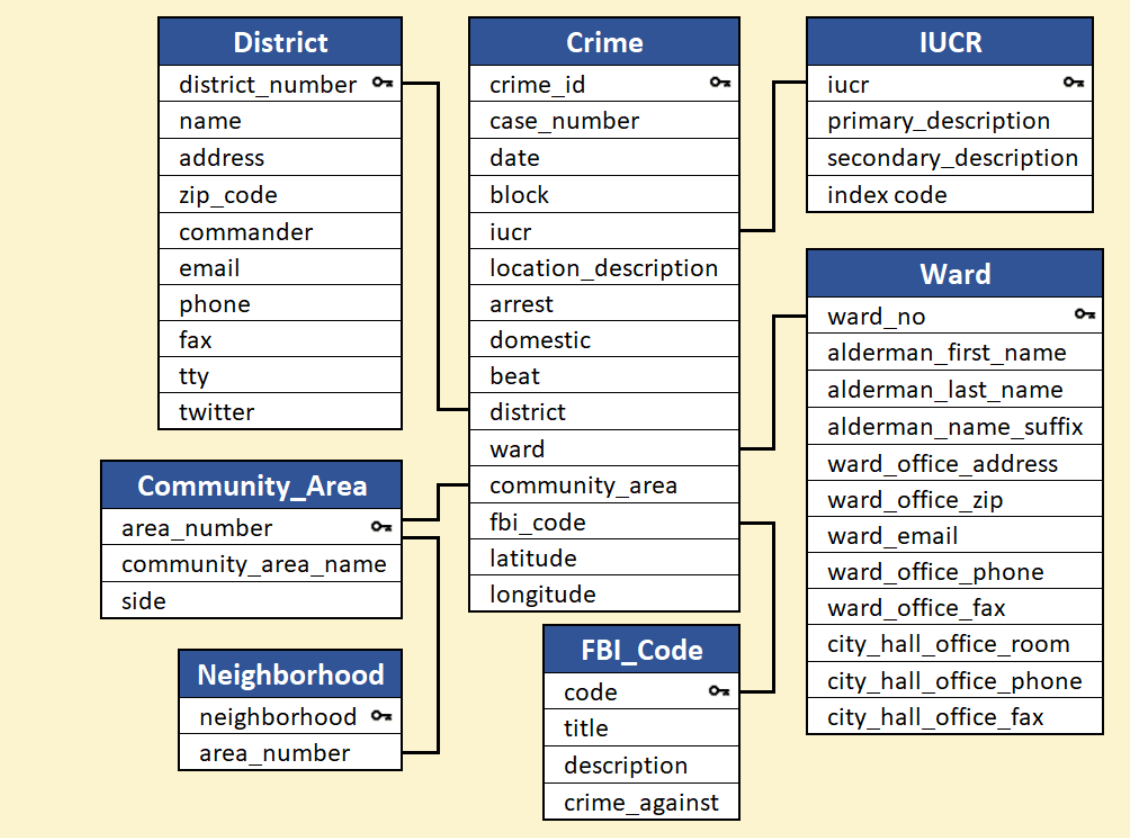
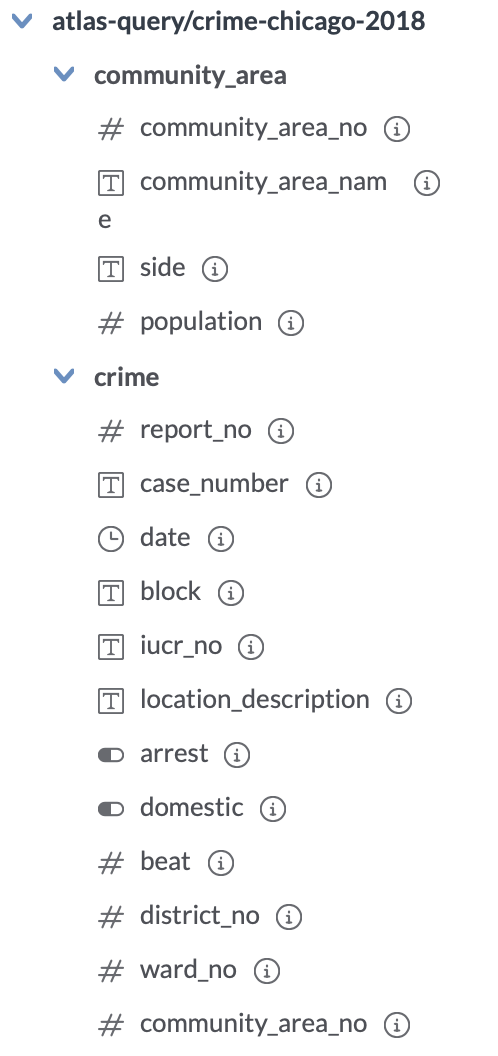
The platform gives you a normalized schema description upfront — usually six to ten tables with their columns and key relationships laid out in a visual or text diagram. Then you get between 8 and 12 questions. Each question has strict requirements: specific output columns, exact ordering, sometimes a particular join type called for. The "restrictions" part is where people trip up. A question might say "return active users who made purchases in the last 90 days but haven't contacted support" — that's three conditions that interact in ways that feel deceptively simple. You're working against a clock, typically 45 to 60 minutes total. The platform validates your queries against hidden test cases, so even if your query runs locally and looks correct, it can still fail if you're not matching exact column names, returning extra columns, or using a join that produces unexpected duplicates. Here's a thing most guides won't tell you: the schema diagrams are intentionally slightly incomplete. They'll show you the primary keys and obvious foreign keys but leave some relationship paths ambiguous. You're expected to infer the join conditions from context. I once spent six minutes on a single question trying to figure out whether to join on user_id or customer_ref because the diagram labeled them differently in each table. The test was specifically checking whether I'd try both and verify which one actually linked the data.
Breaking Down the Question Types
There are roughly four categories you'll run into, and they appear in a fairly predictable order of increasing difficulty. The first batch is straightforward filtering and sorting. Basic SELECT statements with WHERE clauses, maybe a GROUP BY, ORDER BY limiting to the top N results. These are free points if you know your syntax. Don't rush them though — rushing is how you miss a case sensitivity requirement or forget to alias a column the way the grader expects. The second tier introduces JOINs, usually two or three tables. You'll need INNER JOIN, sometimes LEFT JOIN. This is where I lost points on my first attempt. The question asked for all orders and their associated customers, including orders with no matching customer record. I wrote an INNER JOIN because that's what felt natural for "matching data." It returned zero results for the edge cases. A LEFT JOIN was the correct answer. The question gave you the hint with "including orders with no matching customer" but people read past that stuff when they're nervous.
Get the Full Details
The third tier brings in subqueries and CTEs. Aggregate functions with HAVING clauses. Correlated subqueries. Questions like "find the department with the highest average salary that also has at least three employees earning above the company-wide median." That requires understanding nested logic, not just syntax you can memorize. The final tier is the one that separates people who've done this before from people who haven't. Window functions, recursive CTEs, handling NULLs intentionally, and queries that need to be written in a specific dialect. Some assessments run against PostgreSQL, some against MySQL, some against SQLite. The difference between COUNT(*) and COUNT(column_name) matters enormously when NULLs are in play. PostgreSQL treats certain edge cases differently than MySQL does.
My Approach to Tackling Each Question
I read the full question first, including every single constraint, before looking at the schema. There's a tendency to immediately start matching keywords to column names, but that leads to shallow reading. You need to know what the output should look like before you write a single line of SQL. Then I sketch the answer on paper or in a text editor. Not the full query — just the structure. What tables do I need? What's the main filter? Are there subqueries or CTEs required? This takes maybe thirty seconds per question but saves you from writing something and then realizing halfway through that you missed a constraint. When you start typing, write the FROM and JOIN clauses first. Get your table relationships right before you add any WHERE conditions. I've watched people write complex WHERE clauses and then realize they were joining the wrong tables or missing a join entirely. Fixing the structure after you've built the filtering logic is much slower and more frustrating.
For aggregation questions, write the GROUP BY first. If you're grouping by something and then filtering on that aggregate, that filter goes in HAVING, not WHERE. This is almost always tested and almost always tripped up. One practical tip that comes from real experience: if a question mentions "excluding" something, think about whether NOT EXISTS, NOT IN, or a LEFT JOIN with a NULL check is the right approach. Each has different behavior with NULL values. NOT IN will return no rows if the subquery contains even a single NULL. That caught me on a problem involving user preferences where some preference fields were nullable. Switching to NOT EXISTS fixed it immediately.
Common Pitfalls That Tank Scores
Column ordering matters. If the question asks for name, email, signup_date, the grader checks the output column sequence. name, signup_date, email fails even if the data is correct. Always match the requested column order exactly. Extra columns are worse than missing columns. Returning five columns when four are asked for often triggers a validation failure. If you're building a query with multiple JOINs, make sure you're only selecting the columns the question asks for, not every column from every table. Duplicate handling is another silent killer. If a question asks for distinct results and you forget DISTINCT, or if a JOIN creates duplicate rows and you don't account for it, your aggregations will be wrong. Running totals, averages, and counts all explode with duplicates.
Date filtering is where dialect differences bite hardest. PostgreSQL uses INTERVAL for date arithmetic. MySQL uses DATE_SUB or simple subtraction. If you're practicing without knowing which dialect you'll face, learn both patterns. I always write my practice queries in PostgreSQL syntax and then test them against a MySQL instance when I can to catch incompatibilities early. Another thing nobody emphasizes enough: the performance of your query doesn't usually matter for scoring, but inefficient queries can time out in longer assessments. A query that cross-joins two large tables and then filters afterward will run, but it might exceed the execution timeout. Use EXISTS or JOIN with explicit conditions rather than scanning entire tables.
How to Prepare Specifically for This Assessment
Practice with a schema, not just random SQL problems. Most online resources give you exercises with no context about the underlying data model. The 1311 Queries With Restrictions Assessment requires you to navigate an unfamiliar schema quickly. Build your own practice scenarios with seven or eight interconnected tables and write questions that mirror the types above. Time yourself. Thirty to forty-five minutes is your target for a full set. I created a practice set using a simplified e-commerce schema with users, orders, order_items, products, categories, payments, and reviews. I wrote questions covering every difficulty tier and timed each one. The hardest question I built involved finding products that had never been purchased by users who signed up in Q4 2023, grouped by category, ordered by the number of unpurchased products descending. That single question took me twelve minutes on the first attempt and five minutes by the fifth. Speed comes from pattern recognition, and pattern recognition comes from repetition. Learn to read schema diagrams fast. In the assessment, you'll have maybe two minutes to understand the entire data model before the questions start testing you. Practice looking at a diagram and immediately identifying the main entity, the relationship paths, and any potential ambiguity in foreign key naming.
When This Assessment Type Falls Short
The 1311 Queries With Restrictions Assessment measures a narrow skill set well — writing SQL under constraints — but it doesn't reflect real work. In production, you'd have access to query explain plans, you'd test against realistic data volumes, you'd write migrations, and you'd collaborate with product managers about what "active user" actually means. This test checks syntax and logic under time pressure, which is useful but incomplete. If you're preparing for it, treat it as a specific exercise, not a definitive measure of your engineering ability. For most of the questions, the skills transfer directly. The schema navigation, the constraint parsing, the careful attention to output format — all of that is genuine work skill. The artificial time pressure and the hidden test case validation are the parts that exist purely for screening purposes. Don't let the format make you doubt your actual capability with real databases. Focus on speed, accuracy on the fundamentals, and careful reading of each constraint. That's what separates people who pass from people who don't.