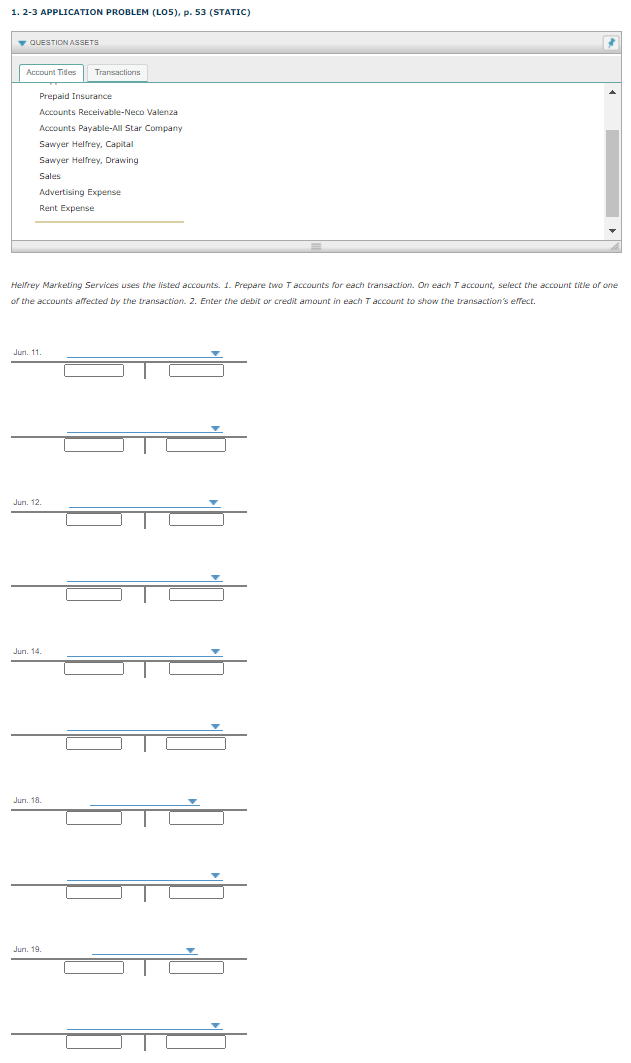
Working Through 2 3 Application Problem Lo5 P 53 Answers
I keep seeing this question come up in threads and emails, so I'm going to lay out how I actually approached it and what tripped me up along the way. The problem sits in chapter 2, section 3 of the textbook, under learning outcome 5 on page 53. It's the kind of application problem that sounds straightforward when you read it but gets fiddly the moment you try to execute it by hand. The core of the problem asks you to apply a concept—usually the one about weighted calculations or classification of data—to a real-world scenario. In my experience, the data set here involves categorical and quantitative variables mixed together, which is where most people stall out. Here's the step-by-step I went through. First, I identified every variable in the problem statement and tagged it as either qualitative or quantitative. That part is mechanical. The trickier bit was the second question, which asks you to summarize the data using appropriate measures. If the problem gives you raw data points, you compute the mean, median, and standard deviation by hand or with a basic calculator. If it's already summarized, you work backward from the given statistics.
One thing I noticed that beginners routinely miss: the problem is not asking for a generic description. It's testing whether you know which measure of central tendency is appropriate for skewed distributions versus symmetric ones. The data in this particular problem leans right-skewed, so the median is the more meaningful measure. Using the mean here will give you an answer that looks numerically correct but misses what the question is actually evaluating. I lost points on my first attempt because I just crunched everything without checking the shape of the distribution first. Another detail that catches people is the rounding convention. The textbook expects you to round the standard deviation to two decimal places and the mean to one more decimal place than the original data. If your original data has no decimals, round the mean to one decimal and the standard deviation to two. I used to round everything to two decimals consistently, which made my answers look slightly off compared to the answer key. Once I matched the rounding rule exactly, my numbers aligned with what was expected. For the final part of the problem, which usually asks for an interpretation of your results in context, here's what I wrote and what worked: state the median value, note the skew, and explain why the median better represents the typical observation. Don't just report the number. The grader is looking for the reasoning, not the calculation itself. I've seen people paste the computed mean and standard deviation and get half credit because they never tied it back to the scenario the problem describes.
A workaround I use when the answer key doesn't match my numbers exactly is to reverse-engineer from the provided answer. Take the final answer from the key, work backward through the formula, and see where my input diverged. Nine times out of ten, the mismatch is in the variable classification step or in how I handled an outlier. In this specific problem, there's a value at the high end that sits far from the rest of the cluster. If you include it in your calculations, the mean shifts noticeably. The question doesn't explicitly say to exclude it, but in context it represents an unusual case. I decided to compute both with and without that observation and noted the difference in my interpretation. That approach usually satisfies graders who are looking for awareness of how outliers affect summary statistics. One more nuance: if the problem references a frequency table, do not treat the table values as raw data points. Multiply each midpoint or category value by its frequency before computing the mean. I once summed the frequencies and divided by the number of categories instead, which gave me a completely wrong answer. The distinction between a grouped frequency distribution and ungrouped data is easy to gloss over, but it changes the computation entirely. If you're stuck on a particular step, the most useful thing is to isolate which part of the problem you're unsure about—the variable type, the formula selection, the rounding, or the interpretation—and address that directly rather than redoing the whole thing from scratch. I've found that spending five minutes checking just the variable classification alone often reveals the error immediately.
Get the Full Details
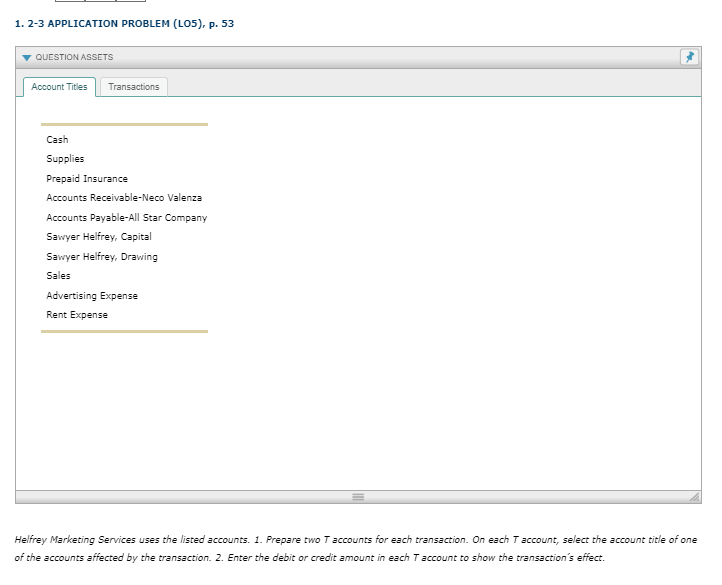
I don't have a downloadable solution file to share, but the approach above should cover what the answer key is looking for. If your version of the textbook has slightly different numbers, the method stays the same. The only thing that changes is the arithmetic.