Scatter Plots and Regression Lines: A Practical Guide
I spent years grading these worksheets, and honestly they're one of the more straightforward topics in introductory statistics if you take it one step at a time. The core idea is simple enough. You have paired data points — something like hours studied versus test scores — and you want to see if there's a pattern. Plot them on graph paper or in a spreadsheet. Draw a line that represents the trend. Calculate where that line crosses the y-axis and how steep it is. Most students rush through the plotting part and then get stuck on the math. Don't do that. Take your time with the scatter plot. If the points look random, no amount of algebra will save you. A visible trend should be obvious before you touch a single formula. If you can't draw a rough line by eye that roughly fits the cloud of dots, your data probably doesn't warrant a regression analysis in the first place.
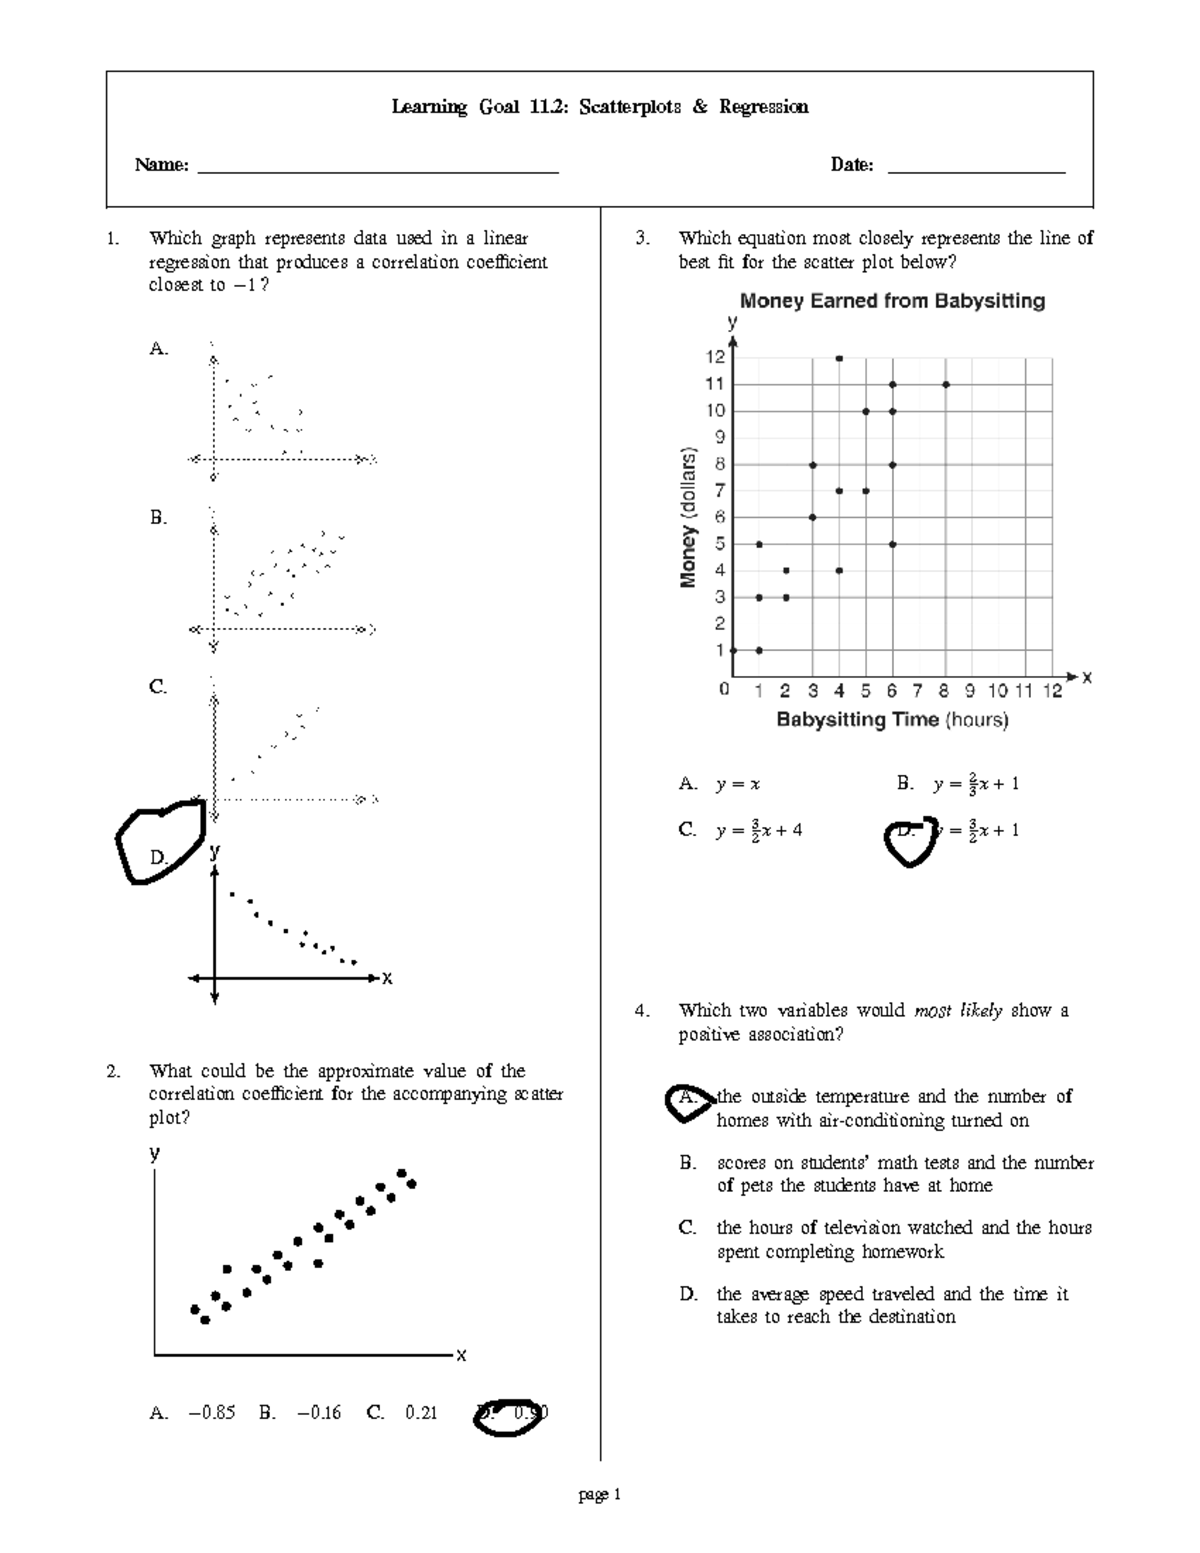
2 5 Skills Practice Scatter Plots And Lines Of Regression
When you're working through the practice problems, here's the actual procedure. First, organize your data into an x column and a y column. You need the sum of x, the sum of y, the sum of x times y, the sum of x squared, and the sum of y squared. That's five totals. Write them out clearly. I can't count how many times I saw students combine two rows incorrectly or drop a negative sign and spend twenty minutes wondering why their slope came out wrong. The slope formula is n times the sum of xy minus the sum of x times the sum of y, all divided by n times the sum of x squared minus the sum of x squared. Then the y-intercept is the mean of y minus the slope times the mean of x. It sounds intimidating on paper but it's just arithmetic once you have your five sums correct. Here's a quick walkthrough with real numbers. Let's say you have five data points: (1, 2), (2, 4), (3, 5), (4, 4), and (5, 5). The sum of x is 15. The sum of y is 20. The sum of xy is 69. The sum of x squared is 55. The sum of y squared is 90. Plugging into the slope formula: 5 times 69 minus 15 times 20 gives you 345 minus 300, which is 45. The denominator is 5 times 55 minus 225, which equals 275 minus 225, or 50. So the slope is 45 divided by 50, which is 0.9. The mean of y is 4 and the mean of x is 3. The intercept is 4 minus 0.9 times 3, which gives you 1.3. Your equation is y equals 0.9x plus 1.3.
The correlation coefficient r tells you how tight the fit is. It's the same numerator as the slope formula divided by the square root of n times sum of x squared minus the sum of x squared, all times n times sum of y squared minus the sum of y squared. In this example that works out to roughly 0.86, which is a decent positive correlation but not a strong one. Don't confuse a high r value with causation. That mistake shows up on exams constantly. One edge case that trips people up involves outliers. I had a student once who had four points clustered tightly around a clear positive trend and one point way off in the lower right. The regression line shifted dramatically because of that single outlier. She didn't realize it until we plotted the data first. The fix was straightforward — identify the outlier, check if it's a data entry error, and if it's legitimate, consider running the regression both with and without it and reporting both results. Some textbooks tell you to just delete outliers. That's bad advice. Document what you did and why. Another thing beginners miss: the regression line only works within the range of your data. Extrapolating beyond your smallest or largest x value is where things fall apart. I've seen students use a line derived from data ranging from 1 to 10 to predict values at x equals 50. The linear relationship might hold for a while and then break completely. There's no way to know from the math alone whether your line is still valid outside the observed range.
Get the Full Details

Residuals matter more than the r value alone. A residual is the vertical distance between an actual data point and the predicted value on the line. If you plot the residuals and see a curved pattern instead of random scatter, your linear model is the wrong choice. The data might follow a curve, and forcing a straight line through it gives you misleading predictions. This happens more often than you'd think with real world data. If you're looking for practice material, search for "2 5 Skills Practice Scatter Plots And Lines Of Regression" and you'll find several worksheet PDFs from educational publishers and teacher resource sites. The standard ones from publishers like Pearson or Kuta Software have between ten and fifteen problems each, covering everything from basic plotting to calculating the line of best fit and interpreting the slope and intercept in context. Some include calculator steps for TI-84 and Desmos users. Using technology speeds things up significantly. A TI-84 takes about thirty seconds to spit out the regression equation once you've entered the data. Desmos does it even faster and renders the scatter plot and line simultaneously. But don't rely on the calculator blindly. Always check that the output makes sense. If the slope has the wrong sign or the intercept is wildly off, you entered the data incorrectly or selected the wrong regression type. Linear regression assumes a straight line. Your calculator won't warn you if the data clearly curves.
The biggest limitation of these worksheets is that they use clean, made-up data. Real data is messy. Variables interact. There's measurement error. The line of best fit is a simplification, and sometimes a useful one, but it's not the whole story. If you're doing this for a stats class, you'll be fine. If you're planning to use regression in actual research or business, you'll need to learn about multiple regression, assumption checking, and confidence intervals next. One final note on interpretation. The slope tells you the average change in y for each one-unit increase in x. The intercept tells you the predicted value of y when x is zero, but that prediction is only meaningful if x equals zero is within your data range or makes logical sense. If your x values start at 5 and go to 50, the intercept is just a mathematical artifact with no real-world meaning. Don't pretend otherwise.