The Number Two Across Languages
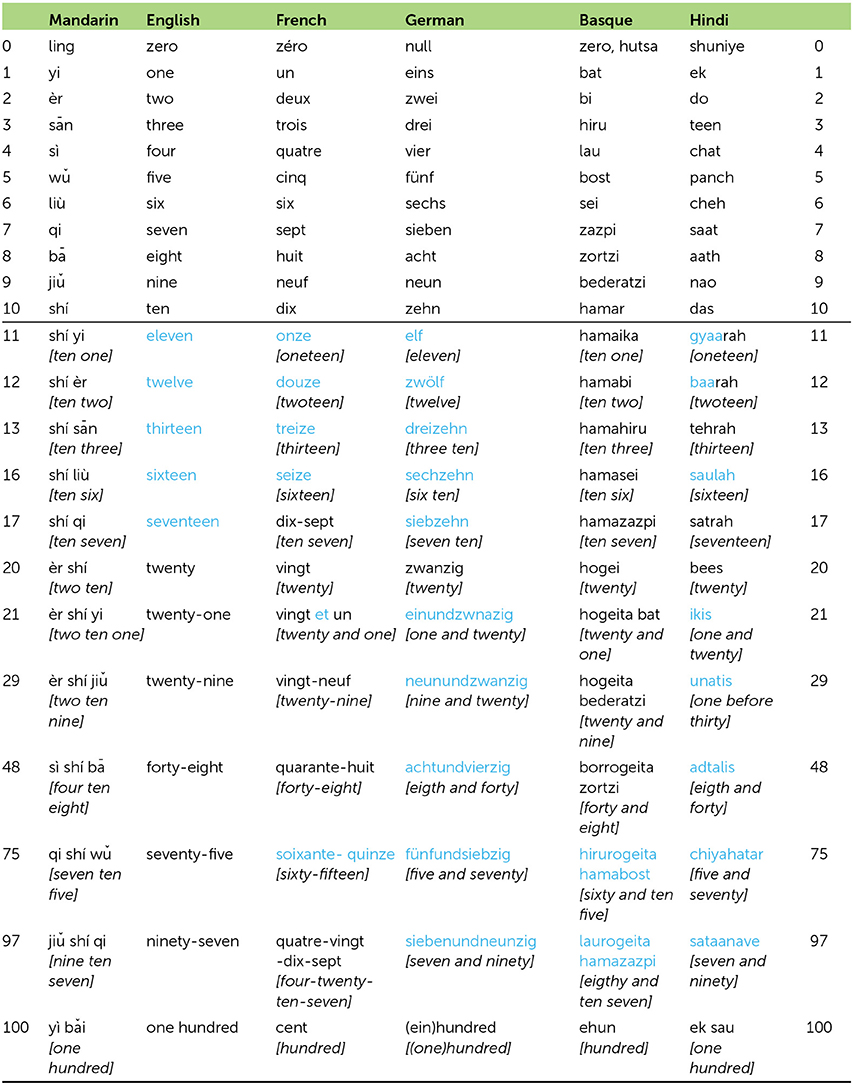
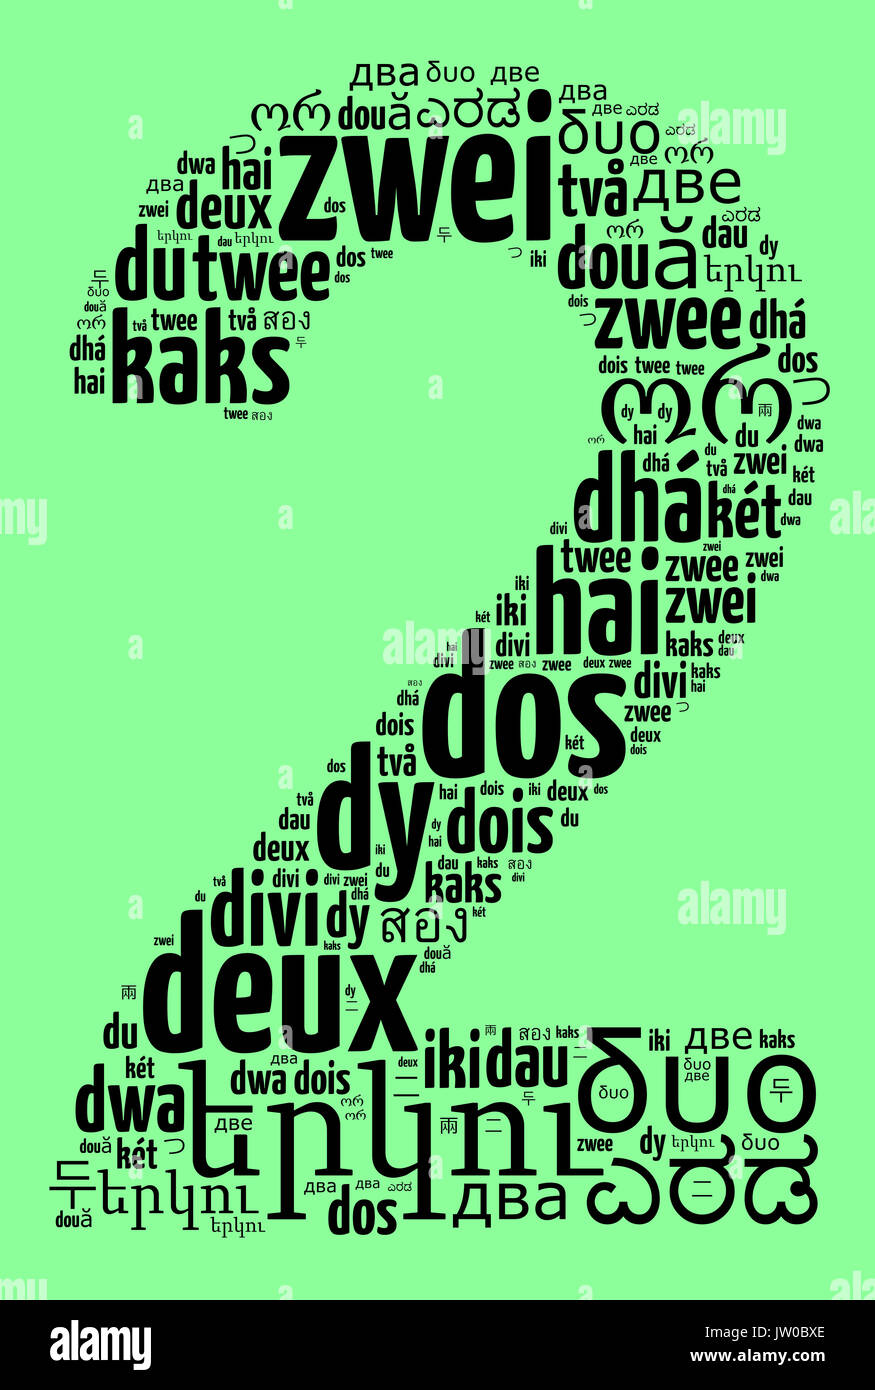
The number 2 appears in a surprising number of forms once you start looking at it outside English. Most people know "dos" in Spanish and "deux" in French, but the real mess starts when you deal with languages that don't use the Latin alphabet or that have distinct formal and informal counting systems. I once spent an entire afternoon reformatting a dataset because I didn't realize Georgian has its own unique numeral system — the number 2 is "" (ori) — and the Unicode handling on some older systems turned it into replacement characters. That cost me about four hours of manual correction. Here is the practical breakdown of how "2" looks across a range of languages, along with notes on pronunciation and any gotchas you might run into. Arabic: (ithnan) — In formal written Arabic you'll see the Eastern Arabic numerals as well. If you are building software that needs to support both Eastern and Western Arabic numerals, test both forms. Some systems will accept one and reject the other without any warning.
Bengali: (dui) — Bengali has a separate form used in mathematical notation () that is distinct from the standard digit 2 in Unicode. I ran into an issue where a data import script silently mapped both forms to different byte values, causing duplicate rows. The fix was to normalize using Unicode NFKC decomposition before processing. Chinese (Mandarin): (èr) or (liǎng) — This is one of the trickier ones. "" is the default number, but "" is used when counting objects (like meaning "two items"). Using the wrong one in natural language contexts sounds distinctly unnatural, even if a native speaker can understand you. In technical contexts like barcodes or IDs, only appears. Dutch: twee — Pronounced roughly like "tway." The double "e" can trip up text-to-speech engines that aren't trained on Dutch phonology.
Finnish: kaksi — Finnish numeral systems carry through compounds seamlessly (kaksitoista = 12). No special handling needed unless you are doing plural inflection, which gets complicated fast. German: zwei — Standard. No surprises here unless you are dealing with Swiss German dialects, where "zwa" or "zwi" may appear in informal writing. Hindi: (do) — Devanagari script. The digit form is . Same normalization issue as Bengali if you are processing raw text from unverified sources.
Get the Full Details

Japanese: (ni) or (futatatsu) — Japanese has multiple counting systems depending on context. On-screen numerals usually use 2, but in formal documents is standard. The counter word changes entirely based on what you are counting — books use (satsu), people use (nin), flat objects use (mai). Picking the wrong counter doesn't just sound wrong, it can actually change the meaning of what you are describing. Korean: (du) — Hanja form is . Like Japanese, Korean has Sino-Korean and native counting systems, and they are used in different contexts. Native Korean numbers (, ) are used for small quantities and counting objects, while Sino-Korean (, ) show up in dates, money, and phone numbers. Portuguese: dois — Brazilian Portuguese uses "dois" universally in most contexts. European Portuguese can differ slightly in colloquial speech but the written form stays the same.
Russian: (dva) — Cyrillic. The numeral declines by gender: (masculine/neutral), (feminine). This matters if you are writing sentences that include the number, not just displaying it in isolation. Swahili: mbili — Used in Kenya and Tanzania. The wider Swahili-speaking region has some dialectal variation but "mbili" is widely understood. Tamil: (irau) — Tamil numerals have their own script form (). The Latin transliteration and the Tamil script numeral are completely different code points in Unicode, so a simple character swap won't work. You need a proper conversion library.
Thai: (song) — Thai numerals use their own digits: . These are distinct from Arabic numerals in encoding. A common pitfall is assuming a field contains "2" when it actually contains the Thai digit, which breaks numeric comparison operations. Turkish: iki — Straightforward. No special cases worth noting beyond the obvious that Turkish uses Latin script with dotted and dotless I distinction, but that doesn't apply to the number 2. Welsh: dau (masculine) / dwy (feminine) — Like Russian, gender affects the form. This is another case where just displaying the number in isolation hides the complexity that appears in actual usage.
Common Pitfalls When Working With Multilingual Numerals
The biggest issue most people hit is assuming all numeral systems play nice together. They don't. Eastern Arabic, Devanagari, Thai, and several other scripts have their own digit characters that look nothing like 0-9. Your spreadsheet will happily treat "" as text and refuse to do math with it. Always normalize before you calculate. A second issue is the difference between the standalone digit and the spoken/written word form. In Japanese, Chinese, and Korean, displaying the right symbol depends entirely on context. There is no single "correct" version. You need to know what the number is attached to — a date, a quantity, a rank — before picking the right form. If you are building anything that handles these inputs at scale, I'd recommend using a Unicode normalization library like ICU or Python's unicodedata module with NFKC decomposition. It won't solve every problem, but it will catch the majority of the silent mismatches that cause data corruption down the line.