Getting Started With Biological Tracking in 2026
Most people trying to manage lab data, field observations, or sequencing results are looking for something that does not require a full bioinformatics pipeline just to log what they saw yesterday. That is where 2026 Biology Tracker fits in. It is a lightweight data capture and organization system designed for biologists who need structured records without the overhead of a database administrator. The core workflow is straightforward. You install it, point it at your data source — whether that is a CSV export from an Osmotic pressure meter, a list of specimen barcodes, or your own spreadsheet entries — and then map your fields. The field mapper is the part most people skip, but it is what prevents the whole thing from falling apart later. If you do not assign proper data types at import, every downstream query becomes a guessing game. Dates stored as strings will not sort. Numeric values wrapped in quotes become unusable for any kind of filtering or graphing.
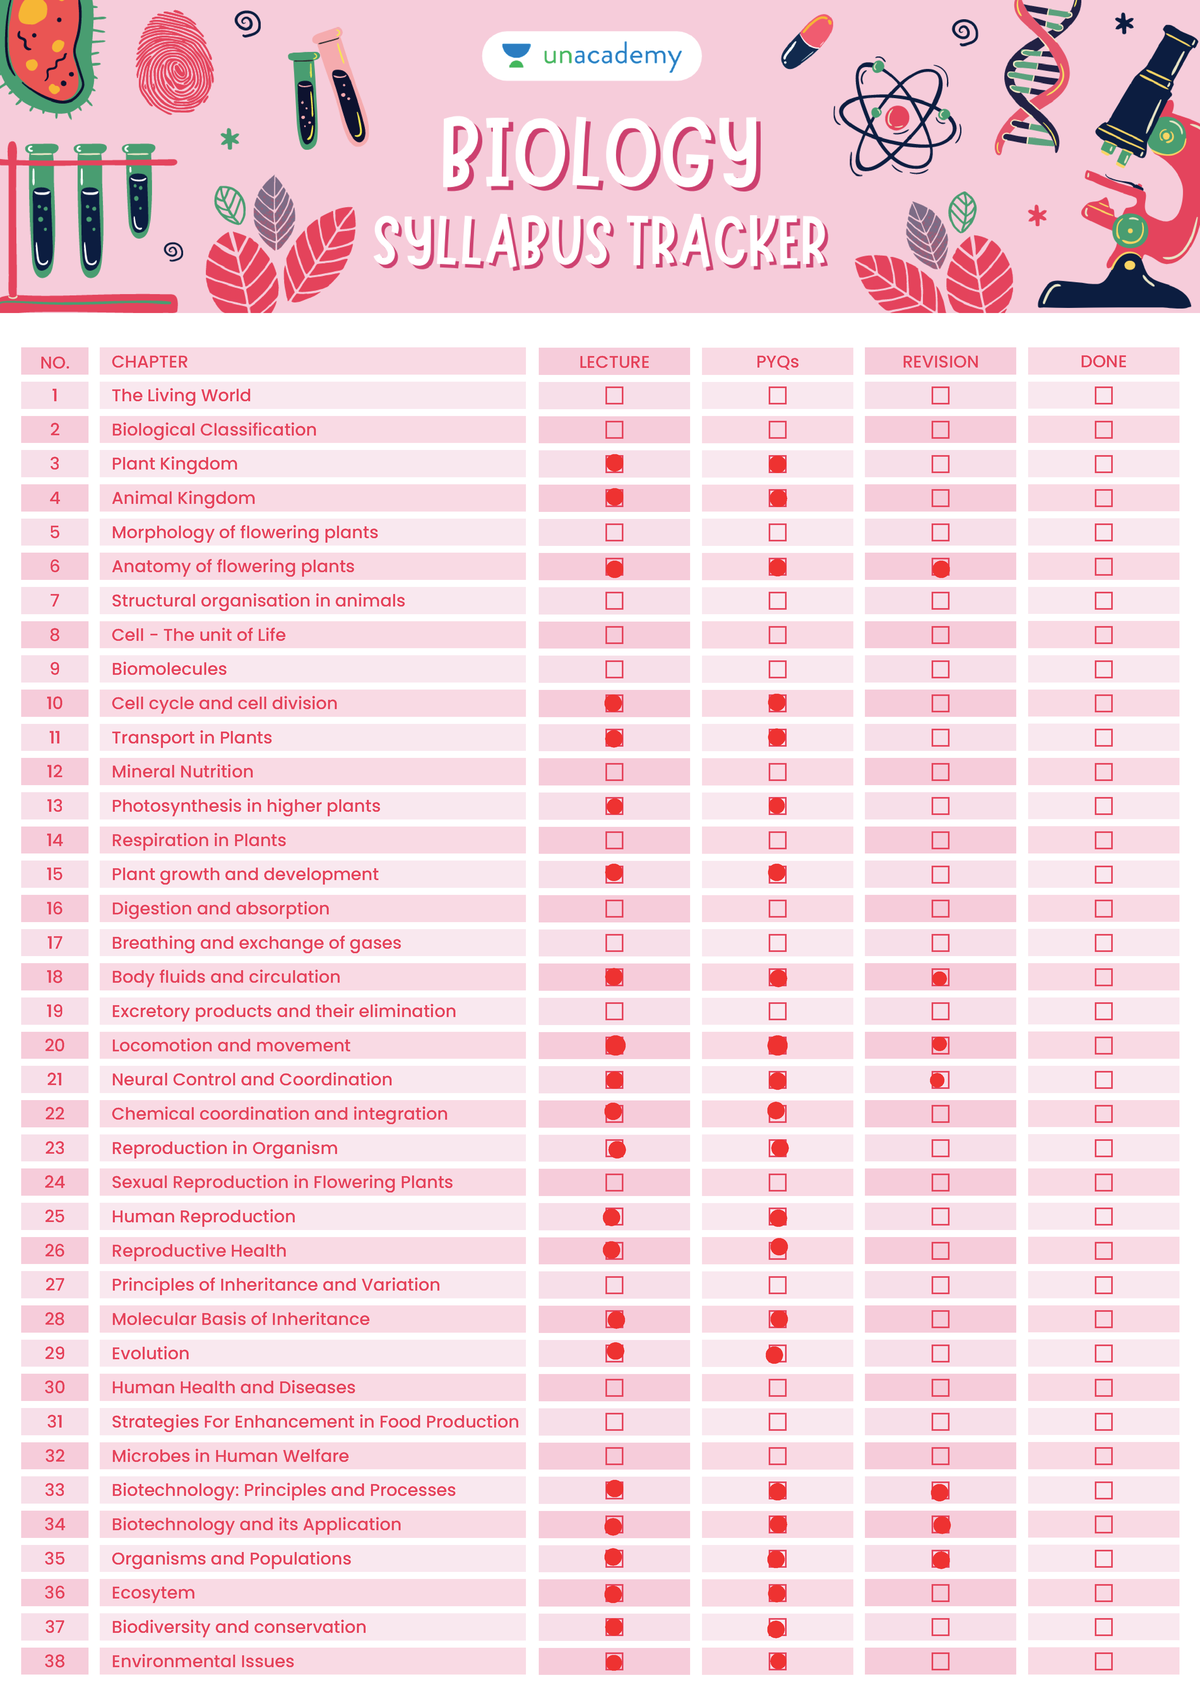
2026 Biology Tracker
I ran into a specific problem last November that took me about two days to fix. I was tracking temperature-dependent developmental rates across three strains of Drosophila melanogaster with repeated measurements over 14 days. The tracker was importing my time-series data, but every time I tried to generate a growth curve, the X-axis labels were duplicating at random intervals. The timestamps looked fine in the raw export, but the tracker was interpreting my local timezone offset as a fixed UTC value and collapsing multiple data points onto the same datetime index. The workaround was ugly but effective: I added a dummy millisecond column to the CSV before import, ran a quick script to append random sub-second values so each row had a unique timestamp, then hid that column from view after the import. The tracker accepted it without complaint and the curves rendered correctly. I still do not know if this was a bug in the parsing logic or just expected behavior given how some European date formats interact with the default parser. Here is what the software actually does well. Field-based querying is fast once your schema is set up. You can filter by organism ID, collection date range, GPS coordinates, or any custom tag you have assigned. The spatial visualization module works if you need to map transect points or specimen collection sites on a basemap. Export options include standard formats — JSON, CSV, GeoJSON, and a few other things most people will never use. The mobile companion app lets you drop observations in the field with photo attachments and GPS pinning, which syncs back when you are on Wi-Fi. This alone probably saves you thirty minutes per field session compared to writing everything down and transcribing later. There are real limitations. The sync engine is not built for large datasets. If you are collecting more than ten thousand records per experiment and syncing from a remote field site with spotty cellular coverage, you will hit timeouts and orphaned entries that require manual reconciliation. I have seen people lose weeks of phenology data this way because they assumed the app would buffer uploads seamlessly. It does not. You need a stable connection or you need to batch your uploads and check the sync log after every session.
The query builder is another weak point. It supports basic boolean logic and range filters, but if you need nested conditions — say, filter specimens where temperature was above a threshold AND the measurement was taken by a specific researcher AND the sample ID matches a regex pattern — you are out of luck. You either export to a spreadsheet and filter there, or you write a small Python script using their API endpoint, which is documented but not particularly intuitive. The API documentation itself could use an update. It references some deprecated endpoints that still appear in older tutorial videos floating around the forums. Cost is another factor worth mentioning upfront. The free tier gives you five hundred records and limited cloud storage. For an undergraduate research project, that might last a semester. For a lab running multiple parallel studies, you will quickly hit the wall and need to upgrade. The premium tier runs about forty dollars per month per seat, which stacks fast if your whole team needs access. A couple of labs I know have worked around this by running a local-only instance and sharing via network drive instead of cloud sync, but that defeats the purpose of the field app and creates its own version control headaches. If you already have a well-maintained PostgreSQL database with some post-processing scripts, you might find that building your own logging pipeline is more flexible and significantly cheaper long-term. The 2026 Biology Tracker is genuinely useful as a starting point, especially for groups that do not have a dedicated data manager on staff. It gets you from zero to structured records in an afternoon. But if your project grows beyond what the free tier allows, or if your data structure gets complicated enough that the query builder becomes a constant friction point, you should be prepared to migrate to something more robust before you accumulate so much history that the move becomes painful.
Get the Full Details