Getting a grip on project planning when everything keeps changing
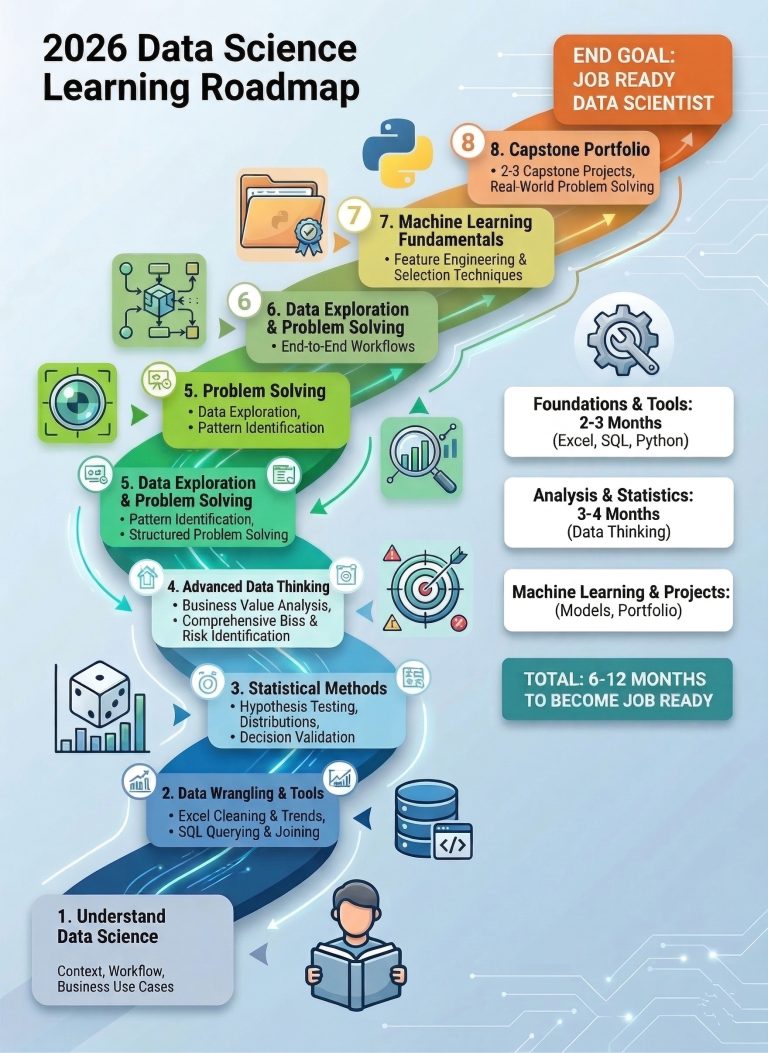
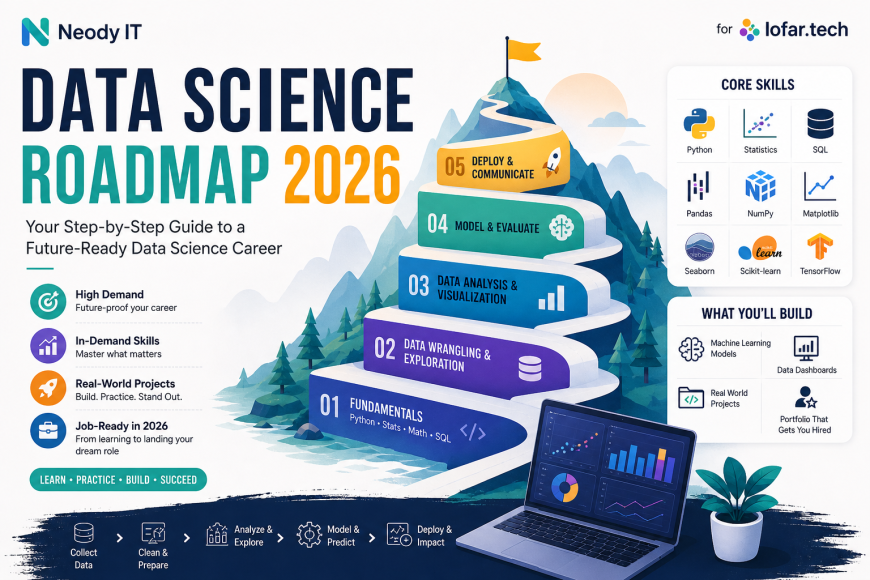
I spent three years building dashboards that nobody used because we never figured out the scope before writing a single line of Python. That changed when I started treating data science timelines like actual engineering deliverables instead of vague research goals. The 2026 Data Science Planner approach isn't about fancy software. It is a structured way of mapping out what a data science project actually requires from week one to deployment, and it stops the kind of mess I was making regularly. It is a planning framework that breaks a data science initiative into five explicit phases: problem framing, data assessment, modeling, evaluation, and deployment. Each phase has defined gates. You do not move forward until you have written documentation that answers specific questions for that stage. The 2026 Data Science Planner format forces you to confront ugly realities early, like the fact that your source data is missing three critical columns or your stakeholder does not actually know what metric they want improved. The framework became popular because traditional project management templates do not account for the uncertainty built into data work. A Gantt chart assumes you know the tasks. In data science, you often do not know the tasks until you have explored the data. This planner accepts that uncertainty and structures around it rather than pretending it does not exist.
How to use it step by step
Start with Phase One, which is problem framing. Write a one-page document that states the business question, the success metric, and the decision that will be made once the model exists. I once saw a team spend six weeks building a churn prediction model that their client had already decided would not change because the contract was fixed. The planner prevents that waste by making you prove the decision value before any data is touched. Phase Two is data assessment. This is where most people rush and pay for it later. Map every data source, note the quality issues, identify gaps, and estimate how long cleaning will take. Multiply your first estimate by two. I learned this the hard way on a healthcare project where I estimated a three-week data prep sprint. The provider's API returned malformed timestamps and inconsistent patient IDs. It took eleven weeks. The workaround I used was building a data profiling script with Pandas together with great_expectations that automatically generated quality reports. That script cut my discovery time from days to hours and gave the team concrete evidence when I asked for a timeline extension. Phase Three covers modeling. Pick a baseline model first. A logistic regression or a decision tree on tabular data usually beats a neural network on performance and always beats it on interpretability. Document why you chose each algorithm. The 2026 Data Science Planner format requires you to record what features you tried, what hyperparameters you tested, and what metrics you tracked across experiments. This seems like paperwork until you need to explain to a stakeholder why Model B is better than Model A six months later.
Phase Four is evaluation. Do not rely on a single test score. Run cross validation, check for data leakage, and test on a holdout set that matches real distribution. A common mistake I see is people validating on random splits when the data has a time component. That gives you inflated accuracy and a model that fails in production. The planner requires a leakage audit checklist at this stage. Phase Five is deployment. This is where projects usually die. Write the deployment plan before you finish modeling. Include monitoring, retraining triggers, rollback procedures, and ownership. An API endpoint that nobody calls is a worse failure than no model at all because it creates false confidence.
Get the Full Details
Where this framework falls apart
It does not work well for exploratory research or R&D projects where the goal is learning rather than delivery. If you are doing algorithm development or testing whether a new technique is viable, the gate structure becomes bureaucratic noise. You can still use the planning phases informally, but treating them as hard requirements will slow you down more than it helps. The other limitation is team size. A solo practitioner can produce the documentation quickly. A team of ten requires discipline. I have seen planners become stale artifacts in organizations where people fill them out after the fact just to satisfy management. The document then has zero connection to what actually happened. That is a cultural problem, not a framework problem, but it is worth noting.
Getting started with the 2026 Data Science Planner
You do not need a special tool. A shared Google Doc or Notion template works fine. Create sections for each phase with the gate questions listed above. The 2026 Data Science Planner is available as a free template on GitHub under the name ds-planner-2026, and several consulting firms publish their own versions. The content is similar across all of them because the underlying logic is the same. What matters is using it consistently, not which version you pick. Here is the realistic expectation. Using this approach will add roughly one week of planning time to small projects and two to three weeks to larger ones. It will save you three to six weeks later by preventing rework. The math only works if you actually complete the gates and refuse to skip them when things feel urgent. That is the part nobody likes. Skipping Phase Two to start modeling feels fast. It is slow. I still use this framework for every project now. It is boring, it is slightly tedious, and it keeps me from repeating the same expensive mistakes. That is enough for me.