Working with Second-Order Kinetics in the Lab
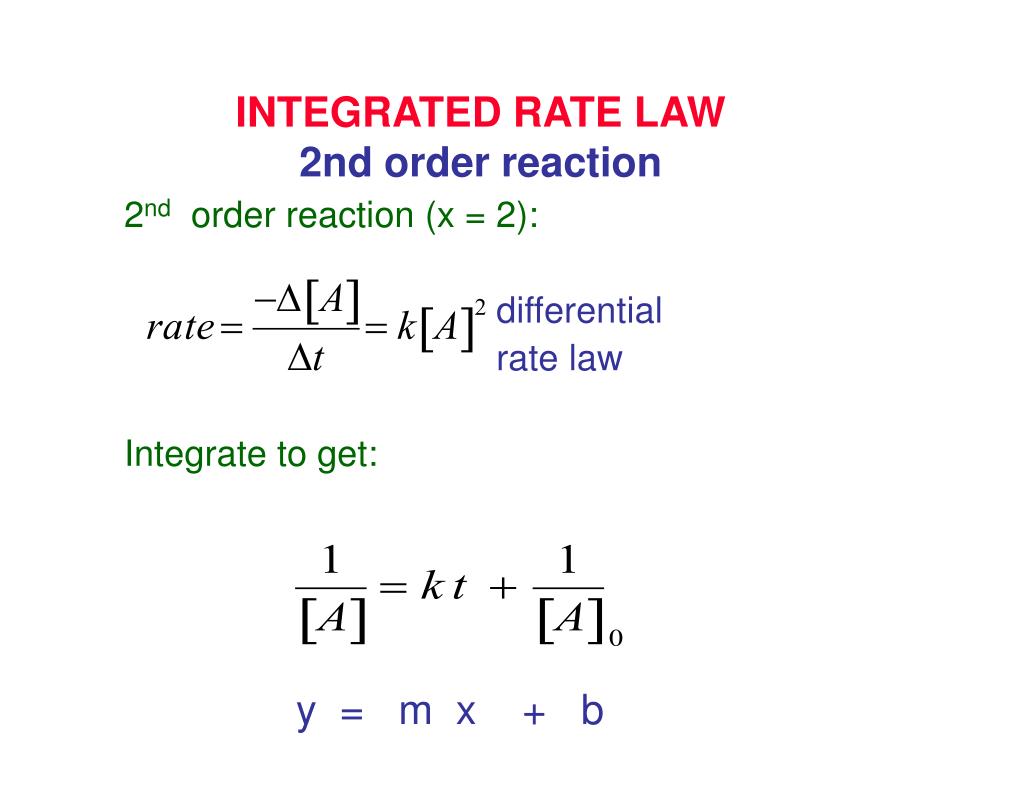
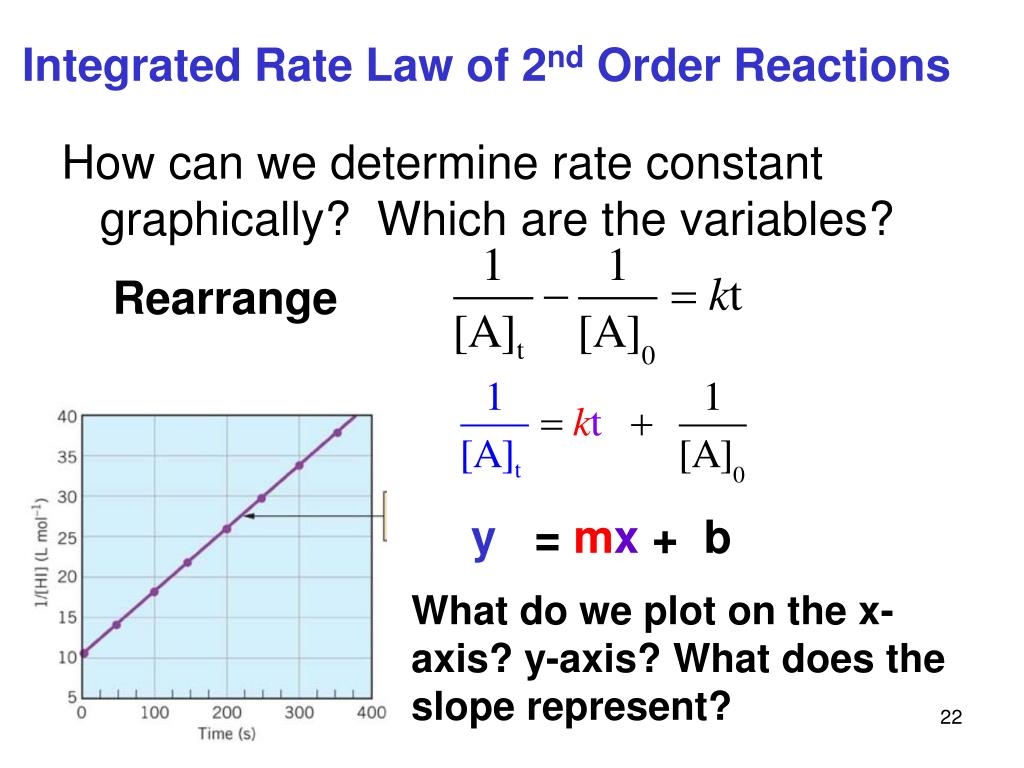
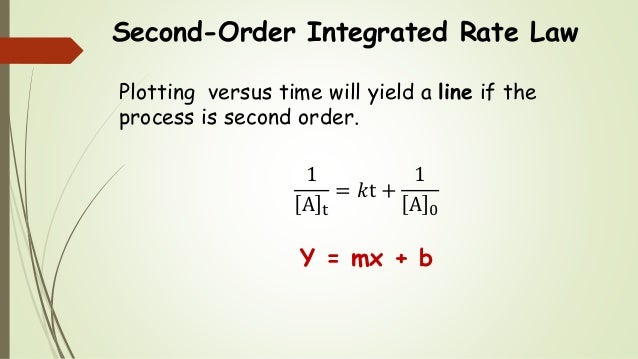
The integrated rate law for a second-order reaction is 1/[A] = kt + 1/[A]. That's the backbone. Everything else follows from that single equation. You plot 1/[A] versus time and the slope gives you k. If your data doesn't line up, the reaction probably isn't second order, not the other way around. I've seen too many students force a fit because the problem set says it has to be. Let me walk through a concrete example before getting into the weeds. Say you're tracking the decomposition of NO at 300°C. You collect concentration data at regular intervals: t = 0 s, [NO] = 0.0100 M
t = 50 s, [NO] = 0.0065 M t = 100 s, [NO] = 0.0048 M t = 150 s, [NO] = 0.0038 M
Convert each concentration to its reciprocal. Then plot those values against time. The points should fall on a straight line. Calculate the slope using two well-separated points to minimize error. Slope = (1/0.0038 1/0.0100) / (150 0) = (263.16 100) / 150 = 1.09 M¹s¹. That's your rate constant. One thing most textbooks don't stress enough: the units of k for a second-order reaction are always M¹s¹ (or L·mol¹·s¹). If your calculation gives you different units, you've made a mistake somewhere. I caught this once when a grad student reported k in s¹ for a second-order process. We traced it back to a missing concentration term in their spreadsheet. Took twenty minutes to find. The regression had been run on raw [A] values instead of 1/[A]. There's also the half-life expression: t/ = 1/(k[A]). Notice it depends on initial concentration. That's the difference between first and second order. A first-order half-life stays constant no matter how much you start with. For second order, double the starting concentration and you halve the half-life. This matters when you're designing a reactor or predicting how long a reaction will take under different conditions.
Get the Full Details

A Real Problem I Hit
Last year I was analyzing data from a dimerization reaction where the product itself absorbed at the same wavelength as the reactant. Standard practice is to monitor one species directly via UV-Vis. When both contribute to absorbance, the recorded "concentration" of the reactant is actually a composite signal, which completely ruins the linear 1/[A] plot. Your data will look noisy and curved even if the kinetics are perfectly second order. The workaround: I switched to monitoring the product formation instead. Since stoichiometry ties product formation to reactant consumption (for a simple A + A P reaction, [P] = ([A] [A])/2), I could reconstruct [A] at each time point from the product signal. This required knowing the molar absorptivity of the product independently, which I got from running a separate calibration with a pure sample. Once I had clean [A] values, the integrated rate law plot came out straight with an R² of 0.998. The apparent k value was nearly identical to what I'd gotten from a completely different method (NMR) on an aliquot taken at the endpoint.
Things That Go Wrong and How to Catch Them Early
Pseudosecond-order conditions. If one reactant is in large excess, the reaction appears second order overall but behaves as first order with respect to the limiting reagent. The math collapses into a pseudo-first-order form: 1/[A] no longer gives a clean straight line. Instead you get curvature. The telltale sign is when your apparent k changes depending on how much excess you use. Run the experiment at two different excess concentrations. If the calculated k shifts, you're not under true second-order conditions and you need to account for the excess reactant explicitly in your rate law. Temperature drift. Second-order rate constants are sensitive to temperature the same way all rate constants are, but because you're working with reciprocal concentrations, small errors in [A] get amplified at low concentrations. Near the end of a reaction when [A] is small, 1/[A] becomes large and a 1% error in concentration translates to a much larger error in the reciprocal. Keep your reaction temperature stable within ±0.5°C. A drift of 2°C can shift k by 10-15% depending on the activation energy. Auto-catalysis masquerading as second order. Some reactions produce a catalyst as a product, which accelerates the reaction over time. The 1/[A] vs. time plot curves upward instead of staying linear. Beginners often misidentify this as "experimental error" and smooth it away. Don't. An upward curve means the rate is increasing beyond what second-order kinetics predict. Check if your product is known to catalyze the reaction. If so, you're dealing with auto-catalytic kinetics and the standard integrated rate law doesn't apply.
When Second-Order Integrated Rate Law Fails Completely
This approach assumes elementary second-order kinetics with a single reactant pair. It breaks down if: For enzyme kinetics, for instance, trying to force the second-order integrated rate law onto substrate depletion data will give you nonsense k values that change with [E]. That's your signal to switch models. If you need to handle mixed-order systems or reactions where the order changes over the course of the conversion, consider numerical integration. Tools like Python's scipy.integrate.odeint let you define arbitrary rate laws and fit them directly to your concentration-time data without assuming a fixed order upfront. This usually cuts the trial-and-error process down to under an hour, compared to the half-day I used to spend trying different linearization plots by hand.

Quick Reference for Common Mistakes
Always verify linearity before calculating k. An R² value below 0.99 on your 1/[A] plot is a red flag, not a reason to delete outliers. Check the residuals. Systematic patterns in the residuals mean your model is wrong, not your data. Don't use the differential method (plotting rate vs. concentration) unless you have reliable derivative data. Numerical differentiation amplifies noise. The integrated method is more robust with real experimental data. Report k with proper significant figures. Your concentration measurements probably have 3 significant figures at best. Your k value shouldn't pretend to have more. I've seen k values reported to 5 or 6 figures from data that was clearly only precise to 2 or 3.