What You Need to Know Before Using the Empirical Rule
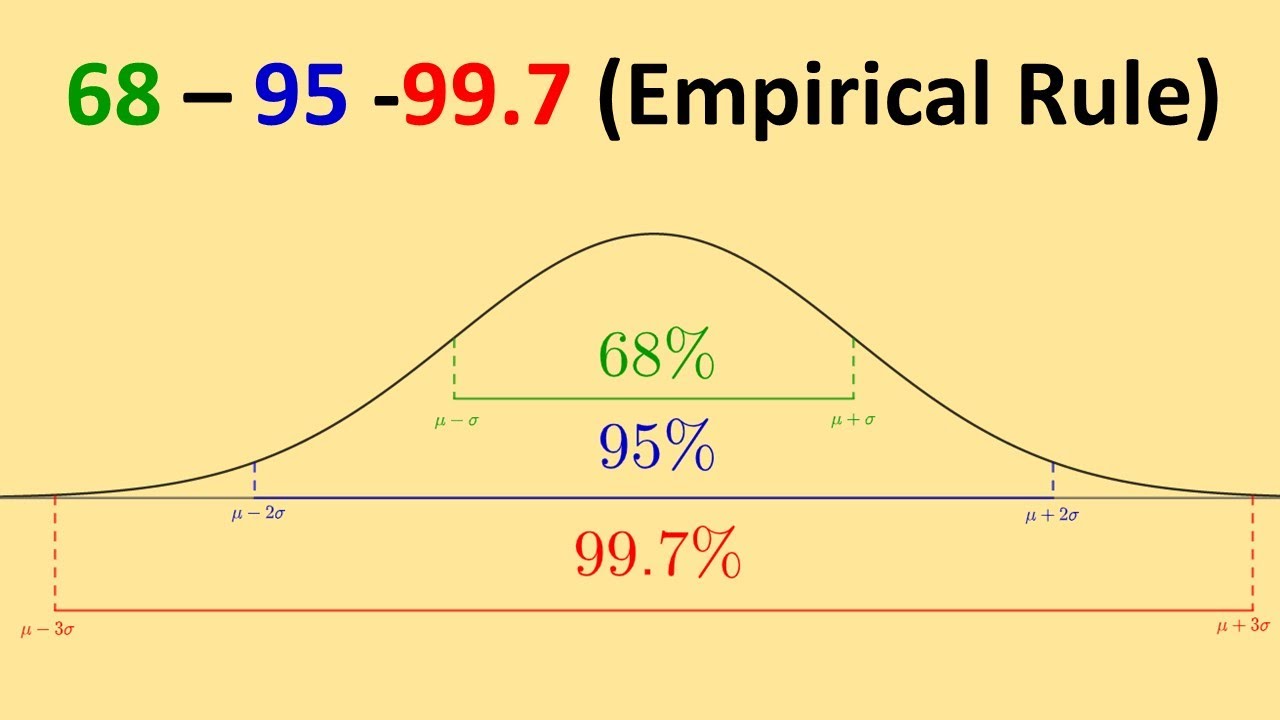
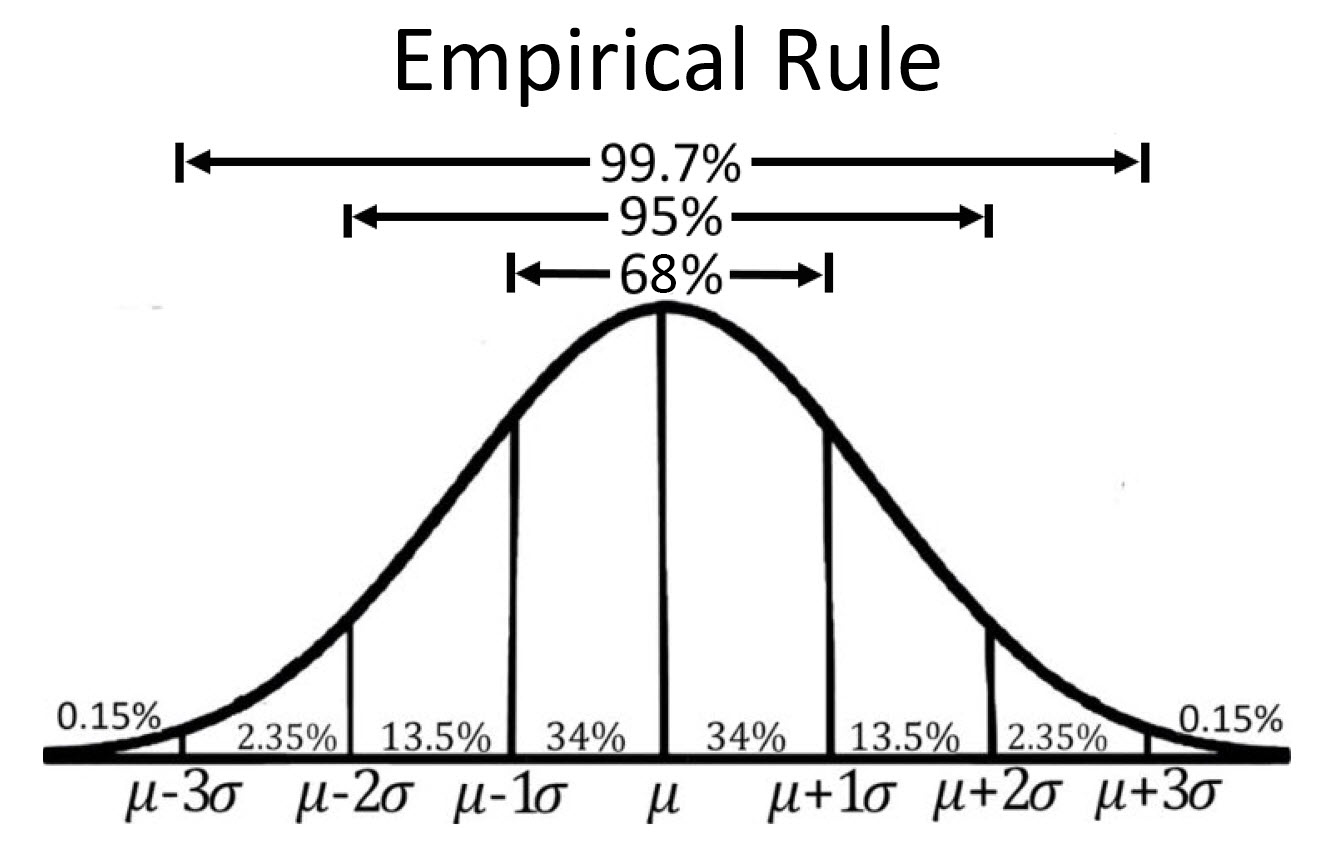
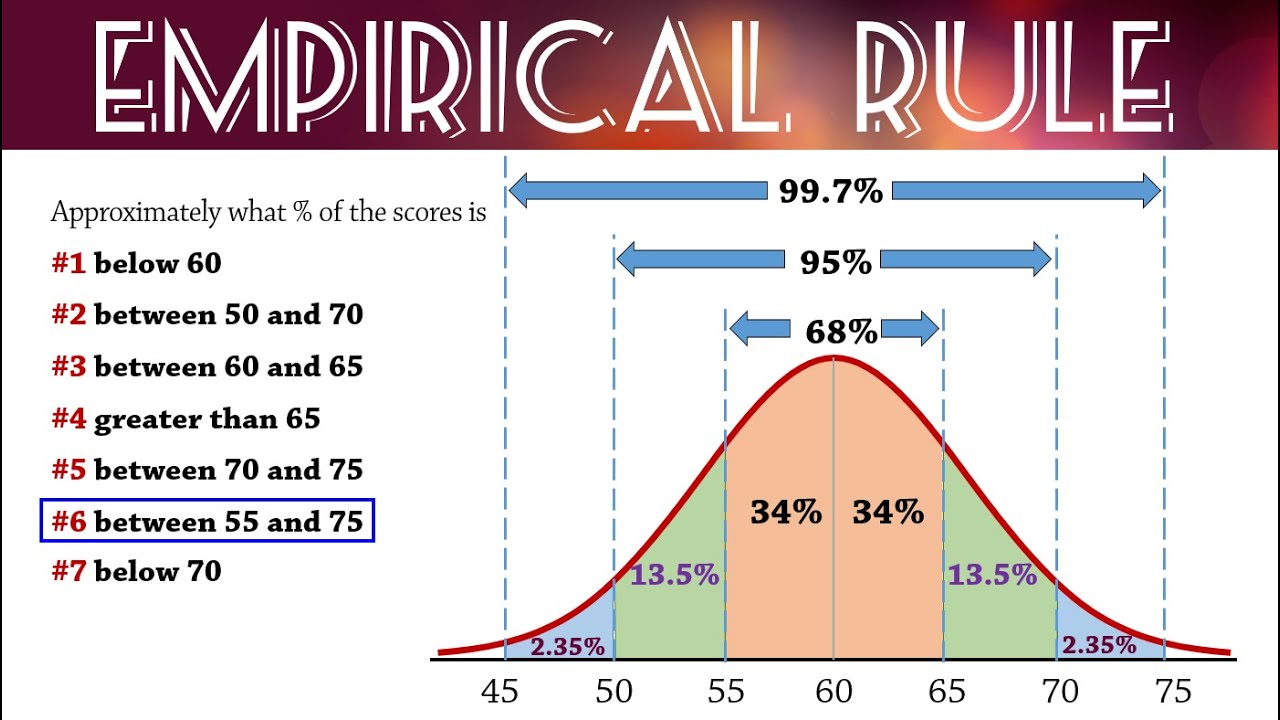
The 68 95 99 Rule is shorthand for something that sounds simpler than it actually is. It states that in a normal distribution, about 68% of values fall within one standard deviation of the mean, 95% within two, and 99.7% within three. That's the textbook version. The real version involves deciding whether your data actually qualifies as normal in the first place, which is where most people mess up. I need to lead with the calculation because that's what you're here for. You take your dataset, compute the mean and standard deviation, and then map those bell curve boundaries. Any observation inside plus or minus one sigma gets flagged as typical. Inside two sigma is still ordinary territory. Beyond three sigma is where you start asking whether the data is garbage or whether you've found something worth investigating. In practice, I use this when I'm reviewing quarterly performance metrics for client dashboards. My most common workflow runs through Excel or Google Sheets using the NORMDIST and NORMINV functions, but honestly I just calculate the boundaries manually and plot them on a quick scatter chart. Takes about ten minutes for a medium-sized dataset. Much faster than building a full statistical model and then explaining to a stakeholder why their outlier isn't actually an outlier, it's just within expected variance.
Where It Actually Breaks Down
Here's the part most tutorials skip. The 68 95 99 Rule assumes a symmetric, unimodal distribution. Real data rarely complies. I worked on a logistics project last year tracking delivery times across three regions. The raw data showed a heavy right skew because a few packages got stuck in customs for weeks. A naive application of the empirical rule would have labeled half the delays as three-sigma outliers when they were actually the normal shape of the distribution. My workaround was straightforward: I log-transformed the delivery times, recalculated the mean and standard deviation on the transformed data, applied the 68 95 99 Rule on that, and then mapped the boundaries back to the original scale. The adjusted thresholds caught the actual problematic shipments without drowning the report in false alarms. It added maybe five minutes to the process but saved hours of unnecessary investigation later. Another thing nobody warns you about is sample size. With fewer than 30 observations, the standard deviation estimate becomes unstable enough that the empirical rule's percentages lose practical meaning. You might get 95% of your data within two standard deviations by coincidence, not because the underlying distribution supports it. I've seen this bite people in quality control settings where they apply the rule to small batch samples and then feel confident about process capability that doesn't actually exist.
Practical Applications That Work
For properly distributed data, the 68 95 99 Rule is still one of the fastest ways to get a sanity check on any dataset. It's especially useful in manufacturing tolerances, A/B test analysis, and basic anomaly detection where you don't need precision, you need speed. If you're screening 10,000 transactions for fraud, flagging everything beyond three standard deviations gives you a reasonable shortlist to investigate manually. It won't catch sophisticated fraud that stays within bounds, but it removes the noise. I also rely on it for quick client consultations. When someone asks whether their conversion rate is behaving normally, I calculate the mean and standard deviation, apply the rule, and can tell them within thirty seconds whether their variation is consistent with a normal pattern or whether something structural is changing. That's worth more than running a full Shapiro-Wilk test and waiting thirty minutes for the output.
Get the Full Details
When to Look Elsewhere
The honest limitation is that the 68 95 99 Rule fails completely on multi-modal distributions, heavily skewed data, and datasets with hard lower or upper bounds. Revenue data, for example, has a hard floor at zero and usually skews right. Using the empirical rule on revenue figures will give you nonsensical negative boundaries on the lower end. In those cases, I switch to Chebyshev's inequality, which works for any distribution shape, though it produces much wider and less useful intervals. Or I transform the data first and then apply the rule to the transformed version. Another scenario where it underperforms is high-dimensional data. The rule is fundamentally a one-dimensional concept. Once you're dealing with correlated variables, a single observation might look normal on each axis individually but be anomalous in the multivariate space. That's when I move to Mahalanobis distance instead. It's more work to set up, roughly ten to fifteen minutes depending on comfort with the tooling, but it catches the patterns the 68 95 99 Rule misses entirely.