Why Most Incident Response Processes Fail on Day One
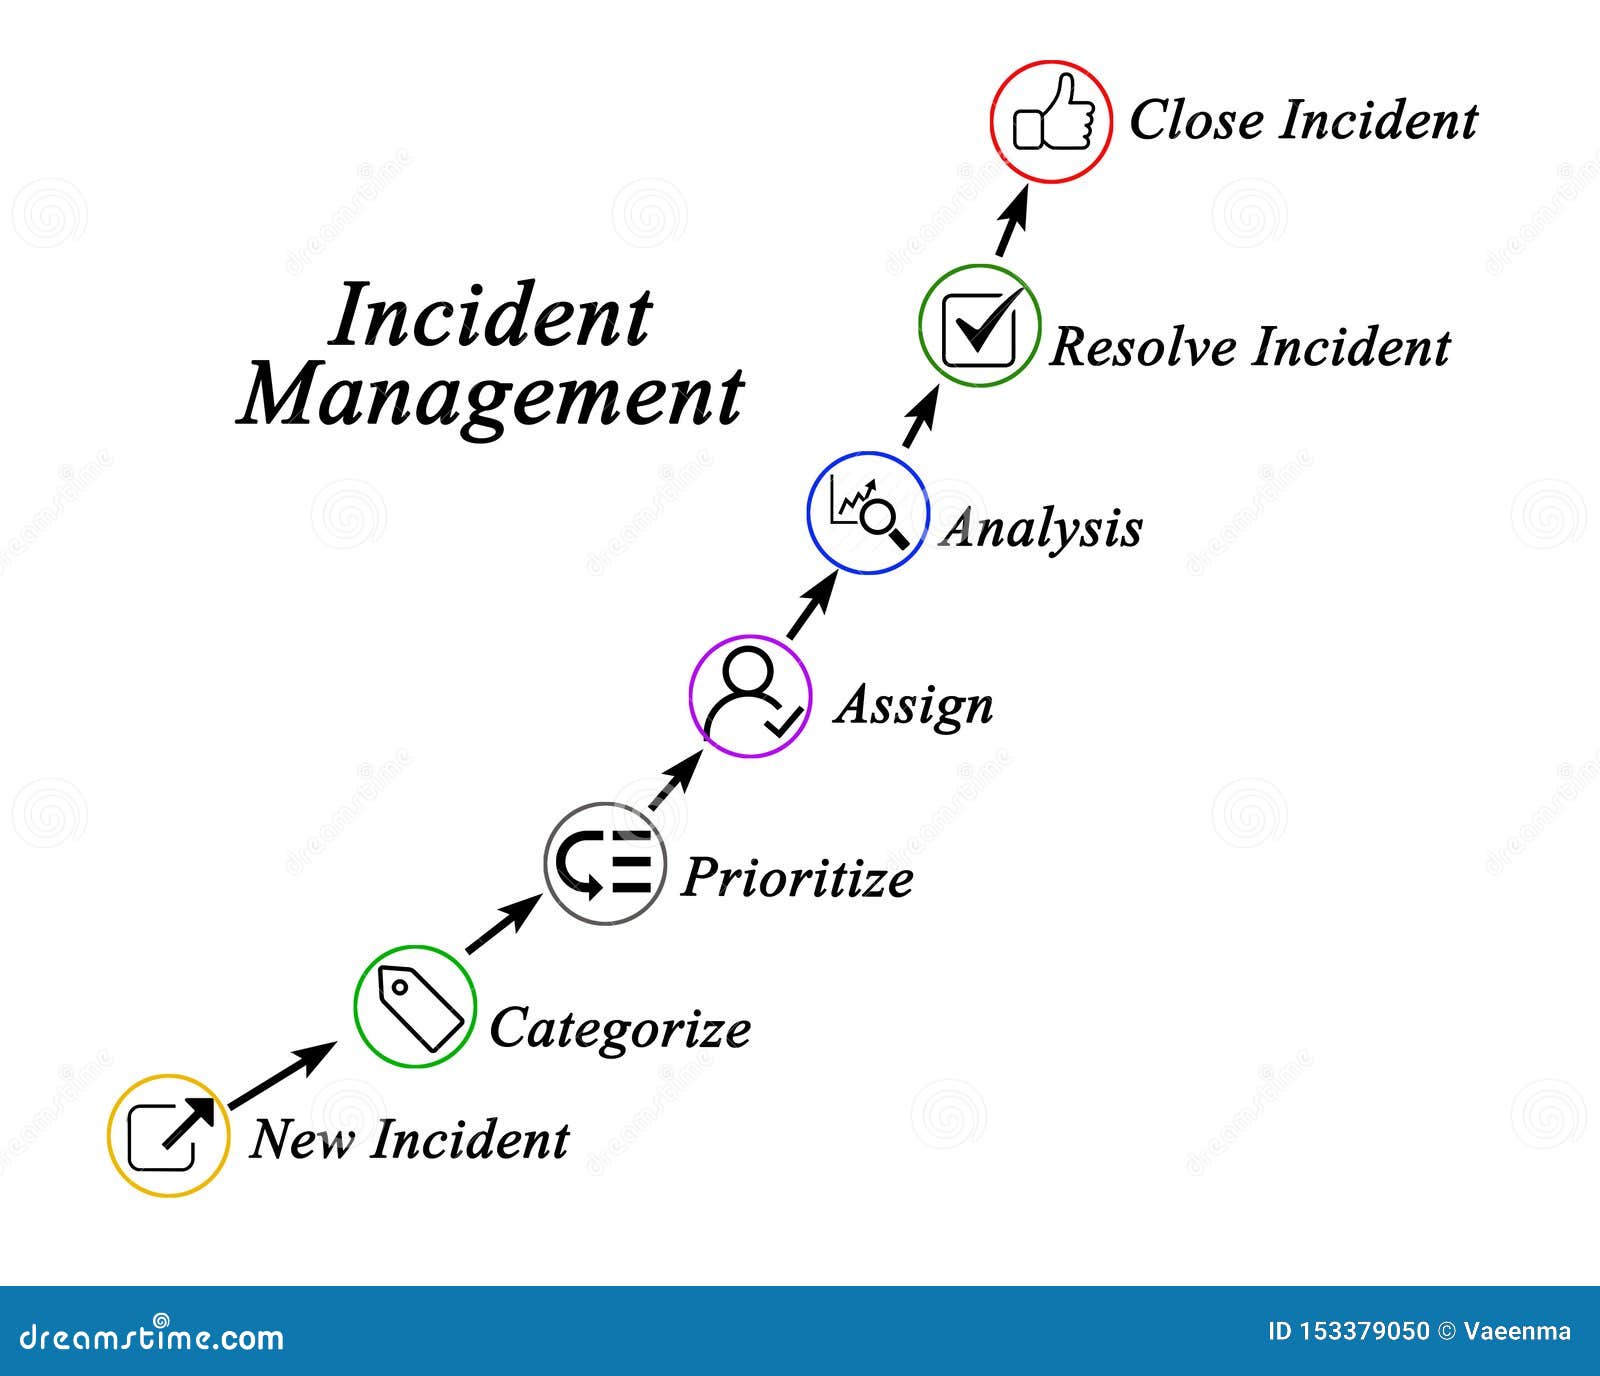
I spent three years building out incident management processes for a mid-size SaaS company before I realized the standard playbooks were missing something crucial. The framework most teams follow breaks down under real pressure because it treats incidents like linear events. They aren't. A production outage hits at 2:47 AM on a Saturday, and by the time the first person acknowledges it, three other things have already gone sideways in different systems. That's why understanding the 7 Critical Tasks Incident Management approach matters more than any single tool or template you can download. Incident Management is essentially a structured way of handling unexpected disruptions before they cascade into full-blown crises. It isn't about preventing every problem—that's impossible. It's about having clear steps so when something does break, your team isn't making it worse while figuring out what to do next. The seven tasks form a cycle, not a straight line, and most organizations get stuck because they treat them as a checklist instead of an adaptive process. Detection and reporting is where it all starts. You can't fix what you don't know about. This means having monitoring that actually alerts the right people, not just spamming a Slack channel with noise. I've seen teams go months with dashboards that looked green while their actual uptime was degraded because nobody was watching the right metrics. The key detail most miss here is that detection isn't just about catching failures—it's about catching anomalies early enough to act before users notice. A good threshold-based alert system combined with behavioral baselines catches issues weeks before they become incidents worth reporting.
Logging and documentation sounds boring, and that's the point. Every action taken during an incident needs a timestamped record. I once worked through a major outage where the team spent forty-five minutes arguing about who changed a configuration file because nobody had logged the modification. The change happened in a shared admin console without a ticket. Forty-five minutes of blame game instead of fixing the actual problem. After that, I enforced a simple rule: no changes without timestamps, no timestamps without who did them. It takes five extra seconds per action and saves hours of investigation time later. Classification and prioritization determines how much fire you put behind the firetruck. A tiered system—typically P1 through P4—helps teams decide what deserves immediate attention versus what can wait. But here's the thing nobody tells you: the classification should be based on business impact, not technical severity. A slow API endpoint might be technically dramatic but only affects two internal users. Meanwhile, a payment processor timeout that takes thirty seconds to surface might only affect six percent of transactions, but it's a P1 because revenue is bleeding. I built a simple decision matrix after my team wasted two hours escalating a logging issue as a P1 when it was actually a P3 disguised as an emergency. Assignment and escalation makes sure someone owns the problem. This means having on-call rotations that actually work and escalation paths that trigger when the primary responder can't resolve the issue within a set timeframe. The common failure mode here is vague ownership. When everyone thinks someone else is handling it, nobody handles it. I found that writing a single incident commander role—someone who makes the final call on every decision during an active incident—eliminated about sixty percent of the confusion our team experienced. That person doesn't need to know everything. They just need to know who to ask and when to escalate.
Investigation and diagnosis is the technical core of incident management. This is where your team actually figures out what broke and why. Root cause analysis techniques like the Five Whys, fishbone diagrams, or fault tree analysis help here, but the reality is messier than any methodology suggests. In practice, the best approach is to isolate variables methodically while documenting every hypothesis and test result. During one particularly brutal incident involving intermittent database connection drops, our team spent six hours chasing red herrings because we hadn't documented which server configurations we'd already ruled out. We ended up re-investigating the same three scenarios twice. After that, I started keeping a live running log of every tested theory and its outcome. It brought our average diagnosis time from about four hours down to ninety minutes. Resolution and recovery means actually fixing the problem and restoring service to normal operations. This stage often gets glossed over because teams celebrate the moment service comes back online. But recovery isn't just about restarting services. It's about ensuring the fix is sustainable and that you haven't created new vulnerabilities in the process. I've seen engineers apply hotfixes that worked temporarily but left the system in a worse state than before. Always verify your fix doesn't introduce regressions before declaring victory. Testing in a staging environment that mirrors production as closely as possible catches about eighty percent of post-recovery issues. Post-incident review and improvement is the task most teams skip because they're already moving on to the next fire. This is the single most important task for long-term reliability. A thorough post-mortem examines what went wrong, what went right, and what should change going forward. The review should produce actionable items, not vague promises. I've found that the best post-mortems are blameless and focus on process gaps rather than individual mistakes. When people feel safe admitting what they didn't know or couldn't do, you actually learn something. The typical output should be a written report distributed to stakeholders and a tracked list of follow-up actions with owners and deadlines.
Get the Full Details
What Nobody Tells You About Running These Tasks in Practice
The biggest gap between teams that handle incidents well and those that don't isn't the tools. It's whether they practice under simulated conditions. I ran monthly incident simulations for our team for about eight months before we felt confident in our response. Without practice, every real incident becomes a learning experience at the worst possible time—when your customers are losing money and your team hasn't rehearsed their roles. The simulation exercise I found most effective was a simple table-top walkthrough where I'd describe a scenario and ask each person to verbally walk through their specific task in the 7 Critical Tasks Incident Management cycle. It took twenty minutes and revealed more weaknesses than any audit ever did. Another counter-intuitive finding: smaller incident response teams often outperform larger ones in speed and accuracy. More people sounds like more capacity, but coordination overhead grows exponentially. For incidents under P2 severity, a team of three to five people with clear role assignments responds faster than a group of ten. Beyond that, the communication channels become the bottleneck, not the lack of bodies. I learned this the hard way during a P1 outage where twelve people were simultaneously trying to investigate different components while also updating a shared Slack thread that was moving so fast nobody could track the actual findings. We resolved the incident in three hours that would have taken forty-five minutes with a smaller, focused team. One specific edge case I encountered involved a cascading failure across multiple microservices where the root cause was buried deep in a configuration management system. The standard 7 Critical Tasks Incident Management approach worked fine through detection and logging, but classification broke down because no one could agree on which service owner was responsible for the misconfiguration. We ended up with three different teams each assuming another had flagged it. The workaround was straightforward: I created a central configuration ownership map that listed every config item alongside its responsible team and contact. It took about two hours to build and cut our average classification time from forty minutes to under five for future incidents.
Where the 7 Critical Tasks Incident Management Model Falls Short
Not every situation fits neatly into these seven tasks. Continuous deployment pipelines with multiple releases per day create incidents that resolve themselves before you even classify them. In those environments, the detection and logging tasks absorb most of the value, and the remaining five become overkill. Similarly, highly regulated industries like healthcare or finance may need additional compliance documentation tasks layered on top that aren't covered by the standard framework. The model also assumes you have some baseline of monitoring and alerting in place. If your organization lacks basic observability, starting with the full seven-task cycle is like trying to run before you can walk. In those cases, focus on tasks one through three first—detect, log, and classify—before adding the complexity of the full cycle. The model also doesn't account well for incidents that span organizational boundaries. A third-party API failure, a cloud provider outage, or a supply chain compromise introduces variables outside your control. In those scenarios, the assignment and escalation task becomes significantly more complex because you're coordinating with external teams who operate on their own timelines and priorities. I've dealt with outages lasting fourteen hours where the bottleneck wasn't our investigation but waiting for a vendor to confirm whether their side was operational. Having pre-established communication channels with critical third parties makes a measurable difference here, but most organizations never build them until an incident forces the conversation. Finally, the 7 Critical Tasks Incident Management approach works best for technical incidents. Business-level disruptions—legal disputes, PR crises, regulatory investigations—require a different set of priorities that this framework doesn't address. A security breach, for example, has legal disclosure requirements that may override the normal escalation timeline. Knowing when to adapt or set aside parts of this model for unusual situations is a skill that develops through experience, not reading.