Working With Protein Sequences in Practice
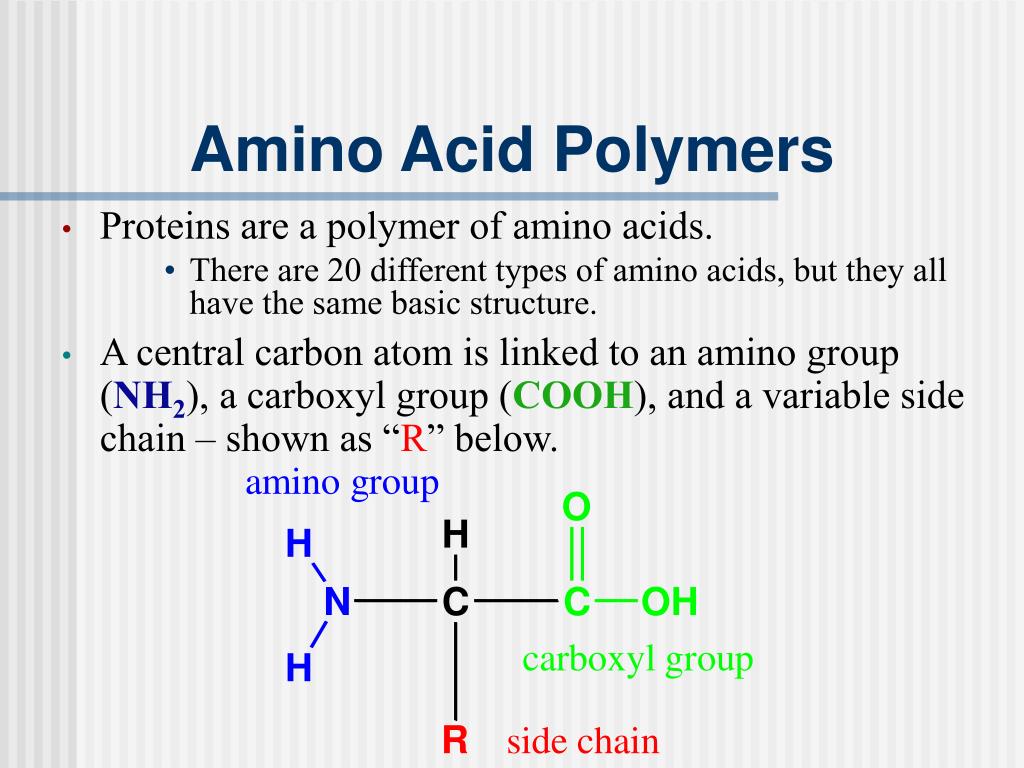
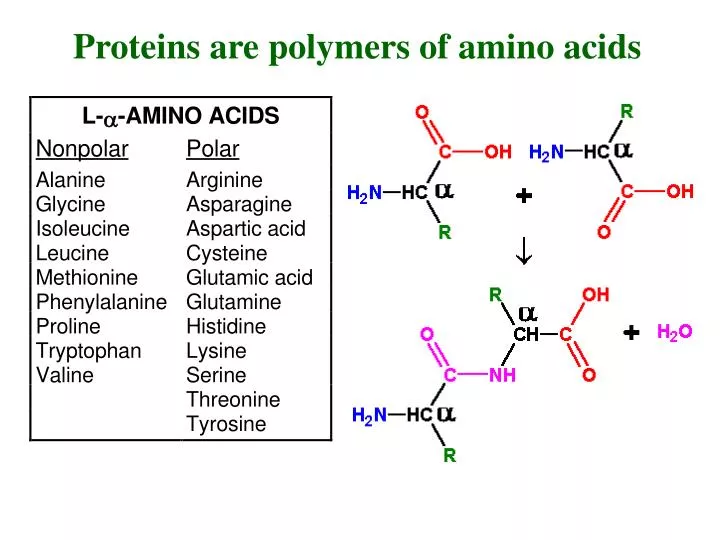
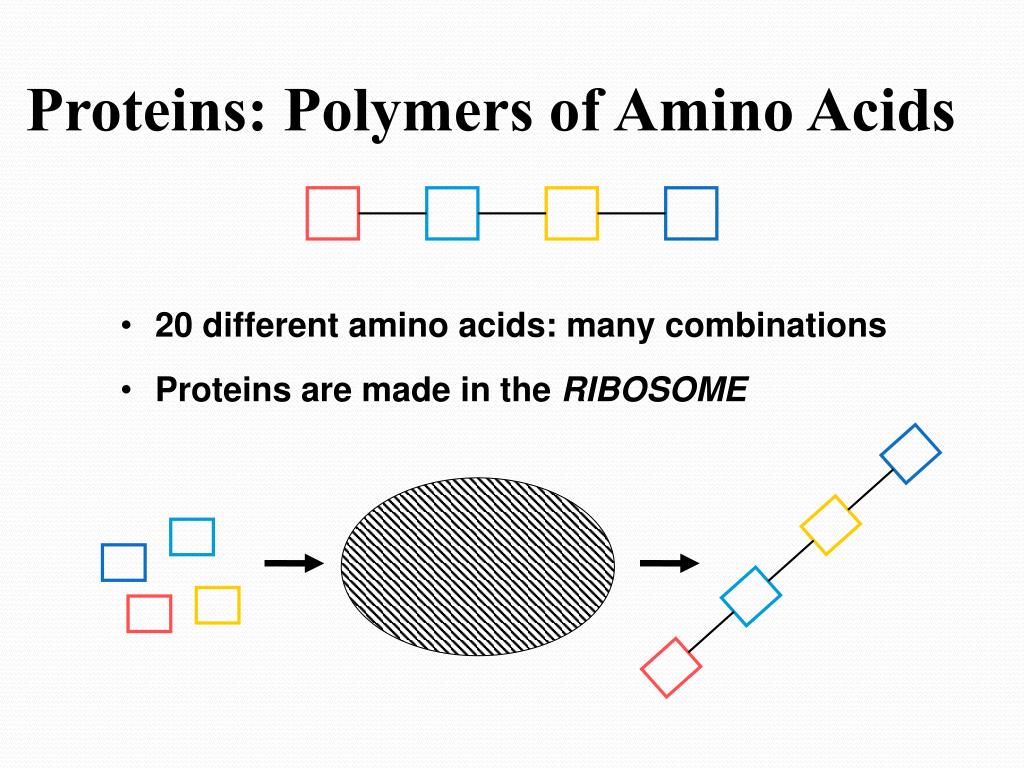
Most people encounter proteins through textbooks that show them as elegant ribbons folding into perfect shapes. The reality of handling A Polymer That Is Comprised Of Amino Acids in a lab or computational setting is far less cinematic. You are dealing with sequences that misfold, aggregate, degrade at room temperature, and refuse to behave the way the three-dimensional models suggest they should. The basics are simple enough. Twenty standard amino acids link together through peptide bonds, each residue contributing a specific side chain that drives folding, solubility, and reactivity. That is the textbook version. What nobody tells you is that the order matters enormously and a single proline in the wrong spot can stall a synthesis cycle for hours, or a cysteine pair that oxidizes during purification can turn an entire batch into insoluble gunk.
What A Polymer That Is Comprised Of Amino Acids Actually Is
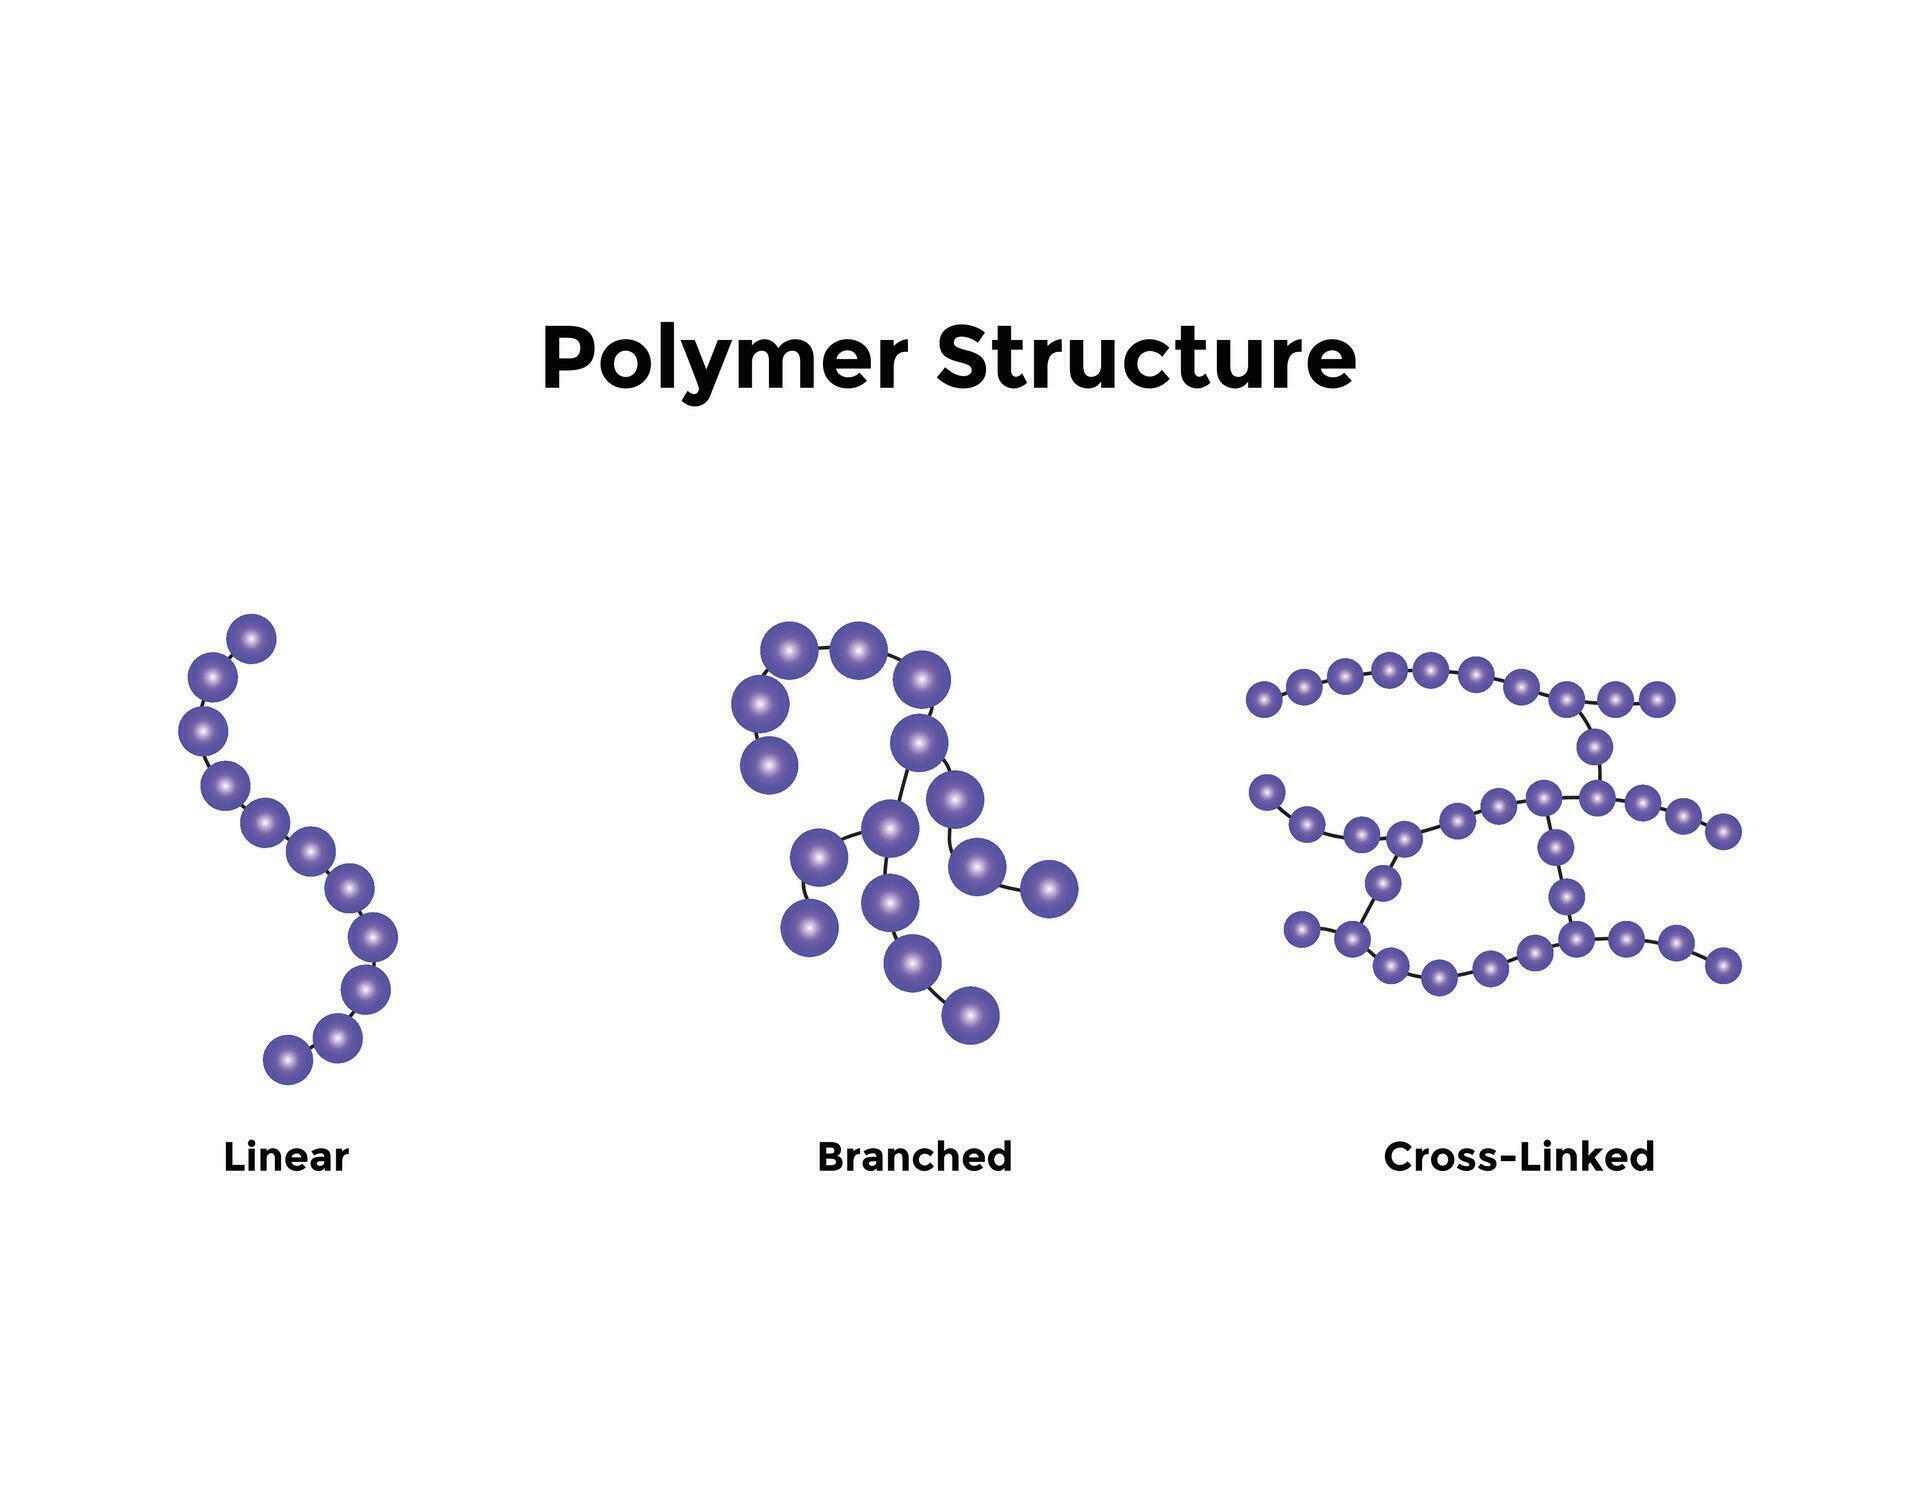
A protein is a linear polymer where the monomer units are alpha-amino acids connected by amide linkages, commonly called peptide bonds. The sequence from the N-terminus to the C-terminus encodes everything about its structure and function, but encoding is not the same as expression or folding. Secondary structure elements like alpha helices and beta sheets form from backbone hydrogen bonding patterns, not from the side chains themselves. The side chains determine whether those patterns are stable in your buffer conditions or fall apart the moment you change pH by half a unit. Thermodynamically, the folded state sits in a narrow energy well. Kinetically, the protein spends most of its time sampling misfolded intermediates before settling. That is why you see aggregation during expression and why solubility tags like GST or MBP do not always solve the problem even when they work for neighboring clones.
How to Approach a New Sequence Before You Commit Resources
I used to run expression tests blindly and waste three days per clone waiting for results. Now I do a quick in silico assessment first, and it usually cuts screening time down to roughly half a day instead of two or three full days per construct. Run a theoretical isoelectric point and molecular weight calculation. Check the GRAVY score for hydrophobicity. Look for problematic motifs like consecutive arginines, internal restriction sites you actually need, or low-complexity regions that tend to cause truncation during expression. These steps take about ten minutes in any basic bioinformatics tool and can save you from building a vector you will never get to work. For expression, choose the right system based on what you need. Bacterial systems are fast and cheap but lack post-translational modification capability. Insect cells with baculovirus give better folding for eukaryotic proteins and handle disulfide bonds more reliably. Mammalian systems are the answer when glycosylation patterns matter for function or structure. Each system has a turnaround time and a cost profile that diverges sharply after the first week.
Get the Full Details
Purification strategy should be decided before cloning, not after. A hexahistidine tag works for most recombinant proteins under native conditions, but imidazole competes with certain binding motifs and can interfere with downstream assays. Flag or HA tags are cleaner for immunoprecipitation but require larger volumes for elution. Protease cleavage sites like TEV or Thrombin need to be placed carefully so they do not leave extra residues that could affect crystallization or activity measurements.
Common Problems and What Actually Works
Solubility is the first bottleneck. When a protein precipitates, it is usually because hydrophobic patches on the surface interact with each other faster than the protein can find its native fold. Lowering the induction temperature to eighteen degrees Celsius and extending the expression time to sixteen to twenty hours often shifts the balance toward soluble protein. It is not a guarantee, but it changes the kinetics in a useful direction. Aggregation during purification is another familiar problem. I once spent two weeks trying to refold a disulfide-rich enzyme from inclusion bodies. The redox pairing was not the native pattern, and I ended up with four different mixed-disulfide species that co-eluted on size exclusion chromatography and looked identical on a gel. The workaround was to express the protein in a strain engineered for disulfide bond formation in the cytoplasm and purify under fully oxidizing conditions instead of trying to refold later. That saved me approximately ten days of futile work. Proteolytic degradation during expression or purification is common when the protein contains exposed cleavage sites or when host proteases remain active. Adding protease inhibitors to every lysis and purification step is standard, but it is equally important to work at four degrees Celsius whenever possible and to minimize the time the protein spends in its partially folded states where hidden cleavage sites become accessible.
When a protein is inherently unstable, adding a stabilizing ligand or cofactor during purification can lock it into a protected conformation. Zinc for certain metalloproteins, ATP or ADP for kinase domains, or simple reductions in buffer pH can extend handling time from minutes to several hours without significant loss of activity.
What Beginners Miss About Sequence Design
Removing internal cleavage sites is something almost everyone overlooks until it is too late. If you are cloning into a vector with a particular restriction site inside the coding region, you will either lose the insert during digestion or end up with unwanted mutations. Silent codon optimization fixes this without changing the amino acid sequence, though you should avoid over-optimizing for the host codon bias because rare codons near the N-terminus can actually improve folding by slowing translation at critical points. Another overlooked issue is the effect of the N-terminal methionine. Most expression systems remove it, but not all. A retained methionine can shift the apparent molecular weight on a gel by one kilodalton and sometimes affects stability or activity depending on how close it sits to the active site. Buffer composition matters more than most protocol sheets admit. A standard PBS buffer is fine for short-term storage but can promote aggregation over days or weeks. Adding a low concentration of non-ionic detergent like 0.01 percent Tween-20 or 0.05 percent NP-40 often improves long-term stability without interfering with most enzymatic assays. Glycerol at five to ten percent also helps, though it can inhibit certain enzymes and complicate crystallization trials.
Limitations and When to Walk Away
Not every protein yields well to standard expression and purification pipelines. Membrane proteins are the most obvious example. They require detergents or lipid mimetics to remain soluble, and finding the right combination is still largely empirical. Even when you succeed, the detergent can interfere with activity measurements and structural studies. Nanodiscs or amphipols are better alternatives now, but they add steps and cost. Highly dynamic or intrinsically disordered proteins resist crystallization and often give poor signals in standard biophysical assays. If your goal is structural biology rather than functional characterization, these proteins may need truncation, fusion partners, or stabilizing mutations before anything useful comes out of the pipeline. Post-translational modifications like phosphorylation, glycosylation, or methylation are impossible to reproduce in bacterial systems. If your protein requires a specific modification for activity or stability, you need an appropriate eukaryotic system, and you should expect longer expression times and lower yields. Mammalian cell lines can produce milligram quantities per liter, but that requires expensive media, larger culture vessels, and significantly more time than bacterial expression.
There is also a hard limit on protein length for many systems. Very large proteins or multiprotein complexes often require co-expression of multiple plasmids or viral vectors, which introduces additional variables around stoichiometry and cooperative folding. In practice, this means you may need to assemble subcomplexes separately and then combine them, which is a much more involved process than expressing a single construct. If you are starting from scratch and the protein does not come back soluble after testing at least three expression conditions across two different systems, it is usually worth reconsidering the approach rather than pushing harder on the same method. There is no shame in choosing a different construct design or a different target region instead of spending months on a problematic full-length protein.
Practical Next Steps
Download a sequence analysis tool like ExPASy ProtParam or install a local copy of EMBOSS if you prefer command-line workflows. Run every new sequence through it before ordering any primers or constructs. Use FoldX or Rosetta for quick stability predictions when you are designing mutants, understanding that these tools have known limitations with disordered regions and membrane proteins. Keep a lab notebook with expression conditions, buffer compositions, and observed solubility for every clone. Two years from now, that notebook will be more useful than any published protocol. The field moves quickly, and new methods for protein expression, stabilization, and purification appear regularly. The core principles do not change though. Understand your sequence, plan your construct carefully, test early and often, and be willing to adjust your strategy when the data tells you to. That is what actually works.


