The Work That Actually Happens
Most people think competitive intelligence is reading press releases and pricing pages. It's not. It's the slow accumulation of unglamorous data points that eventually let you predict what a competitor will do before they announce it. I spent three years watching my company lose deals because we were reacting instead of anticipating. We fixed it, but it cost us roughly two million in a single quarter.A Practical Guide To Competitive Intelligence
Start by mapping every customer-facing touchpoint your competitor has. Their website isn't enough. You need their careers page, their LinkedIn activity, their patent filings, their support documentation, and most importantly, the RFPs they're responding to. The RFP data is where you learn what questions prospects are actually asking and what objections your competitor is trying to overcome. When I built our first pipeline, I started scraping publicly available RFP responses from their vendor portal. Most companies don't lock those down. It took me about four hours to set up the scrape and another six to clean the data, but the resulting dataset gave us an edge on objection handling for the next eighteen months. Signal over noise. The biggest mistake I see is collecting everything and learning nothing. You need a thesis-driven approach. Pick one competitive threat and form a hypothesis around it. Then gather only the data that confirms or refutes that hypothesis. If you're trying to understand whether Competitor X is planning to expand into the mid-market, don't read their entire product roadmap. Look at their hiring patterns in mid-market accounts, check if they've added channel partnerships targeting smaller businesses, and review any investor calls where executives mention the segment. Three data points can be worth more than three hundred blog posts. The part nobody talks about is maintaining the database. CI is a muscle that atrophies fast. I once ran a quarterly intelligence process for a product team that went dark for six months because the person responsible left and nobody had documented the workflow. When we tried to restart, we couldn't even remember where we'd stored the contact lists or what tools we'd been using. We ended up rebuilding the entire operation from scratch. Now I require that anyone who starts a CI project documents three things before they stop working on it: where the data lives, what the refresh cadence is, and who owns the next update. It adds maybe twenty minutes to their workload and has saved us from complete blind spots twice.
One counter-intuitive thing about competitive intelligence: the best sources are usually the ones your competitors think are irrelevant. Their engineering blog comments, the typo-ridden forum posts from their community managers, the GitHub issues on their open source projects. These channels have no editorial oversight and no PR filter. I once discovered a competitor was struggling with API rate limiting because a frustrated customer posted a detailed error log on a niche forum. We used that information to design our own throttling architecture to specifically address that weakness. Their marketing team had zero awareness that this public frustration was being studied. Another thing beginners miss is the difference between intelligence and information. Information is that Competitor Y raised $50 million. Intelligence is figuring out what they're actually going to spend it on, which product line gets priority, and how that changes their pricing strategy in the next two quarters. To get from information to intelligence, you need to understand their unit economics, their burn rate, and their investor expectations. That requires financial analysis skills, not just web browsing. I spent weeks learning how to read between the lines of Series B and C term sheets because that's where the real behavior signals live. There are tools that help. Crunchbase Pro, AppFollo, and similar platforms can automate parts of the data collection. But automation has a ceiling. These tools are good at surface-level tracking: funding rounds, hiring spikes, product launch dates. They are terrible at context. When a competitor hires five engineers in a new city, the tool tells you who was hired and when. It cannot tell you whether they're building a new feature, supporting an existing one, or filling turnover. You have to make that judgment call yourself, and judgment comes from talking to people in the market, not from a dashboard.
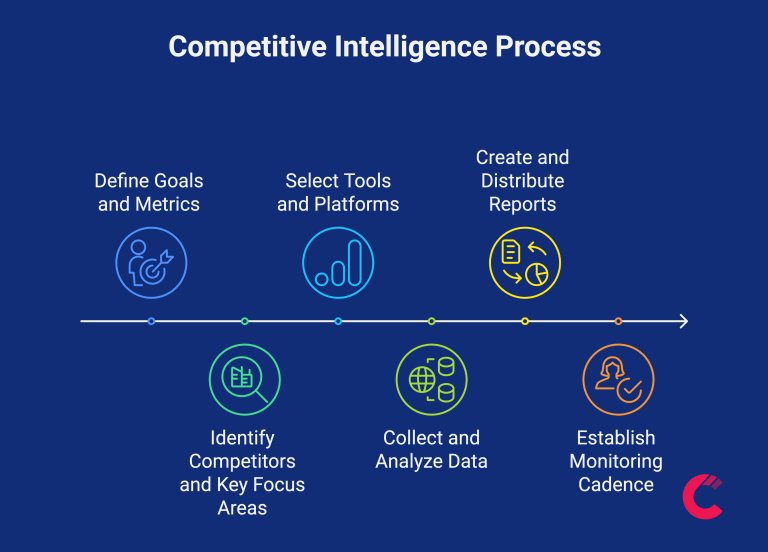
The process I use takes about two hours per week for a mid-size competitive landscape. Monday is for scanning and tagging new information. Wednesday is for deep analysis on one specific question. Friday is for writing the brief and distributing it to stakeholders. That's it. The brevity is intentional. Long reports get ignored. A three-paragraph email with a bolded lead and one chart lands better than a thirty-page PDF. I learned this the hard way when my first comprehensive competitive analysis was read by exactly one person and that person never mentioned it again. Here's where the method breaks down. Competitive intelligence fails when your competitors are honest. If they publish transparent roadmaps, share clear pricing, and send helpful support docs, there's less signal to extract. In those cases, you pivot to operational intelligence: analyzing customer satisfaction metrics, support ticket resolution times, and net promoter scores. These are harder to get but often more useful because they reveal what customers actually experience, not what marketing says they experience. Another scenario where CI hits a wall is when the competitive landscape is shifting so rapidly that by the time you compile your findings, they're obsolete. I experienced this during a market disruption when a new entrant changed the pricing model overnight. Our quarterly cycle was too slow. The workaround was building a real-time alert system for key triggers: funding announcements, executive hires in critical roles, and changes to their public API documentation. These alerts feed directly into Slack so the team sees them within minutes, not weeks.
Get the Full Details

If you want to start, pick one competitor and one question. Spend one week answering it with as much rigor as you can manage. Document everything. The output doesn't need to be perfect; it needs to be actionable. If the answer changes how you pitch a deal or position a feature, you've succeeded. If it doesn't, refine your approach and try again. This is a skill that improves with repetition, not a one-time project. The downloadable framework I use is a simple spreadsheet that tracks hypotheses, evidence, source links, and confidence levels. It has columns for data type, date collected, and whether the finding is confirmed or still speculative. I'm not linking to it here because it's a living document that's changed significantly since I shared it publicly, and outdated versions cause more confusion than value. If you want it, ask for it in the replies and I can update the link. The structure is straightforward enough that you can build your own in under an hour.