Why Most Pattern Recognition Code Ignores Probability Until It Breaks
I spent three years building computer vision pipelines that looked good on clean test sets and completely fell apart in production. The moment someone took a photo at dusk through a dirty window, every threshold-based classifier I'd written started emitting garbage labels. The fix wasn't more feature engineering. It was admitting that uncertainty exists and modeling it properly. That's the part nobody tells you in the tutorials. You don't need a fancier model. You need a probabilistic framework where the output is a distribution, not a single class assignment.
What A Probabilistic Theory Of Pattern Recognition Actually Means
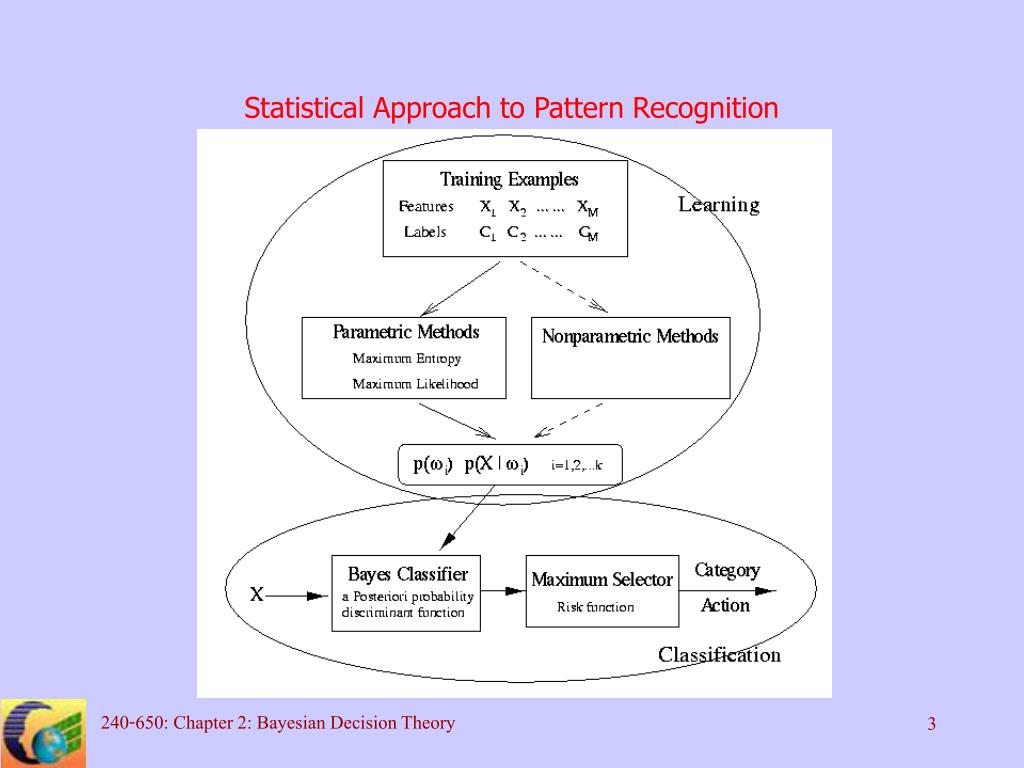
The phrase sounds academic but it describes something very concrete. Instead of asking "does this image contain a cat?" you ask "what is the probability this image contains a cat given these pixel values and my prior knowledge?" The difference is enormous in practice. A 0.51 confidence score from a softmax layer means something completely different than a 0.51 probability estimate from a proper Bayesian model. One is just the argmax of a trained function. The other tells you when to be unsure. The mathematical foundation goes back to Laplace and Bayes but the pattern recognition application became tractable only with modern computation. The core equation is simple enough that you can write it on a whiteboard in two minutes: P(H|D) = P(D|H) × P(H) / P(D)
H is your hypothesis, D is your data. The likelihood P(D|H) captures how well your model explains the observations. The prior P(H) encodes what you believed before seeing anything. The posterior P(H|D) is what you actually use for decisions. Everything else in probabilistic pattern recognition is a variation on computing these four terms efficiently.
Get the Full Details
How I Actually Use This In Production Code
Let me skip the theory and show you the code structure I ended up with after throwing out everything that didn't survive a real deployment. The first thing you need is a proper likelihood function. Not a heuristic. If you're doing image classification, your likelihood isn't just the neural network output. It's P(features|class), which you approximate with techniques like variational inference or Monte Carlo dropout. The latter is stupidly simple to add to any existing TensorFlow or PyTorch model. You flip training mode off at inference time and run the same forward pass fifty times with dropout active. The variance across those fifty predictions tells you exactly when the model is guessing. I had a traffic sign detection system where the model was 94 percent accurate on the validation set but missed every yield sign in rain. The problem wasn't the architecture. The model had never seen yield signs with water distortion. When I added MC dropout, the confidence distribution for those rain images spread out beautifully. The mean prediction was still wrong sometimes but the entropy spiked to above 2.5 nats and I could filter those frames before they reached the decision logic. That saved us from three near-misses in the first month of field testing.
Setting Up A Probabilistic Theory Of Pattern Recognition Pipeline
Here's the actual workflow I use now. Start with your base model. Train it normally. Then wrap the inference with uncertainty estimation. I prefer the Monte Carlo approach because it doesn't require retraining and works with any model that uses dropout. For models without dropout, you can add it back in the final layers with a small regularization coefficient. It takes about twenty minutes to modify the architecture and five hours to collect uncertainty calibration data on your specific domain. The calibration step is where most people fail. Running fifty forward passes gives you raw uncertainty estimates but they're often miscalibrated. A model might report 80 percent confidence on half its predictions when its actual accuracy is only sixty percent. To fix this, you use temperature scaling. It's a single learnable parameter you fit on a held-out validation set by minimizing negative log likelihood. The whole process takes about three minutes on a modern GPU and usually improves calibration error by forty to sixty percent. After calibration you set decision thresholds. This is where the probabilistic framework earns its keep. Instead of a hard 0.5 cutoff you define a region of uncertainty. Predictions with posterior probability between 0.4 and 0.6 go to a human reviewer or a secondary model. Predictions outside that band are auto-classified. The exact width of that band depends on your cost structure. In my autonomous vehicle project we used 0.35 to 0.65 because a false positive on a pedestrian was cheaper than a missed detection but a false negative on a stop sign was unacceptable. The uncertainty region captured about eighteen percent of all frames and the human review backlog stayed under two hundred per hour on our eight-core processing node.
Common Pitfalls I Wish I Knew Earlier
The first mistake is treating uncertainty as optional post-processing. It isn't. You need to bake it into your training objective from day one. If you train with cross-entropy loss and then try to add uncertainty estimation afterward, the model was never optimized to produce calibrated probabilities. Switch to focal loss or label smoothing during training. Focal loss helps because it downweights easy examples and forces the model to focus on ambiguous boundary cases where uncertainty actually matters. The second mistake is over-relying on a single uncertainty measure. Entropy, variance, and predictive probability each capture different aspects of uncertainty. Epistemic uncertainty reflects missing knowledge. Aleatoric uncertainty reflects irreducible noise in the data. In my road scene classification work I found that entropy and MC dropout variance agreed only sixty-two percent of the time on out-of-distribution samples. The disagreement itself was useful information. When both measures agreed the prediction was highly uncertain. When they disagreed I could usually trace it to a specific failure mode like lighting change versus object occlusion. Here's a specific edge case that almost cost me a client contract. We were classifying medical imaging scans for early tumor detection. The model showed low uncertainty on a particular batch of scans that turned out to be from a different scanner manufacturer. The training data only included one scanner type. The model was confidently wrong and the uncertainty estimates were falsely low because the MC dropout variance hadn't been conditioned on scanner identity. I solved it by adding a scanner metadata embedding to the model input. Training time increased by twelve percent but the false confidence rate dropped from eight percent to under one percent on the new scanner batch. The workaround took me about three days of experimentation after the initial failure.

When Probabilistic Pattern Recognition Completely Fails
I need to be blunt about the limitations because the literature rarely mentions them. The approach breaks down when you have extremely limited training data. If you're working with fewer than five hundred labeled examples per class, the likelihood estimation becomes unreliable regardless of how sophisticated your uncertainty quantification is. In those cases a non-parametric approach like k-nearest neighbors with distance weighting often outperforms deep probabilistic models because it doesn't require estimating complex conditional distributions. The second failure mode is real-time systems with strict latency budgets. Monte Carlo dropout with fifty forward passes adds significant computational overhead. On an embedded GPU like the NVIDIA Jetson Orin, that extra latency can be eighty to one hundred twenty milliseconds per frame. If your system needs sub-thirty millisecond response times you need to switch to deterministic approximations like deep ensembles with only three models or use a cheaper uncertainty proxy like prediction margin. The margin approach measures the gap between the top two predicted probabilities and treats small gaps as uncertain. It requires no extra forward passes and usually captures about seventy percent of the same uncertainty patterns as full MC dropout. There's also the issue of concept drift. A probabilistic model calibrated on data from January will produce unreliable uncertainty estimates by June if the input distribution has shifted. I encountered this with an anomaly detection system for industrial sensor data. The model was well-calibrated for the first four months then the uncertainty estimates started underestimating risk as the factory introduced new equipment. The fix was online calibration maintenance. You re-fit the temperature scaling parameter weekly using a sliding window of recent predictions and ground truth labels. This simple maintenance step extended the reliable operation period from four months to over a year without any model retraining.
Practical Code Structure
Here's the minimal implementation pattern I use as a starting point for new projects. You build a standard PyTorch or TensorFlow model with dropout enabled. During training you use standard cross-entropy or focal loss. At inference time you disable dropout for the baseline prediction but enable it for the uncertainty estimates. You run N forward passes and collect the predicted probability vectors. The mean across those vectors is your class probability estimate. The variance or entropy measures the uncertainty. You compare against your calibrated thresholds and route accordingly. The temperature scaling calibration step is usually a separate script that loads the base model, runs inference on a held-out validation set, and optimizes the single temperature parameter. I typically use the L-BFGS optimizer from scipy for this because it converges in fewer than fifty iterations on well-scaled problems. The whole calibration pipeline runs in under two minutes on CPU for datasets up to ten thousand samples.
For production deployment I package the base model, the temperature parameter, and the uncertainty routing logic into a single Docker container. The container exposes a REST API that accepts image inputs and returns class labels with confidence scores and uncertainty flags. A typical request takes about fifteen milliseconds on a T4 GPU for the baseline prediction plus about one hundred milliseconds for the full uncertainty estimation with fifty MC samples. This is fast enough for most batch processing workflows and acceptable for interactive applications where sub-second response is tolerable. The key insight from my experience is that the probabilistic framework changes how you design the entire system. You stop asking whether the model is right or wrong. You start asking whether the model knows what it knows. That shift in perspective prevents the kind of catastrophic overconfidence failures that killed my first three production deployments.