Why Your Ab Tests Keep Giving You Wrong Answers
I spent about three years running ab tests for an e-commerce platform that did roughly $40 million in annual revenue. We shipped features, measured conversions, called ourselves data-driven, and occasionally made decisions that felt wrong even while the numbers said we were right. The gap between what the test told us and what actually happened in production is where most people lose their edge. Ab testing data analysis sounds like it should be straightforward — you split traffic, you measure outcomes, you call a winner. The reality involves dealing with seasonality, selection bias, novelty effects, and the occasional experiment that looks statistically significant but is just noise pretending to be a signal. Let me walk through how this actually works in practice, including the stuff most tutorials skip.
The Fundamentals of Ab Testing Data Analysis
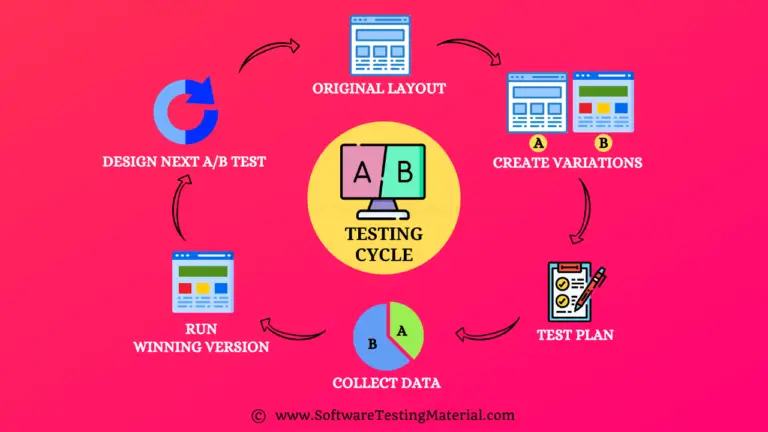
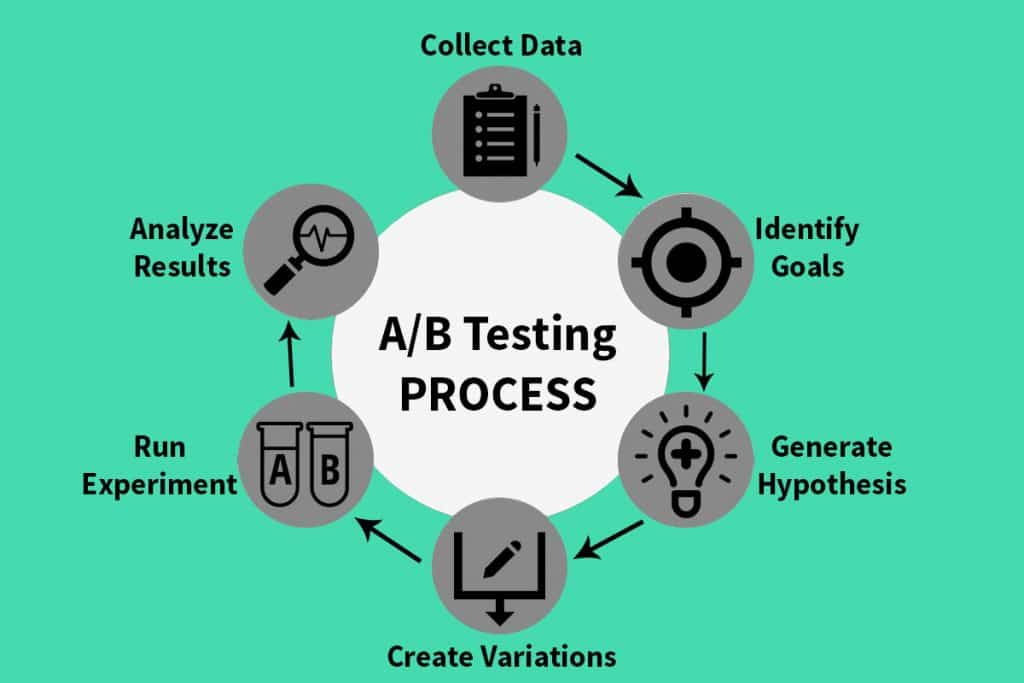
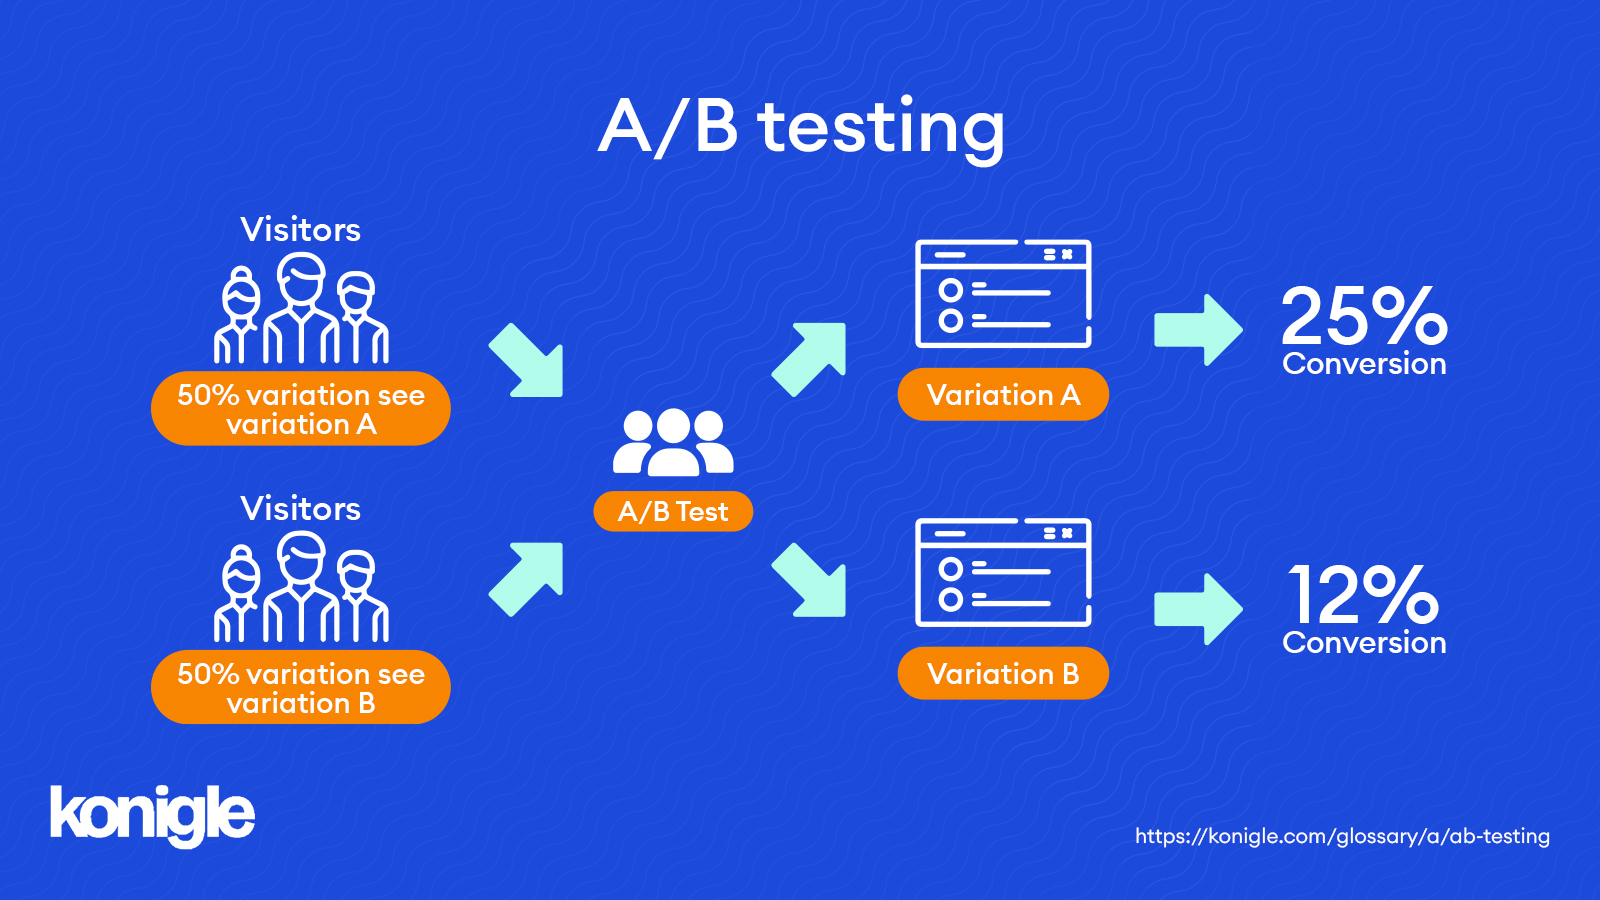
At its core, an A/B test splits your users into at least two groups. Group A sees the control — usually the current version of whatever you are testing. Group B sees the variant — the new feature, button color, pricing model, or whatever you are changing. You then measure a predefined metric, typically conversion rate, revenue per user, or some other business outcome, across both groups over a set period. The statistical part is where people get tripped up. You are not just comparing raw percentages. You need to account for variance, sample size, and confidence intervals. The standard approach uses a two-proportion z-test or a chi-squared test depending on your setup. Most analytics platforms handle this behind the interface, which is convenient until you need to dig into why a result is unreliable. Here is what the actual calculation looks like when you have to do it outside a platform. Say your control group had 50,000 visitors and 3,200 conversions for a 6.4% rate. Your variant had 50,000 visitors and 3,550 conversions for a 7.1% rate. The difference is 0.7 percentage points. Now you calculate the pooled proportion, the standard error, the z-score, and the p-value. If the p-value comes out below 0.05, you reject the null hypothesis and call the variant a winner. This takes about four minutes by hand or thirty seconds in Python.
I learned to stop trusting platform-generated results on tests under 10,000 visitors per variant. The confidence intervals are too wide and the platform often smooths over the uncertainty with overly clean-looking dashboards. Run your own calculation using a tool like Python's scipy.stats module or even a properly configured Google Sheet. It takes maybe twenty minutes to set up the template and then a few seconds per test going forward.
Get the Full Details

Edge Cases That Will Cost You Money
One specific situation I ran into repeatedly was what we called the "Simpson's paradox trap" in our team. We would run a test on a new checkout flow and see a strong positive lift overall. But when we segmented by traffic source, the variant was performing worse for organic search and email users and only better for paid traffic. The overall win was driven entirely by a subgroup that happened to have a higher baseline conversion rate. The workaround was building a segment-level dashboard into our testing workflow that broke down results by traffic source, device, geographic region, and new versus returning users. If any major segment showed a negative or flat trend while the aggregate looked positive, we flagged the test for further investigation before shipping. This added about ten minutes to our review process but prevented at least two bad feature launches per quarter. Another common pitfall is the novelty effect. When you ship a visually different interface, users tend to engage more simply because it is new. This shows up as a spike in the first one to two weeks that decays back toward the baseline. I have seen teams declare a winner after eleven days, ship the variant, and then watch metrics drop back down within a month of wider rollout. The fix is running tests for at least two full business cycles — usually two to four weeks depending on your traffic volume and seasonality. If you are a B2B company with slow decision cycles, plan for six to eight weeks minimum.
Sample Size Calculation Before You Launch
Most teams skip this step or do it lazily. They pick a duration, run the test, and then check if the numbers look good. This is wrong and it biases your results. You should calculate the required sample size before the test starts based on your baseline conversion rate, the minimum detectable effect you care about, and your desired confidence and power levels. For example, if your baseline conversion rate is 4% and you want to detect a 10% relative improvement — meaning you are looking for a shift to about 4.4% — with 95% confidence and 80% power, you need roughly 15,000 users per variant. At 1,000 visitors per day, that is about fifteen days. If you stop early at seven days because the numbers look good, you are working with insufficient power and risk both false positives and false negatives. I use a simple Python script that pulls baseline metrics from our data warehouse, accepts inputs for MDE, confidence level, and power, and outputs the required sample size and duration. It takes about a minute to run. The script also flags when the MDE you are trying to detect is unrealistic given your current traffic levels, which saves time on tests that would otherwise run for months without reaching significance.
When Ab Testing Data Analysis Fails Completely
There are scenarios where ab testing is the wrong tool and smart people still use it anyway. Here are the cases I have seen go wrong: Very low traffic volumes. If you get fewer than 500 daily visitors to a page, your test will either take forever or never reach significance. In these situations, consider multivariate testing with fewer variables or switching to qualitative research methods like user interviews and session recordings. We switched to a heuristic evaluation framework for our internal tools dashboard when traffic was too thin and ended up making better decisions faster. Network effects between groups. When users in the control group interact with users in the variant group, you contaminate the results. Social features, marketplaces, and anything involving user-to-user communication fall into this category. A messaging app test where some users can see new UI elements while others cannot is essentially measuring two different products. Use geohashing or account-level randomization instead of user-level randomization when possible, and acknowledge the limitation in your reporting.

Measuring the wrong metric. I have seen teams optimize for click-through rate on a CTA button and then wonder why revenue dropped. The button got more clicks but attracted lower-intent users or created a confusing flow that reduced actual purchases. Always tie your primary metric to a business outcome, not just a UI interaction. Secondary metrics should support this alignment, not contradict it silently.
Practical Tools I Actually Use
For ab testing data analysis, my go-to stack is Python with pandas for data pulling and transformation, scipy for statistical testing, and seaborn or matplotlib for visualizations. Jupyter notebooks let me document the entire analysis from raw data to final recommendation in one file. Most of my work happens in two notebook types: a template notebook for running standard tests and a segmentation notebook for digging into unexpected results. For teams that do not have Python availability, a well-built Google Sheets dashboard with conditional formatting and built-in statistical functions can handle basic analysis. It is less flexible but gets the job done for simpler tests. The key is consistency — using the same template for every test so that comparisons across time are meaningful. I also recommend keeping a test log spreadsheet that records every experiment you run, its hypothesis, sample size, duration, primary metric, p-value, and business impact after shipping. This becomes invaluable when you need to explain to leadership why a test failed or why you decided against shipping something that looked good statistically. We spent about three hours setting up our log system and it has saved us countless hours in post-mortems and strategy meetings.
Interpreting Results When Nothing Is Significant
The hardest part of ab testing data analysis is dealing with inconclusive results. You run the test, wait the right duration, and the p-value comes out at 0.23. The variant looks slightly better but the confidence interval is massive. What do you do? First, check whether you ran the test long enough. Use your sample size calculation to verify. If the test was adequately powered and the result is still not significant, the honest answer is that you do not know. The variant might help, it might hurt, or it might do nothing. Shipping based on a near-significant result is gambling, not data-driven decision making. Second, look at the effect size and confidence interval, not just the p-value. A p-value of 0.06 with a tight confidence interval around a meaningful effect is different from a p-value of 0.06 with a confidence interval spanning from negative to highly positive. The former suggests you probably need more data. The latter suggests the test was underpowered or the effect is genuinely uncertain.
I once had a variant that showed a 2.1% absolute lift in revenue with a p-value of 0.08 and a confidence interval of plus or minus 1.8%. The team wanted to ship it because the point estimate was attractive. We held it for another two weeks, collected more data, and the confidence interval narrowed to plus or minus 0.9%. The lift was still there but no longer statistically significant. Shipping that variant would have been a mistake. Waiting gave us the clarity to kill it and move on to something else.