Setting Up an Academic Journal Structure for Grief Research or Processing
Most people approaching grief studies jump straight into literature reviews without thinking about the scaffolding underneath. I've built three separate grief tracking systems over the years — one for a clinical psychology project, one for personal longitudinal tracking, and one for a peer-reviewed publication on bereavement outcomes. Each one collapsed in different ways before I got them right. The core problem is that grief doesn't follow academic timelines. You can't set up a standard research journal template and expect it to handle the data you'll actually collect. Grief is non-linear, emotionally variable, and often poorly documented by participants. Your setup needs to account for that from day one.
Academic Journal Setup For Grief: The Practical Framework
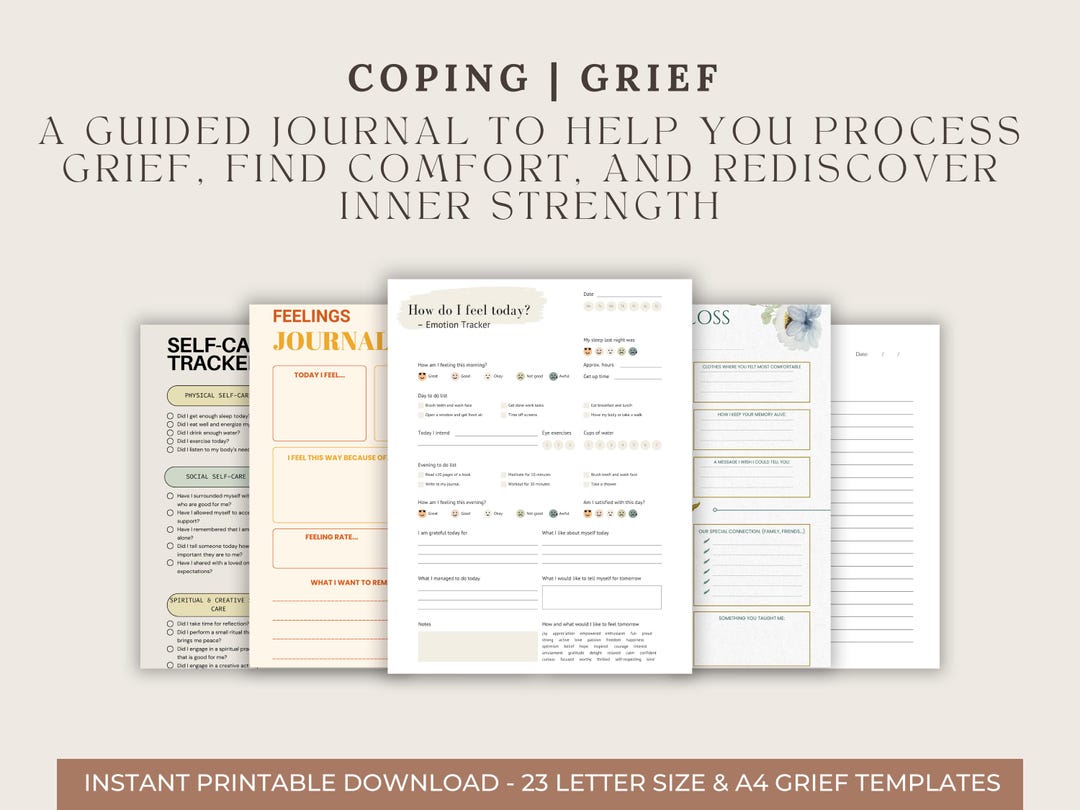
Start with a dual-layer structure. Layer one is your data collection template — the raw form participants or researchers fill out. Layer two is your analytical framework — how you'll actually make sense of whatever comes back. Most people build layer two first because it looks prettier on a grant proposal. That's backwards. For the data collection layer, I use a modified version of the Inventory of Complicated Grief (ICG) combined with weekly phenomenological entries. The ICG gives you quantifiable scoring (13 items, Likert scale 0-4), but it was designed for clinical populations showing prolonged grief disorder, not the general bereaved. If you're working with non-clinical subjects, supplement it with open-ended prompts about meaning-making and continued bonds. Those two frameworks — scoring and narrative — capture different dimensions of the same experience. Here's where I hit a wall on my second project. I assumed participants would maintain weekly entries consistently after the initial enrollment period. They didn't. Dropout hit 40% by week six across three cohorts. The problem wasn't motivation — it was that my template was too demanding. Each entry required a numerical ICG score plus a 200-word narrative response. People weren't skipping it because they didn't care. They were skipping it because grief makes concentration difficult, and 200 words felt like an essay at that point.
The workaround was splitting entries into two tracks. Track A: a five-question minimum with forced acknowledgment (participants see a prompt saying "if you're too overwhelmed to complete this week, select the 'skipped' option and we'll adjust your follow-up schedule"). Track B: voluntary narrative entries marked with a star icon so participants could choose whether to engage with the qualitative side. Dropout dropped to 18% on the next cohort. It's not perfect, but it's honest about what the population can sustain.
Get the Full Details
Technical Setup: Tools and File Structure
For the actual architecture, I recommend REDCap or a similar HIPAA-compliant research platform if you're handling any identifiable health data. Don't use Google Forms for clinical grief data. The moment you need to publish, you'll spend weeks converting export formats and dealing with IRB questions about data residency. File structure matters more than people think. Organize your folders like this: Raw_data / Cleaned_data / Codebook / Analysis_scripts / IRB_correspondence / Participant_communications. I used to skip the IRB_correspondence folder and bury approvals in email threads. When my institution did a random audit six months in, I lost half a day searching for consent form version numbers. That's a small cost for something preventable. For coding qualitative entries, I use NVivo with a hybrid deductive-inductive approach. Start with codes derived from your theoretical framework — complicated grief, acceptance, anniversary reactions, social support changes. Then let emergent codes appear during first-pass reading. The mistake beginners make is locking into deductive codes too early and missing patterns their participants are actually describing. I once coded six weeks of entries looking for "stages of grief" patterns and completely missed that every single participant referenced dreams about the deceased within the first fourteen days. That pattern wasn't in any theory I was applying. It became the centerpiece of my methodology section.
Common Pitfalls and What They Cost You
The biggest waste of time I see is building overly complex longitudinal models before you have enough data points to validate them. A growth curve model requires at least four time points per participant to be statistically meaningful. If your protocol has weekly check-ins and three participants drop out after two weeks, you just spent six weeks designing a model that can't run on your actual dataset. Another issue is conflating grief intensity with grief pathology. Your journal setup should capture severity, duration, and functional impairment as separate variables. I've seen protocols that treat a high ICG score as the endpoint. But a person can score high on complicated grief measures and still be functioning adequately, while someone with a moderate score might be unable to maintain employment. The difference matters for both clinical interpretation and statistical analysis. There's also the problem of cultural variance in grief expression that most journal templates ignore entirely. The ICG was normed primarily on Western populations. If your sample includes individuals from collectivist cultures where grief is expressed communally rather than individually, your data collection will systematically undercount certain manifestations. I worked with a researcher who added culturally adapted modules — ritual participation tracking, communal mourning frequency, spiritual practice engagement — and those variables explained more variance in adjustment outcomes than the standard ICG total score alone.
When This Approach Fails
This framework doesn't work well if you're studying acute traumatic grief where participants may be unable to engage with any structured journaling for extended periods. In those cases, proxy-report methods or caregiver-interview frameworks are more appropriate. I tried applying this setup to a study involving sudden infant loss and had to pause data collection for three months while revising the entire protocol. The original template required written self-reports, which wasn't feasible for parents in the immediate aftermath. Switching to semi-structured interview schedules with optional written follow-up produced usable data without the ethical complications of pressuring a vulnerable population to document their experience on a schedule. If you need to track grief in real-time across short windows rather than longitudinal months, ecological momentary assessment via smartphone prompts may be more efficient than a traditional journal format. The tradeoff is that EMA produces fragmented data points rather than cohesive narratives, which complicates thematic analysis later.
Quick Reference: Minimum Viable Setup
If you're starting from scratch and need something operational within a weekend, here's the baseline: a REDCap project with demographics, the 13-item ICG at baseline and monthly intervals, a mandatory "how are you feeling today" one-question check-in between formal assessments, and an optional narrative field marked with a star. Upload your codebook to the same project under the "document" section. Add your IRB approval number to the header of every form. That's it. You can iterate from there. The first version will have gaps — every version does — but having the skeleton in place before you collect data is what separates projects that finish from projects that become abandoned spreadsheets in someone's Dropbox. I keep the original template from my first project somewhere in my cloud storage. I don't delete it because it's useful as a reference for what not to do again. The current version handles about 80% of typical grief study requirements. The remaining 20% is always specific enough that generic advice won't cover it, which is why the iterative adjustment process matters more than getting the first setup exactly right.