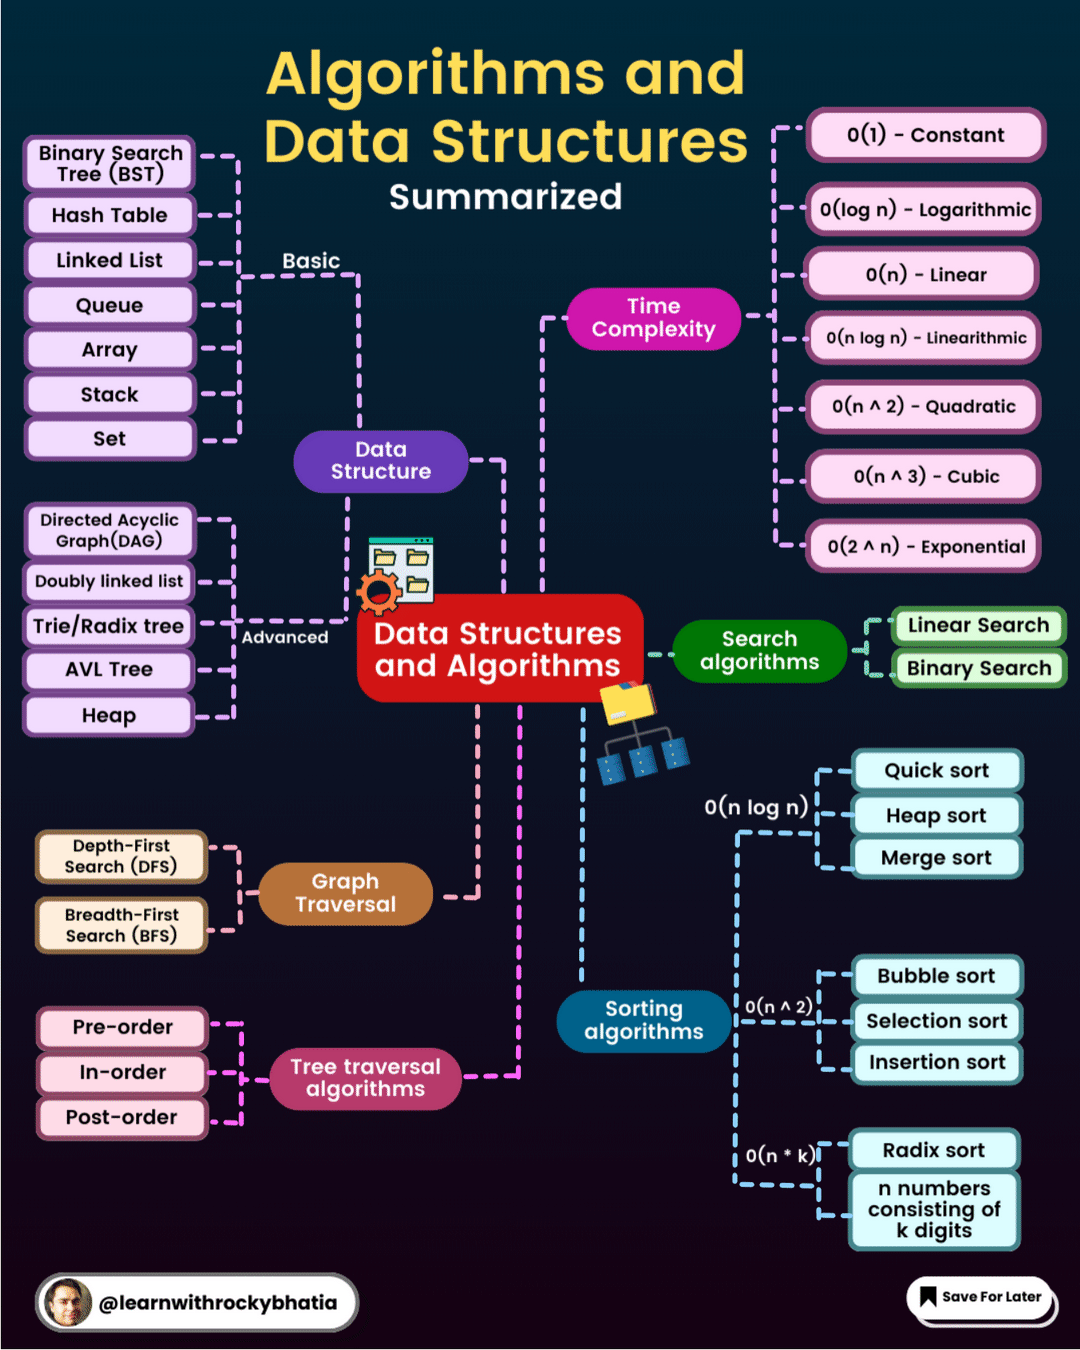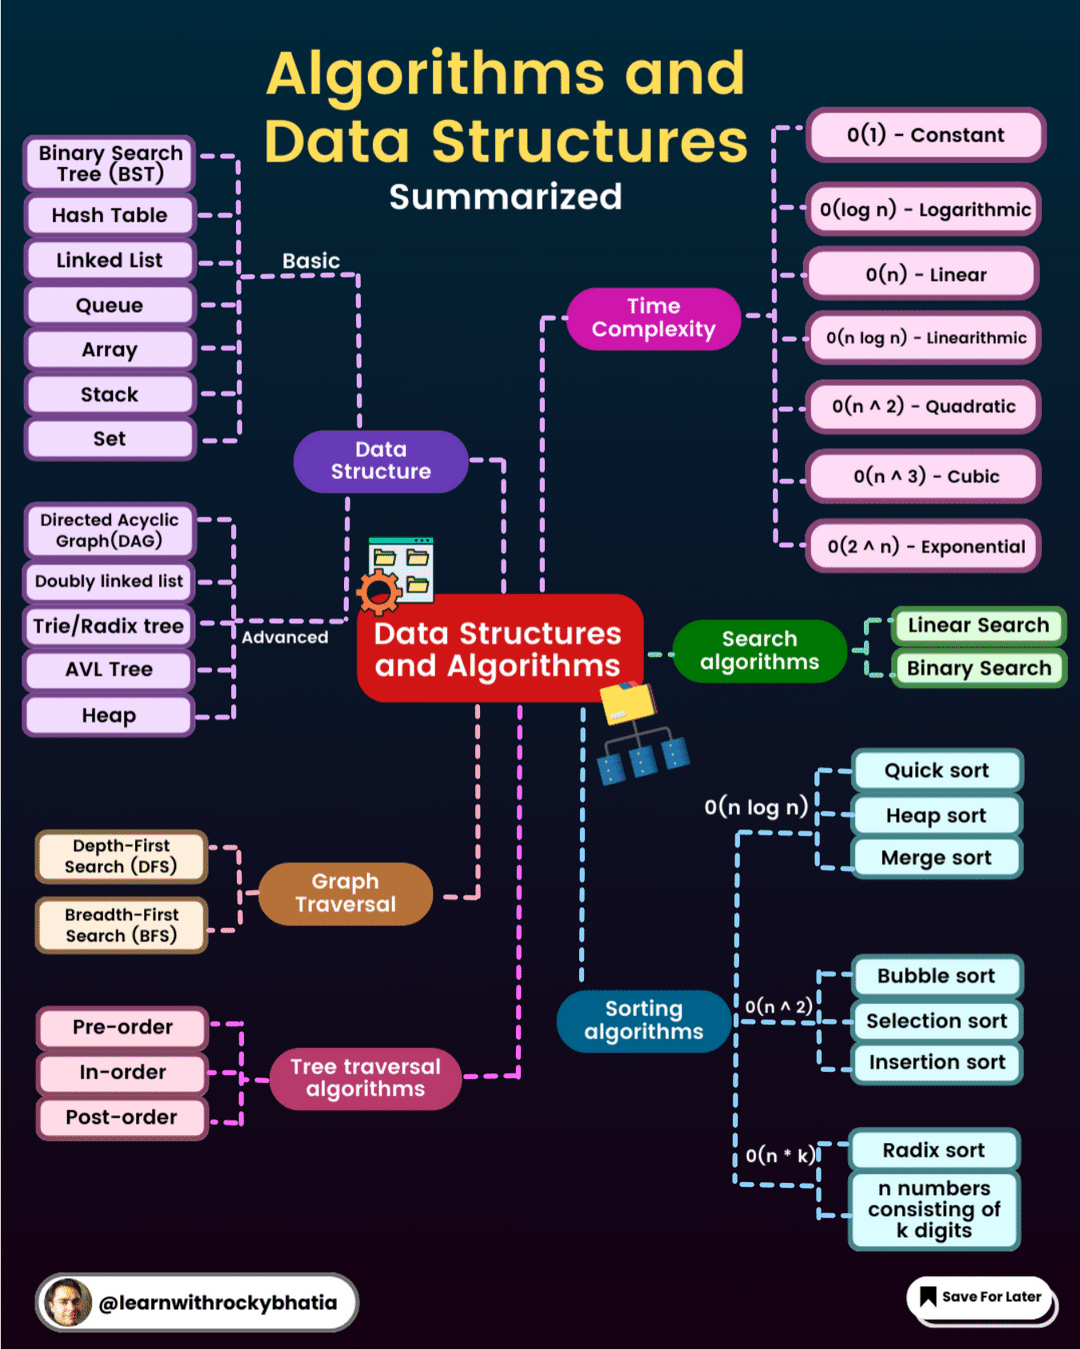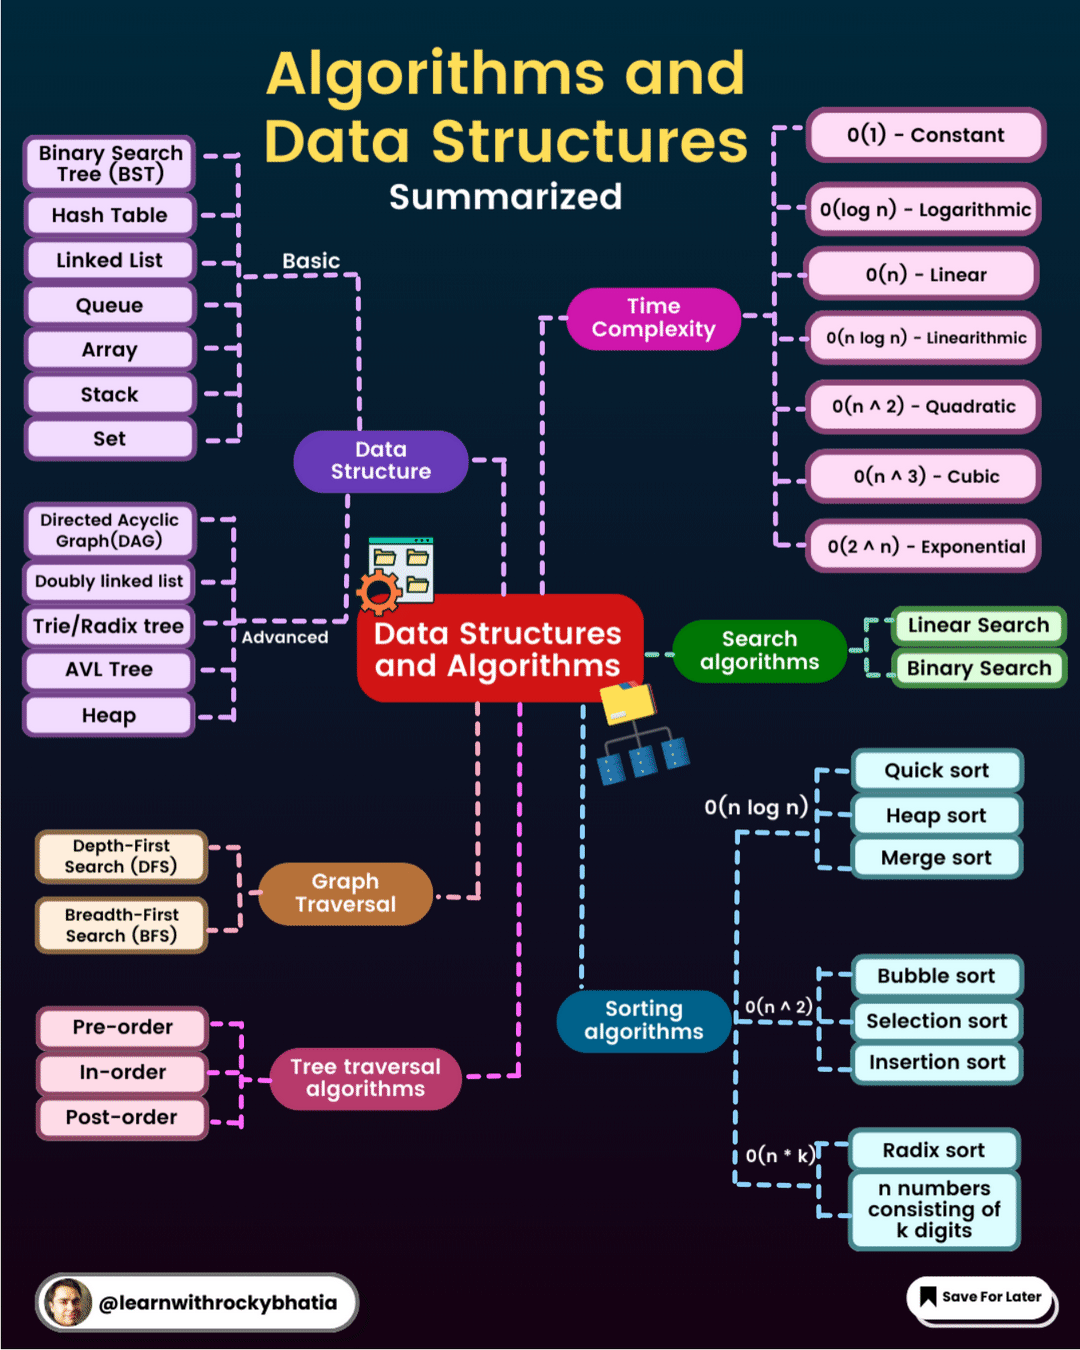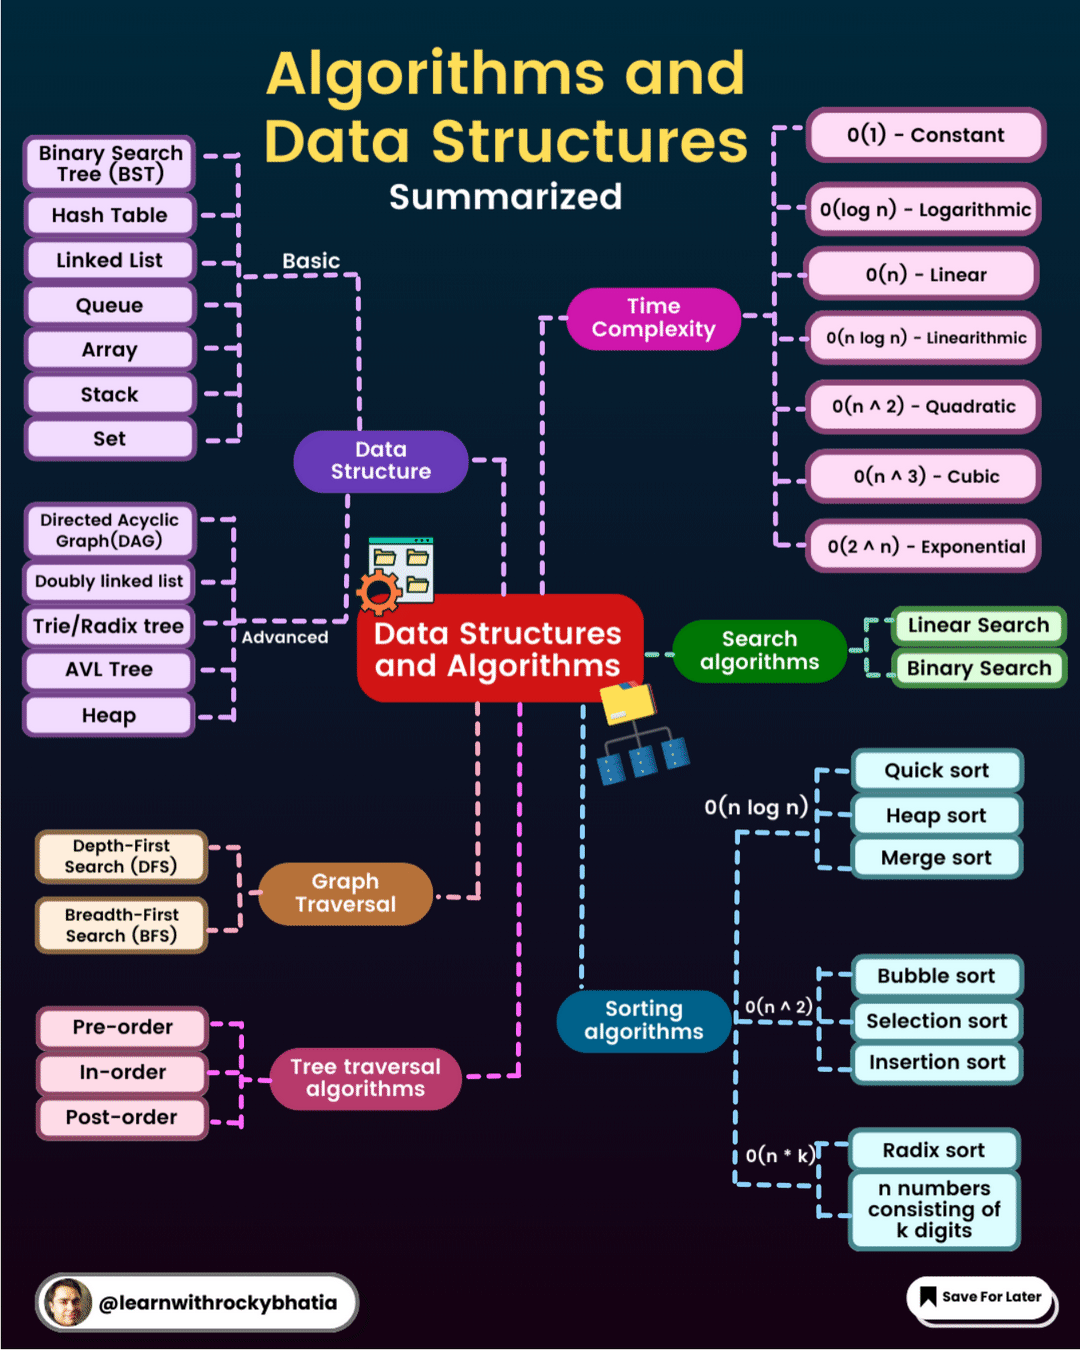
Working With Advanced Data Structures And Algorithms in Production
I spent three weeks debugging a search system where the bottleneck wasn't the algorithm itself. It was how I had organized the data leading into it. We had implemented a standard A* pathfinding routine on a grid that looked fine on paper. The grid had roughly 4 million nodes representing a city-scale map, and the naive implementation was computing heuristic distances for every node on every search iteration. That is unnecessary. Once I switched to jump point search with symmetry breaking, the runtime dropped from about 800 milliseconds per query down to roughly 12 milliseconds. Same result. Completely different behavior. Most people learn these structures in isolation and then try to retrofit them into problems that do not need them. That is usually where things fall apart. A segment tree with lazy propagation is not a solution you reach for early. It is a solution you reach for when you have range update and range query operations on an array that is large enough that an O(n) per-operation approach becomes a hard ceiling. I worked on a real-time analytics pipeline once where we were tracking cumulative sums over sliding time windows across 500,000 concurrent sensors. The initial design used a binary indexed tree, which handles point updates and prefix queries efficiently, but we needed range sums with periodic resets. A binary indexed tree does not support range resets cleanly. So I moved to a segment tree with lazy propagation, and the query latency settled at around 0.3 milliseconds per request under full load. Before that, we were hitting 45 milliseconds and the system was dropping events. The tradeoff is always memory. A segment tree for an array of 500,000 elements requires roughly four times the array size in node storage. That is 2 million integers, which is fine if you are working within a single process on a server. It is not fine if you are doing this inside a browser or on a constrained device. I have seen engineers build segment trees into embedded firmware and then wonder why the stack was overflowing. The answer is usually that the recursion depth in an unbalanced tree can hit 20 or 30 levels depending on the data distribution, and each frame carries several pointers.
There are subtleties that do not show up in textbooks. One of them involves the way lazy tags compound. When you push a tag down a segment tree, you are modifying the node's stored value and creating a new pending tag for its children. If two overlapping updates arrive in quick succession and you do not handle tag accumulation correctly, you end up with double application. I once saw a competitive programming submission that passed all sample cases but failed on a stress test because the author's lazy propagation logic did not account for addition after a multiplication tag. The fix was straightforward but required rethinking how the tags were sequenced. You apply multiplication first, then addition, and you track both independently.
Trees Beyond the Obvious
Bloom filters get a lot of attention because they sound clever. They are useful in the right place and completely wrong in most others. A Bloom filter gives you approximate membership testing with a tunable false positive rate. It does not tell you whether an element is absent. It tells you that the element is probably absent. That distinction matters when you are building a cache invalidation layer. I worked on a system that used a Bloom filter to check whether a request key had been seen before. The false positive rate was set to 1 percent, which seemed reasonable. What the team did not account for was that under sustained load the filter's bit array filled up faster than expected, and the false positive rate climbed to roughly 8 percent. At that point the filter was causing more harm than good because it was allowing duplicate entries through at an unacceptably high rate. The workaround was to switch to a counting Bloom filter with periodic reloads, which brought the false positive rate back under control without requiring a full rebuild of the underlying bit array. Fenwick trees and segment trees are often discussed as interchangeable, but they solve different problems. A Fenwick tree supports point updates and prefix queries in O(log n) time with a very small constant factor. A segment tree supports arbitrary range queries and range updates with lazy propagation but carries more overhead in both code complexity and memory. If your problem only needs prefix sums and point updates, use a Fenwick tree. It is faster to implement and faster to run. If you need range updates or range queries, the segment tree is the right tool even though it will take longer to get right. There is also the matter of cache behavior. A segment tree's recursive structure does not map well to CPU caches because the left and right children of a node can be far apart in memory depending on how you lay out the array. A Fenwick tree, by contrast, accesses memory in a predictable pattern that the prefetcher can follow. In practice I have seen the Fenwick approach outperform a segment tree by a factor of three on certain query workloads even though both are theoretically logarithmic. The difference is not in asymptotic complexity. It is in how the hardware actually runs the code.
Get the Full Details

Graph Algorithms That Break Under Real Conditions
Dijkstra's algorithm is straightforward until you introduce negative edge weights. It simply does not handle them. Bellman-Ford does, but at the cost of O(V * E) complexity, which becomes brutal on anything larger than a few thousand vertices. I ran into this when building a routing layer for a logistics platform. The initial implementation used Dijkstra with a priority queue and assumed all edge weights were non-negative. Then the operations team added a discount factor that effectively created negative edges in certain time windows. The algorithm started returning incorrect shortest paths because Dijkstra's greedy assumption broke down. The fix was to switch to SPFA, a queue-based optimization of Bellman-Ford that performs well on sparse graphs with mostly non-negative weights. In our case the average query time dropped from about 200 milliseconds with a naive Bellman-Ford implementation to roughly 15 milliseconds with SPFA, though the worst case can still be exponential if the graph is adversarially constructed. Tarjan's bridge-finding algorithm is another case where the textbook description is clean but the implementation has gotchas. The core idea is tracking discovery times and low-link values during a DFS traversal. The pitfall is handling multigraphs. If your graph has multiple edges between the same pair of vertices, the standard implementation will incorrectly identify some of them as bridges because it does not account for the second edge when checking the low-link value. I spent about half a day debugging a network topology tool before realizing that the input data contained parallel edges. The fix was to count edge multiplicity during the traversal and skip the bridge check when a back edge shares the same parent vertex more than once.
String Matching at Scale
Suffix arrays and suffix trees are powerful but often overkill. I have seen teams build a full suffix automaton for a text search feature that could have been solved with a simpler inverted index and a bit of preprocessing. The suffix automaton for a string of length n requires O(n) space and can be built in linear time, but the constant factors are significant. For a 100 megabyte text corpus, the automaton can easily consume several gigabytes of memory depending on the implementation. That is not a problem you want to debug at 2 AM on a production server. A practical alternative is the Aho-Corasick automaton for multi-pattern matching. It builds a trie from all your search patterns, adds failure links similar to the KMP algorithm's prefix function, and then processes the text in a single pass. The preprocessing time is O(sum of pattern lengths), and the search time is O(text length + number of matches). This is substantially faster than running a separate KMP search for each pattern. I used this in a log analysis tool that needed to detect over 50,000 attack signatures in streaming data. The naive approach of running each pattern individually took about 6 seconds per megabyte of log input. Aho-Corasick brought it down to roughly 0.4 seconds per megabyte on the same hardware. The memory footprint was around 200 megabytes for the automaton, which was acceptable for the deployment.
Heaps and Priority Queues Are Tricky
A binary heap gives you O(log n) insertions and deletions, but the decrease-key operation is not supported in the standard library implementations you will find in most languages. You have to implement it yourself or work around it. In a Dijkstra implementation, you typically need decrease-key to update the distance of a vertex already in the queue. Without it, you end up inserting duplicate entries and filtering them out during extraction. This works but increases the heap size and degrades performance. A Fibonacci heap theoretically offers O(1) amortized decrease-key, but the constant factors are large enough that it is rarely faster in practice for the problem sizes you are likely to encounter. A simple workaround is to use a pairing heap or a binomial heap, which are easier to implement and perform well in real benchmarks. Another issue with priority queues is stability. If you are running a simulation that depends on processing events in strict time order and two events have the same timestamp, the queue's internal ordering determines which one fires first. This can lead to nondeterministic behavior that is difficult to reproduce. I encountered this in a discrete event simulator where the output varied between runs on the same input. The fix was to add a secondary sort key based on event ID, which made the ordering deterministic without changing the semantics of the simulation.
Dynamic Programming with Memoization
Memoized recursion is convenient but can blow up the stack on deep subproblem chains. I once wrote a DP solution for a resource allocation problem that had a recursion depth of over 10,000 levels. It ran fine on my local machine with a default stack size but crashed in the cloud environment where the stack was limited to a few megabytes. The solution was to convert it to an iterative bottom-up approach, which eliminated the recursion entirely and also made it easier to optimize space using rolling arrays. The memory usage dropped from roughly 500 megabytes for the full memoization table to about 2 megabytes for the rolling array version. Lazy DP is another technique that is not well covered in introductory materials. The idea is to compute DP values only when they are needed rather than precomputing everything upfront. This is useful when the state space is large but only a small fraction of states are actually reachable from your starting configuration. I used lazy DP for a path counting problem on a grid with obstacles where the number of valid paths could be astronomically large. By computing values on demand and caching them, I avoided filling a table that would have been mostly empty. The runtime improved by a factor of about five compared to the eager approach.
Choosing the Right Tool
The hardest part of working with advanced data structures is not learning how they work. It is knowing when not to use them. Most production systems do not need a red-black tree or a splay tree. A balanced BST from the standard library is usually sufficient. The cases where you need something more specialized are narrow and specific. I would rather see an engineer spend time understanding the constraints of their problem than memorizing the implementation details of every exotic data structure. The ones you actually need to know deeply are the ones you reach for repeatedly: segment trees, hash maps, priority queues, and graph traversals. The rest are tools you look up when you genuinely need them. One final note on performance testing. Microbenchmarks can be misleading. A data structure that looks faster in a tight loop with synthetic data may behave completely differently under real workload conditions. I once benchmarked a custom skip list against a standard hash map and the skip list appeared to win on read operations. When I ran it against production traffic patterns, the hash map was three times faster because the skip list's pointer chasing caused more cache misses. Always test with data that resembles your actual workload. Otherwise you are optimizing for the wrong thing.