Most people use about five percent of what Excel can do and wonder why their spreadsheets are slow and breaking
I spent last Tuesday trying to figure out why a lookup across a 40,000-row table kept returning #N/A when the value clearly existed in the dataset. The problem wasn't the function. It was that one column had mixed text and numbers stored as text, and XLOOKUP refuses to coerce types the way older functions sometimes did by accident. I spent forty minutes running a CLEAN and VALUE wrap across both ranges before I caught it. This is the gap between knowing Excel functions and actually using Advanced Excel Functions And Formulas in production. The difference is mostly about understanding edge cases, not about memorizing syntax.
Advanced Excel Functions And Formulas that actually move the needle
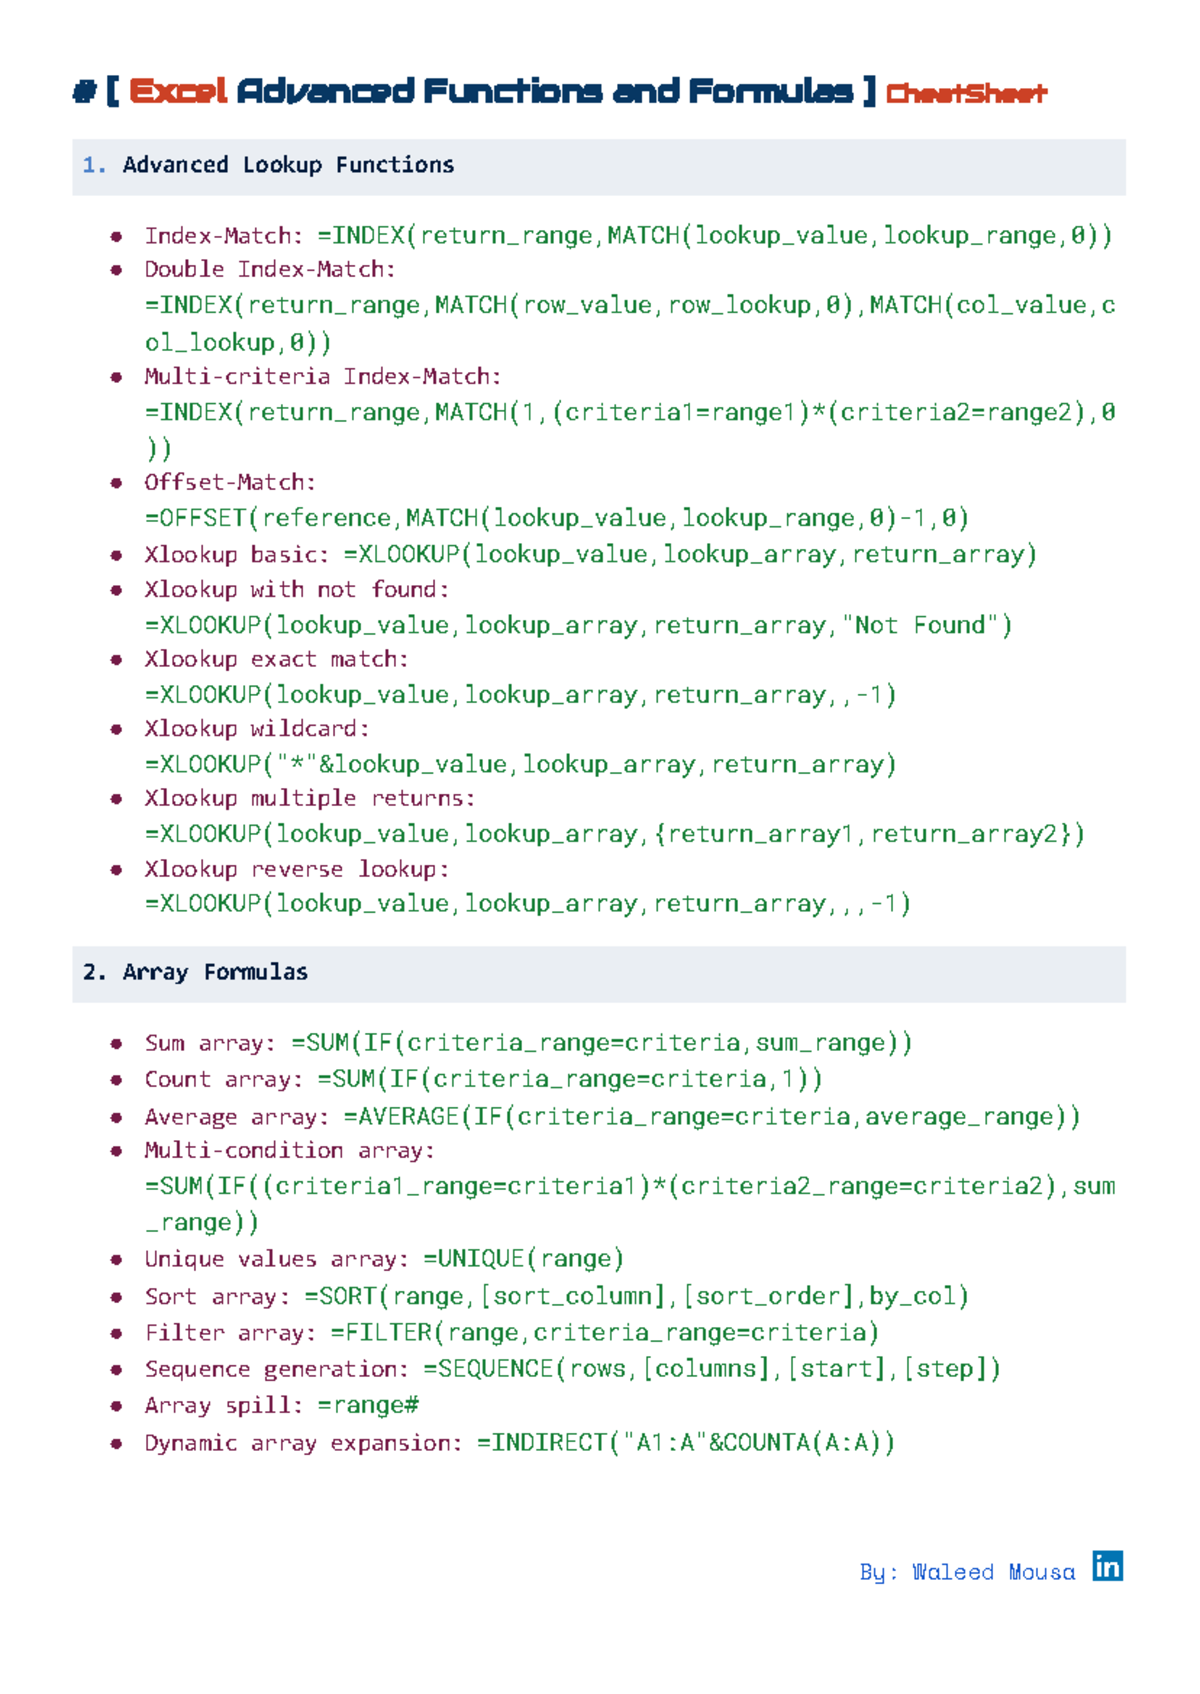
XLOOKUP replaced VLOOKUP for most people, but the real shift happened because of how it handles errors natively. You no longer need IFERROR wrapping every single call. The syntax is XLOOKUP(lookup_value, lookup_array, return_array, [if_not_found], [match_mode], [search_mode]). The match_mode and search_mode arguments are where most people stall out. Match_mode -1 finds the next smaller item and 1 finds the next larger item. Search_mode 2 searches first-to-last and -1 searches last-to-first. These two flags alone solved a quarterly reconciliation problem I had where I needed to find the most recent transaction date that didn't exceed a cutoff date. A nested MAX with conditions would have taken eight steps. XLOOKUP with match_mode -1 and search_mode -1 did it in one. Then there's LET. It sounds like syntax decoration until you write a formula that calculates the same intermediate value three times inside a single expression. LET lets you name that value once and reuse it. I had a weighted average calculation where the denominator was a SUMPRODUCT of quantities and prices divided by total quantity, and the total quantity appeared in two different branches of the logic. Without LET I was duplicating the aggregation logic and introducing a mismatch because one branch used a filtered range and the other didn't. With LET I defined total_qty once, passed it through, and caught the mismatch in five minutes instead of spending an hour comparing two nearly identical nested formulas. LAMBDA functions are the third piece that changed how I think about these tools. They let you build custom functions without VBA. The syntax LOOKUP(, LAMBDA(x, x*2)) is straightforward. The harder part is recursive LAMBDAs, which require the LAMBDA to reference itself by name. Excel's approach uses NAMEs defined in the Name Manager with a self-reference trick. It works but it is fragile. If someone renames the function or copies the workbook to a new environment, the recursion breaks silently and you get a #NAME? error that points at nothing helpful.
The functions that matter most in practice
SUMIFS and COUNTIFS are the workhorses but most people use them wrong. The criteria range and the sum range must be the same size and shape. If you apply SUMIFS to a dynamic range that grows unevenly, you get wrong totals and no error to warn you. I learned this the hard way when a manager copied a template and pasted data into column B without adjusting the SUMIFS range, which was hardcoded to B2:B500. The actual data went to row 720. The function returned a sum that looked correct because it was summing the right cells, just not all of them. Using named ranges or Excel Tables fixed this permanently because the range expands automatically. INDEX and MATCH combined is still faster than XLOOKUP in some situations, specifically when you need bidirectional lookups across two dimensions. XLOOKUP can handle arrays now but INDEX/MATCH remains useful when you are building a matrix where both the row and column criteria vary. The formula structure is INDEX(return_range, MATCH(row_criteria, row_range, 0), MATCH(column_criteria, column_range, 0)). It looks long but it runs fast on large datasets because it does two separate column scans instead of crossing every row against every column like a brute-force approach would. FILTER is the function that made me realize how much time I wasted on manual filtering and copy-pasting. FILTER(range, criteria, [if_empty]) returns a dynamic array that spills into adjacent cells. The spill behavior is what makes it powerful and also what makes it dangerous. If something blocks the spill range, you get a #SPILL! error and the rest of your sheet breaks. I had a dashboard where a FILTER result spilled into a cell that contained a manually typed summary note. The entire layout shifted and every downstream reference broke. The workaround was wrapping the FILTER in a TOROW or TOCOL conversion and anchoring the output with a fixed table, or just accepting that dynamic arrays need breathing room around them.
Get the Full Details

Where these tools actually fail
Dynamic arrays are the biggest quality of life improvement in recent Excel history and also the biggest source of support tickets. When a formula spills, it creates a region dependency. Any operation that writes to that region fails. Any delete operation on a spilling cell deletes the entire array and recalculates everything tied to it. This is fine until you share the file with someone using Excel 2019 or earlier, at which point the spill syntax breaks and returns #SPILL! across the board. If you need backward compatibility, you cannot use FILTER, SORT, UNIQUE, or any function that relies on implicit intersection with arrays. Power Query is not an Excel function. It lives in a different engine entirely. But it is worth mentioning because it solves problems that Advanced Excel Functions And Formulas handle poorly. When you are merging five CSV files from different departments, each with slightly different column orders and encoding issues, trying to do that with TEXTSPLIT, CONCAT, and INDEX/MATCH is an exercise in frustration. Power Query handles the merge, transformation, and refresh cycle in a repeatable pipeline. The learning curve is real but the payoff is immediate for anything involving repeated data assembly. I moved a monthly consolidation process that took three people eight hours down to a single button click that runs in about four minutes. The formula-based version would have been twice as long to build and half as reliable. Another hard limitation: Excel's calculation engine is serial for most operations. Complex nested arrays with hundreds of thousands of rows will recalculate slowly no matter how optimized the formulas are. If you have a model that hits sixty-second recalculation times, the problem is usually array volatility from functions like OFFSET, INDIRECT, or full-column references in SUMPRODUCT. Switching those to explicit ranges or using INDEX with a defined last row cuts recalculation time dramatically. I had a workbook where replacing three full-column SUMPRODUCT calls with explicit range references using INDEX reduced recalculation from 47 seconds to 6 seconds. The formulas became longer but they ran faster because Excel stopped evaluating empty cells in columns Z through IV.
What to learn first and what to skip
Master XLOOKUP with match_mode and search_mode before you touch LAMBDA. Master Excel Tables before you touch Power Query. Master named ranges before you try to build a custom dashboard that other people will maintain. Every person I have seen struggle with advanced Excel is usually struggling because they skipped the foundation. They learned a fancy function and then built something on top of it that collapsed when the data structure changed slightly. The practical path is to pick one recurring task and automate it completely. Not partially. Completely. A task you do every week that involves pulling data, matching it to another source, transforming it, and producing a summary. Build the solution with the tools you have. When it breaks, learn the function that would have prevented the break. This is how the knowledge sticks. Reading about LET does not teach you LET. Writing a formula where LET saves you from a ten-layer nesting mess does. The functions themselves are straightforward. The expertise is in knowing which ones to combine, which ones to avoid, and what happens when the data does not behave the way the documentation assumes it will. That part comes from breaking things and fixing them.