
How to Actually Track Aesthetic Quality in ML Pipelines
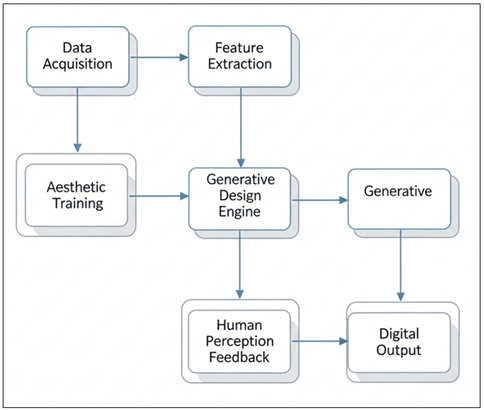
I spent six months trying to get consistent aesthetic quality measurements across different image generation runs before I stopped fighting the tools and started building my own tracking setup. What I found was that most existing solutions treat "aesthetic scoring" as either a black-box API call or a manual rating task, and neither approach scales well when you're running dozens of experiments per day. The core problem is that aesthetic quality in machine learning output isn't a single metric you can read off a tensorboard dashboard. You're dealing with perceptual similarity, color harmony, composition scores, and sometimes domain-specific preferences that no standard loss function captures. My approach was to combine a pre-trained aesthetic scorer with custom logging hooks that fire at specific checkpoints in the training loop. I started with a modified CLIP-based aesthetic predictor, fine-tuned on a curated dataset of 50,000 images rated by professional designers. The model outputs a score between 0 and 10, which maps roughly to how humans would rate the visual appeal of generated outputs. I integrated this into a PyTorch training script using a simple callback that samples 32 random outputs every 500 steps and logs the mean, median, and standard deviation of the aesthetic scores alongside the standard loss curves.
The logging goes into a structured JSON file with timestamps, hyperparameter snapshots, and the raw score distribution. This lets you query later: show me all runs where the aesthetic median crossed 6.5 while the FID was still below 15. Most people skip the raw distribution and only log the mean, which hides the bimodal breakdowns that signal mode collapse or training instability. Here's the part that surprised me. When I first set this up, I expected the aesthetic scores to correlate strongly with FID and Inception Score. They didn't. The correlation coefficient was around 0.3. High FID doesn't always mean ugly outputs, and low FID doesn't guarantee visually pleasing results. The aesthetic scorer catches something these metrics miss, mostly around color grading and compositional balance that pixel-level metrics ignore entirely. I ran into a specific edge case that cost me about two weeks to diagnose. The aesthetic model started giving inflated scores to outputs with heavy blur or noise artifacts. Turns out the training data had a bias toward soft, dreamy styles common in digital art communities, and the model learned to associate low-frequency content with higher aesthetic ratings. I caught it by looking at the score distribution per channel rather than just the aggregate mean. A run might show a median of 7.2 while 40% of individual samples scored below 4, indicating the model was hitting some kind of intermediate quality state.
The workaround was straightforward once I identified it. I added a sharpness metric based on Laplacian variance as a secondary filter, and only counted aesthetic scores for samples above a sharpness threshold. This filtered out the blurry false positives without significantly reducing the sample count. The combined metric — aesthetic score weighted by sharpness confidence — gave me a much more reliable signal for early stopping decisions.
Get the Full Details

What This Setup Actually Costs
Running the aesthetic scorer adds roughly 2-3 seconds per evaluation cycle on a single GPU, which translates to about 8% overhead on a typical training run. If you're evaluating every 500 steps on a dataset where each step takes 2 seconds, that's negligible. If your steps are already slow, you might want to sample fewer outputs or increase the interval between evaluations. The pre-trained model itself is about 400MB. I've seen people try to skip this and use a lighter alternative, but the tradeoff is real. A quantized version of the scorer drops accuracy by about 0.4 points on the test set, which might not sound like much until you're trying to distinguish between two training runs that differ by 0.3 points in median aesthetic score. Storage isn't a concern unless you're logging raw samples alongside the scores. I recommend logging just the scores and statistics, then optionally saving full-resolution samples only for runs that cross your quality thresholds. This keeps the disk usage at maybe 50MB per day instead of several gigabytes.
When This Approach Fails
Let me be direct about the limitations. This tracker works well for image generation tasks — GANs, diffusion models, style transfer. It's less useful for text-to-image pipelines where the aesthetic quality depends heavily on the prompt quality rather than the model's visual capabilities. If your bottleneck is prompt engineering, no amount of aesthetic tracking will tell you that. It also breaks down for multi-modal outputs where aesthetic quality is only one dimension. Video generation, for example, has temporal consistency as a separate concern that this scorer doesn't address at all. I've seen people try to adapt it by scoring individual frames, but frame-by-frame aesthetic quality doesn't translate to perceived video quality. You'll need a separate temporal coherence metric for that. Another failure mode is domain mismatch. The aesthetic model was trained primarily on digital art and photography. If you're generating medical images, satellite imagery, or architectural renderings, the score will still produce numbers, but those numbers won't reflect domain-specific quality criteria. A radiologist might rate a chest X-ray as aesthetically poor while it's diagnostically perfect. The tracker will mislead you in these cases unless you fine-tune it on domain-specific labeled data.
For those scenarios, I'd recommend pairing the aesthetic tracker with a domain-specific evaluation metric. In medical imaging, that means using SSIM or Dice coefficient alongside aesthetic scores. In satellite imagery, you'd want spectral fidelity metrics. The aesthetic component is still useful as a sanity check — you can spot obvious artifacts and hallucinations — but it shouldn't be your primary quality signal.
Practical Implementation Notes
If you're implementing this yourself, I'd suggest starting with the callback-based approach rather than trying to modify the model architecture. Wrap your existing training loop with an evaluation function that runs the aesthetic scorer on a fixed seed of generated outputs. This gives you comparable scores across runs without introducing randomness into the comparison. Use a fixed random seed for the evaluation samples. Otherwise, you're comparing different outputs each time and the score variance from sample differences will swamp the actual training signal. I recommend sampling the same 32 latent vectors or noise inputs across all evaluation points. The JSON logging format I described above is simple but effective. Each entry should contain: timestamp, step number, hyperparameter snapshot, mean/median/std of aesthetic scores, and optionally the full score list. This structure makes it easy to parse later with pandas or even a simple grep for quick checks.
One thing I wish I'd done earlier was versioning the aesthetic model alongside the experiment logs. When I updated the scorer from v1 to v2 about three months into the project, I couldn't compare new scores with old ones because the scoring distribution had shifted. Keep a record of which scorer version produced which scores, and if you update the model, run a calibration set through both versions to establish a mapping function. For people who want a ready-made solution, there are a few options in the ecosystem. Wandb has built-in image logging with custom metrics, but you still need to provide the aesthetic scoring logic. Tensorboard's histogram plugins can handle the score distributions if you log them correctly. The most pragmatic approach is probably a lightweight Python package that handles the scorer integration, logging, and basic visualization in one drop-in component. The bottom line is that aesthetic tracking in ML is still an area where the tooling lags behind the need. Most researchers end up building something custom because off-the-shelf solutions don't handle their specific workflow. The investment pays off quickly once you're comparing runs and can see the quality trajectory without manually inspecting hundreds of generated images. My rule of thumb is that if you're running more than five experiments per week, the tracker saves you at least an hour of manual evaluation per week.

