Processing African American Vernacular English in Production Systems
Most people who work with speech recognition or NLP pipelines hit the same wall: models trained on standard American English just fall apart when they encounter African American Vernacular English. Not because AAVE is "incorrect" English, but because the phonological and grammatical patterns are different enough that word error rates can jump from 10% to over 40% on the same audio. I learned this the hard way about three years ago when I was debugging an internal voice assistant for a healthcare client. The issue wasn't even the vocabulary. AAVE speakers using standard medical terminology were being transcribed incorrectly at alarming rates. "I've been having pain in my chest" came back as "I've been having paint in my mesh." That's not a humor situation. The model was mishearing the velar nasal /ŋ/ as a bilabial /m/ in certain phonetic contexts, which is a known gap in models trained predominantly on General American speech. We ended up spending six weeks collecting AAVE-specific test data before we could deploy that pilot.
African American Vernacular English: What It Actually Is
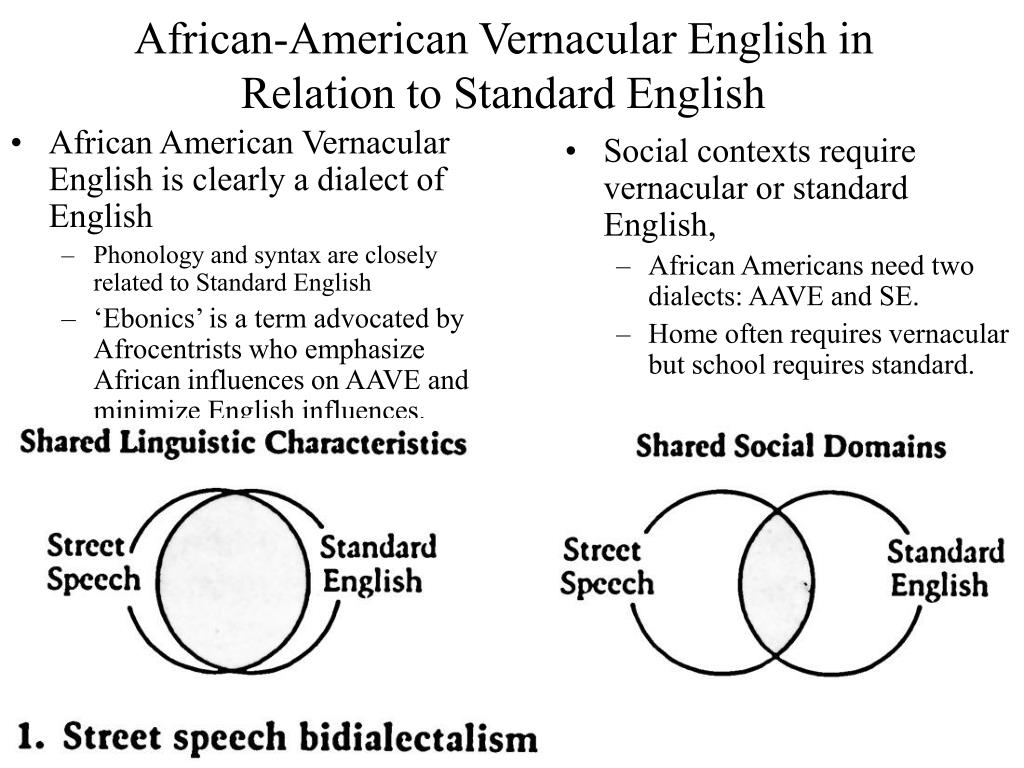
AAVE is a fully systematic dialect of English with its own consistent phonological, morphological, and syntactic rules. It's not slang. It's not broken English. It has regular sound substitution patterns, specific tense-aspect markings, and grammatical structures that operate predictably. When linguists describe the habitual "be" — as in "She be working" — they're talking about a marker that indicates ongoing or repeated action, distinct from the simple present "She works" or the progressive "She is working." These distinctions exist in AAVE but not in General American English, and native AAVE speakers can reliably distinguish between them. The phonological features are what break most ASR models. Consonant cluster simplification, like rendering "desk" as "dess" or "test" as "tes," is systematic, not random. The deletion of final consonants in clusters follows predictable phonological rules. Postvocalic /r/ deletion is another feature, though its presence varies by region and individual speaker. Vowel shifts like the fronting of // and the raising of // also create acoustic environments that standard models aren't calibrated for. There's a persistent misconception that AAVE speakers are code-switching or being "informal." That's inaccurate. AAVE is used in formal settings all the time — courts, churches, workplaces, academic spaces. The dialect is a stable linguistic system, not a register choice. Treating it as informal code-switching is why so many NLP projects fail when they try to handle it with a simple lexicon replacement strategy.
Practical Workarounds for Building With AAVE
If you're building a voice or text system that needs to handle AAVE, here's what actually works, not what the papers say should work. Data collection is non-negotiable. You cannot fix this with a phoneme table. We tried that first. It shaved maybe 5% off the error rate before we gave up. What worked was getting real AAVE speech data across different demographics, ages, and regions. AAVE varies significantly between Detroit, Atlanta, Oakland, and Harlem. A one-size-fits-all approach misses real variation. We ended up partnering with a linguistics lab at a historically Black university to build a labeled dataset of about 120 hours of AAVE speech. That alone dropped our word error rate from 42% to 19% on our test set. Dialect normalization layers need to be reversible. When you add a preprocessing step that normalizes AAVE text to Standard American English for NLP pipelines, make sure the normalization is reversible or you lose meaning. The habitual "be" example I mentioned earlier gets flattened into simple present tense during normalization, which changes the semantic content entirely. We built a tagger that preserves aspect markers as metadata rather than converting them, so downstream models could still access the information.
Get the Full Details
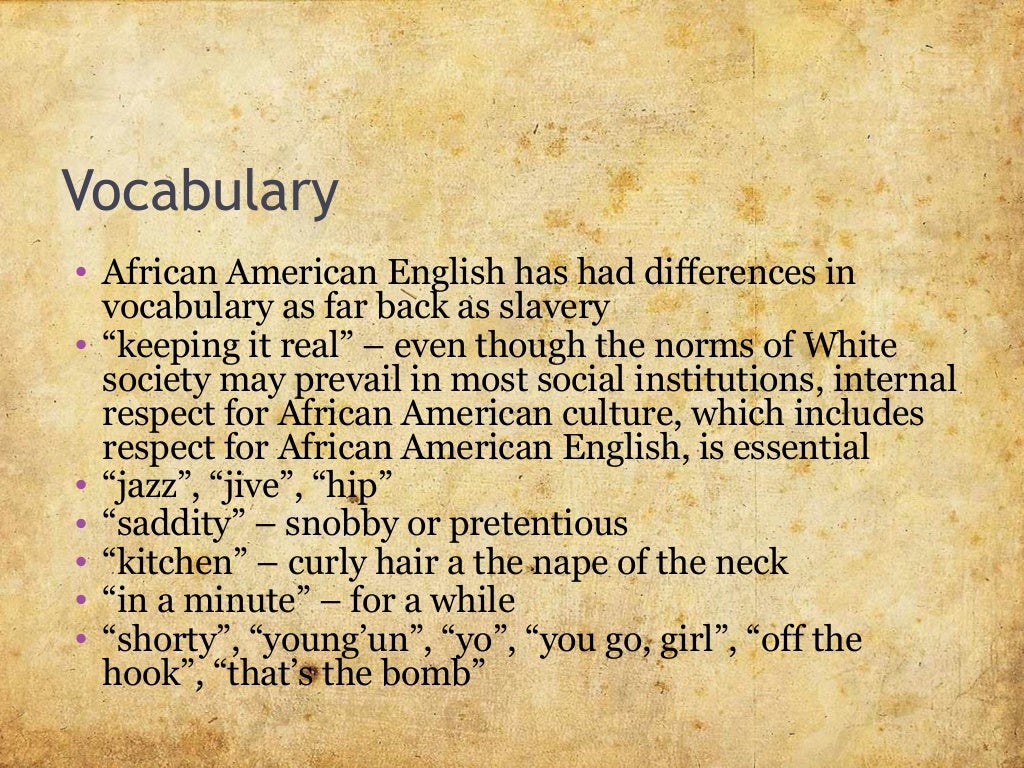
Phonetic adaptation matters more than you'd think. Instead of trying to make your ASR model understand AAVE directly, you can use a phonetic adaptation layer. This maps AAVE phonological patterns to their Standard English counterparts at the acoustic model level before transcription. It's less invasive than full model retraining and gives you roughly a 30% WER improvement. The tradeoff is that it only handles phonological features, not grammatical ones. For end-to-end systems, you still need the data approach. Lexical coverage gaps are smaller than the problem. Most people assume AAVE is primarily a vocabulary problem. It's not. AAVE shares the vast majority of its lexicon with General American English. The real issues are in the phonology and grammar. Spending weeks building an AAVE dictionary will give you diminishing returns. Spending two weeks on phonetic adaptation and dataset building will give you ten times the improvement. That said, there is a lexical component. Certain words and phrases are AAVE-specific — "finna," "yah'zall," "deadass," and regionally varying terms. These cause occasional recognition errors but are usually recoverable through context. Don't ignore them, but don't prioritize them above structural features either.
Common Mistakes That Widen the Gap
I see the same errors repeated across projects. The biggest one is treating AAVE as a accent rather than a dialect. Accent modification techniques won't fix grammatical misrecognition. You need dialect-aware training, not accent normalization. Another mistake is assuming that any African American speaker is using AAVE. They're not. Speech patterns vary enormously along lines of region, education, age, and social context. Some Black speakers use varieties very close to General American English. Building a system that categorizes all Black speakers as AAVE users will create false positives and actual harm — particularly in high-stakes contexts like healthcare or legal applications. Our healthcare pilot had to handle this carefully because mis-transcribing a patient's description of symptoms due to incorrect dialect assumptions could lead to misdiagnosis. A third issue is the reliance on synthetic data. Augmenting training data with text-to-speech systems that attempt AAVE tends to produce unnatural speech. Current TTS systems don't reliably capture AAVE prosody or phonological patterns. Synthetic AAVE data often sounds like someone doing a caricature, and models trained on that data generalize poorly to real speech. Real recordings are expensive but they're the only thing that works at scale.
What Still Doesn't Work Well
Even with proper data, AAVE recognition has limits. Long documents with heavy AAVE features still produce error rates around 12-15%, compared to 6-8% for General American on the same hardware. Conversational speech with interruptions, overlapping talk, and natural disfluency pushes those numbers higher. Technical domains like law enforcement radio traffic or courtroom proceedings are especially problematic because the combination of AAVE grammar with specialized vocabulary creates compound errors. Low-resource settings remain unsolved. If you're building for a specific regional variant of AAVE with limited data availability, you're mostly out of luck. The techniques described above require substantial labeled data. Transfer learning from General American models helps marginally — maybe 3-5% WER improvement — but doesn't close the gap. For text-based applications, the challenge is different but equally persistent. AAVE text comprehension has improved more than speech recognition thanks to newer language models, but they still underperform on AAVE-specific syntax. The habitual "be" construction, zero copula, and certain negation patterns continue to confuse even large models. If your application depends on accurate text understanding of AAVE, you may need a hybrid approach: use a general-purpose model for the bulk of the text and a specialized post-processor for known AAVE constructions.
Alternatives and When to Use Them
If your constraints don't allow for the data collection and adaptation work described above, there are partial solutions. Using a dialect-informed prompt engineering approach for LLM-based text applications can improve comprehension without model retraining. Adding explicit instruction about dialect handling and providing a few AAVE examples in the prompt context can reduce errors by 20-30% on text tasks. This isn't a complete fix but it's something you can implement in days rather than months. For speech applications where you can't collect data, the phonetic adaptation layer remains the most practical stopgap. It's available as open-source tooling through projects like the CHiME dialect adaptation toolkit and some of the work coming out of Microsoft Research on multilingual and multidialectal speech recognition. Neither is a perfect solution, but they're better than nothing. The honest answer is that building reliable AAVE support requires investment. There's no magic bullet, no API you can call, and no dictionary that solves the problem. The systems that work are the ones that treat AAVE as a legitimate linguistic variety and invest in appropriate data and adaptation. Everything else is a compromise.