Generating Comics From Prompts Without Going Completely Insane
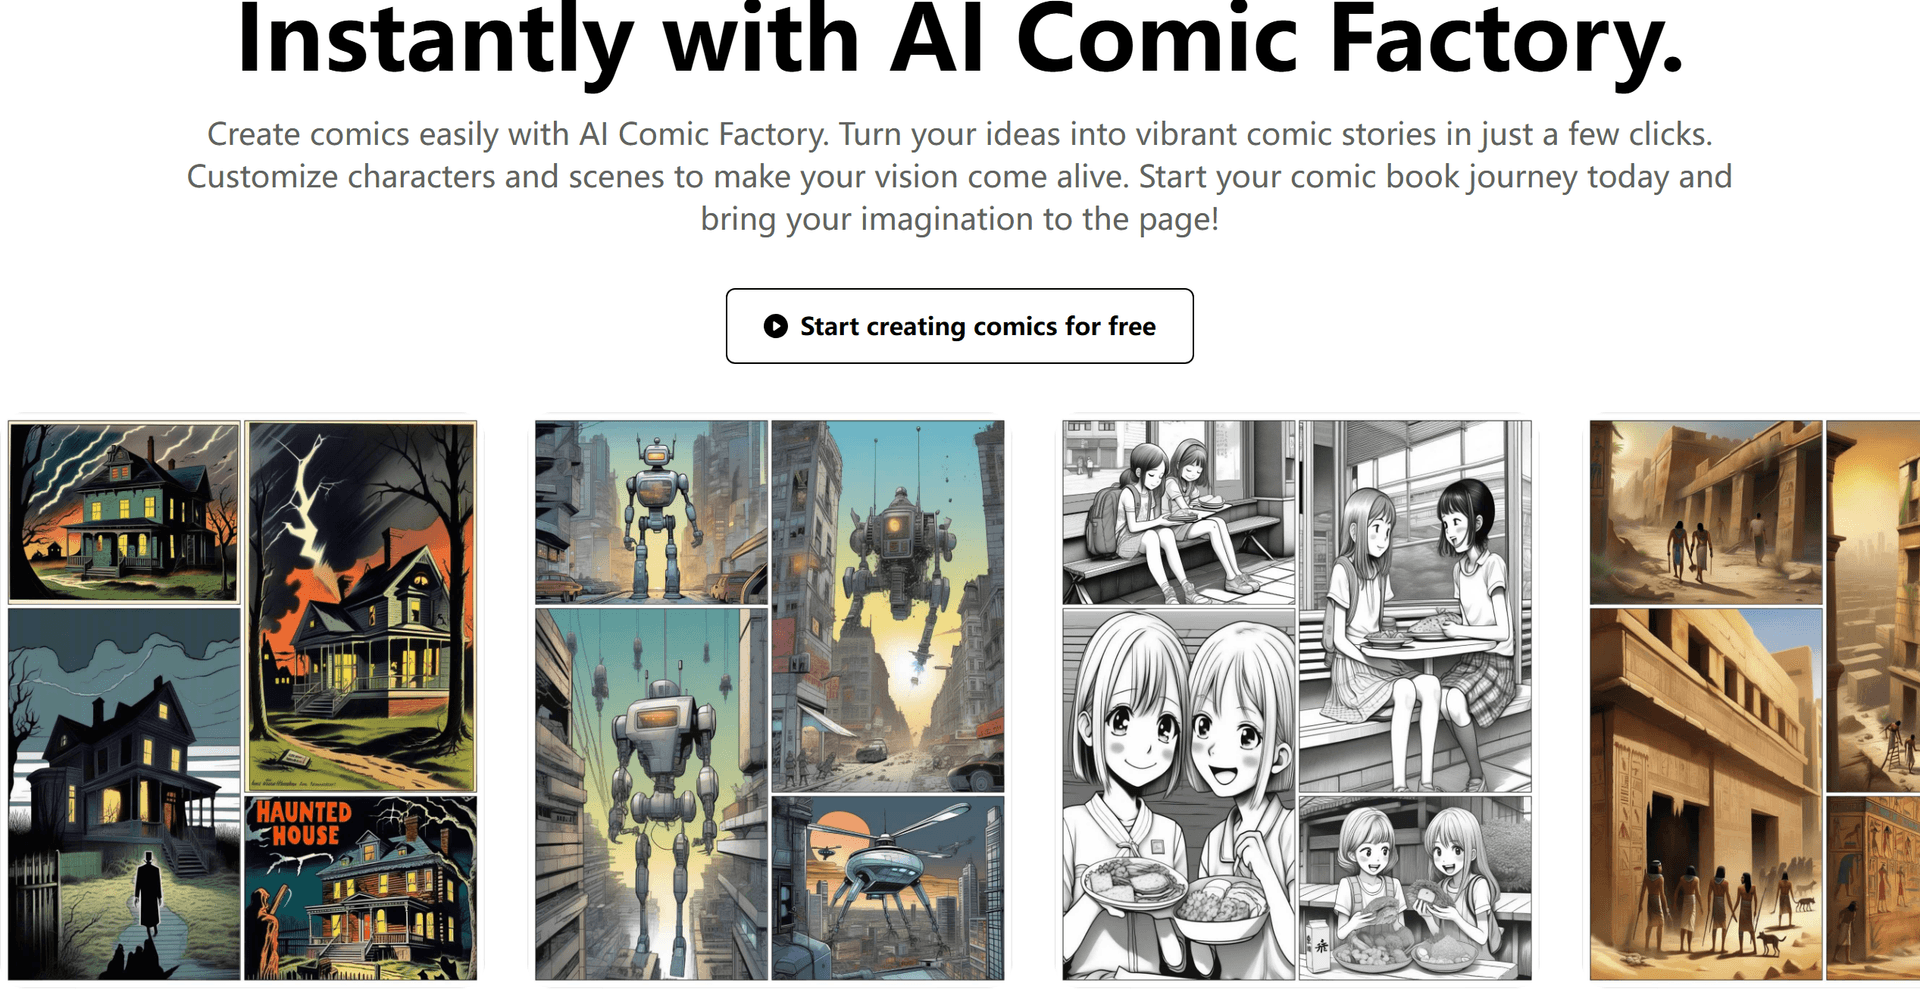
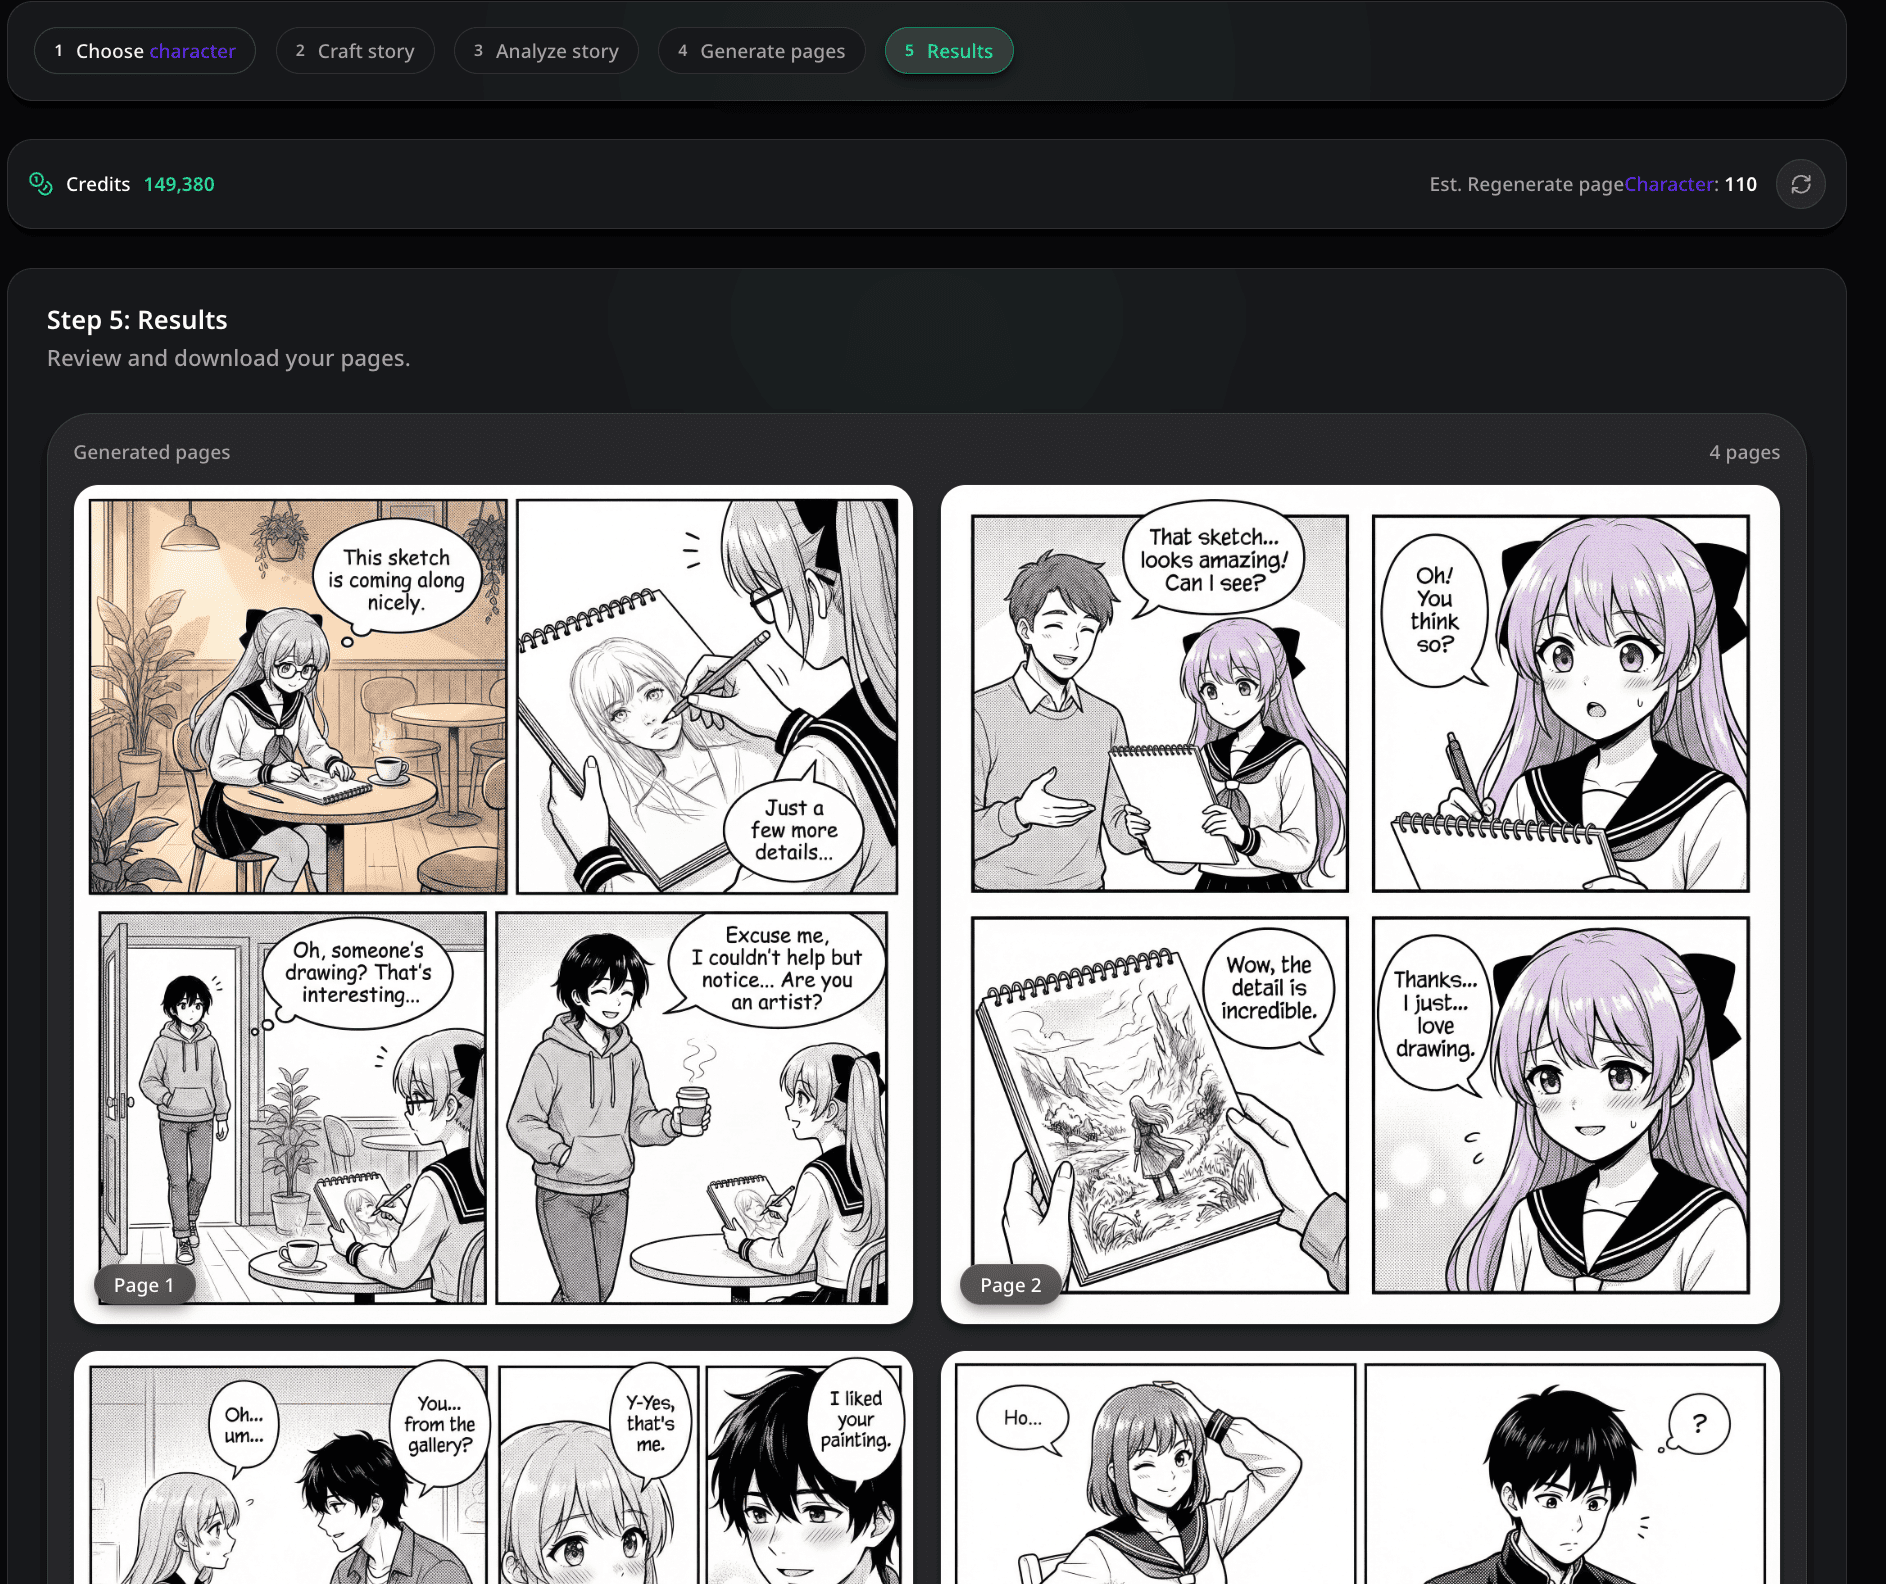
The workflow for generating comic pages from text is straightforward once you understand what the pipeline actually does under the hood. You type a script or a scene description, the model breaks it into panels, renders each panel as an image, and then composes them onto a page with speech bubbles. The output quality ranges from decent to frustrating depending on how much you prepare beforehand. The space runs on Hugging Face Spaces and typically uses a combination of Stable Diffusion models fine-tuned for sequential panel generation. You access it through your browser at the Hugging Face URL, enter a scene prompt, and select your panel count. The generation usually takes between 5 and 15 minutes per page on a free tier depending on queue length. I'd recommend setting your prompt to at least two to three sentences per panel rather than one-line descriptions, because the model falls apart when the input is too thin. It needs context to determine character consistency, panel layout, and pacing across the page. One thing most tutorials don't mention is that the speech bubble generation is the weak point. The model will attempt to place text into bubbles, but OCR-quality transcription inside bubbles is inconsistent. I spent about forty-five minutes trying to get a three-panel sequence where a character said "Wait, you're actually going to do that" across three expressions. The first two panels came out fine. The third one had the bubble text jumbled and positioned behind the character's head. My workaround was to generate the panels without any text at all, then overlay my own speech bubbles using a free editor like Photopea or even Canva. It added maybe five minutes to the process, but the final result looked professional instead of broken.
Another detail nobody talks about enough is character consistency. If you have a protagonist appearing in all six panels, the model won't keep their appearance uniform by default. You need to seed your prompts with specific visual descriptors repeated across each panel description. Something like "young woman with short black hair wearing a red jacket" needs to appear in every panel prompt where she shows up, not just the first one. This is basic prompting discipline, but it's easy to skip when you're rushing through a full page.
What Actually Works vs What Doesn't
Simple scenes work well. A conversation between two characters in a single location, moderate dialogue, standard panel layouts. Those come out cleanly most of the time. Complex action sequences with overlapping characters, motion blur effects, or perspective shifts tend to produce garbled results. The model doesn't understand spatial relationships between figures in the same way a human storyboard artist would. If you need something more reliable for professional work, you might consider running the base image generation through ComfyUI or Automatic1111 with a controlnet for pose and composition, then feeding those generated panels into the comic layout stage separately. That doubles your workflow time but gives you significantly better control over the visual output. For quick concepting and brainstorming pages, the Hugging Face space is fine. For anything you're planning to publish, treat it as a first draft tool rather than a final production pipeline. The generation queue on Hugging Face can also be unpredictable. During peak hours I've seen wait times stretch past twenty minutes with zero progress. If you're working on a tight deadline, either run it late at night or set up a local instance if you have the hardware for it. A decent GPU will give you consistent output without the queue anxiety, and you can batch process multiple panels in parallel.
Get the Full Details