The reality of finding free AI aesthetic downloads
You spend enough time on Pinterest or ArtStation noticing certain recurring styles. Soft gradients, dreamy filters, that particular mid-century Japanese illustration vibe mixed with a Lo-fi sunset. People want these. Not the originals, obviously, but something close. So they search for a way to get them for free. What they usually find is either a watermarked mess or a sketchy link that installs mining software. I stopped trusting random download pages years ago and just work with open-source models now. The honest way to do this is through Stable Diffusion, specifically the SD 1.5 or SDXL architecture, running locally on your own machine. The aesthetic you are looking for is heavily tied to specific checkpoint models and LoRAs. A checkpoint is the base model file. A LoRA is a small adapter that tweaks style. The combination is what actually produces those coherent, usable images instead of garbage blobs. I used to run everything through web interfaces just to avoid the setup. That was wrong. Web interfaces throttle output, stamp watermarks on your results, and often resell your prompt data. When I switched to a local install, I started generating around 12 to 18 images per minute on an RTX 3080 using Automatic1111 with xformers enabled. That is a meaningful difference when you are iterating through styles.
The model I recommend starting with is anything from the DreamShaper family for general aesthetics, or RevAnimated if your work skews toward illustrative styles. Download these from Civitai. Use the official site, not a mirror. I wasted two hours once chasing a fake Civitai mirror that served a trojanized executable disguised as a Stable Diffusion checkpoint. The file looked identical. It was not. Check the hash. It takes thirty seconds and saves you from cleaning malware off your system. Once the model is loaded, you need positive and negative prompts. A negative prompt matters more than most beginners realize. For clean aesthetic work, you want to explicitly exclude things like "watermark, text, signature, deformed, ugly, bad anatomy, cropped, out of frame." Without that, the model happily fills every inch of the canvas with artifacts. A positive prompt like "aesthetic, soft lighting, pastel tones, cinematic composition, high detail, professional color grading" gets you closer to what you actually want in one try instead of ten. Sampling steps between 20 and 30 is the sweet spot. Going higher just makes the render slower with almost zero visible improvement. Seed control is important too. If you generate something close but not quite right, lock the seed and nudge just one word in the prompt. That is how you iterate without starting from scratch every time.
There are limits to this approach. If you do not have a GPU with at least 8GB of VRAM, SDXL will struggle or fail entirely. SD 1.5 runs on lower hardware but the output quality ceiling is lower. You will also hit a wall with photorealistic portraits. These models are good at atmospheres and stylized scenes. They are terrible at hands, fingers, and consistent faces unless you add heavy post-processing. I learned that the hard way when a client needed a sequence of six character concept shots. The faces drifted between generations. I ended up using a face-swap tool on top of a consistent base generation, which added an entire extra step I had not planned for. Resolution matters more than people tell you. The default 512x512 square output looks amateurish for almost any aesthetic use. Going to 768x1024 or 1024x1024 changes the composition entirely. The model has more canvas to work with and the details come out sharper. If you are generating for web, 1080p width is usually enough. Anything larger is overkill and just inflates your storage without visible benefit. Another thing nobody warns you about is batch generation noise. When you run five variations at once, they all look similar after step ten. It is better to run single images with different seeds, evaluate, then batch the promising ones. You save time and GPU cycles. My typical workflow goes from empty prompt to final saved image in about eight to twelve minutes per usable asset. That is with iteration included. If you skip iteration and just take the first pass, you get acceptable results in under three minutes, but they are rarely the ones you actually keep.
Get the Full Details
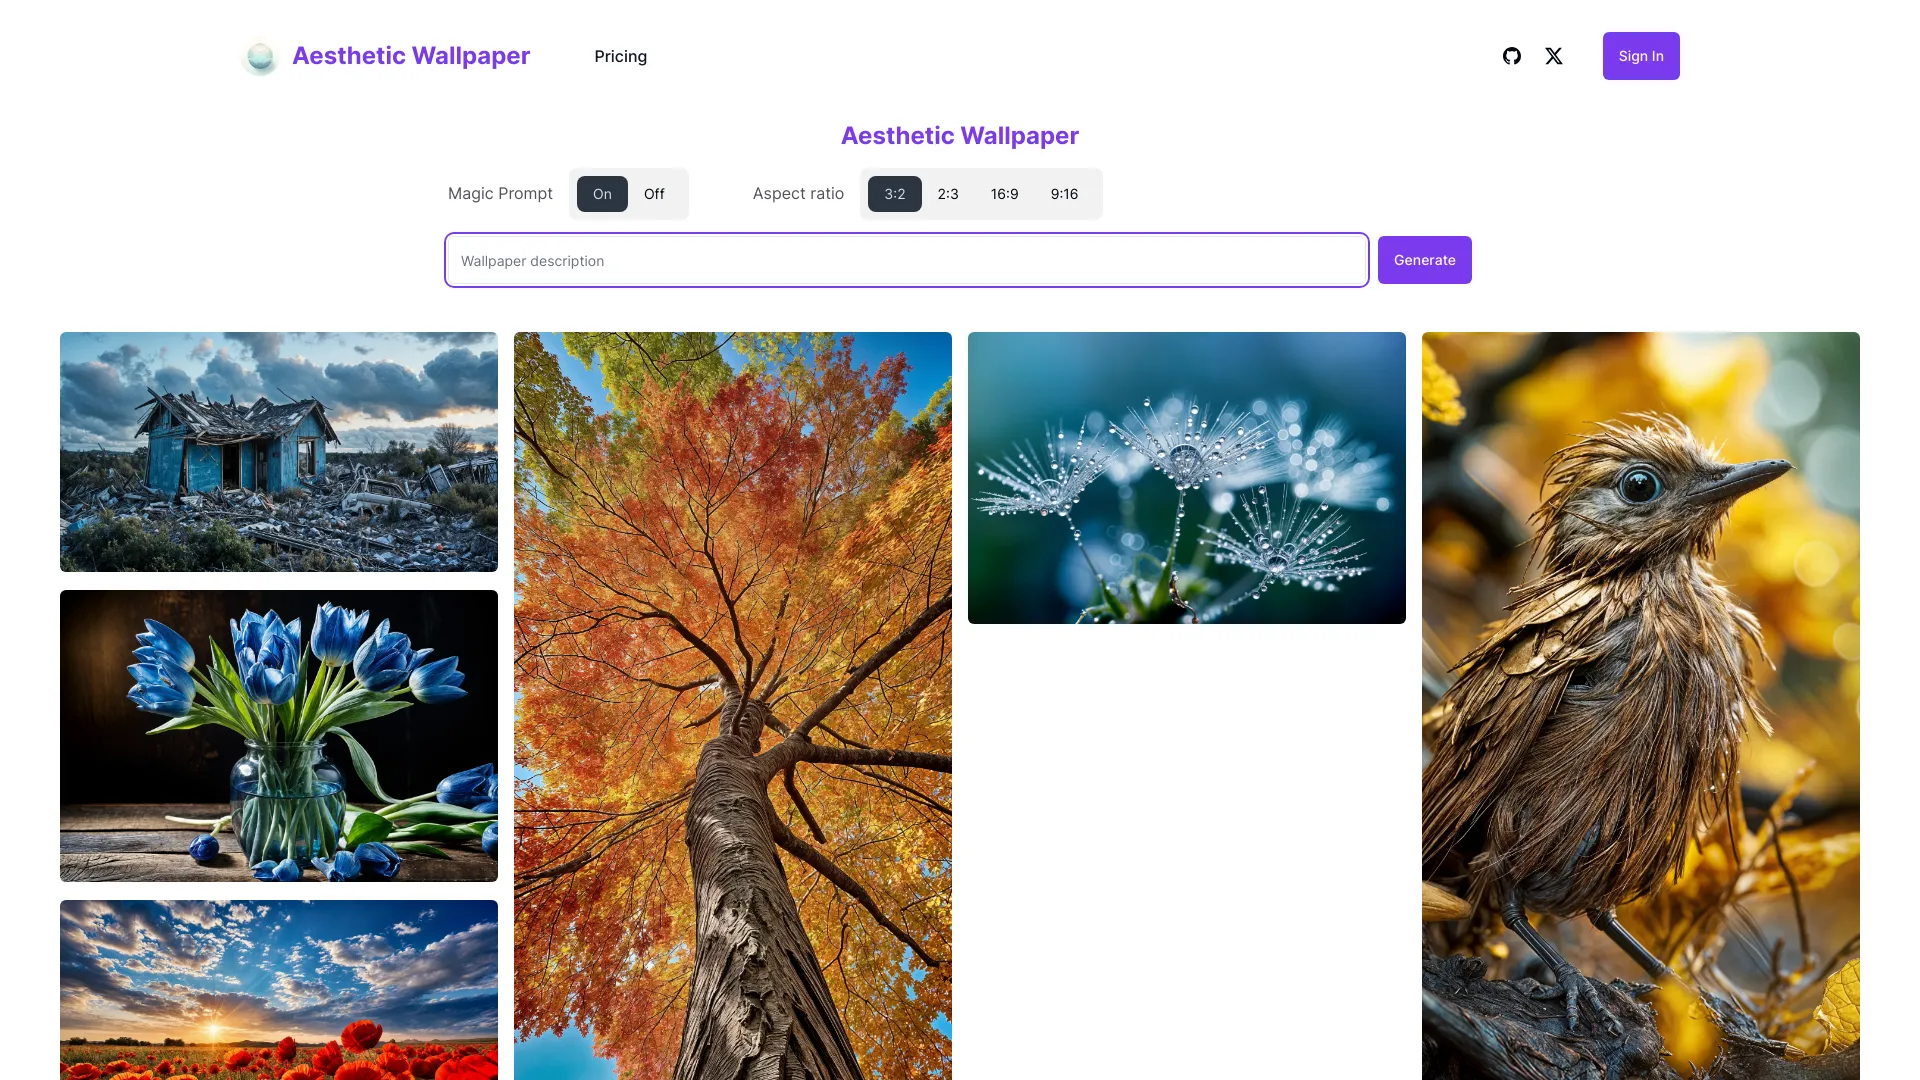
If you cannot run this locally, the next option is a free tier on a service like Tensor.art or Playground AI. These are not perfect. Tensor.art has a daily credit limit that refreshes at midnight UTC. Playground AI has softer resolution caps on the free plan. Neither matches local generation, but they are functional if you are on weaker hardware. Just do not expect unlimited exports or the ability to control seeds precisely. Download links for the models themselves live on Civitai and Hugging Face. I keep a folder on my main drive labeled "SD checkpoints" with the file names and their intended use cases written in a plain text file. It sounds like overkill until you are six months in and trying to remember why you downloaded three versions of the same model with slightly different naming. A simple text file saves you from reloading a two-gigabyte file you already have sitting on your drive. The whole thing is straightforward once you stop looking for a magic one-click installer. There is none. You install the software, load a model, write a prompt, and iterate. The learning curve is about two weeks of nightly practice before it feels routine. After that it is just work.