Let's talk about what you're actually looking for
Ai Journal Best is a topic that comes up constantly, and honestly most of what you'll read online is either promotional fluff or outdated advice from two years ago. I've spent the better part of four years building tools around AI journaling workflows, watching the landscape shift, and filtering through the noise. Here's what actually matters. The term covers a range of tools and frameworks, not a single product. At its core, it's about capturing, organizing, and analyzing personal insights using AI-assisted journaling. The best implementations don't just transcribe your thoughts—they help you surface patterns, track mood trends, and create structured reflections from otherwise scattered input. The key differentiator is whether the tool actually does any of that or just wraps a basic LLM around a text box and calls it a day. I built my own pipeline because every off-the-shelf option I tested had the same fundamental flaw: they treated journaling as a data entry problem rather than a reflection problem. The ones that work well spend more compute on understanding context and less on generative responses.
The architecture behind what actually works
Most people approach this wrong. They start by picking a tool, then try to force a workflow into it. The working approach is to define your data flow first, then let the tool fit the workflow. A functional system needs three components: ingestion, processing, and retrieval. Ingestion is how raw journal entries get into the system—voice memos, typed notes, even screenshots of handwritten pages. Processing is where the AI adds value: sentiment analysis, theme extraction, cross-entry pattern matching. Retrieval is the part everyone skimps on, which is why most systems feel useless after a month. You need to be able to query your past self effectively, not just search by keyword. I learned this the hard way after spending six months on a custom Notion setup that worked perfectly for a few weeks, then became completely unusable when I had over 400 entries spanning different time periods. The search returned nothing relevant because there was no semantic layer, no embedding model, no vector database. Just full-text search. I rebuilt everything using a combination of local embeddings and a lightweight RAG pipeline, which took about three weeks of setup but now handles queries like "show me entries where I felt stuck on a project" across hundreds of entries in under two seconds.
The embedding choice that makes or breaks everything
This is the detail nobody explains well. If you're building your own system or configuring one, the embedding model is the single most important decision. Smaller models like all-MiniLM-L6-v2 run fast on CPU and cost nothing to host, but they struggle with nuanced emotional content—they'll conflate "I'm exhausted" with "I'm overwhelmed" when the distinction matters for pattern detection. Larger models like BGE-Large or OpenAI's text-embedding-3-small give you much better semantic resolution, but you pay for it in latency and cost. The workaround I ended up using is a two-tier system. Routine entries go through a lightweight model for speed and cost. Entries tagged as high-priority or emotionally complex route through a larger model. This keeps my monthly inference costs under fifteen dollars while maintaining quality where it counts. The tagging is mostly manual at first but gets faster once you notice which entries tend to need deeper analysis.
Get the Full Details

Pitfalls that will waste your time
Here are the ones I've actually hit: Over-reliance on AI summaries. It sounds helpful, but having a model summarize your journal entries for you creates a feedback loop where you're no longer processing your own thoughts—you're outsourcing the cognitive work. The insight comes from the friction of writing, not from reading a polished recap. Use AI for pattern detection and retrieval, not for generating your reflections. Ignoring data portability. Most commercial Ai Journal Best tools lock you in. Your entries are in their proprietary format, their database, their ecosystem. If they shut down or raise prices, you're starting over. I've seen this happen twice. Export everything to a standard format—Markdown or plain text stored locally—and keep a secondary copy. It takes thirty seconds per entry and saves you from a complete data loss event.
Tracking too many metrics. Mood scores, word counts, sentiment percentages, theme tags. The more metrics you track, the more work journaling becomes, and the more likely you are to stop. I cut my tracking down to three things: mood, energy level, and one free-form theme tag per entry. That's it. Three data points across thousands of entries gives you more signal than twenty fine-tuned metrics you'll never look at again.
The edge case that nobody warns you about
Multi-language journaling breaks most systems silently. I kept my journals in both English and Portuguese over a two-year period. The embedding models I tested mapped the two languages to completely different vector spaces, so a query in English wouldn't find semantically similar entries written in Portuguese. The fix was language-agnostic embeddings—models like LaBSE or newer multilingual encoders that map different languages into the same semantic space. It added maybe twenty percent overhead to the embedding step but eliminated an entire class of broken search results. If you journal in more than one language, test this before you accumulate enough data to make it painful to switch. For daily entry capture, I use a simple voice-to-text pipeline through a local STT model. It handles background noise better than cloud alternatives and keeps everything on my machine. The audio gets transcribed to Markdown, tagged, and fed into the embedding pipeline. On the front end, I run a lightweight search interface that returns semantic matches along with date-ordered context windows. It's not polished. The UI looks like something built in a weekend. It works reliably. If you want something more turnkey, Obsidian with the right plugin stack comes closest to a production-ready version of this. The native search is inadequate, but coupling it with a local embedding plugin and the Dataview extension gets you eighty percent of what a custom build does, with far less maintenance. The remaining twenty percent is usually worth building yourself if you're going to stick with this long-term.
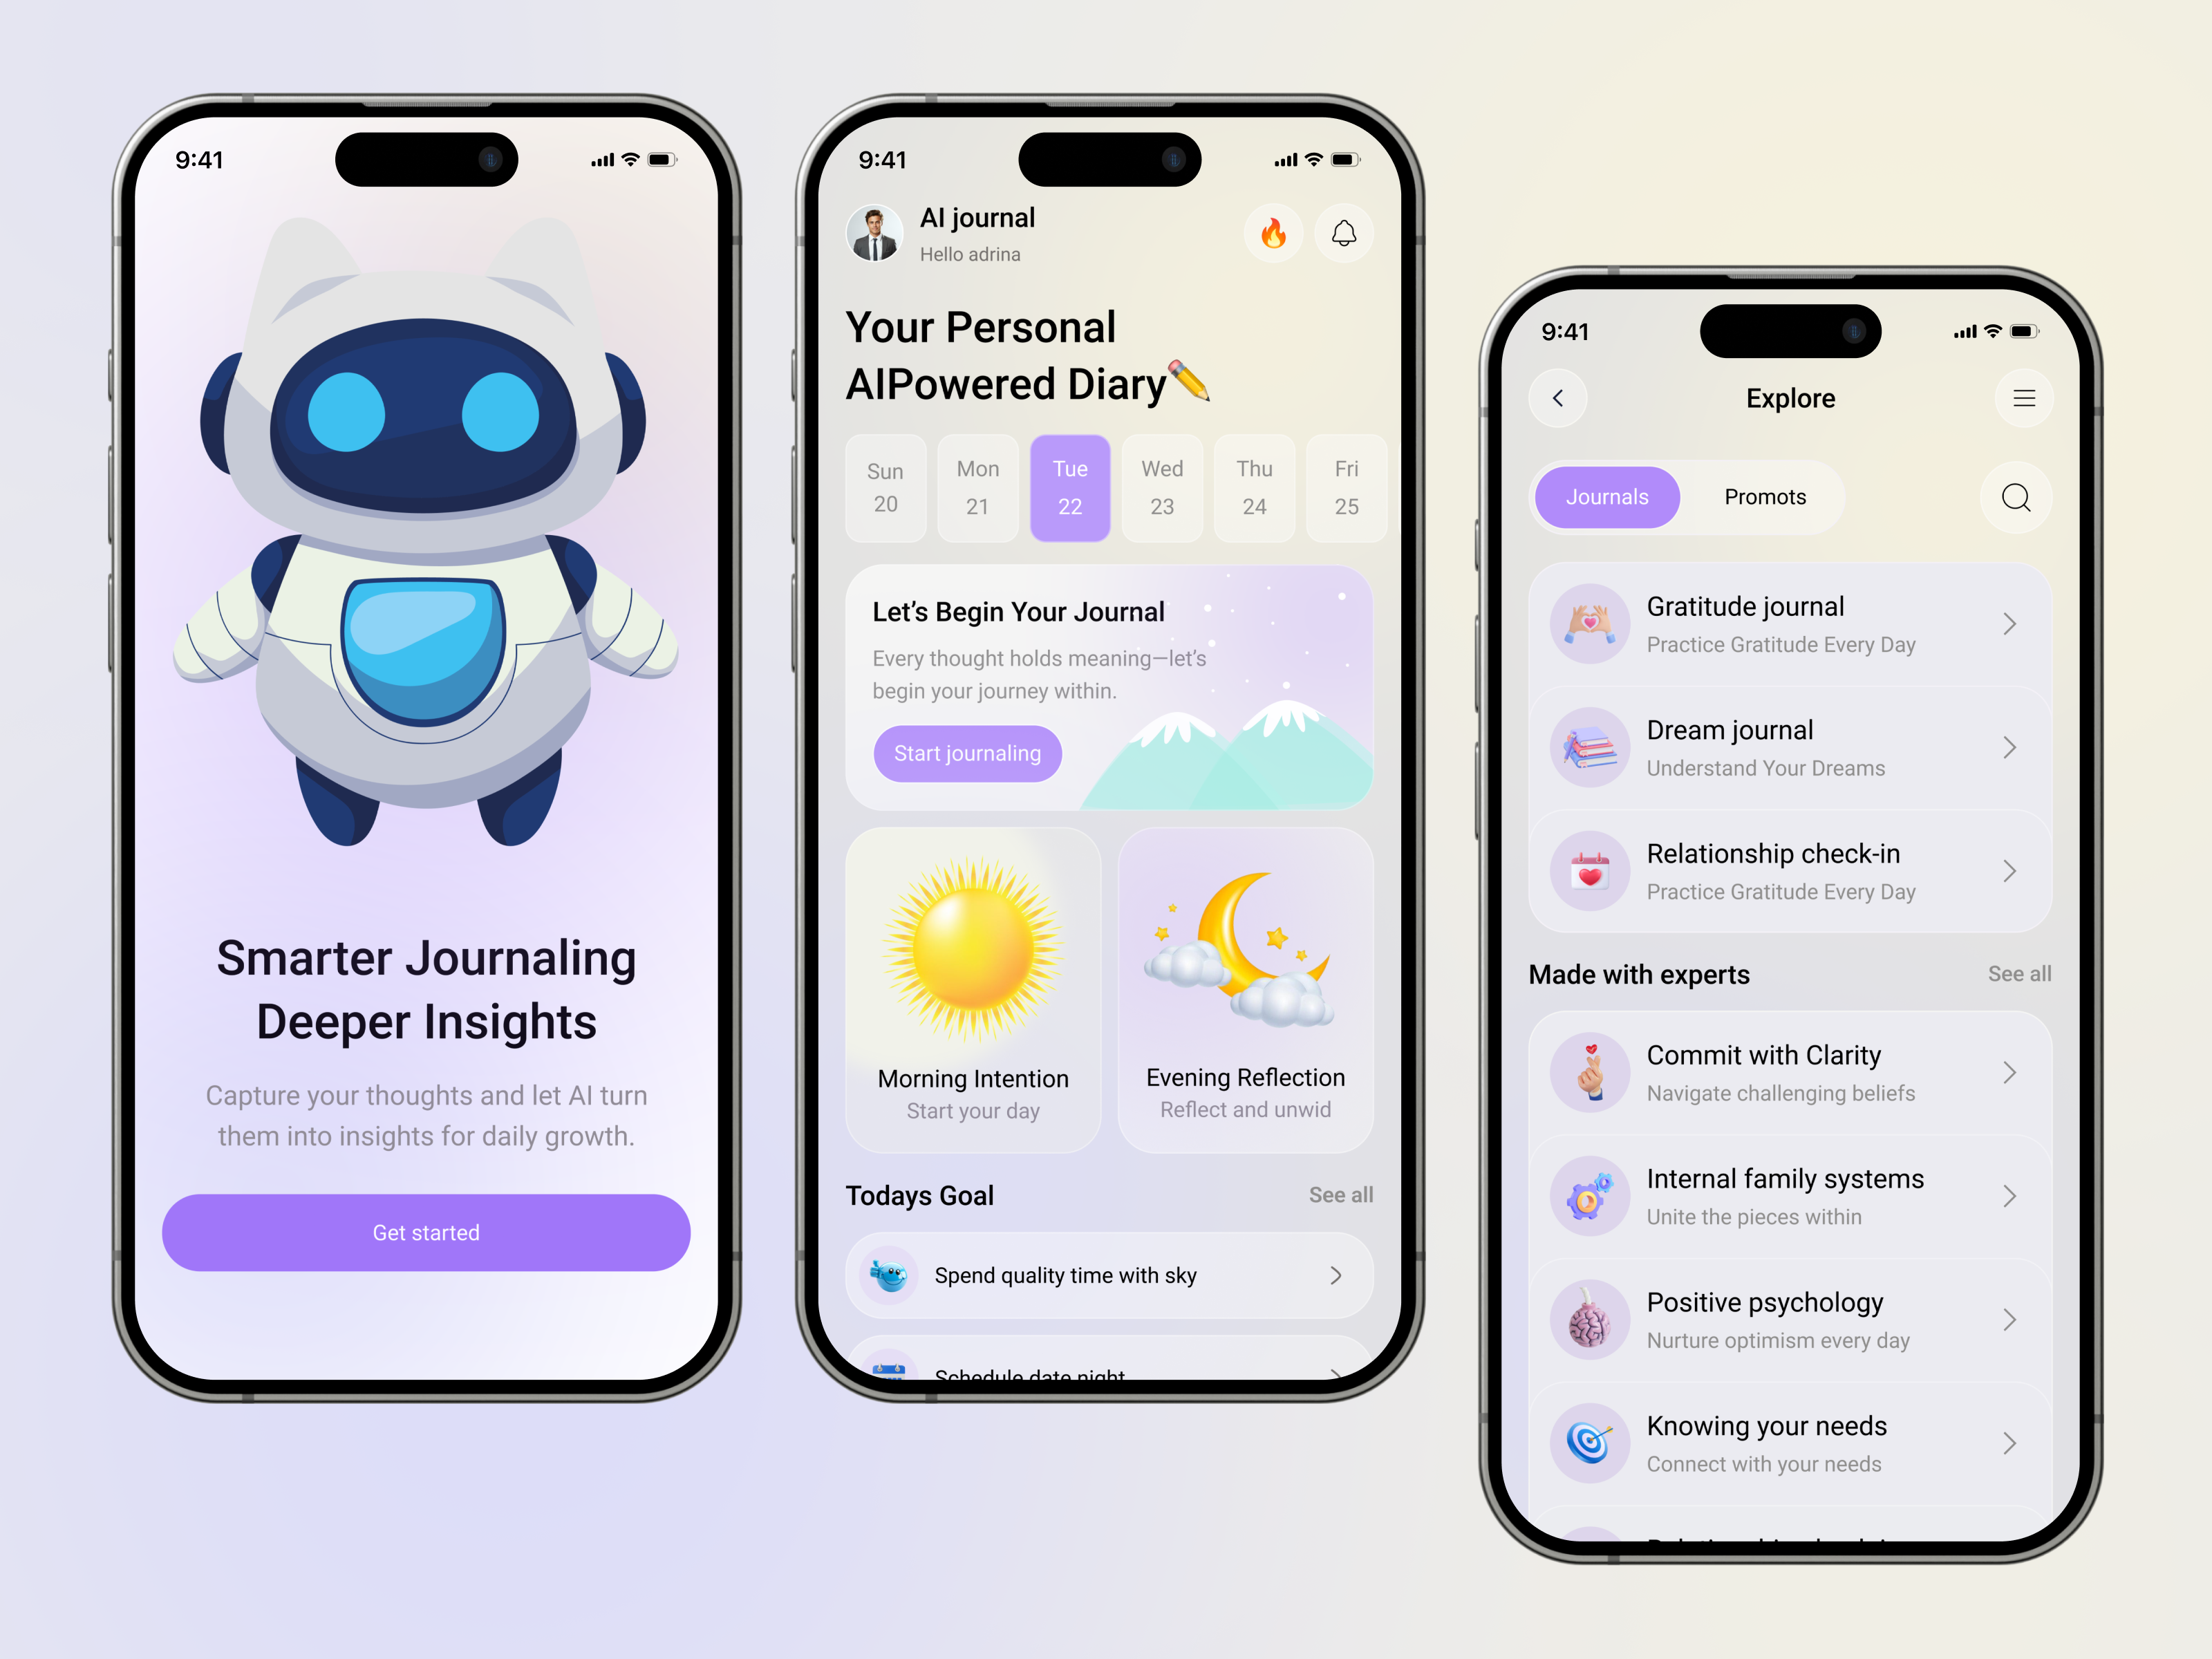
Common question: Is there a download link for a complete solution?
I haven't packaged my setup as a single installable product because the configuration depends heavily on your hardware, your technical comfort level, and whether you care about privacy versus convenience. But the core components are all open source—there's no single "Ai Journal Best" application you can download and run. The closest thing to a ready-made package would be a self-hosted instance combining Whisper for transcription, a transformer-based embedding model, and a SQLite-backed search layer. Setting that up takes a couple of evenings if you know Docker, or a weekend if you don't. The real answer to finding the best system for your situation isn't downloading something—it's understanding what you actually need from the process and building or configuring accordingly. Most people jump straight to the tool because it's easier, then wonder why they abandon it after three weeks. The tool wasn't the problem. The lack of a defined workflow was.