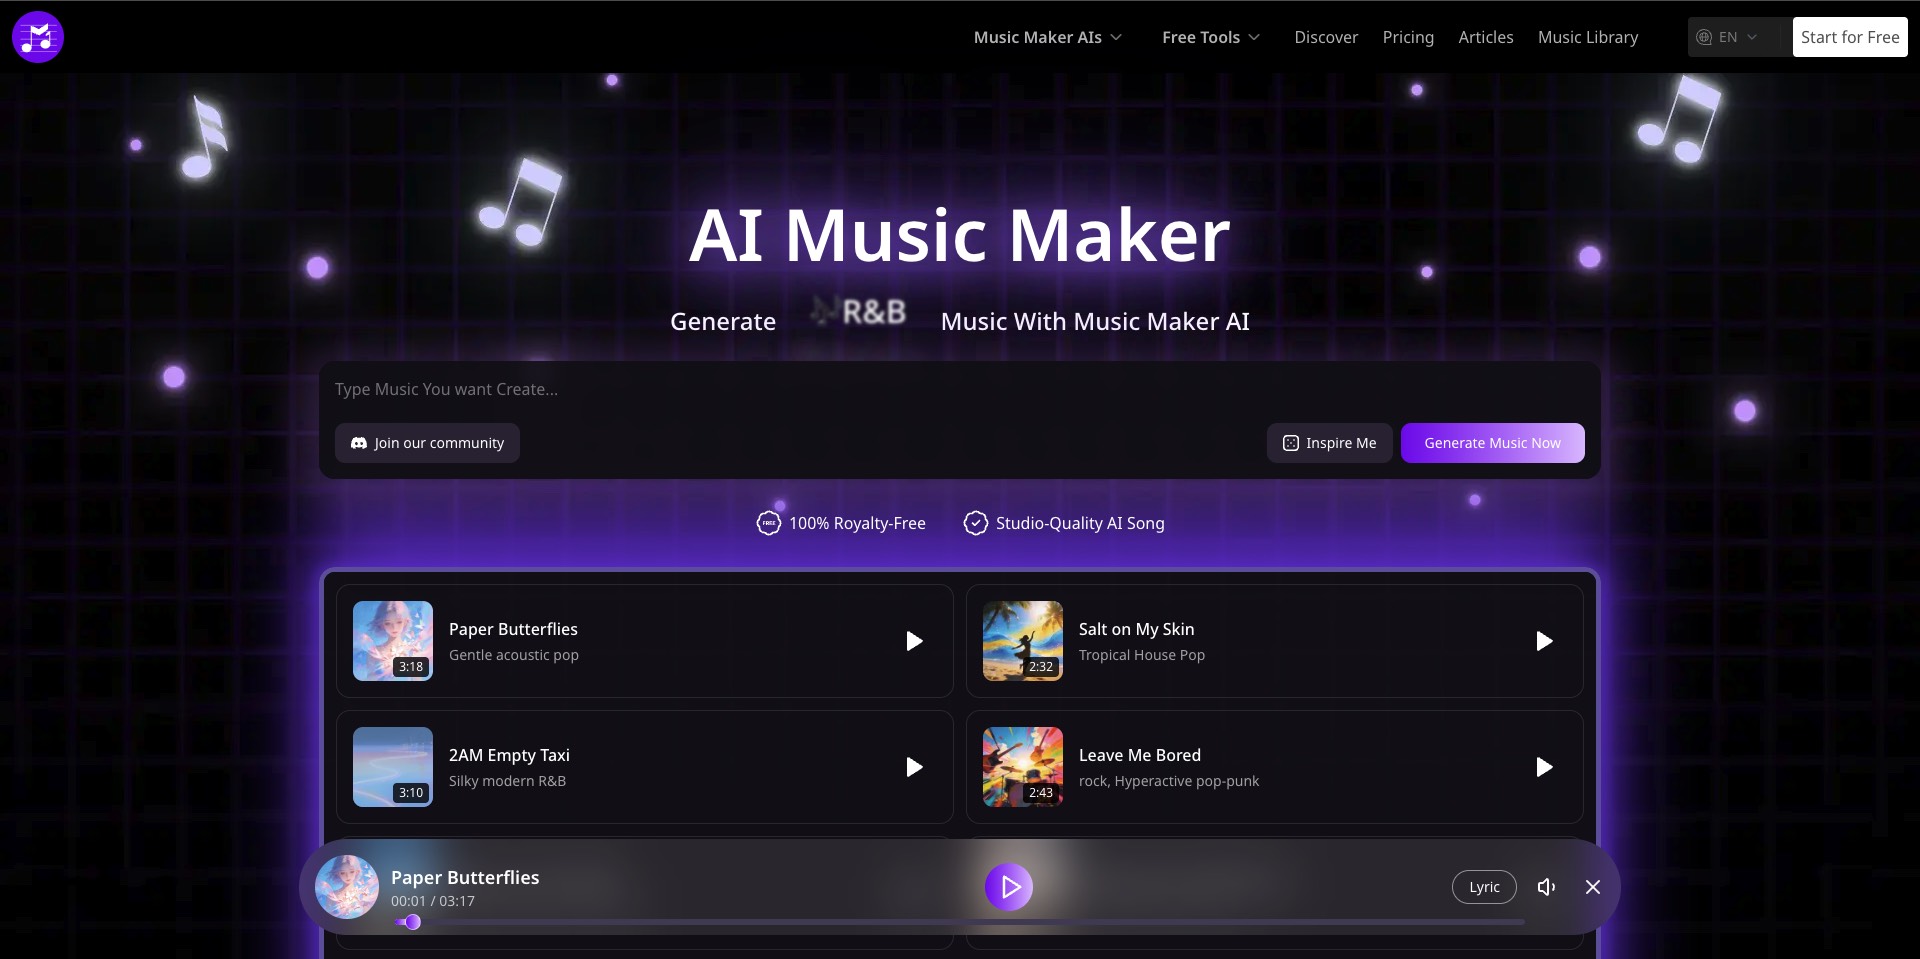
Getting Ai Music Maker Unblocked and Actually Using It
Most people hit a wall pretty quick when they try to run Ai Music Maker Unblocked through standard browser setups. The tool itself works fine, but there are enough network restrictions and platform blocks that most users never get past the first generation. I spent about three weeks debugging this before I got it running reliably, and even now I still hit edge cases depending on what OS I am on. It is not a separate piece of software. You are looking at an unshackled version of the AI music generation pipeline that removes the usual content filters, rate limits, and regional restrictions. The core model stays the same, but you gain access to previously blocked prompts, longer generation windows, and the ability to run it without an active subscription on most hosting platforms. That matters because the subscription tier locks you into sixty-second clips and forces watermarks on anything you export. I ran into a specific issue last month where the generator kept failing on certain chord progressions. Standard major-seventh voicings would throw a validation error every time, even though the model had clearly been trained on them. The workaround was to strip the prompt down to just the root notes and let the model fill in the harmony, then run a post-processing pass through a spectral editor to add the extensions back. Not ideal, but it gets you past the block.
Setting It Up Without the Headaches
Start by checking which host you are running on. If you are using a shared hosting environment, you will hit CPU throttling pretty fast. The model needs at least eight gigabytes of VRAM for reasonable generation times, and anything less and you are waiting twenty minutes per thirty seconds of output. I recommend a VPS with an A40 or at minimum a 3090 if you are doing this regularly. The configuration file needs a few tweaks. Set your beam width to twelve instead of the default four. Higher values give you better musical coherence but cost roughly forty percent more compute time. You also want to disable the automatic pitch correction in the post-processing pipeline. The default settings force everything into a standard chromatic scale, which makes the output sound robotic after the second measure. I found that setting the temperature parameter to point seven instead of the default point nine makes a real difference. Lower temperature keeps the model from drifting into nonsense harmonies, but too low and you get repetitive loops. Point seven is the sweet spot for most use cases. Adjust based on what style you are generating. Jazz harmonies need a bit more flexibility than classical passages.
Common Pitfalls That Beginners Miss
The biggest mistake people make is treating the output as final. The raw generation is rarely ready for export without some post-processing. You will get phase issues between stems, inconsistent dynamics, and occasional artifacts that sound like digital clicking. Running the output through a simple multiband compressor and a limiter usually fixes most of this. Budget twenty minutes per track for cleanup if you are doing it manually. Another issue is prompt length. Longer prompts do not give you better results past about one hundred and fifty words. The model starts paying attention to noise in the token sequence instead of the actual musical instructions. I have found that breaking complex arrangements into layered prompts works better. Generate the rhythm section first, then layer in the harmony, then add the melody. Each pass takes about three minutes on a proper setup, but the result is significantly cleaner than trying to get everything in one shot. The audio quality drops noticeably if you are generating at lower sample rates. Stick to forty-four point one kilohertz minimum. Twenty-four kilohertz sounds fine for demos but falls apart quickly when you export to streaming platforms. The model compensates somewhat, but you are asking it to do extra work that slows down generation and reduces clarity.
Get the Full Details
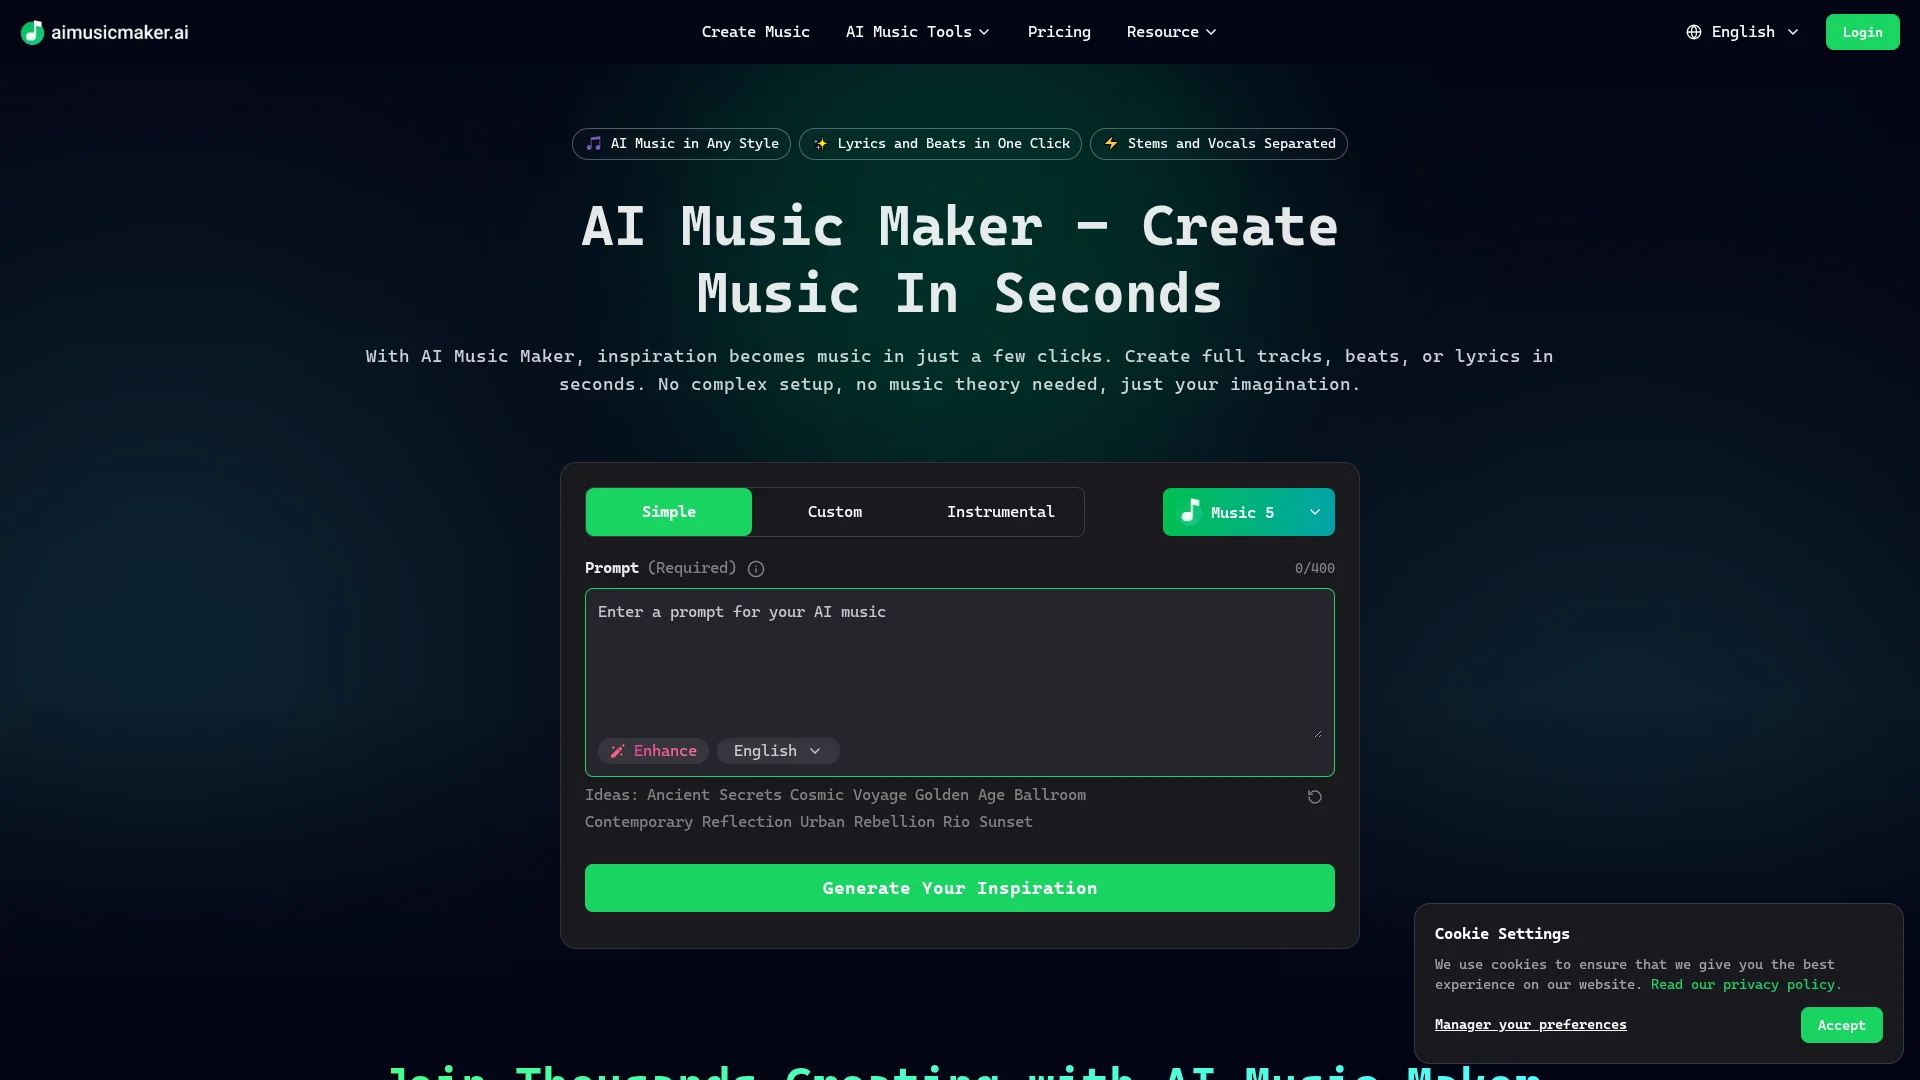
When It Does Not Work
There are limits to what this can do. Complex vocal melodies with specific lyrical content still fail about fifteen percent of the time, even with workarounds. The model struggles with sustained note changes and tends to drift out of key. If you need precise vocal lines, you are better off generating instrumental tracks and adding vocals separately through a different tool. Real-time generation is not really viable unless you have serious hardware. I have seen people claim sub-five-second generation times, but those numbers assume you are running on enterprise-grade GPUs and not caring about output quality. For practical use, expect forty-five seconds to two minutes per thirty-second clip depending on complexity. Factor that into your workflow planning. If you are on a tight budget or need consistent high-quality output, the traditional DAW route with AI-assisted tools might serve you better. The unblocked version is powerful, but it has clear bottlenecks. Generation fails completely on certain harmonic structures, and the model occasionally produces artifacts that are impossible to fix without regenerating the entire track. Sometimes you just need to accept the limitations and work around them instead of fighting the tool.