Where Most People Go Wrong With Modern AI Implementation
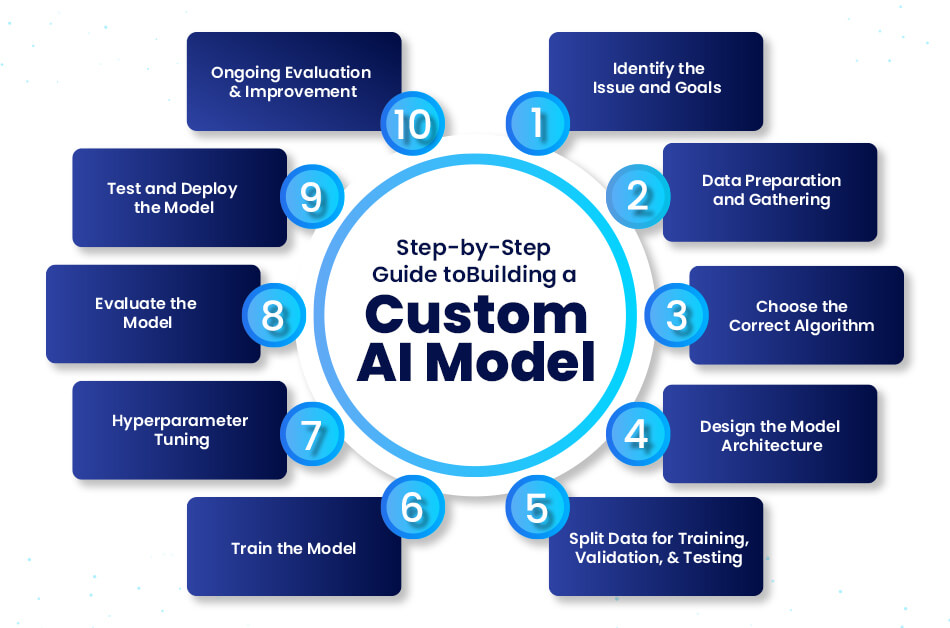
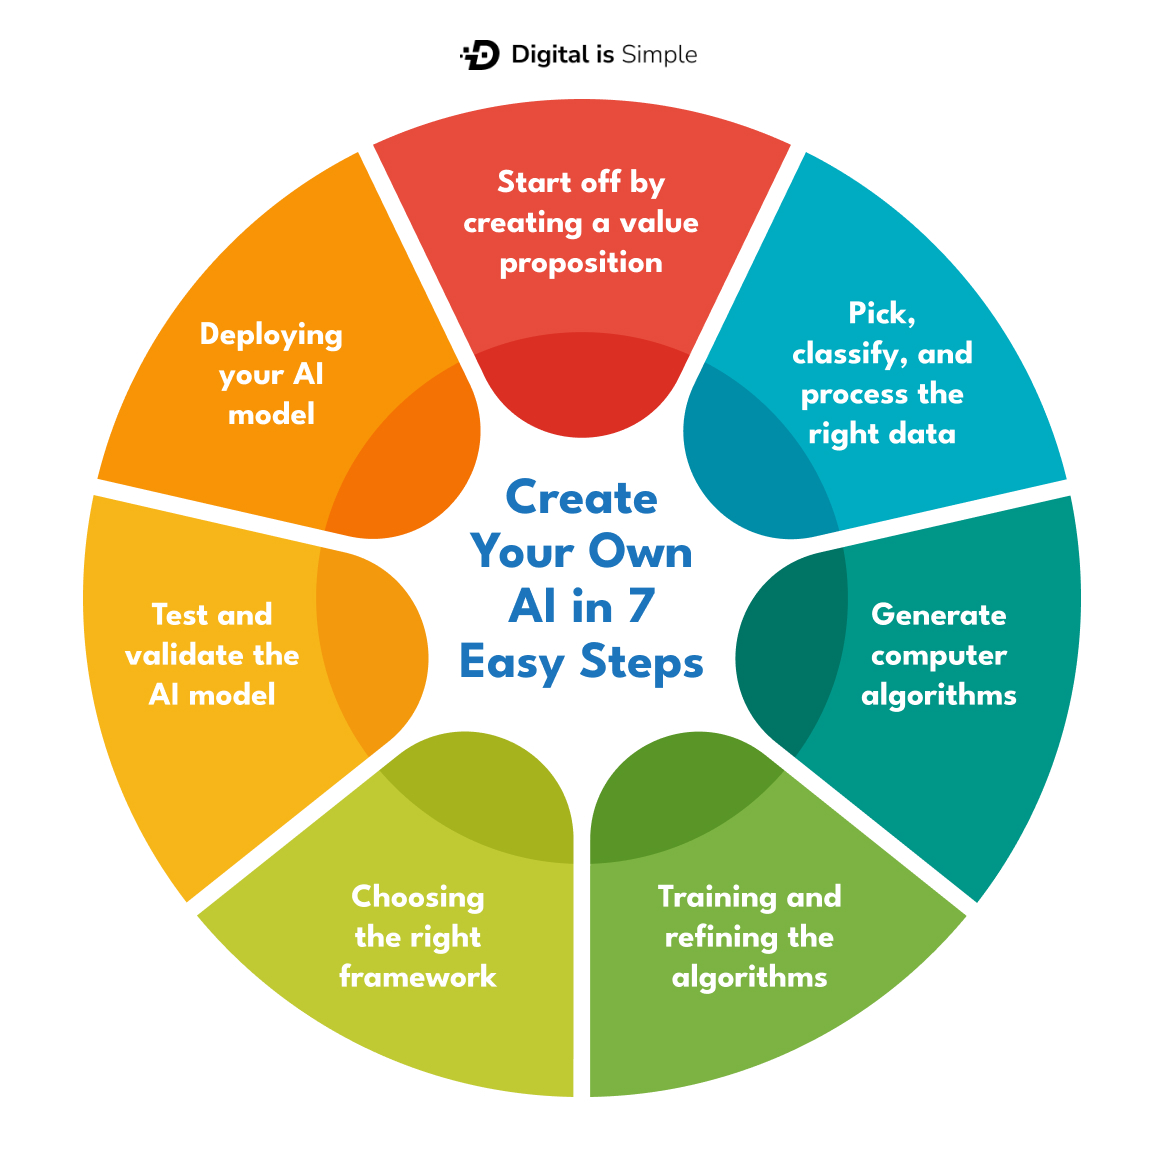
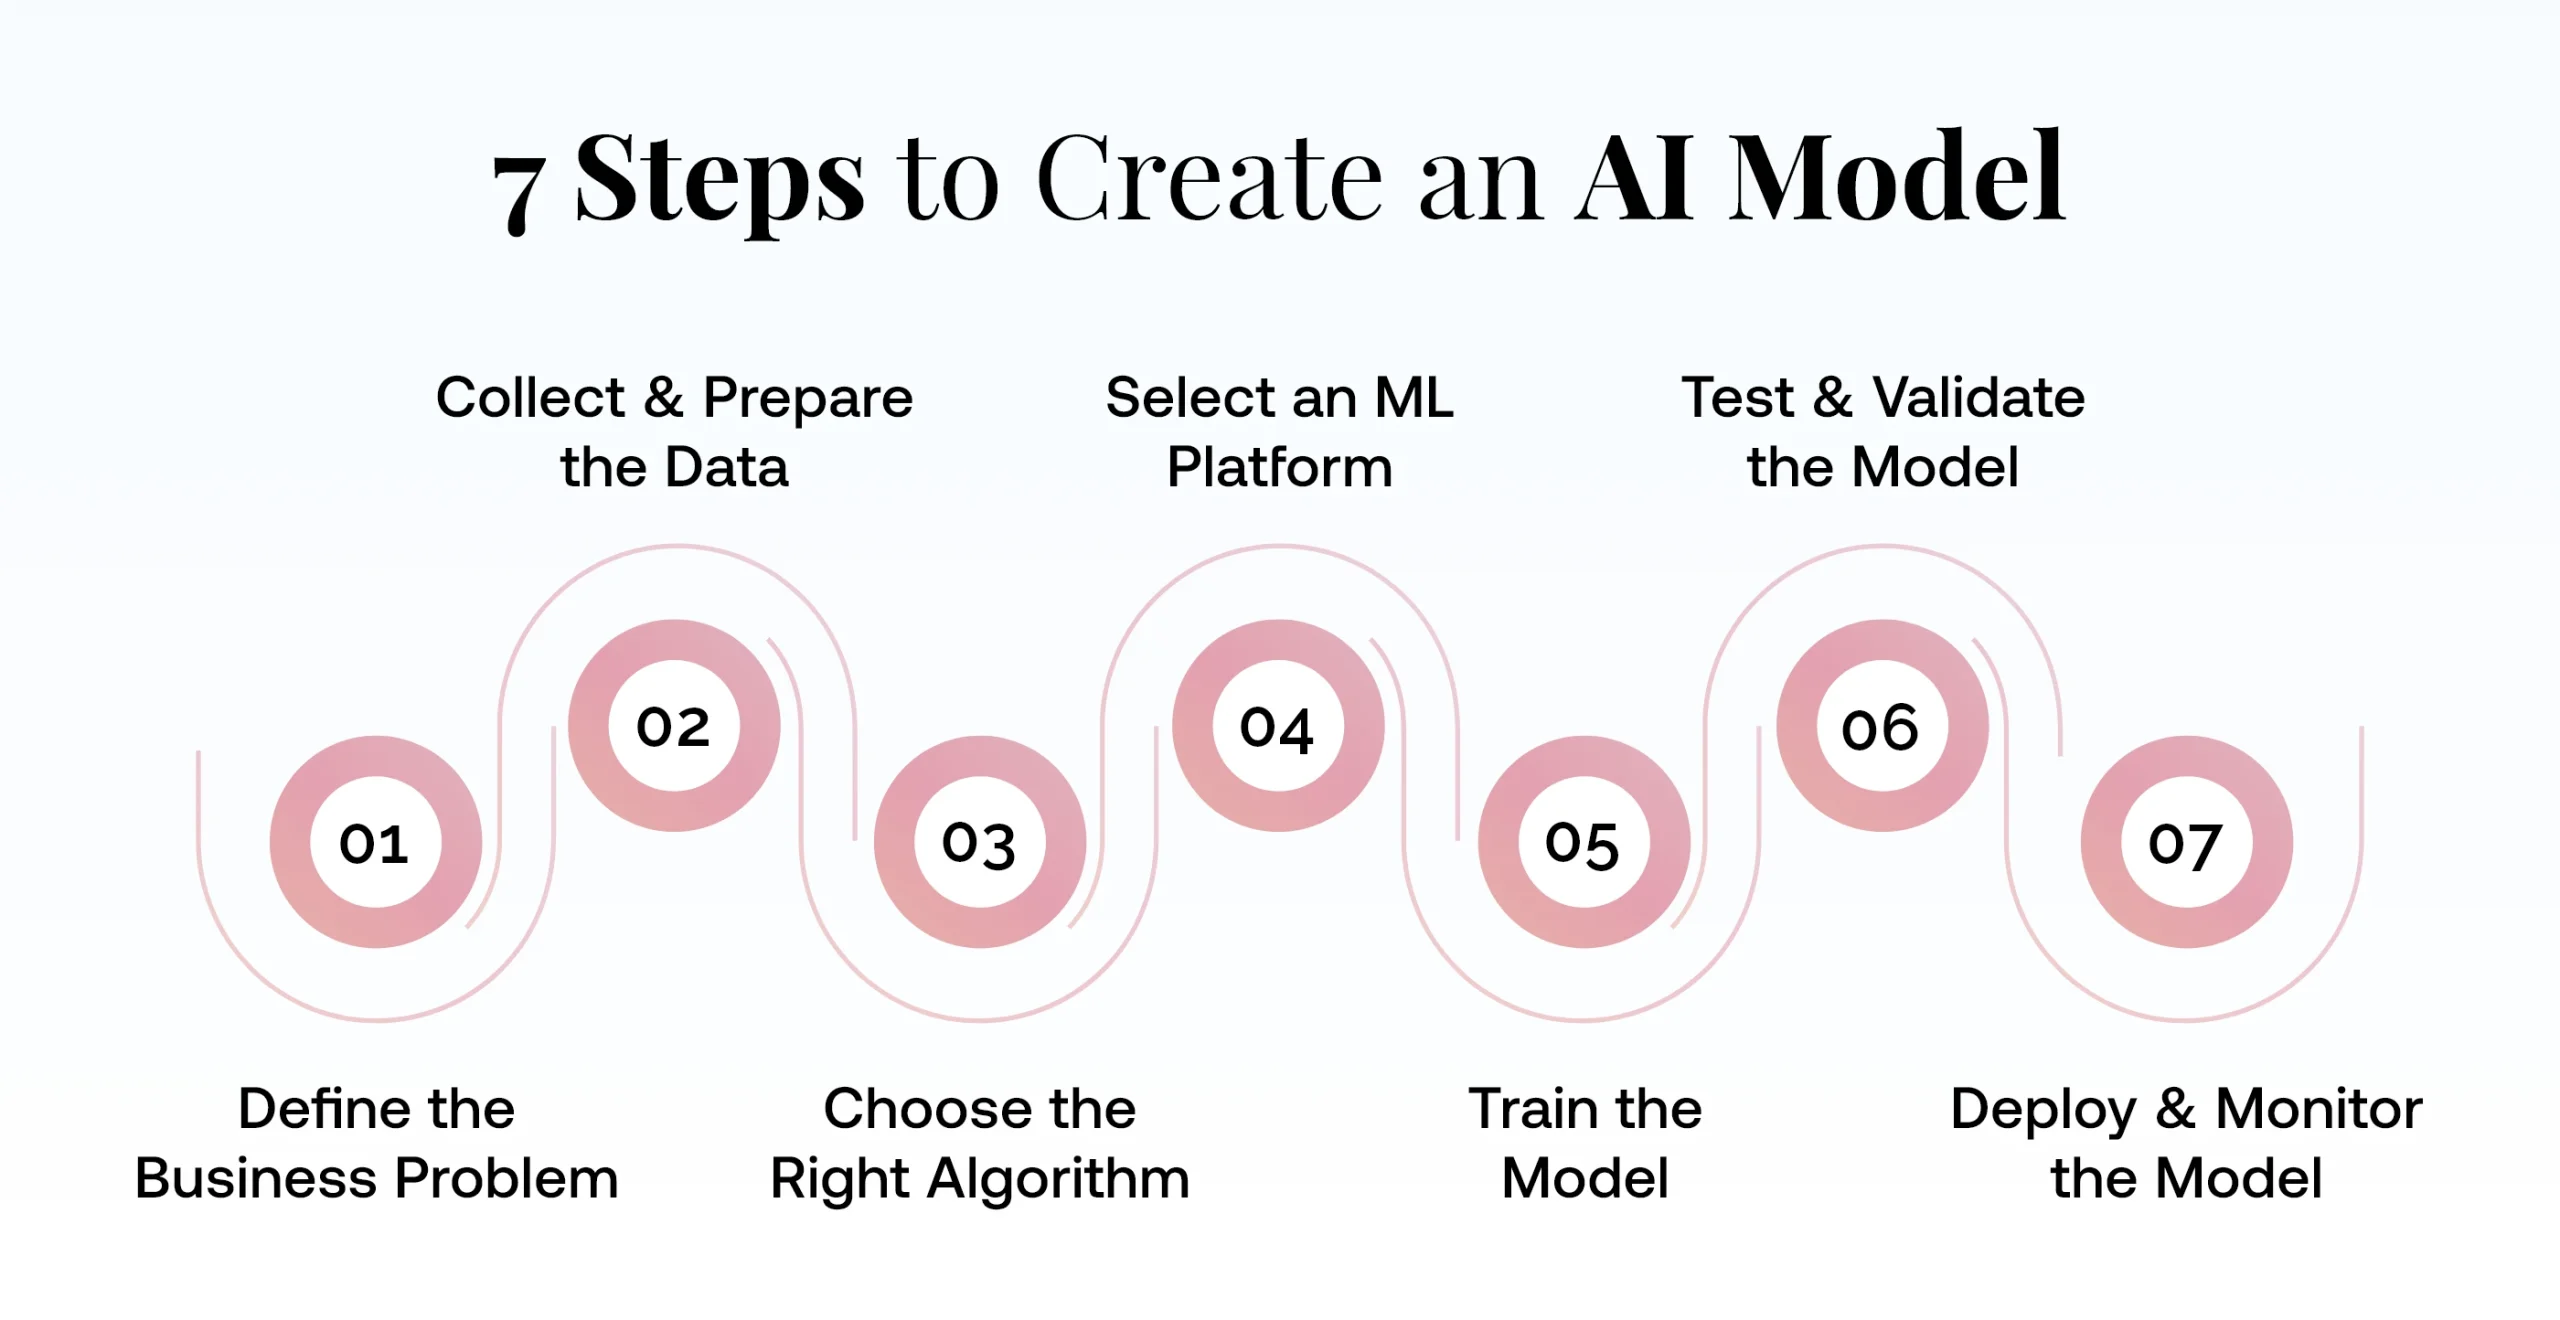
People start with the wrong thing. They open a fresh chat interface and type "build me an AI agent" expecting a structured result. It doesn't work like that. The gap between what the marketing shows and what actually ships in production comes down to a handful of concrete steps that almost nobody explains properly. The modern approach to building with AI isn't a single tool or framework. It's a sequence of decisions. First you pick a base model that matches your output format needs. Then you define the input structure. Then you wrap it in a system that handles failures gracefully. Then you test it against edge cases that the training data never covered. Most people skip straight to step four without doing steps one through three, and wonder why the output looks like a press release written by a committee. I ran into this with a document classification pipeline last year. The model would consistently collapse nuanced categories into whatever felt most probable on average. A legal contract dispute got classified as a "general business inquiry" because the embeddings clustered those topics too closely together in the embedding space. The fix wasn't better prompting. It was adding a structured output layer with explicit decision criteria and a confidence threshold. Anything below 0.82 got routed to a secondary model fine-tuned on that specific domain. Output was no longer a freeform JSON blob but a two-stage pipeline with clear handoff logic.
This is what the step-by-step modern workflow actually looks like in practice.
Pick Your Model Before You Write Any Code
The model choice determines everything after it. Not which model is "best" in some abstract sense. Which model matches your format constraints, latency budget, and cost ceiling. The models that do well at creative generation are usually the worst at structured output. The models that do well at structured output often can't handle long context windows without degradation. There is no universal model. When I built a customer support routing system, I started with a general-purpose model that handled open-ended queries. It produced useful responses but failed on structured extraction tasks about thirty percent of the time. Switching to a model specifically trained on function calling cut that failure rate to under five percent. The tradeoff was slower response times and higher cost per request. Worth it for that use case. Not worth it for a casual chat interface. Look at your output requirement first. Do you need JSON with a specific schema? Do you need conversational prose? Do you need code generation? Match the model to the job, not the other way around. The model card on the provider's documentation page will tell you which benchmarks they were optimized for. Treat that as your first signal.
Get the Full Details

Define the Input Format Strictly
Vague inputs produce vague outputs. This sounds obvious until you watch someone feed a paragraph of unstructured text into a model and then express confusion when the result is a paragraph of equally unstructured text. Structure your input. Even if the user provides messy input, preprocess it before it reaches the model. Strip unnecessary whitespace, normalize dates to a consistent format, extract key entities into a separate field. I use a light preprocessing step that converts raw user messages into a structured dictionary with fields like intent, entities, context, and constraints. The model never sees the raw text. It sees a clean object. This alone cuts hallucination rates significantly. When the model receives structured data with labeled fields, it has less room to invent information to fill gaps. Gaps that don't exist get filled with placeholder values instead of plausible-sounding fabrications.
Build the Guardrails Around the Core Logic
The core logic is the model call. The guardrails are everything else. Rate limiting, output validation, fallback chains, error logging, and human review triggers. Most tutorials skip straight to the model call and pretend the rest happens automatically. It doesn't. After my document classification incident, I added an output validation layer that checks every model response against a predefined schema before it reaches the application. If the response doesn't match, it either gets re-requested with a stricter prompt or routed to a fallback handler. The fallback handler in my case was a smaller, faster model that could handle simpler tasks without the hallucination risk of the larger one. You should also add a confidence threshold. If the model's self-assessed confidence falls below your threshold, route to a human or a secondary verification step. Most providers return a confidence score or probability distribution. Use it. Ignoring it means you're trusting the model on its own terms, and the model's terms are designed for average cases, not edge cases.
Test Against the Weird Stuff
Standard test cases are not enough. The model will pass those by design. You need edge cases. Contradictory inputs. Partially formed questions. Inputs in languages the model has limited exposure to. Requests that deliberately try to push the model outside its intended scope. I keep a running test file with inputs that broke things in production. A user asking "what's the weather in the office" when the office is a fictional location in a novel they're reading. Another input was a mixed-language query combining French and English technical terms about API rate limits. A third was a deliberately adversarial request that tried to extract system instructions by framing them as a creative writing exercise. Each of these exposed different failure modes. Document those failures. Note which inputs cause which problems. Re-run them after every model update or prompt change. This is not optional. Every model update changes behavior in subtle ways that standard benchmarks won't catch.
Measure What Actually Matters
User satisfaction metrics are unreliable. People will say a response was good even when it contained factual errors, especially if the response sounds confident. Instead of tracking engagement, track correctness. Pull a sample of responses weekly and have a human verify them against ground truth. Track the percentage that contain errors, hallucinations, or incomplete answers. Also track latency distribution. Not the average. The p95 and p99. Because when the model takes three seconds on average but occasionally takes twenty seconds, your users are dealing with the twenty-second version, not the average. Cost per successful request matters too. Some implementations look cheap on paper until you factor in retry costs, fallback model costs, and the labor cost of fixing model errors downstream. My document classification system looked expensive until I calculated the cost of incorrect classifications going through manual review. The two-stage pipeline with the confidence threshold was cheaper overall because it reduced downstream labor costs by roughly sixty percent.
When This Approach Doesn't Work
Structured pipelines like this add complexity. They require more upfront work, more testing, and more maintenance than a simple chat interface. If your use case is low-stakes and high-volume with minimal consequences for errors, a simpler approach may be sufficient. A FAQ bot, for example, doesn't need a two-stage classification pipeline with confidence thresholds. If your requirements involve strict accuracy on specialized domains, structured outputs, or handling unpredictable user inputs, then the modern step-by-step approach is necessary. The complexity is the point. It's what separates something that works reliably from something that works sometimes. There are tools that attempt to simplify this entire pipeline into a single interface. They exist. They work for straightforward tasks. They break in predictable ways on anything that requires precision. Knowing when to use them and when to build the pipeline yourself is the actual skill here. The pipeline isn't hard to build once you understand the components. It's hard because people try to assemble it without understanding how each component affects the others.