How Face Swap Actually Works Under the Hood
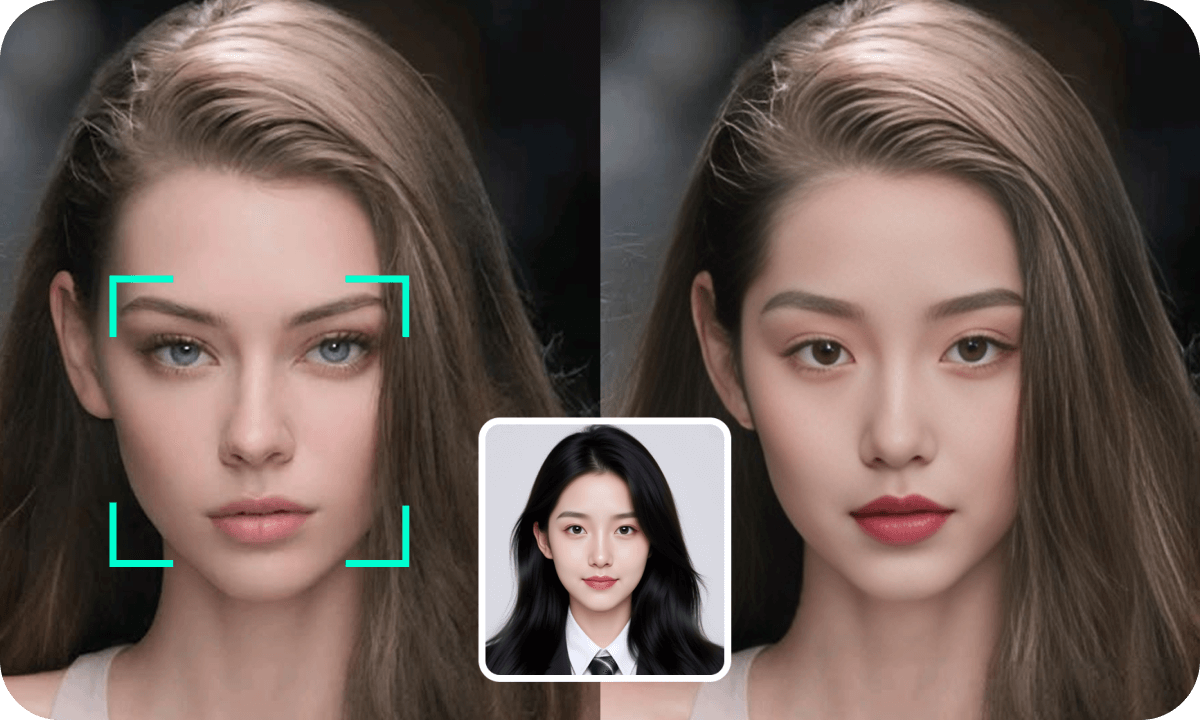
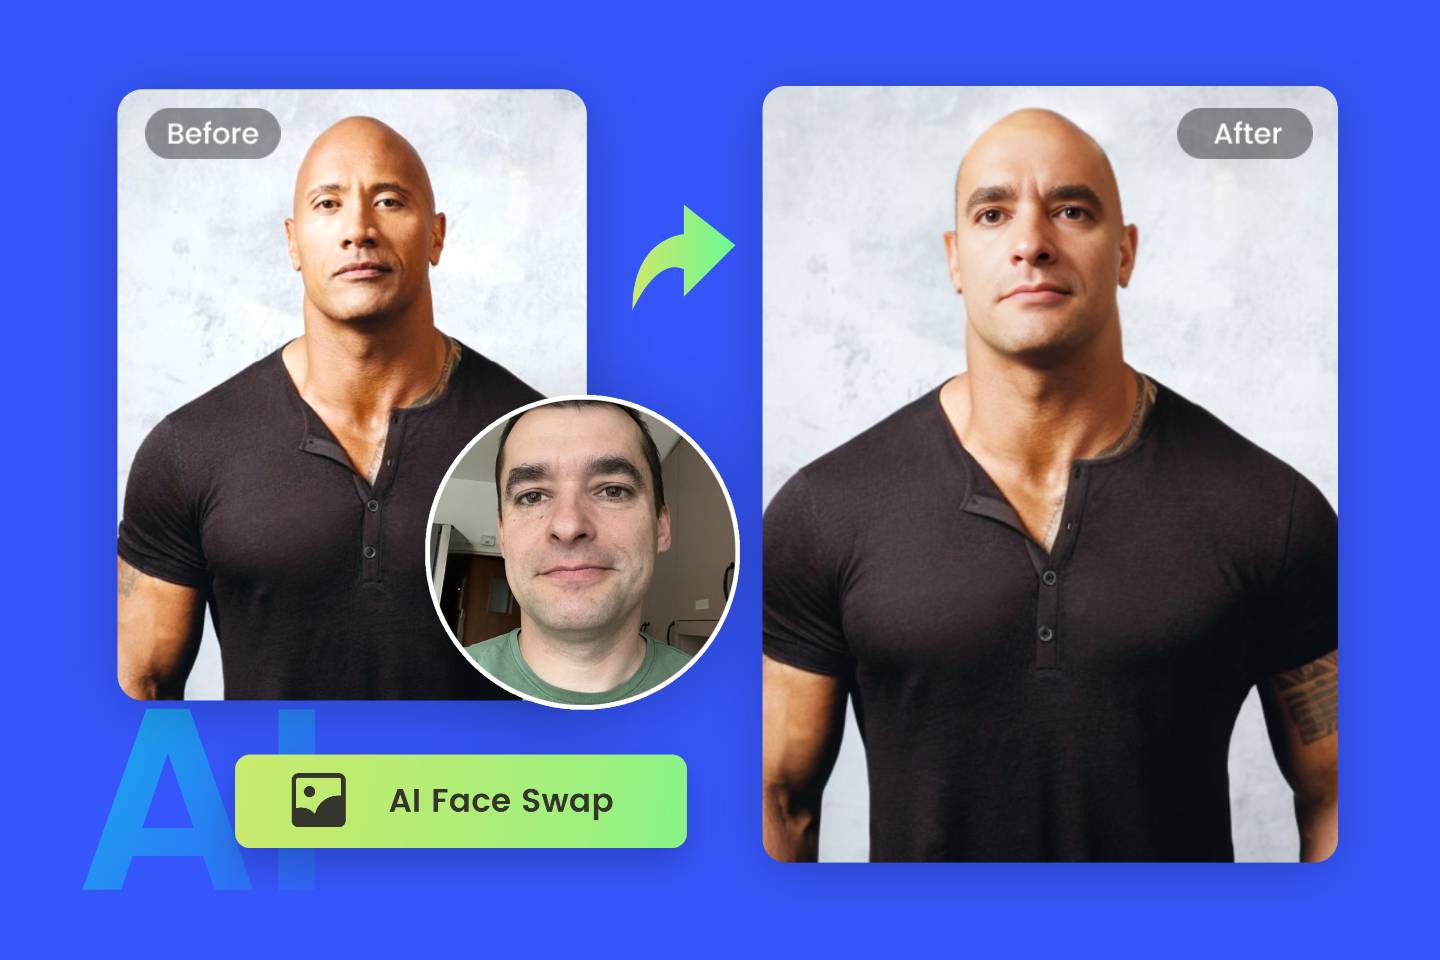
Face swap technology has moved far beyond the crude overlay tricks people remember from early 2010s meme generators. Modern implementations use deep learning models—typically variations of autoencoders and generative adversarial networks—to extract facial features from a source image and reconstruct them onto a target face while preserving lighting, angles, and expression. The result isn't just a cutout pasted on; it's a full synthesis pass that attempts to match skin texture, shadows, and pose. I've spent years working with these pipelines in production environments, and the gap between what the demos show and what you actually get is where most people run into trouble. I'll walk through how to do this properly, what breaks, and where the technology genuinely falls apart.
Ai Technology Face Swap: The Practical Guide
The core workflow involves three distinct stages. First, you run a face detector to locate faces in both images. Second, you extract a facial embedding or landmark set from the source face. Third, you use a reconstruction model to map those features onto the target face geometry while blending the result into the original image. Here's the straightforward version that works for most cases. Grab a recent implementation like DeepFaceLab, FaceFusion, or Roddick's open-source work on GitHub. DeepFaceLab is the heaviest option but gives you the most control. FaceFusion is lighter and runs decently on consumer GPUs. For quick one-off swaps, there are also browser-based tools, though you shouldn't trust those with sensitive content. I typically start with RetinaFace or SCRFD for detection. These are more reliable than the older MTCNN models, especially on non-frontal faces. Once detection is solid, I extract landmarks using a 68-point or 104-point predictor, then feed those into the alignment step. The alignment is where most people mess up. If your source and target faces aren't properly aligned geometrically before the swap, the output looks distorted around the edges. I usually adjust the scale factor manually rather than relying on automatic scaling—it gives you much tighter results.
For the actual encoding and decoding, standard autoencoder architectures like U-Net based encoders work well for still images. If you're doing video, you'll want something that preserves temporal consistency, which means adding optical flow estimation or using a recurrent structure. This is where the process gets complicated quickly. One thing nobody tells you: the training data matters more than the model architecture. I ran a project last year where we swapped faces across different lighting conditions, and the model kept failing on backlit subjects. The issue wasn't the algorithm—it was that our training set had almost no high-contrast backlight examples. We added about 200 more backlit images to the training pool and the quality jumped noticeably. You can't hack your way out of bad training data with better post-processing.
Get the Full Details
Where Things Break and What To Do About It
Face swap has real limitations, and they show up in predictable ways. The most common failure mode is extreme angles. Profiles above roughly 45 degrees from center tend to produce garbled results because most models are trained primarily on near-frontal faces. If you need profile swaps, you'll have to accept lower quality or find a model specifically trained on profile data, which are rare. Another issue is hair and accessories. Models struggle with faces where the source has hair covering part of the forehead or where the target doesn't. The reconstruction tends to either erase eyebrows or blend them into the wrong position. I've worked around this by doing a manual mask pass in Photoshop after the swap, repainting the hair region from the original target image. It adds twenty minutes to the workflow but saves hours of fighting with the model. Color consistency is the third major problem. Even when the geometry looks right, the skin tone from the source face often doesn't match the target's lighting environment. A dedicated color transfer step using methods like Reinhard color mapping or learning-based tone adjustment helps significantly. I usually run a simple histogram matching pass after the swap, which takes about thirty seconds per frame in video projects.
For video specifically, flickering between frames is a persistent issue. The face detection and swap quality varies slightly from frame to frame, creating a jittery appearance. I solve this by running temporal smoothing on the face landmarks before the swap, and then applying a mild motion blur to the face region in the output. It's not perfect, but it reduces the flicker to acceptable levels for most use cases. The smoothing step adds maybe fifteen percent to processing time, which is a reasonable trade-off. I also encountered a specific problem last quarter working on a project that required swapping faces in low-resolution surveillance footage. The faces were tiny—sometimes only thirty pixels wide—and every standard model failed. The workaround was to first upscale the source and target frames using a dedicated super-resolution model like ESRGAN, then run the face swap on the upscaled frames, and finally re-scale everything back down. This added an extra processing step but produced results that were actually usable. Without the upscaling, the face features were too indistinct for any model to work with reliably.
Performance Expectations and Tool Selection
If you're running on a consumer GPU like an RTX 3080 or 4090, expect a single high-quality face swap on a still image to take between three and ten seconds depending on resolution and model size. Video processing scales linearly with frame count—a sixty-second clip at 30fps might take anywhere from twenty minutes to over an hour depending on your settings and the complexity of the scene. CPU-only processing is possible but impractical for anything beyond quick tests. The bottleneck is the convolutional operations in the encoder-decoder pipeline, and CPUs don't handle those efficiently. If you don't have a GPU, you're better off using cloud-based services, though you should be aware of the privacy implications of uploading content to someone else's servers. For most people who just need to do a one-time swap, I'd recommend starting with FaceFusion or similar lightweight tools. They have reasonable defaults, good documentation, and active communities for troubleshooting. If you need production-quality results or are doing this repeatedly, invest time in learning DeepFaceLab or building a custom pipeline with PyTorch. The learning curve is steep but the control you gain is significant.
Don't expect plug-and-perfect results. The technology works well enough for casual use and certain professional applications, but it requires understanding what each parameter does and being willing to iterate. The people getting good results aren't running default settings—they're tweaking landmark detection thresholds, adjusting alignment tolerance, and spending time on post-processing steps that most tutorials skip. The field moves fast. What worked well six months ago may already be outdated. Keep an eye on new releases and papers, but don't chase every novelty. The core techniques haven't changed fundamentally, and mastering the fundamentals will serve you better than jumping between every new tool that drops.