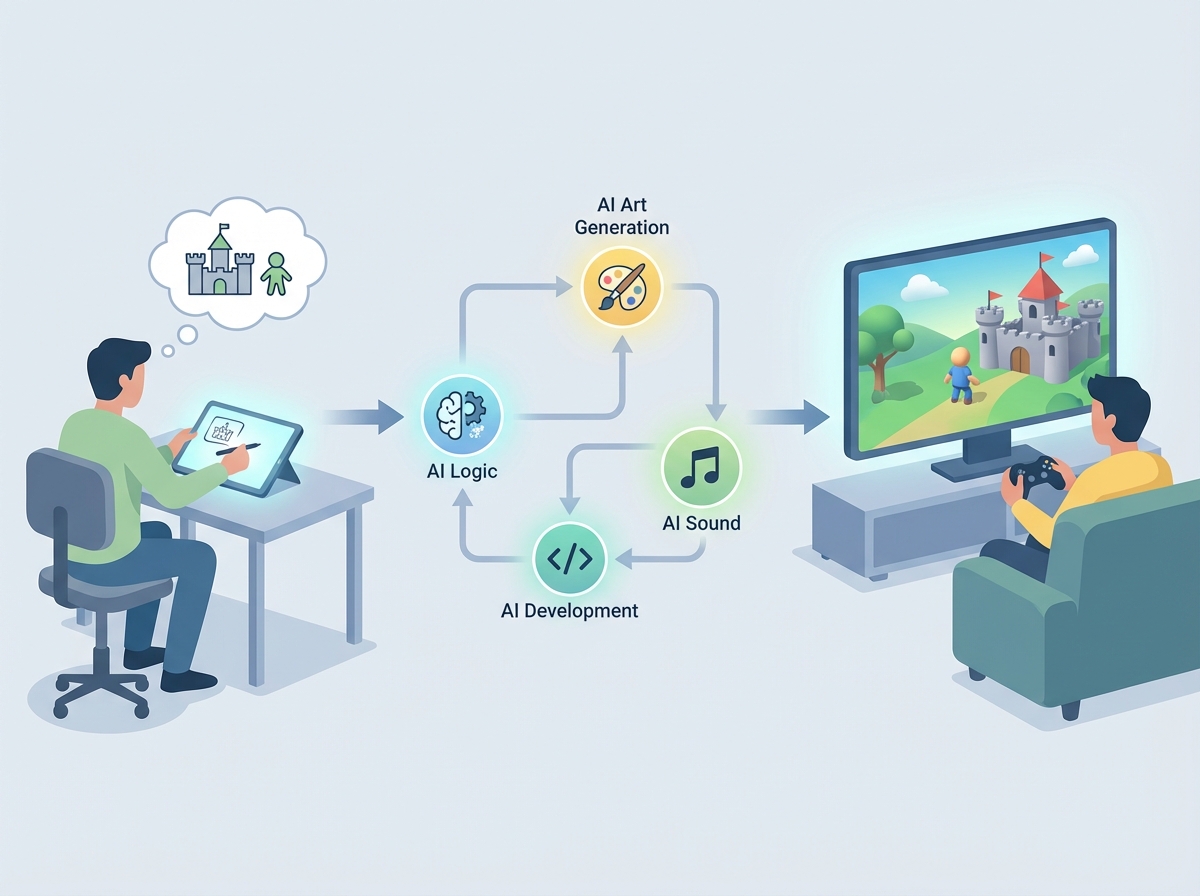
What Ai Tutorial Modern Actually Is
Ai Tutorial Modern is a collection of curated learning paths and workflow templates built around current generative AI tools. It isn't a single piece of software you download. It's more like a framework — a set of structured approaches for learning how to use AI in production workflows. People find it through GitHub repositories, documentation sites, and community forums. The idea is that instead of randomly clicking through tool interfaces, you follow a sequence that builds actual competency. I first ran into it when someone linked to a README file late one evening. I spent about two hours going through the materials and realized I'd been doing things the wrong way the whole time. The difference between a structured approach and random exploration is roughly the difference between spending six hours on a task and spending forty-five minutes on it. It depends on what you're trying to achieve.
Ai Tutorial Modern: Setting Up Your Environment
Before you dive into the actual tutorials, you need to get your environment sorted. Most guides assume you already have Python 3.10 or higher installed, along with pip and a package manager. I'd recommend using a virtual environment from the start. It saves you from dependency conflicts that will otherwise eat up half a day. Run python -m venv tutorial-env, activate it, then install the packages the tutorial lists. Don't skip reading the requirements file. Some tutorials depend on specific versions of libraries like transformers, langchain, or openai, and mixing versions causes silent failures that look like bugs but aren't. Here's something beginners consistently miss: the order in which you install packages matters more than the individual versions. When I was setting up for a vector search project last spring, I installed FAISS before numpy got updated, and my entire pipeline threw shape mismatch errors for three days. The error messages pointed at FAISS but the root cause was a numpy version conflict. Installing numpy and scipy first, then FAISS, fixed it immediately.
How the Tutorials Actually Work
Most Ai Tutorial Modern guides follow a progression pattern. They start with basic prompt engineering, move into API usage, then layer in RAG pipelines, tool use, and finally evaluation. The reason this order exists is practical. Prompting is the foundation. If your prompts are unstable, everything downstream becomes unreliable. I've seen people skip ahead to building complex agent systems before they could reliably format a response, and those projects always collapsed under their own weight. The tutorials typically use one or two demo applications as anchors. Common examples include a research assistant that reads PDFs and answers questions, a code reviewer that analyzes pull requests, or a document classifier. These aren't arbitrary choices. They represent the most common production use cases right now, and they stress-test the same core skills in different combinations. When I worked through the RAG tutorial section recently, I hit a wall with chunk overlap settings. The default overlap of 200 tokens produced fragmented answers on legal documents. My workaround was to switch to semantic chunking using sentence boundaries instead of fixed token counts. It added about ten minutes to preprocessing but improved answer quality noticeably. The tutorial didn't mention this edge case because it assumed a general-purpose document set, not specialized legal or technical writing.
Get the Full Details
Common Pitfalls and What to Watch For
The biggest mistake people make is treating the tutorial as a copy-paste exercise. These guides are designed to be followed, understood, then modified. If you just copy the code without understanding the why behind each step, you'll hit problems you can't solve when you leave the tutorial environment. I see this constantly in community channels. Someone finishes a tutorial, tries to adapt it for their own data, and doesn't know where to begin because they never learned how the pieces connect. Another issue is over-relying on free tier API access during the learning phase. Free tiers have rate limits that vary unpredictably. When your tutorial script hangs because of a 429 error mid-execution, you're not learning anything about the technology. Setting up local models or using a paid tier for learning, even if it's just a small amount, removes this variable and lets you focus on the actual concepts. Token limits also catch people off guard. The default context windows on most models range from 8K to 128K tokens depending on which one you're using. A single Ai Tutorial Modern guide might suggest loading an entire book into context. That works fine in a tutorial with a small sample, but real documents rarely behave the same way. Understanding token counting and implementing proper splitting strategies early prevents headaches later.
Advanced Techniques You Should Know About
Once you're comfortable with the basics, the more interesting work begins. Advanced prompt techniques like chain-of-thought prompting, ReAct patterns, and self-consistency decoding can dramatically improve output quality on complex tasks. The tutorials cover some of this, but usually at a surface level. The real depth comes from experimenting with these techniques across different model families and seeing how they respond differently. Evaluation is another area that most people neglect until it's too late. Building a RAG system that seems to work on three sample queries is not the same as having confidence it will work on your actual use cases. Set up a basic evaluation suite early. Even something simple like a gold standard question-answer pair list with automated scoring gives you a baseline. Without it, you're optimizing blind. I recently benchmarked a pipeline across five different model providers and the ranking changed significantly depending on the task type. A model that excelled at code generation scored poorly on factual QA. The lesson here isn't that any particular model is best. It's that you need to test your specific workload before committing to one provider. The tutorials don't always make this clear because they usually demonstrate with a single model.
Where to Find the Materials
The main resources are hosted on GitHub under various repository names and on dedicated documentation portals. Search for "Ai Tutorial Modern" on GitHub or look for community-maintained lists on platforms like Reddit and Discord. The materials are generally free and openly licensed. Some repositories include video walkthroughs alongside written guides, which can help when a text explanation isn't quite landing. Keep in mind that the field moves fast. A tutorial that was accurate six months ago might reference deprecated APIs or outdated model versions. Always check the repository's issue tracker and recent commits for notes about breaking changes. The maintainers usually update quickly, but there can be a lag between when something breaks and when the docs reflect the fix. The practical result of working through these materials consistently is that you stop feeling like you're guessing with AI tools. You develop a mental model of what each component does, how they interact, and where the failure points are. That's the actual value. The code snippets are temporary. The understanding sticks around.


