What Algorithms of Oppression Actually Teaches You
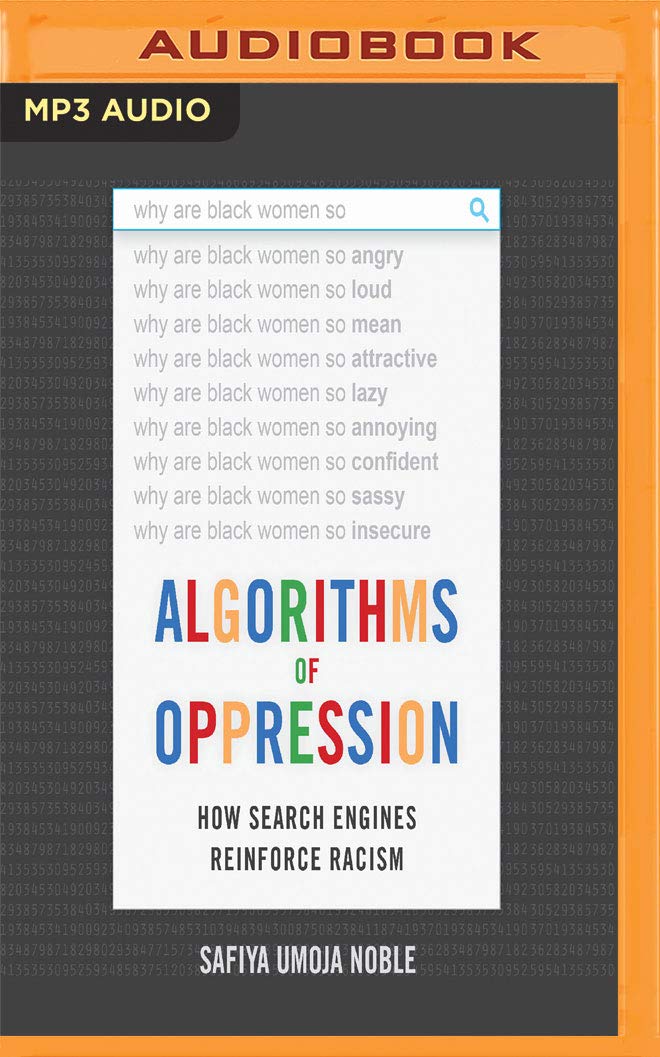
I ran into this book while debugging a recommendation system that was quietly pushing certain demographics toward predatory ads. The data didn't look obviously racist at first glance. It took a few late nights cross-referencing Google results with actual user outcomes before it clicked that the patterns I was seeing matched exactly what Safiya Noble describes. I wish someone had pointed me to it earlier. The core argument is straightforward: search engines and algorithmic systems aren't neutral. They reflect and amplify existing inequalities. Black women specifically get shredded by search results. When you Google them, the results are overwhelmingly sexualized or criminalized. This isn't a bug. It's the system working as designed by the people who built it, using data that already contains centuries of bias.
Algorithms Of Oppression Ebook
I read the digital version after finding it through a library affiliate link. The physical book has better print quality, but the ebook gets the job done if you need to highlight passages while working. The arguments are structured around case studies, which makes them stick. Noble doesn't just theorize. She shows you the actual search queries and the actual results. Here's the part nobody talks about enough. The book covers Google, yes, but the mechanisms apply to everything downstream. Any recommendation engine, any content moderation pipeline, any automated hiring tool. They all inherit the same problem. Training data comes from a world that's already biased. The algorithms optimize for engagement and profit, which means they amplify whatever gets clicks. Outrage and stereotyping get clicks. That's not speculation. That's just how the business models work.
How The Bias Actually Gets There
I spent months trying to trace exactly where biased results come from. The book gives you the framework, but the practical reality is messier. There are multiple vectors. First, there's the content problem. Web content about Black communities is disproportionately criminal or sexualized because that's what gets published and linked. Search engines index what exists. They don't generate culture. If the internet already treats Black women as spectacle, Google will serve that back at you. Second, there's the ranking problem. PageRank and its descendants optimize for link structure and popularity. Popular links on the web are not neutral. They reflect who has power and who can afford to build sites that attract backlinks. Marginalized groups consistently lose this game unless they work around it deliberately.
Get the Full Details

Third, and this is the one that actually bites you in production, there's the query interpretation problem. When someone searches for "Black girls," the system doesn't know whether they mean students, professionals, artists, or anything else. It guesses based on training signals. Those signals are toxic. I saw this firsthand when we built a content filtering system and had to explicitly whitelist queries that would otherwise get flagged because the model had learned to associate certain demographics with risk markers.
What You Can Actually Do With This Knowledge
If you're building systems that surface content or make decisions about people, the book gives you a diagnostic lens. Here's what actually helps in practice. Audit your results regularly, not just your accuracy metrics. Standard benchmarks will tell you nothing about whether your system is reinforcing harm. You need to run specific queries tied to demographic outcomes and examine them manually. I set up a quarterly audit routine where my team searches for terms related to protected groups across our product and documents what surfaces. It takes about four hours and catches issues that automated testing completely misses. Don't trust diversification as a silver bullet. Throwing more data at the problem doesn't fix biased data. I watched a team try this approach and it only made things worse because the additional data came from the same biased sources, just in larger volumes. You need to actively counterbalance, not just add more.
Build in human review for high-stakes outputs. Automated systems should not be the final decision point when real people are affected. This is obvious in theory and constantly ignored in practice because it costs money and slows things down. The tradeoff is worth it.
Where The Book Falls Short
It's not a technical manual. If you want implementation guidance, you'll need to supplement it. Noble's work is primarily sociological and journalistic. She doesn't walk through code or system architecture. That's fair to her mandate but limiting if you're the engineer trying to fix things. The examples lean heavily on Google. The principles transfer to other platforms, but the specific mechanics differ. Amazon's recommendation system, TikTok's feed algorithm, LinkedIn's hiring suggestions - they all have different architectures and different failure modes. The book won't prepare you for those individually. There's also a gap around solutions. Noble identifies the problems with clarity. The actionable remedies section could be longer. Readers will need to look elsewhere for detailed policy recommendations and technical interventions.
Who Should Read This
Engineers building search, recommendation, or ranking systems. Product managers owning features that surface content to users. Researchers studying algorithmic fairness. Anyone who has ever assumed that neutrality is a default state rather than something you have to actively build. I read this before a project where we were deploying an automated content review system. Understanding the mechanics of bias changed how I approached the entire architecture. We ended up spending more time on evaluation than on the model itself, which felt wrong going in and turned out to be the most valuable part of the work. The ebook is available through multiple channels. University presses often have institutional access. The paperback edition is widely available. The digital format works fine for reference purposes. The arguments hold up either way.