A Practical Look at Working With All The Real Numbers
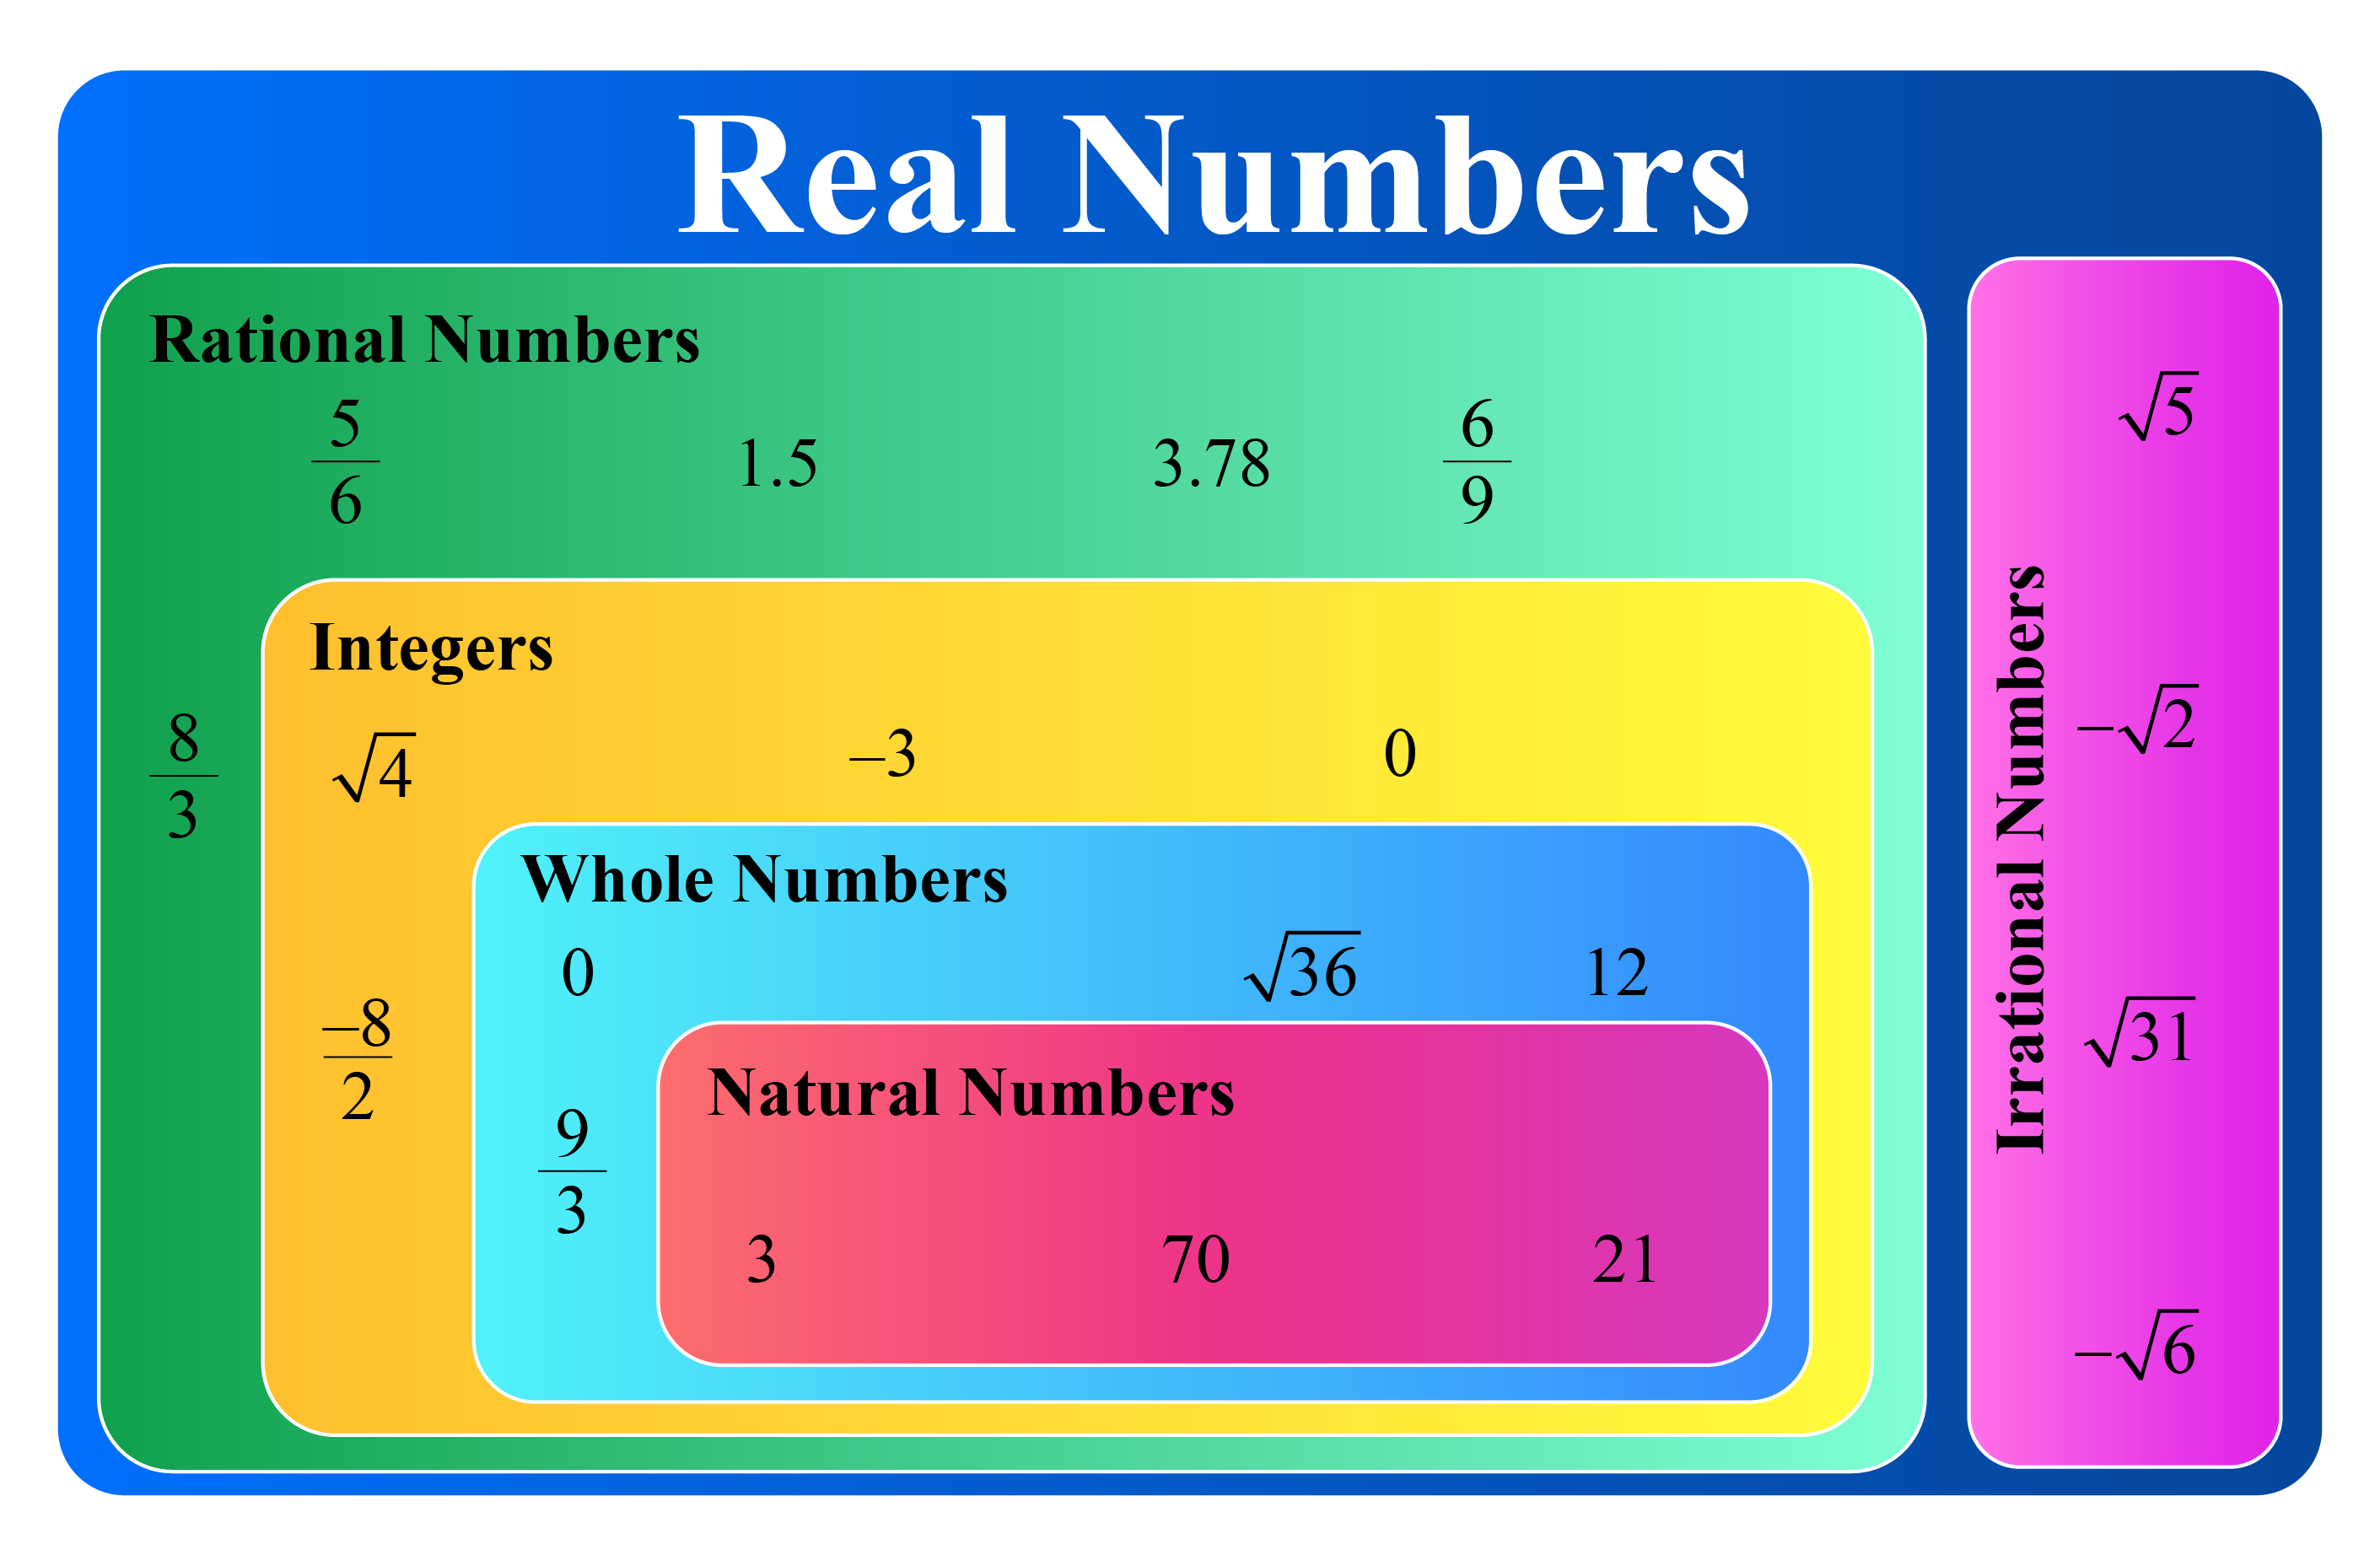
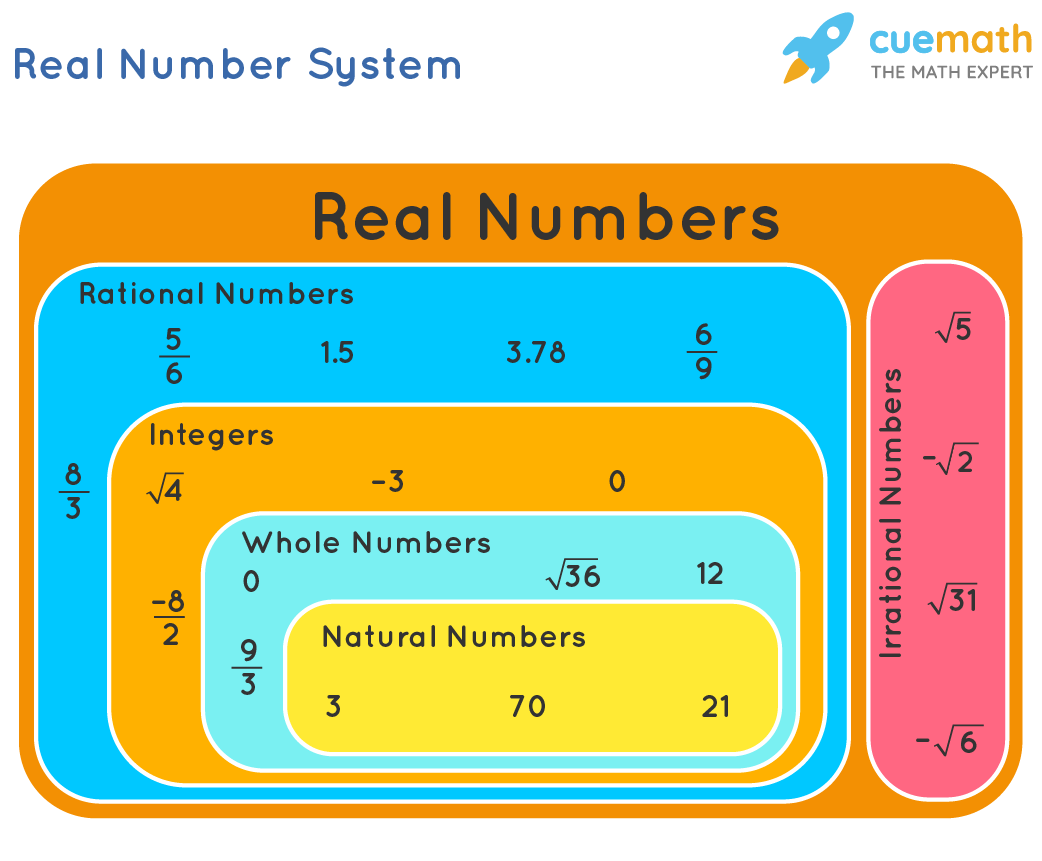
People search for "All The Real Numbers" constantly. Usually because they're building something that requires dense numerical coverage and got tired of hand-rolling their own sequences. The basic idea is simple enough: you want a source that gives you real numbers across whatever range or distribution you need without doing the math yourself. I've used various implementations over the years, and here is how the whole thing actually goes when you stop reading the marketing copy. All The Real Numbers isn't a single magic file. It is a concept that different tools implement differently. Some give you a fixed-size dataset. Others generate on the fly. A few attempt to cover irrational numbers, which is where things get immediately complicated and most people bail out of their implementation very quickly. The practical version that most engineers end up using is a generator or library that produces random reals across configurable ranges, distributions, and precisions. Uniform. Normal. Exponential. Whatever your testing or modeling pipeline demands. If someone is selling you a literal exhaustive list of all real numbers, they are not being serious. There are uncountably infinitely many of them.
How to Actually Use It Without Wasting Two Days
I went down the wrong path early on. I found a project that promised All The Real Numbers as a downloadable CSV spanning everything from negative infinity to positive infinity with normal distribution. The file was 40 gigabytes. It was also just a bunch of repeated values because the sampling algorithm had a bug that clumped everything around the mean. I wasted a weekend on that before I realized I should have just written four lines of code. Here is the straightforward approach most people should start with. Pick a language you are already comfortable in. If you are doing Python work, NumPy handles this natively. If you are in JavaScript, Math.random() with scaling functions gets you uniform reals, and you can layer Box-Muller transforms on top for normal distributions. For production-grade randomness, look at PCG or Xorshift based generators instead of whatever default your language provides.
Setting Up a Reliable Generator Pipeline
The first thing you need to decide is your range and your distribution. That sounds obvious but it is where most projects go sideways. I was working on a numerical integration test once where I needed reals between zero and one with heavy tail coverage. I used a standard uniform generator and wondered why my boundary cases never triggered. The fix was switching to a beta distribution with parameters alpha of 0.5 and beta of 0.5, which is the arcsine distribution. It concentrates mass near the edges exactly where I needed it. If you are generating for unit tests, seed everything. Reproducibility matters more than people admit. Set a fixed seed, log the parameters, and store the seed with your test data. Otherwise you will spend three hours debugging a flaky test that only fails on CI because the random sequence changed.
Get the Full Details
Common Pitfalls That Will Bite You
Floating point representation is the thing nobody warns you about until it is too late. When you generate "random reals" and then cast them to floats, you are not actually getting true real numbers. You are getting IEEE 754 approximations. The gap between adjacent representable numbers changes as values get larger. Around one, the spacing is about 2.2e-16. Around one million, it jumps to about 0.00012. This matters enormously if you are doing things like equality checks or distance calculations in high-value ranges. Another issue I ran into involved decimal rounding in financial contexts. A colleague was generating test data with All The Real Numbers for a payment processing system. The values looked fine on the surface. But when we summed thousands of them, the floating point drift added up to nearly forty cents in discrepancies. The workaround was switching to decimal types or integer-based cent representations from the start. Not a fun discovery to make after integration.
When All The Real Numbers Falls Short
There are scenarios where generator-based approaches completely fail. If you need cryptographically secure randomness, standard math libraries are not sufficient. If you need provably uniform coverage across a continuous domain for formal verification, pseudo-random generators don't cut it either. For those cases you need specialized tools like GMP for arbitrary precision or SPHINCS+-based random number generation if security is the priority. Also worth noting: distributed generation introduces its own headaches. If you are splitting generation across multiple workers, you need to coordinate seeds carefully or you will get overlaps in your coverage. I once had a Spark job where two partitions produced nearly identical value sets because the seed derivation function wasn't spreading the space properly. The fix was using a counter-based approach where each partition gets a derived seed from a master key and its partition index.
Practical Implementation You Can Use Today
For most people, a focused generator class is enough. Here is a minimal but robust pattern I keep around. Define your range, pick your distribution, set your seed strategy, and expose a method that returns values with proper type handling. Wrap the floating point logic so you can swap implementations later without touching the rest of your codebase. If you want a ready-made solution, the NumPy random module covers 90 percent of use cases out of the box. For JavaScript projects, random-js or seedrandom give you the reproducibility and distribution options you need. In Go, the standard math/rand package with a custom source works fine for non-crypto use, and crypto/rand when you actually need it. The whole thing takes about fifteen minutes to set up properly if you aren't overthinking it. The people who struggle are the ones who treat it like a trivial task and then spend weeks debugging issues that came from a bad distribution choice or an unseeded generator in a multithreaded context.
Where to Find Resources
Search for All The Real Numbers tools alongside your specific language and distribution needs. The generic searches mostly return math textbooks. Add terms like "generator," "random real numbers," or "continuous distribution sampling" and you will find the actual implementations. Check the documentation for seed management, overflow behavior, and whether the generator handles edge cases like denormalized numbers correctly. Those details separate usable tools from things that look fine until your data hits five million rows.