Getting Your Head Around AMC as a Working Advertiser
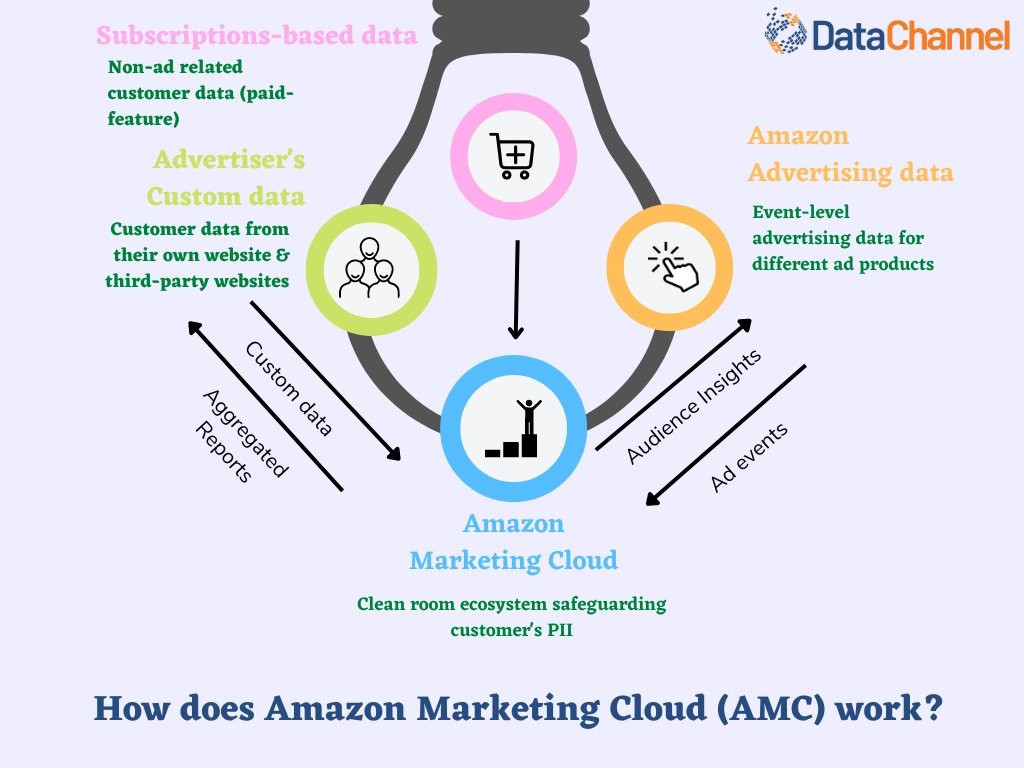
AMC is not a dashboard you open and immediately understand. It is a sandboxed SQL environment where Amazon stores anonymized click and view data from every ad type they run, and then asks you to query that data yourself. Most people treat it like another Amazon Analytics report and get frustrated within an hour. The reason is simple: you are not reading reports anymore. You are writing queries against a data warehouse that has its own rules about how long data sticks around, which tables you can touch, and how much memory your queries can use. I spent about three weeks going in circles before I actually got useful output. The turning point was realizing that AMC does not give you free rein. Your queries are limited to 10 minutes of execution time, you only get a few thousand rows back per result set, and if you join across the wrong tables you will burn your query credits in seconds.
What Amc Amazon Marketing Cloud Actually Is
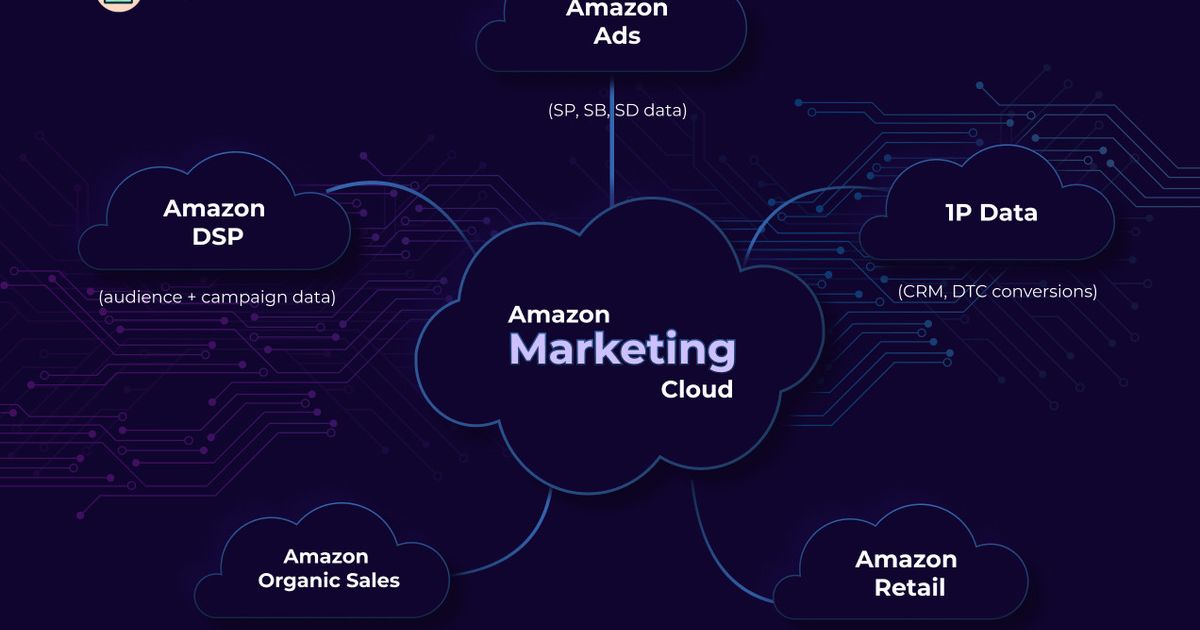
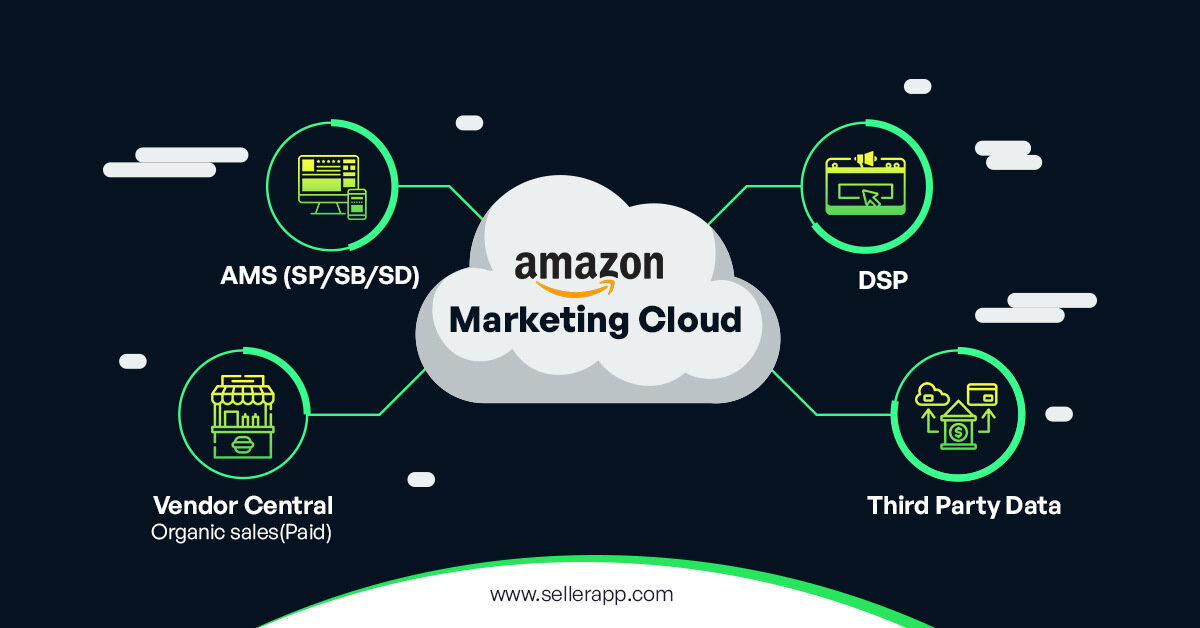
Amazon Marketing Cloud is Amazon's answer to clean room analytics. It gives advertisers a private environment where they can combine their own first-party data with Amazon advertising data, run SQL queries, and produce audience segments or attribution models that go beyond what the standard Amazon Advertising console shows you. The platform launched around 2022 and has been expanded since. You access it through the Amazon Advertising portal, and you need an approved seller or agency account with media spend on Amazon to get in. The core tables you will touch are the campaign-level data, the ad-level data, the product-level data, and the audience or segment tables if your account has them set up. There is also an external data upload feature where you can bring in CSV files with your own customer IDs, email hashes, or SKUs so you can join them against Amazon's ad event streams. Here is a basic query pattern that works if you are just starting out:
SELECT
  s.ad_group_id,
  s.campaign_id,
  SUM(s.spend) AS total_spend,
  COUNT(DISTINCT s.asin) AS asins_impacted
FROM "amazon_advertising"."sponsored_products"."atom"
WHERE s.event_date BETWEEN '2024-01-01' AND '2024-03-31'
GROUP BY 1, 2
ORDER BY total_spend DESC
LIMIT 500
That alone will not win you any awards, but it confirms your connection works and that you can pull spend data without getting throttled. Once you know the table paths and column names are accurate, you can build more complex joins. One thing beginners miss completely is that your query execution budget resets on a schedule tied to your account tier. If you are on the base access level, you might get something like a few hundred query credits per day. High spend accounts get more, but it still scales with your approved media volume. Run twenty heavy joins in an hour and you will hit the wall before lunch. Write smaller queries, batch them, and cache intermediate results instead of running one massive monolithic query every time.
Get the Full Details
How to Upload Your Own Data
This is where AMC becomes useful for most of us. The built-in Amazon data is rich, but it is generic across all sellers in your segment. When you upload your own data, you can link ad events to your actual customers or at least to your actual SKU master list. You upload CSV files through the AMC portal. Amazon expects a specific schema. Your file needs at least one key column that can be hashed, and they strongly recommend using hashed emails or hashed device IDs so your data survives their privacy filtering. If you upload raw PII, Amazon will reject the file or strip the identifying fields before it ever reaches your queryable tables. I learned this the hard way. I uploaded a CSV with about 40,000 rows of customer email addresses in plaintext. Amazon accepted the upload, but when I tried to join it in my query, the email column had been hashed server-side and I could not match it back to my CRM. The workaround was to hash my emails myself using SHA-256 before upload, matching whatever format Amazon requires for your account tier. They publish the hashing guidance in the console, but it is easy to skim past if you are rushing. After I re-uploaded with pre-hashed keys, the join worked on the first try and I finally got attribution that matched my shop manager exports within about five percent. That five percent gap exists because Amazon's attribution window and your internal tracking window are not identical, which is normal and expected.
A Practical Use Case: Cross-Channel Attribution
Let's say you run Meta ads, Google ads, and Amazon ads. You want to know whether people who saw your Meta ads were more likely to convert on Amazon than people who only saw Amazon ads. This is exactly the kind of analysis AMC was built for, and it is also exactly the kind of analysis people get wrong because they do not filter out organic traffic properly. Here is a more realistic query structure for that scenario. I am assuming you have uploaded a segmented audience file with a hashed customer key and a column that labels each person as Meta_exposed, Amazon_only, or Organic:
SELECT
  COALESCE(aud.segment_type, 'unknown') AS audience_segment,
  COUNT(DISTINCT aud.customer_key) AS unique_customers,
  SUM(CASE WHEN sp.event_type = 'buy' THEN 1 ELSE 0 END) AS purchases,
  SUM(sp.spend) AS ad_spend
FROM "amazon_advertising"."sponsored_products"."atom" sp
JOIN "your_schema"."audience_segments" aud
  ON sp.customer_key = aud.customer_key
WHERE sp.event_date BETWEEN '2024-06-01' AND '2024-08-31'
GROUP BY 1
ORDER BY purchases DESC
The problem most people hit here is that their audience table contains duplicate customer keys because they uploaded multiple lists without deduplicating first. AMC does not silently deduplicate your join key. If a customer appears three times in your segment table, they count three times in the join, which inflates your purchaser counts and makes the Meta_exposed segment look artificially stronger. I found this when my numbers did not match any dashboard I had. I added a DISTINCT subquery around the audience table before joining, and the results corrected themselves almost immediately. AMC is powerful, but it has real limitations that you need to accept upfront. The first one is query performance. If you write a join that pulls millions of rows from both sides, your query will either time out or return partial results depending on your allocation tier. There is no way to increase that timeout on lower tiers. You have to rewrite the query to filter earlier, push aggregations into subqueries, or split the analysis into smaller date ranges. The second limitation is the data delay. Events are not real time. You are usually looking at data that is 24 to 48 hours old, sometimes longer during peak seasons. If you run a query on Tuesday morning expecting Monday's full day of data, you might find gaps at the tail end. I started scheduling my weekly refreshes for Thursday mornings instead, which gave the data pipeline enough time to settle.

There is also the issue of suppressed data. Amazon applies statistical noise or suppression to certain cells when the underlying audience size drops below a privacy threshold. You will not always get an error message. Sometimes your query just returns fewer rows than you expect, or certain segment combinations vanish entirely. The workaround is to increase your date range or combine adjacent segments until the count passes Amazon's minimum threshold. It is annoying, but it is how the platform keeps seller-level data from being reverse-engineered. Another structural limitation is that you cannot export raw event-level data. You can export aggregated query results, but you cannot download the underlying millions of impression or click records for offline processing. If your workflow depends on piping raw clickstreams into a third-party data science tool, AMC is not going to support that. You need to keep using AWS Athena or Redshift shifts with your own logging infrastructure for that depth. Finally, there is the access approval bottleneck. Getting approved for AMC can take days or weeks, especially for new agency accounts. The review checks your spend history, your account standing, and whether you have a legitimate advertising business. I had one client whose application sat in pending for eleven days because their brand registry was still being processed in the background. They had to resolve the registry issue before Amazon would flip the switch. If you are planning to run campaigns through AMC, start the approval process before you need it, not after.
What to Do Instead If AMC Is Too Much Friction
If your team does not have SQL experience or your query volume is too low to justify the learning curve, the Amazon Advertising API with Python is a reasonable alternative. You can pull campaign data, ad group data, and keyword data programmatically, and you can join it with your own CRM exports in a Jupyter notebook or a simple database. It takes longer to set up the initial pipeline, maybe two to three weeks for a solid foundation, but once it is running it runs itself and you are not fighting query timeouts or segment suppression. For most mid-sized sellers though, AMC is worth the initial pain. The cross-ad-type analysis, the ability to combine your uploaded data with Amazon's event stream, and the fact that the queries run server-side without you needing to host anything makes it hard to replace. The trick is to stop treating it like a reporting tool and start treating it like a lightweight data warehouse you query sparingly and deliberately.