Working With American Regional Speech Patterns
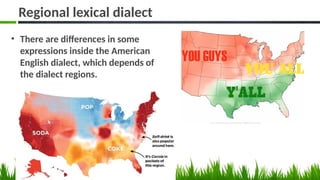
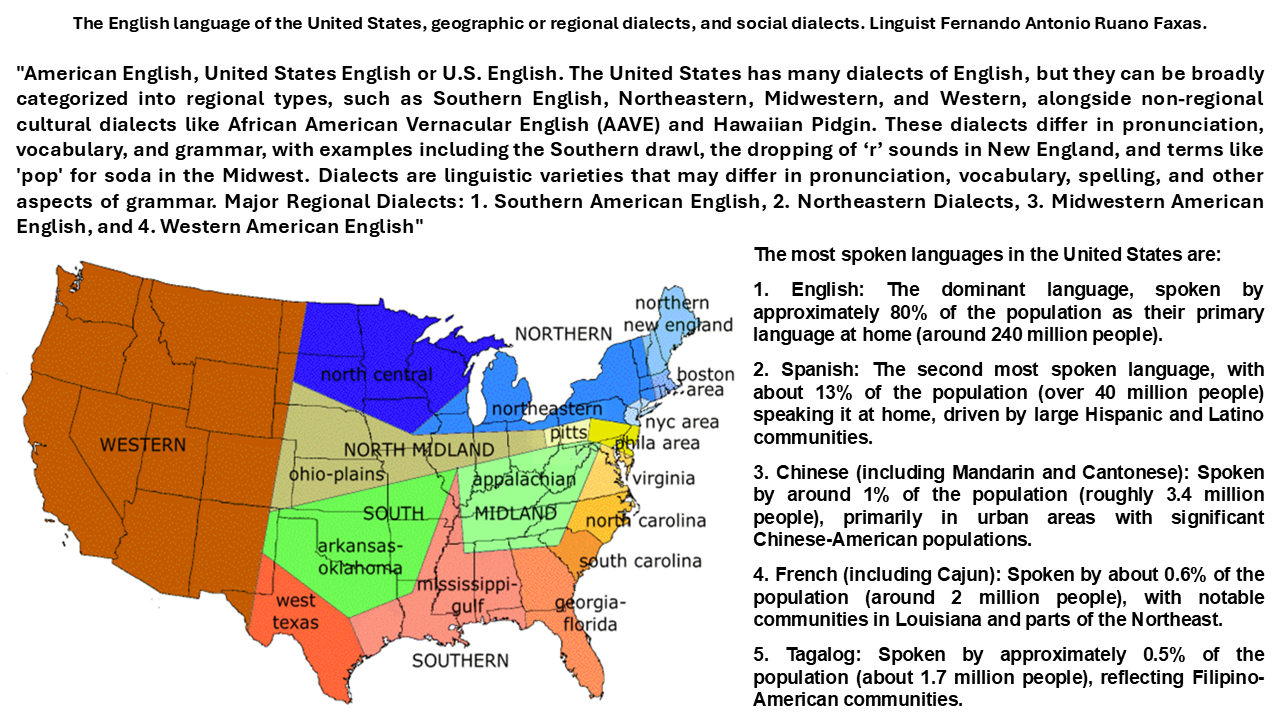
I spent years transcribing recorded interviews across the Southeast and Midwest, and the moment you stop correcting for dialect you realize how much data gets lost when you treat every variation as an error. American English Dialects And Variation Language In Society isn't some linguistic curiosity — it's a daily operational problem for anyone doing field research, content moderation, or customer service routing. The people who try to standardize everything at the collection stage end up with clean data and wrong answers. Start with the phonological map before you touch any software. The major divides are Northern Cities Shift, Southern Vowel Merge, General American rhoticity, and the trap vowel region that cuts through parts of New England and Eastern Canada. You don't need to memorize the Linguistic Atlas database, but you do need to recognize that "cot" and "caught" being pronounced differently is not universal. It is actually the exception in roughly 60 percent of the United States. If you're building a voice model or training a transcription pipeline, assuming rhotic pronunciation everywhere will bias your accuracy downward in places like Philadelphia, Boston, and parts of Alabama without you ever realizing where the drop is happening. I ran into this in 2019 when a client needed transcription models tuned for a healthcare intake system deployed in rural Georgia and Upstate New York simultaneously. The vendor's base model scored 94 percent word error rate in Georgia and 89 percent in New York. We thought the Georgia recordings were just low quality at first. Turns out the model had never seen the Southern Vowel Merge in training data, and the New York recordings triggered the Northern Cities Shift — both pushed words like "bite" toward "boyt" and "deck" toward "deek." The fix wasn't adding more data. It was applying a targeted phoneme-level augmentation layer that shifted the acoustic model's vowel space to match the regional distributions instead of fighting them. Cost about three weeks of engineering and cut the error rate to under 7 percent in both regions. Had we just collected more samples without the augmentation, we'd be running the same problem forever.
How to Approach This Practically
Don't start by hiring a dialect coach. Start by identifying your geographic constraints and your tolerance for variation. If you're working with a narrow region, local accent consultants can help you build custom lexicons and phonetic guides. If you're covering multiple regions, you need a hybrid approach — regional phoneme maps combined with automatic speech recognition models fine-tuned on localized corpora. The Southern America Voices Corpus, the Philadelphia Speech Corpus, and the Midwest English Language Audio Resource are publicly available starting points, though none of them are complete for every subregion. The thing nobody tells you is that sociolect matters more than geolect in most real-world deployments. Two speakers from the same town in Mississippi may sound nothing like each other if one grows up in a rural community and the other in a military housing area. Code-switching, bilingualism, and socioeconomic speech patterns often produce more transcription errors than regional vowels do. I've seen teams spend months tuning models for Southern drawl variations while completely missing that the actual bottleneck was AAE-influenced phonology in mixed-race suburban data. The model kept "neutralizing" grammatical markers and mis-parsing pronoun references.
Common Pitfalls
Standardization bias is the first trap. People in this field will tell you to ask speakers to "read naturally" and then punish them when they don't produce General American. That produces data that doesn't reflect your actual use case. If your system will be used by people who speak with regional features, your training data needs to include those features. Not as noise to filter out, but as signal to learn from. The second trap is overcorrecting. Some teams try to normalize all speech to a single phonetic standard before feeding it into downstream pipelines. That works for some transcription tasks, but it destroys information that sentiment analysis and intent classification models actually depend on. A speaker saying "y'all gonna be alright" carries different pragmatic weight than "you are going to be okay," and stripping the dialect out makes both sentences identical to a classifier. You lose the nuance that matters.
Get the Full Details
What This Doesn't Solve
No amount of dialect work will fix a fundamentally broken data pipeline. If your recording setup captures audio at 8 kilohertz with a cheap membrane microphone, your phoneme-level tuning is wasted effort. Sample rate and signal-to-noise ratio matter more than whether your model understands the cot-caught distinction. I once watched a team try to solve a transcription accuracy problem for two days by adjusting vowel shift parameters while their microphones were picking up HVAC noise at roughly 400 hertz. Fix the recording chain first. Everything else follows. Also, dialect models have a shelf life. Speech patterns shift. The Northern Cities Shift has been weakening among younger speakers in Detroit and Chicago over the past decade. The Southern Shift hasn't spread northward as quickly as some researchers predicted in the early 2000s. If you build a system on dialect assumptions from 2015, it may already be slightly misaligned with current usage. Budget for periodic re-evaluation, ideally every two to three years depending on your region and demographic.
Tools Worth Knowing
For transcription work, Kaldi and its derivatives remain the baseline, but the newer transformer-based models like Whisper and its fine-tuned variants handle dialect variation better out of the box if you're willing to add regional fine-tuning data. Kaldi still wins if you need maximum control over phonetic modeling and you have engineering capacity. The Whisper family wins on setup speed and acceptable accuracy for most use cases once you've added a modest regional dataset. If you're doing smaller-scale projects without a dedicated ML team, look at AssemblyAI and Rev's business tiers. They don't advertise regional support, but their models have been trained on more diverse data than most public datasets. The tradeoff is cost and lack of customization. You get what you get. For anything requiring real adaptation to a specific dialect community, you're still looking at custom fine-tuning. The core lesson is straightforward: dialect variation is data, not noise. Treat it like noise and your system will fail in predictable ways. Most failures happen quietly — accuracy looks fine on paper until you deploy in the actual environment your users inhabit. The fixes are usually practical and expensive in engineering time rather than money, and they require admitting that your initial assumption about what counts as "standard" speech was wrong to begin with.