Why Two-Way ANOVA Keeps Tripping People Up
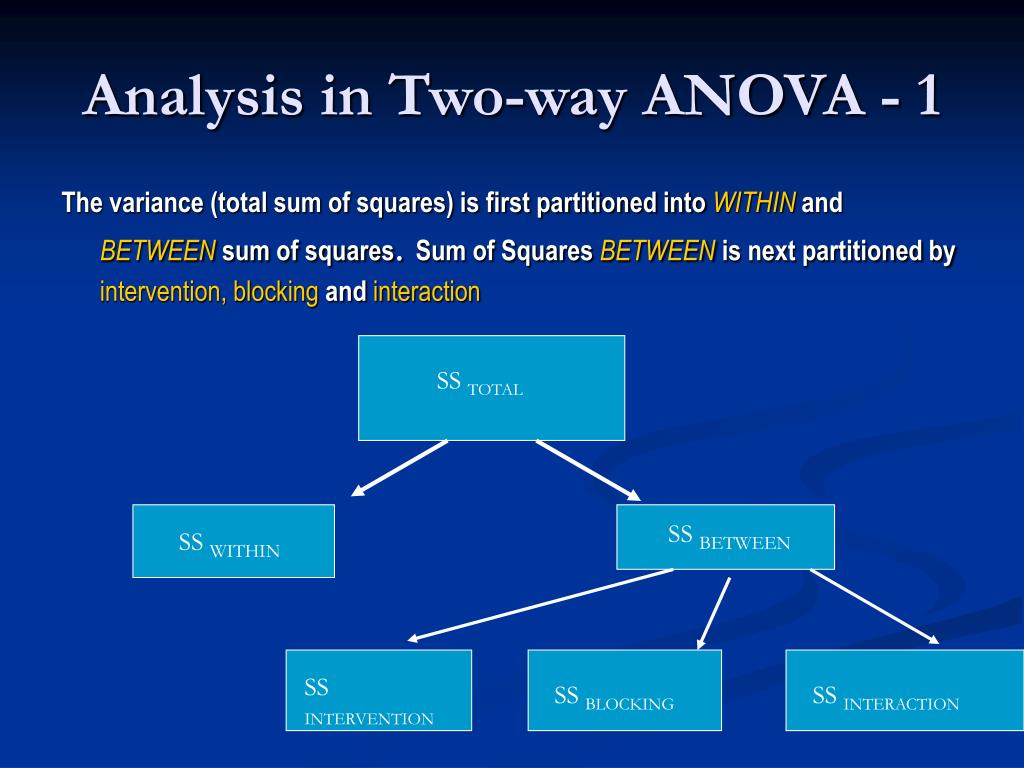
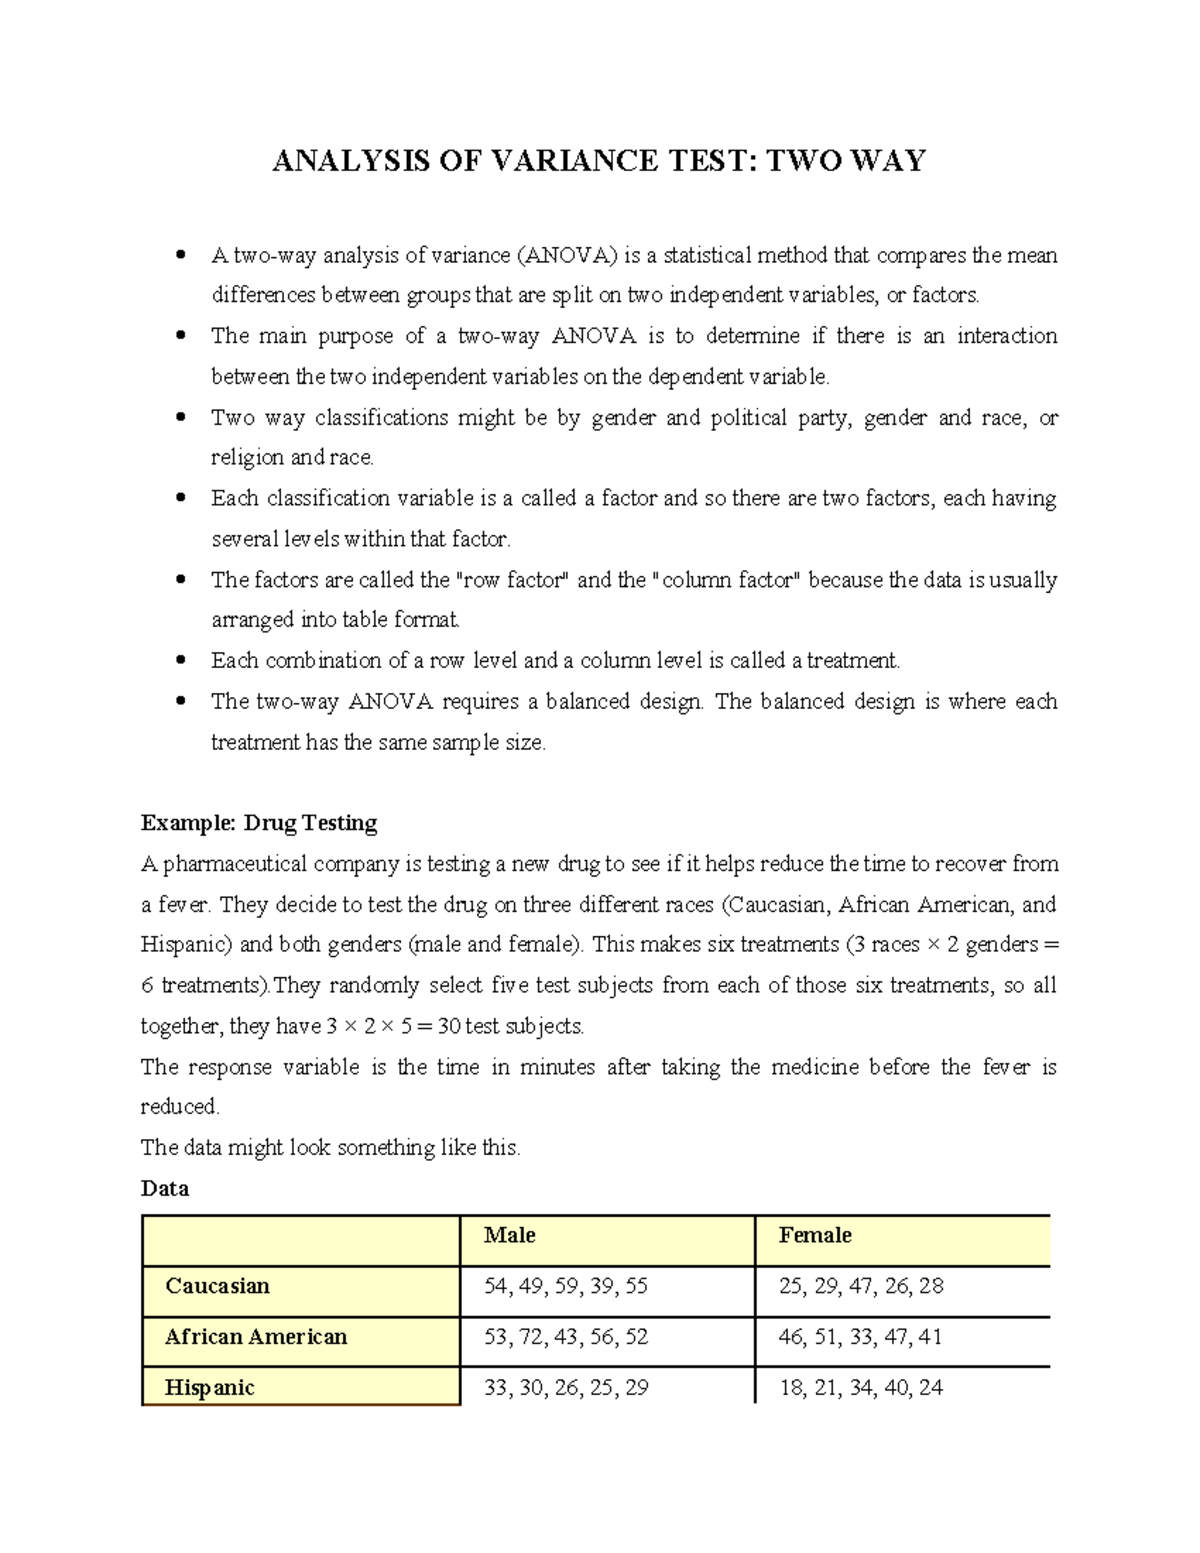
I spent last week running a two-way ANOVA on some soil treatment data, and it hit me again how many people approach this without understanding what actually happens under the hood. You have your dependent variable, you have two independent factors, and you're asking whether each factor matters independently and whether they interact. That sounds straightforward until your data violates assumptions and your software gives you numbers that don't make intuitive sense. The Analysis Of Variance Two Way decomposes total variability into components attributable to Factor A, Factor B, their interaction, and error. That's the textbook version. The real version is messier. You need balanced designs ideally, though software like R's aov() will handle some imbalance with Type II or III sum of squares, but you have to know which one you're using and why. Type I sum of squares depends on the order you enter factors into the model, which is one of those things that bites people who import it from SAS or SPSS without checking.
How I Actually Run It Instead of Just Clicking Buttons
Start by checking your residuals. Not after you get a weird result. Before. Plot the residuals against fitted values and run a Shapiro-Wilk test. If your residuals show clear non-normality or heteroscedasticity, you have options. You can transform the response variable, switch to a Welch-type approach, or go straight to a permutation test. I ran into this with a batch of yield measurements last month where the variance scaled with the mean. Log transformation fixed the homogeneity but made the interaction term borderline significant when it hadn't been before. That's the kind of thing you miss if you only look at the final ANOVA table. Here's the part most guides skip: unbalanced data changes everything. When your cells have very different sample sizes, the main effects and interaction become correlated in ways that make interpretation tricky. If you have missing cells entirely, you can't estimate the interaction. I had a dataset once where one treatment combination had zero replicates because of a contamination event. The software still produced output, but the interaction term was essentially a guess. I dropped that factor level, switched to a Type III approach, and reported the limitation explicitly. Transparency beats a pretty p-value every time. For the actual procedure, you fit the full model first. In R that looks like aov(response ~ FactorA * FactorB + Error(block), data = yourdata). The asterisk expands to main effects plus interaction. If you omit it and just use +, you're running a model without interaction, which means any interaction present gets absorbed into the error term. That inflates your mean square error and reduces power for detecting main effects. I've seen this happen in published papers where the authors claimed "no significant interaction" but never actually tested for one.
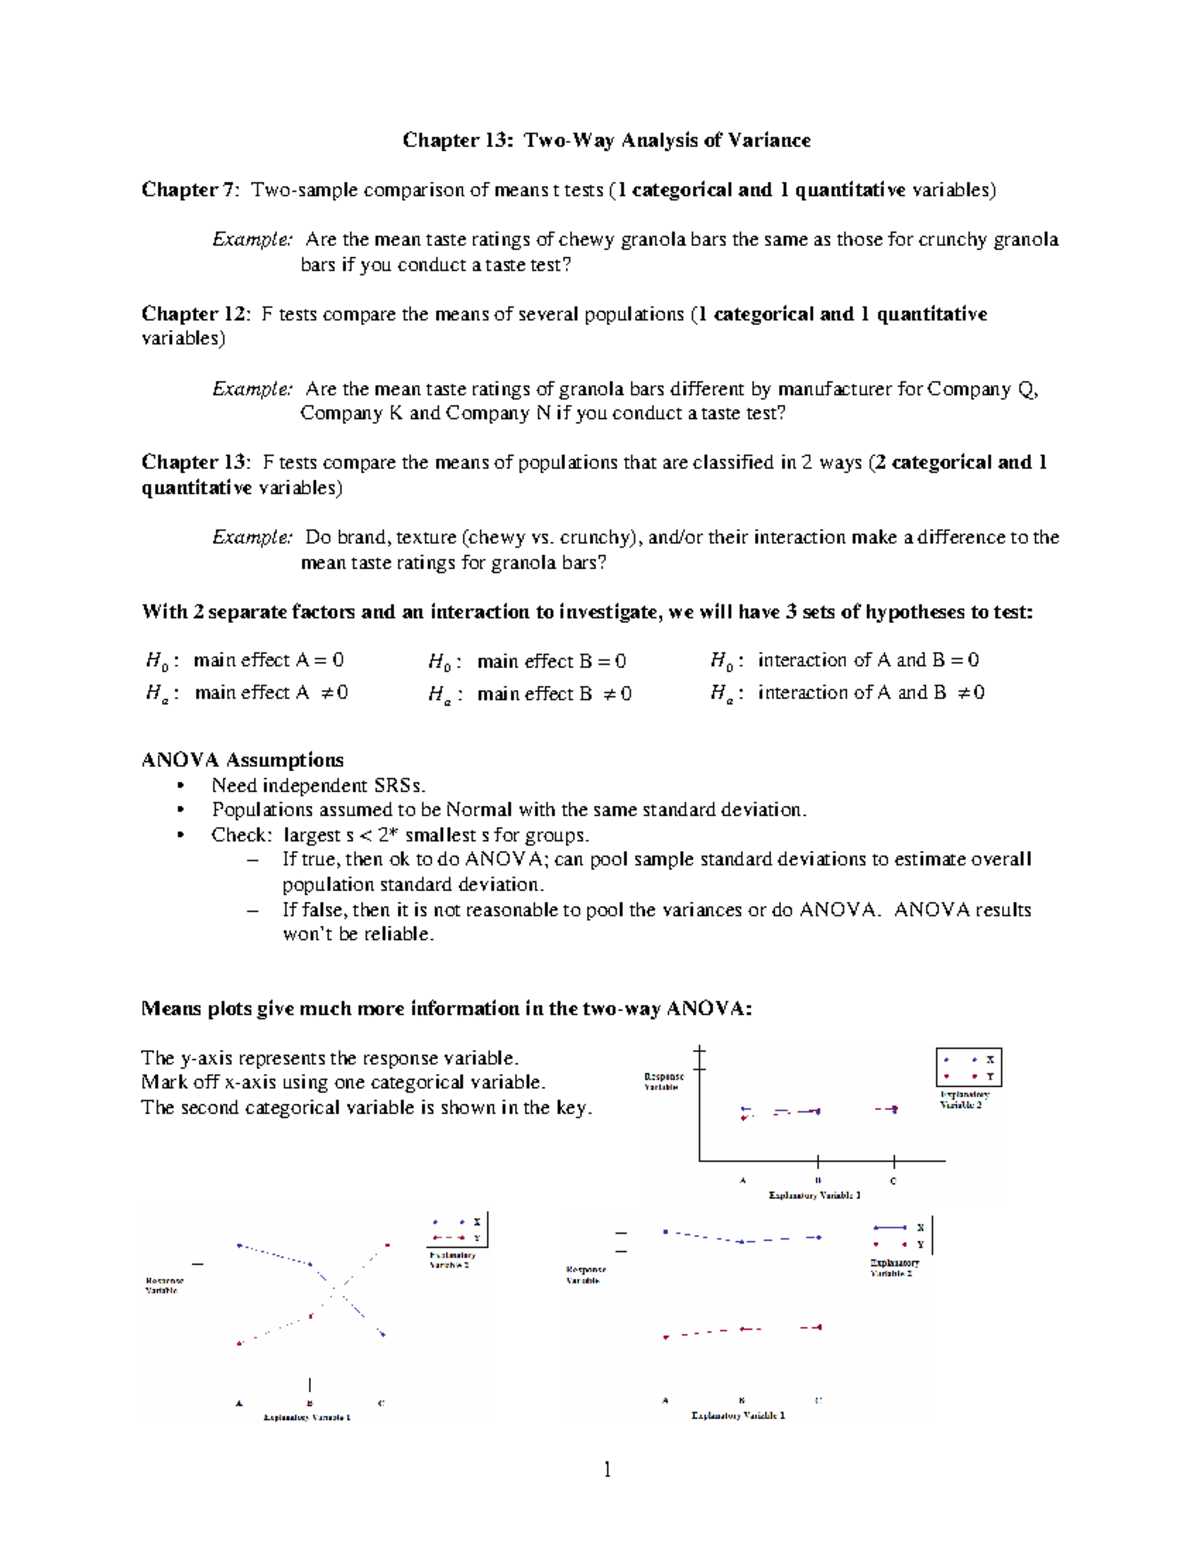
After fitting, check the ANOVA table. Look at the F-statistics and their associated p-values. If the interaction is significant, you don't interpret the main effects in isolation. That's the basic rule, but the practical implication is that you need to do post-hoc comparisons on simple main effects or use something like Tukey's HSD within each level of the other factor. I usually go with emmeans in R because it handles the contrast construction automatically and gives you adjusted p-values. Raw Bonferroni is too conservative for anything beyond two factors with two levels each. Effect size matters more than people realize. Eta-squared and partial eta-squared tell you how much variance each source explains, but they're biased upward in small samples. Omega-squared is better if you're reporting this for publication. I calculate both and report omega when I can. The numbers are usually smaller than what eta-squared suggests, and that honesty prevents overinterpretation. One more thing that catches people: your blocking structure. If you have a randomized block design, you need to include block as a random effect or at least as a factor in the model. Ignoring blocking wastes degrees of freedom and can mask real effects. I worked on an agricultural trial where the field had a fertility gradient. The unblocked analysis showed a non-significant treatment effect. After blocking, the same effect became clearly significant. The treatment variance didn't change. The error variance dropped because the block accounted for systematic variation that was previously sitting in the residual.
Get the Full Details

For software, R with the car and emmeans packages handles most situations well. SPSS and SAS work too but their default settings for unbalanced designs are annoying. Python's statsmodels has a one-way and two-way implementation but it's less polished for post-hoc work. If you're dealing with complex designs or repeated measures, mixed models in lme4 or nlme are worth the learning curve. They handle missing data better and give you proper random effect structure instead of treating blocks as fixed factors that eat up degrees of freedom. The main limitations are the assumptions. Normality of residuals, homogeneity of variances across groups, independence of observations. When those fail, the F-test isn't trustworthy. Small sample sizes make it hard to verify assumptions anyway, which is a catch-22. If you have fewer than five observations per cell, this approach is fragile at best. In those cases, I often fall back to nonparametric alternatives like the aligned rank transform or just report descriptive statistics with confidence intervals. The field has moved past relying solely on p-values from parametric tests. Another limitation people don't talk about is the multiple comparisons problem when you dig into simple effects. Every pairwise comparison adds to your family-wise error rate. Even with adjustments, power drops significantly. I've seen researchers run six or eight post-hoc tests on a two-way design and find "significant" results that wouldn't survive a proper correction. It's easy to do accidentally because the default output from most software doesn't flag which comparisons were part of a larger family.
When Two-Way ANOVA Is the Wrong Tool
If your dependent variable is binary or count-based, standard two-way ANOVA is inappropriate. Use a generalized linear model instead. Logistic regression for binary outcomes, Poisson or negative binomial for counts. The analysis structure is similar but the distributional assumptions are different. I made this mistake early in my career with a survival count dataset and got absurd F-statistics because the variance wasn't constant across the range of means. Switching to a GLM with a quasi-Poisson link fixed it immediately. If you have repeated measures on one or both factors, the standard two-way ANOVA treats observations as independent when they're not. That inflates Type I error rates. A repeated measures two-way ANOVA or a mixed model with the appropriate covariance structure is necessary. The assumption of sphericity becomes relevant here, and violations require Greenhouse-Geisser or Huynh-Feldt corrections. Most software applies these automatically, but you should verify they're being used and check the epsilon values. Practical recommendation: fit the model, diagnose the assumptions thoroughly, check effect sizes not just p-values, handle unbalanced data with the right sum of squares type, and don't chase significance by digging into post-hoc tests without proper adjustment. The method works well when the data meets its assumptions and the design is reasonable. It fails gracefully when they don't, as long as you notice and adjust accordingly.