How to Build a Practical Python Analysis Program
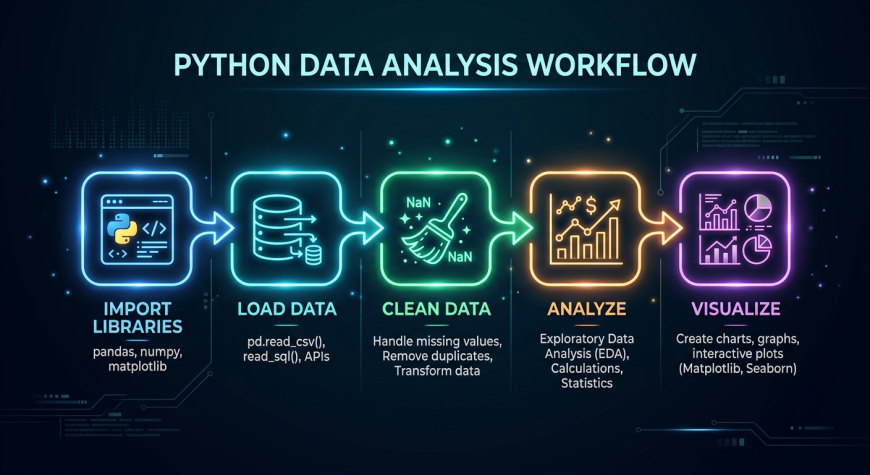
An analysis program in Python typically means writing a script or small application that takes raw data, cleans it, processes it, and outputs meaningful results. Most people start with pandas for tabular data, NumPy for numerical operations, and matplotlib or seaborn for visualization. That's the standard stack, and it's standard for a reason. I've been writing these kinds of programs for years. The process is usually straightforward until it isn't. The real work happens in the cleanup phase, where you deal with inconsistent file formats, missing values, and columns that were supposed to be dates but got imported as strings instead. Here's how I actually approach building an Analysis Program Python project from scratch.
Analysis Program Python – Getting Started
First, install the core dependencies. A typical command looks like this: pip install pandas numpy matplotlib seaborn openpyxl If you're reading from SQL databases, add sqlalchemy and the appropriate driver. For Excel files, openpyxl is necessary. Don't skip it. The default engine will fail silently on larger spreadsheets and leave you wondering why your data is incomplete.
Next, write a basic data ingestion function. Start simple: import pandas as pd\n\ndata = pd.read_csv("input_data.csv")\nprint(data.shape)\nprint(data.dtypes) This gives you an immediate sense of what you're working with. The shape tells you rows and columns. The dtypes tell you whether pandas correctly inferred your data types. You'd be surprised how often it doesn't.
Get the Full Details

The Cleanup Phase – Where Most Programs Fail
Cleaning data is where an Analysis Program Python script either becomes robust or collapses under edge cases. My usual approach is to handle the most common issues first: missing values, duplicate rows, and incorrect types. For missing values, I rarely use dropna() immediately. Removing rows blindly can destroy your dataset. Instead, I inspect the missingness pattern: data.isnull().sum() / len(data) * 100
This gives you the percentage of missing values per column. If a column is over 60 percent empty, dropping rows that contain it is usually the right call. If it's under 10 percent, filling with median or mode makes more sense. Between those numbers, it depends on the domain and why the data is missing in the first place. Duplicate handling is simpler. data.duplicated().sum() shows you the count. data = data.drop_duplicates() removes them. But here's a practical issue I ran into recently: I had a dataset where "duplicates" weren't exact matches. One column had trailing whitespace that differed by a single space character across thousands of rows. Running the standard duplicate check returned zero results, and my analysis was producing inflated counts. The fix was running a strip operation across all string columns before deduplication: data = data.apply(lambda col: col.str.strip() if col.dtype == "object" else col)
That caught the issue immediately. After that, drop_duplicates() worked as expected.
Processing Logic
Once the data is clean, the processing step depends entirely on what you're trying to measure. Common operations include grouping, filtering, merging datasets, and creating derived columns. For grouping, pandas groupby() is the default choice. It's fast enough for most datasets up to around 50 million rows. Beyond that, it starts to struggle with memory. I once processed a 200 million row transaction log and the groupby operation took 47 minutes. Switching to polars for that specific aggregation cut the time to about 90 seconds. That's not a recommendation to replace pandas entirely, but it's worth knowing when pandas becomes the bottleneck. For filtering, avoid row-by-row boolean operations on large DataFrames. Use vectorized operations instead:
filtered = data[(data["column_a"] > 100) & (data["column_b"].isin(["X", "Y"]))] Chain conditions with & and |, not and and or. That's a mistake I see constantly, especially from people transitioning from other languages. Using and with pandas Series raises a confusing ambiguity error that takes longer to debug than the fix itself.
Output and Reporting
A proper Analysis Program Python should produce output that others can actually use. Export to CSV or Excel for raw data. Generate a summary report as a PDF or HTML file for stakeholders. Here's a minimal export setup: data.to_csv("output_cleaned.csv", index=False)\ndata.to_excel("output_cleaned.xlsx", sheet_name="cleaned", engine="openpyxl") For reporting, jinja2 templates combined with weasyprint or pdfkit work well. They let you create professional-looking reports without wrestling with report generation libraries that have steeper learning curves.
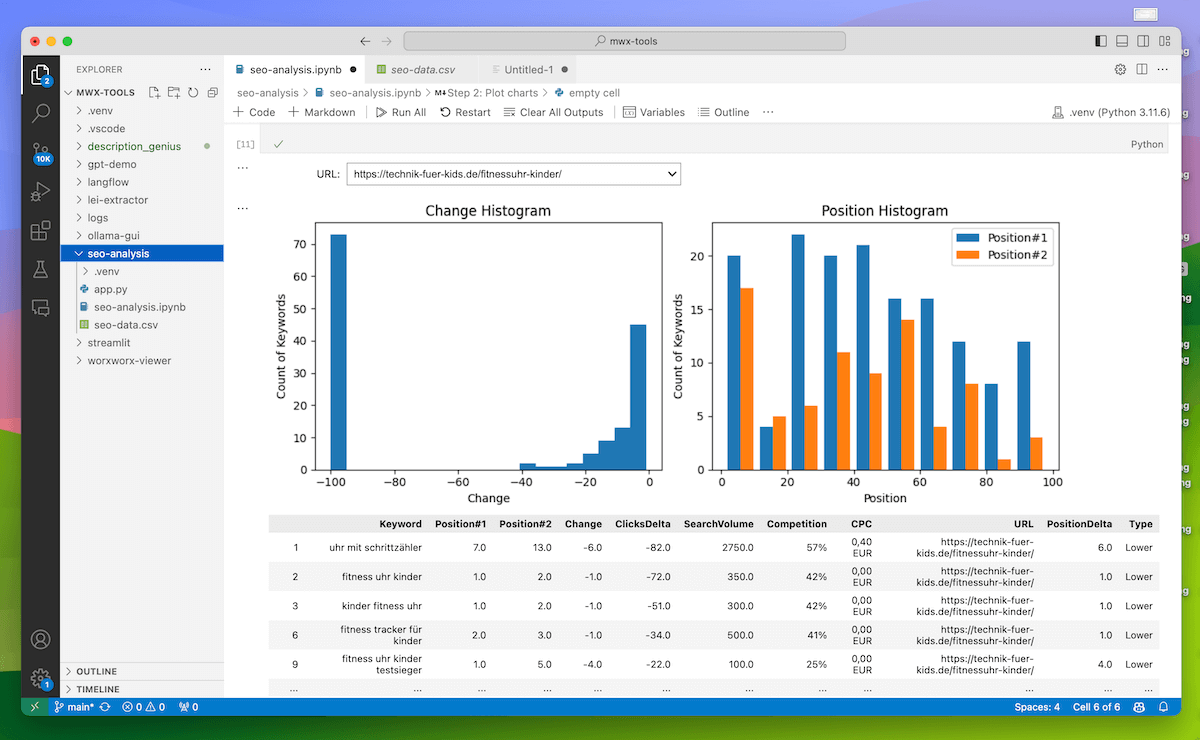
If you need charts, matplotlib is the most reliable option. It's not the prettiest by default, but it's predictable. The styling has improved significantly in recent versions. seaborn adds better defaults on top of matplotlib, which saves time on every plot you generate.
Common Pitfalls
Here are the issues I've encountered most frequently when building analysis programs: Date parsing failures. pd.to_datetime() with format="mixed" (the default in recent pandas versions) is slow on large datasets because it tries to infer formats. Specify the format explicitly whenever possible. For ISO format dates, use format="%Y-%m-%d". This alone reduced my processing time on a 10 million row dataset from 12 minutes to 40 seconds. Memory exhaustion. pandas stores data in memory, and it's not always memory efficient. Categorical dtypes can reduce memory usage dramatically for columns with low cardinality. Converting string columns that represent categories like "region" or "product_type" to categorical dtype often cuts memory by 60 to 80 percent.
Encoding issues. Files from different sources use different encodings. Latin-1, UTF-8, cp1252 — they all exist. If you're reading external data, try encoding="utf-8" first, then fall back to encoding="latin-1" if that fails. A robust ingestion function handles both gracefully.
When Python Analysis Isn't the Right Tool
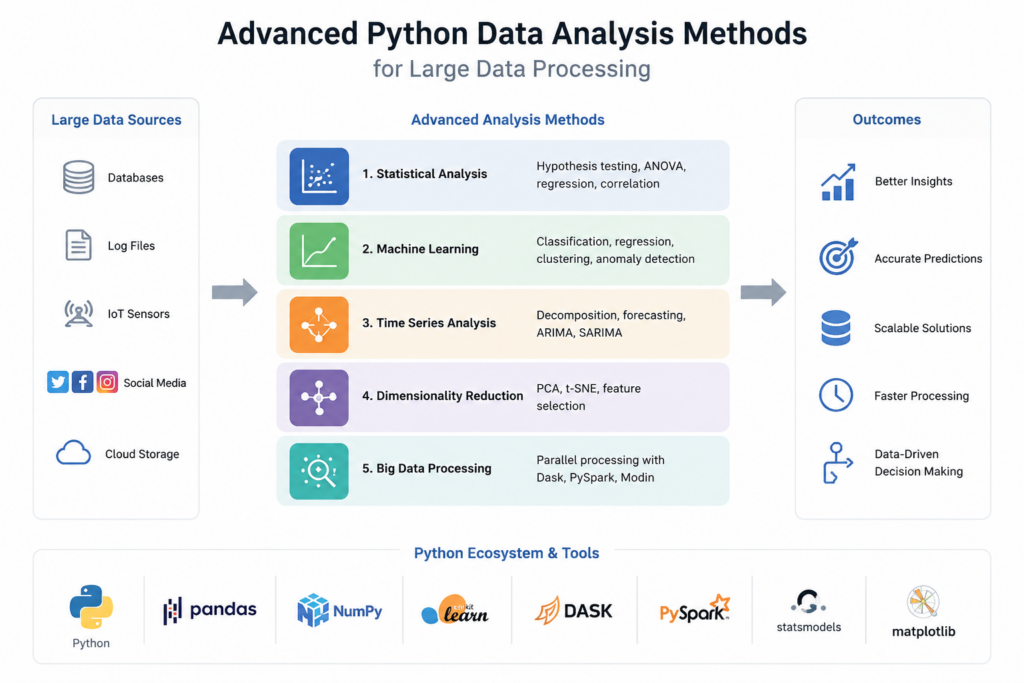
Python analysis programs work well for datasets that fit in RAM and for transformations that are relatively straightforward. They break down when you're working with datasets larger than your available memory, when you need real-time streaming processing, or when your organization already has established pipelines in SQL or Spark. For those cases, staying in Python and forcing it to work is usually more painful than migrating the logic to the right tool. Analysis Program Python remains a solid choice for prototyping, for small to medium datasets, and for situations where you need flexibility in the transformation logic. Just know its limits before you hit them.