Fitting Linear Models Without Losing Your Mind
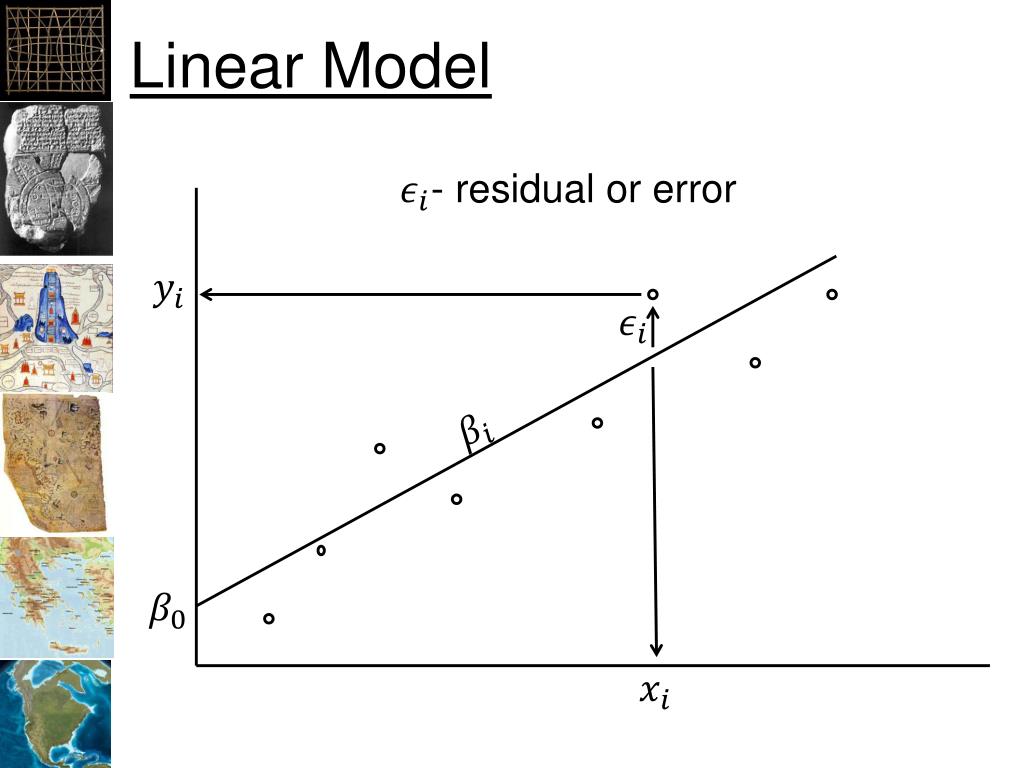
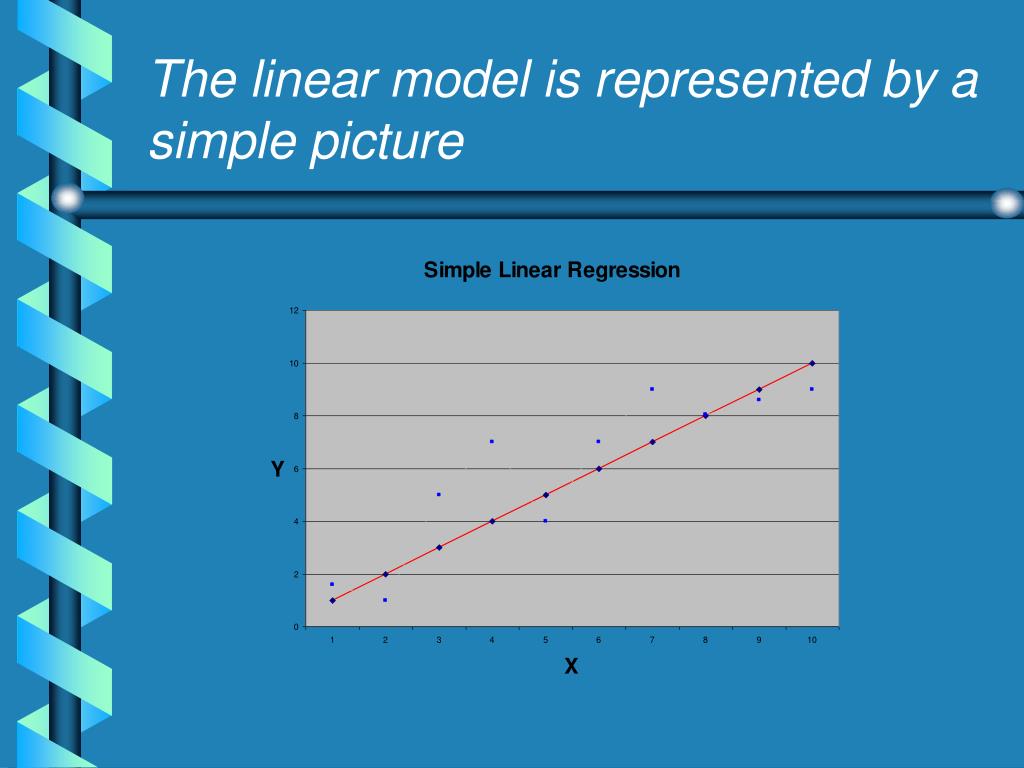
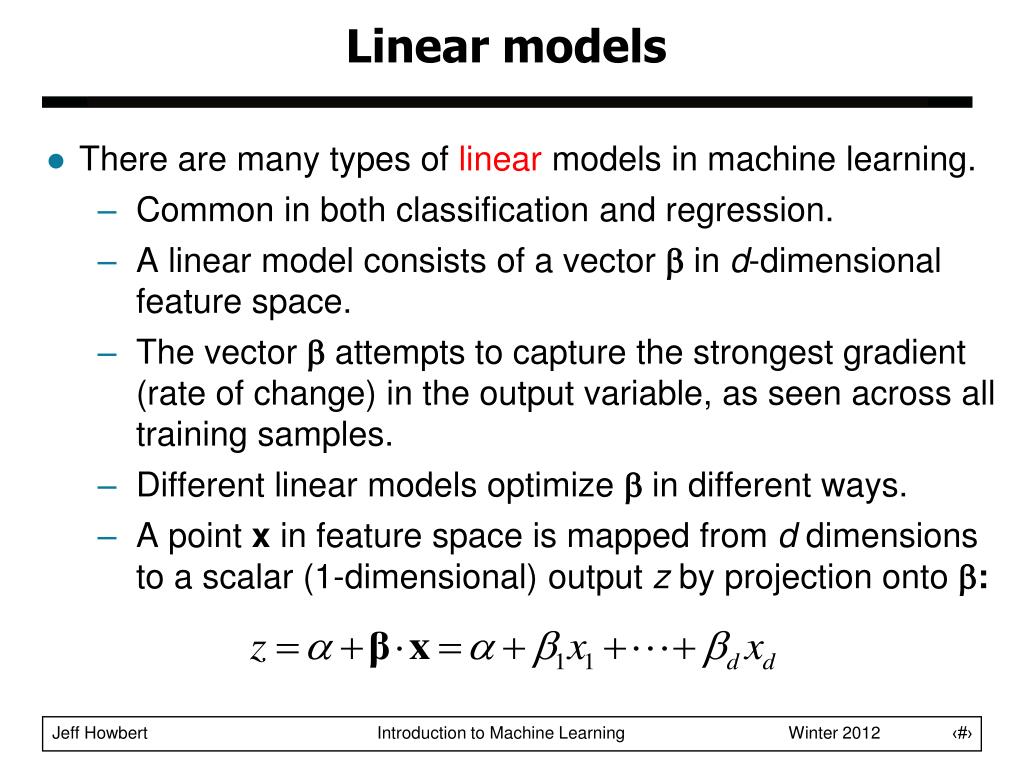
Most people learn the linear model in a statistics class and then never think about it again until something breaks in production. That is a problem because the linear model is still one of the most useful tools available, and the things that go wrong are rarely the things textbooks warn you about. I have spent more years than I care to count debugging regression outputs that looked perfect on paper and completely wrong in practice. The core idea is simple enough that it barely deserves explanation. You have a dependent variable and one or more independent variables. You assume the relationship between them can be approximated by a straight line, or in higher dimensions, a hyperplane. You find the coefficients that minimize the sum of squared residuals. That is ordinary least squares, the default method, and it works fine when the assumptions hold. The assumptions are the part nobody remembers. The errors need to be independent, identically distributed, normally distributed with a mean of zero, and homoscedastic. Your predictors need to be fixed, not random, and they cannot be perfectly collinear with each other. If any of those are violated, the model is still computable, but your standard errors are lying to you and your confidence intervals are narrower than they should be. That means you will be confidently wrong.
I encountered this exact issue last year on a project involving customer churn prediction. The dataset had roughly 40,000 rows and about thirty features, mostly categorical encodings. The model converged without any warnings from the fitting routine. The R-squared looked reasonable at around 0.31, which for churn data is not terrible. But when I plotted the residual versus fitted values, there was a clear funnel shape. The variance of the errors increased systematically with the predicted values. Heteroscedasticity. A quick White test confirmed it with a p-value well below 0.001. The OLS standard errors were biased downward, which meant every p-value for the coefficients was artificially small. I was about to declare three features statistically significant when they were not. The workaround was straightforward: switch to heteroscedasticity-consistent standard errors using the HC3 variant. The coefficient estimates themselves did not change at all. Only the inference changed, and it changed significantly. Two of the three features lost their significance entirely once the correct standard errors were applied. This took about ten minutes to diagnose and fix, but without the diagnostic plot, it would have been weeks before anyone noticed the problem. Another common failure mode is omitted variable bias, and it is even more insidious because there is no diagnostic plot that flags it. If you leave out a variable that is correlated with both your dependent variable and one of your included predictors, the coefficient on that predictor will absorb the effect of the missing variable. The model looks fine. The diagnostics look fine. The coefficient is just wrong, and you will not know which way it is wrong without domain knowledge about what variables should be in the model.
multicollinearity is another frequent problem that does not violate any assumptions but makes the model unstable. When two predictors are highly correlated, the coefficient estimates become very sensitive to small changes in the data. The standard errors blow up. You might see a coefficient flip sign depending on whether you include a particular interaction term or control variable. VIF scores above 10 are the usual red flag, but even scores in the five to ten range can be problematic if you care about individual coefficient interpretation. In those cases, ridge regression or principal component regression can stabilize the estimates, though you lose the clean interpretability that makes linear models attractive in the first place. The linear model also fails hard when the relationship is genuinely nonlinear. Polynomial terms and splines can help, but they add complexity and can overfit quickly if you are not careful. A simple scatterplot matrix between your dependent and independent variables before fitting anything is worth far more than any automated specification test. I still do it manually for every new dataset, even when the fitting routine could handle everything automatically. For implementation, R remains the most straightforward option for analysts who need to move quickly. The lm() function fits ordinary least squares in a single call. For robust standard errors, the clubSandwich package handles clustered and heteroscedasticity-consistent estimators cleanly. Python users typically rely on statsmodels, which gives you more control over the fitting process than sklearn's linear model implementations. The OLS class in statsmodels provides detailed summary tables with diagnostic options, and the HC1, HC2, and HC3 covariance options map directly to the standard robust estimators.
Get the Full Details
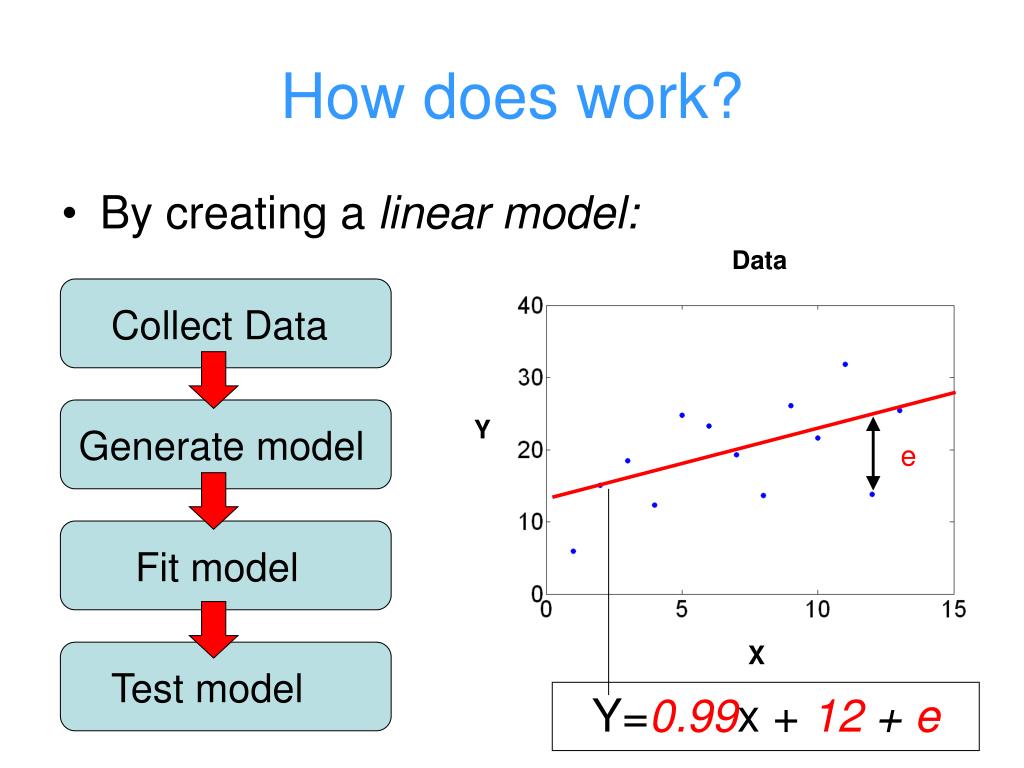
There is no general-purpose download link for a linear model because it is a statistical method, not software. The packages I mentioned are available through standard package managers. R users run install.packages("lmtest") and install.packages("sandwich"). Python users run pip install statsmodels. The actual code for fitting is usually fewer than five lines once the data is loaded and preprocessed. What most beginners miss is that linear models are not just a starting point for more complex methods. They are often the best method for the job when the question is causal rather than predictive. If you need to estimate the effect of a treatment or policy intervention, a carefully specified linear model with proper diagnostic checking and robust inference will usually give you more reliable answers than a random forest or gradient boosting machine. The black-box models might predict better on out-of-sample data, but they do not give you interpretable coefficients or clear causal estimates, and that tradeoff matters when the decision is not just about prediction accuracy. The linear model is not a solution to every problem. It is brittle when assumptions are violated, it does not handle interactions or nonlinearities well without manual specification, and it can be misleading when high-dimensional correlated features are present. But it remains the default tool in most applied work for good reason. It is transparent, fast to fit, and easy to diagnose. The cost is that you have to actually check your diagnostics instead of trusting the output table.