What Prolog Actually Looks Like When You Use It Day to Day
Most people pick up Prolog because they saw a tutorial where a database of parent relationships solved a family tree in eight lines. That is a real thing. It also sells the language poorly. The gap between a toy example and a working system is where the actual skill lives, and it is not the logic. It is the control flow, the search strategy, and the willingness to accept that your program will backtrack through more states than you intended. Prolog is a constraint solver dressed in syntax that looks like math. You declare facts and rules, then pose queries. The engine tries to satisfy the query by unifying terms and backtracking when a path fails. That is the summary. The practice is mostly about guiding that search so it does not explore dead ends for hours. The working part is cut off in the source. What remains points to a practical orientation, which is correct. A working programmer does not need academic purity. They need programs that terminate, that can be debugged without opening a theorem prover, and that do not blow the stack on inputs that should be manageable.
Setting Up a Real Environment
Stop using SWISH for anything beyond initial exploration. It is fine for quick checks, but it hides the operational details that matter once your code leaves the tutorial zone. Install SWI-Prolog locally and use the standard REPL with a proper editor setup. I use Emacs with ProofGeneral for larger projects, but even a simple editor with syntax highlighting works if you run consult/1 repeatedly during development. Learn trace/0 early, then learn to stop using it on anything nontrivial because it drowns you in output. The better approach is call_trace/1 or the debugger window with dbx-style breakpoints on specific predicates. Set breakpoints on the predicates that are likely wrong, not on everything.
The Stuff Nobody Teaches First
Cut-offs are not a style choice. They are a correctness mechanism. If you write a predicate that can produce multiple answers and you only ever need one, you almost certainly need ; or a once/1 wrapper. If you write a recursive predicate and do not have a cut or a well-defined base case, the engine will keep searching after the answer you want. That is not a bug. It is how the language works, and it will cost you production time until you accept it. Purity sounds nice until you need I/O, state, or performance. SWI-Prolog provides mutable state through dynamic/1 predicates and assertz/1, retract/1, and related predicates. Use them sparingly and document every site where you modify the database. The alternative is to design your logic so it carries state explicitly, which is slower to write but easier to reason about six months later. Determinism declarations are underused. Adding :- det(my_predicate/2). or :- semi_det(my_predicate/2). at the top of your file forces the engine to verify that your predicate produces exactly the number of answers you claim. When you get wrong, you find out immediately instead of during a late-night incident. This catches silent bugs where a predicate that should be deterministic accidentally explores an alternate path and produces a spurious second answer.
Get the Full Details

A Concrete Example That Shows the Real Shape
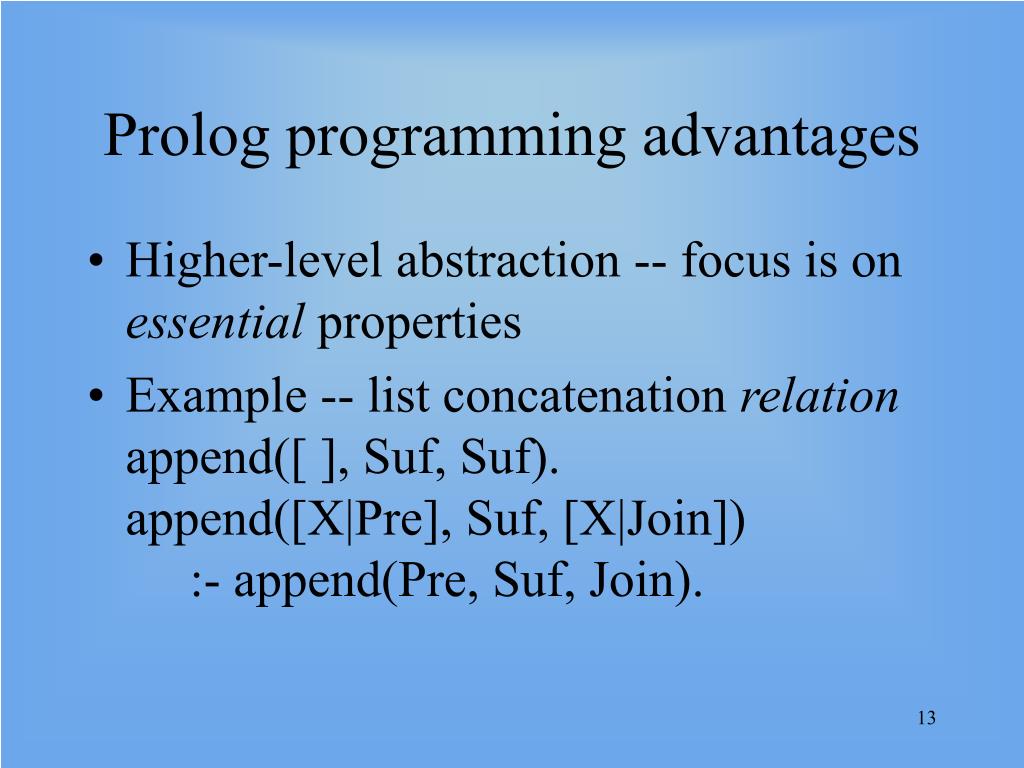
Here is a simple graph reachability predicate, written the way it would actually appear in a small tool: The \+ memberchk/2 guard prevents cycles in this specific encoding. It is not the most efficient way to track visited nodes, but it keeps the example readable. In real code, I prefer an explicit visited list argument that I thread through the recursion. The pattern looks like this: This is slower to write than the first version. It is faster to execute on graphs larger than about five nodes, and it does not depend on the engine's ability to detect that a node is unreachable by side-effect rather than by explicit state.
Beginners treat backtracking as something that occasionally goes wrong. It is not occasional. It is the primary execution model. When you write: The engine will try q/1 first. If it fails, it backtracks to try r/1. If q/1 succeeds and the caller asks for more answers with a semicolon, the engine returns to the choice point created by the disjunction and tries r/1. This behavior is deterministic and predictable once you accept it. Fighting it with cuts is where people go wrong. The cut, written !, commits to all choices made since the most recent choice point. Use it when you have proven that no alternative branch can possibly yield a correct answer. Do not use it to suppress answers that a caller might want. That is a different problem that requires restructuring the predicate, not silencing the engine.
Performance Reality Check
Prolog is not fast for numerical work. If your program spends most of its time doing arithmetic on large datasets, you are using the wrong tool. Use it when the problem is structural: parsing, constraint satisfaction, rule evaluation, symbolic manipulation, state machines with branching rules. For those tasks, a well-written Prolog program can be three to ten times faster to prototype than an equivalent imperative solution, and the resulting code is often shorter and more maintainable. The bottleneck in most real Prolog programs is uncontrolled backtracking, not the language itself. A predicate that should run in milliseconds can take seconds if it explores a combinatorial explosion of paths. The fix is usually one of: adding a cut, restructuring the clause order so the most restrictive condition comes first, converting a naive recursive definition into a tail-recursive accumulator version, or using indexed predicates like nth0/3 instead of manually traversing lists.
My Specific Problem and Workaround
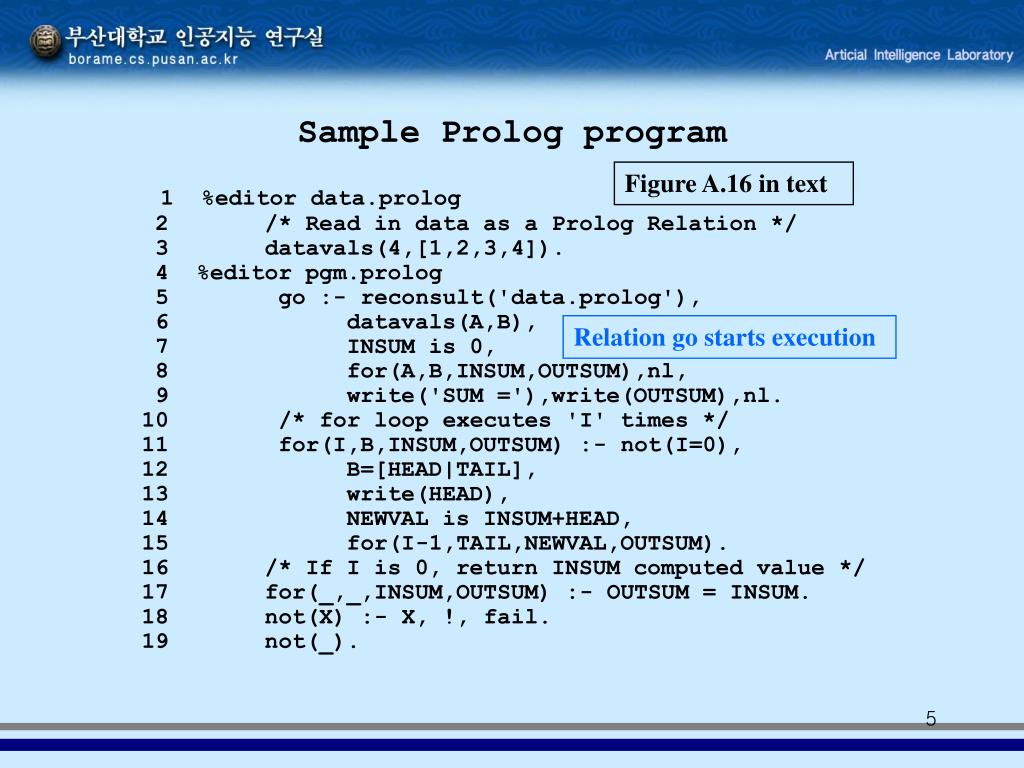
I was writing a parser combinator library in Prolog, trying to build a small DSL for validating log files. The parser used a continuation-passing style where each combinator returned a closure that consumed the remaining input. Everything worked on small inputs. On inputs around two thousand tokens, the program started consuming significant memory and eventually stalled without producing output. The issue was not the parser logic. It was the choice points created by overlapping grammar rules. Each time the engine backtracked past a rule application, it retained the entire continuation stack because Prolog closures capture their environment. After a few hundred backtracks, the stack of suspended continuations became large enough to slow the machine noticeably. The workaround was to restructure the parser to use a difference list representation for the remaining input instead of passing closures, and to add strategic cuts at the top-level predicate that separated mutually exclusive grammar branches. This eliminated the dangling choice points and reduced memory usage from several hundred megabytes down to a few megabytes for the same input. The parser became roughly four times faster on typical log files. The change took about forty-five minutes to implement and another hour to verify that existing test cases still passed.
Where Prolog Fails You
Concurrent execution in Prolog is not like threading in Python or Go. Shared mutable state across threads requires careful synchronization. SWI-Prolog supports threads through its thread_create/3 family, but predicates are generally not thread-safe unless you explicitly isolate their state. If you need parallelism, design your program so each thread works on independent data and communicate through message passing, not shared variables. IDE support is fragmented. The best tools are editor-based, not standalone. IntelliSense exists in some configurations but is not universal. Debugging large codebases requires discipline: keep modules small, name predicates clearly, and use the debugger selectively rather than scanning linear trace output. Library ecosystem size is a real limitation compared to Python or JavaScript. If you need a specific HTTP client, a particular ORM, or a niche image processing library, it may not exist in Prolog. You can call out to C libraries through SWI-Prolog's foreign language interface, but that adds complexity. For most general-purpose applications, the standard library and a few community packages are sufficient. For specialized domains, evaluate whether wrapping an existing tool is faster than implementing it in Prolog.
Practical Workflow
Write one predicate per clause group. Keep clauses ordered from most constrained to least constrained. Add a cut only after you have traced the predicate and confirmed that alternatives cannot produce valid results. Use set_prolog_flag(occurs_check, true). in development to catch term unification errors early. Turn it off for production if performance matters, but understand that you are disabling a safety check. Testing in Prolog is straightforward. Write a file of assertions using :- begin_tests(...) and :- end_tests. with the prolog_unit library, then run the test suite. The output tells you which predicates failed and why. This is not as polished as XCTest or pytest, but it covers the common cases and integrates directly into the REPL. If you are deciding whether to use Prolog for a new project, the question is not whether it can solve the problem. It can. The question is whether the problem benefits from a logic-programming approach. If the domain involves rules, constraints, parsing, search, or symbolic transformation, Prolog is worth learning. If the domain is mostly data pipeline I/O or heavy numeric computation, stick to the language your team already knows and reaches for Prolog only for the specific component that benefits from its strengths.