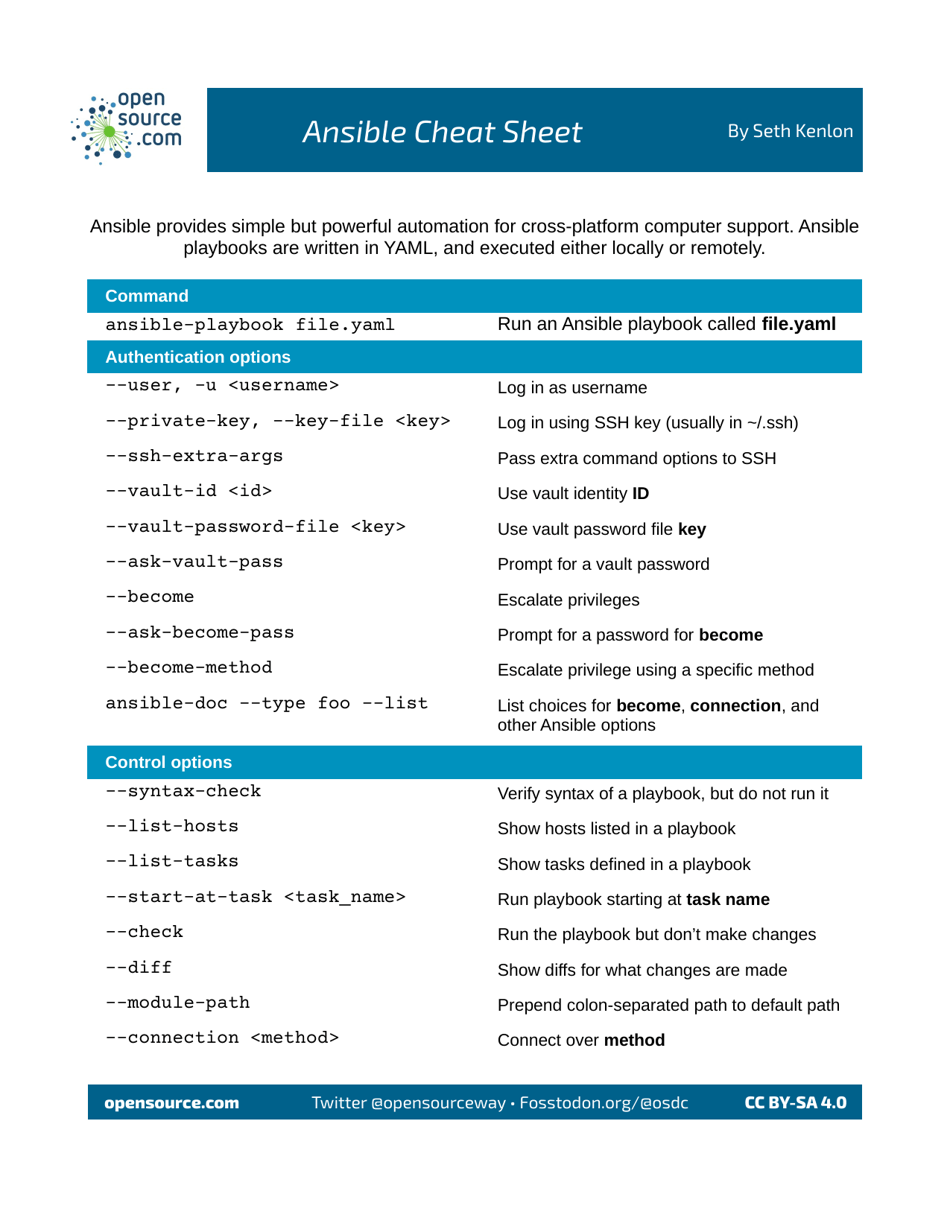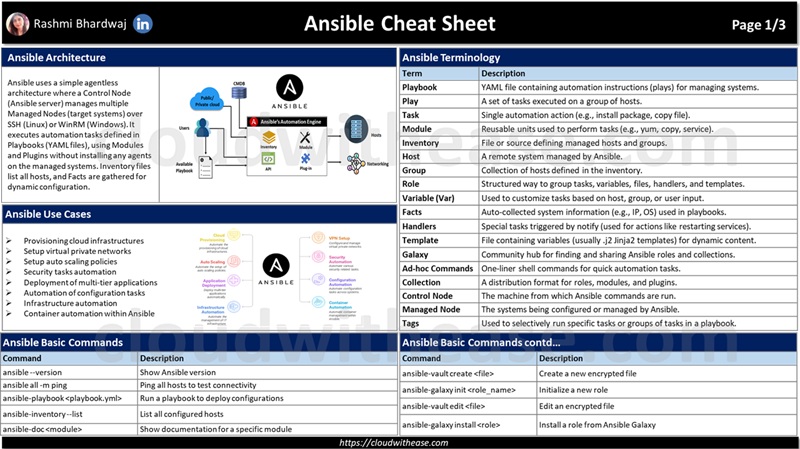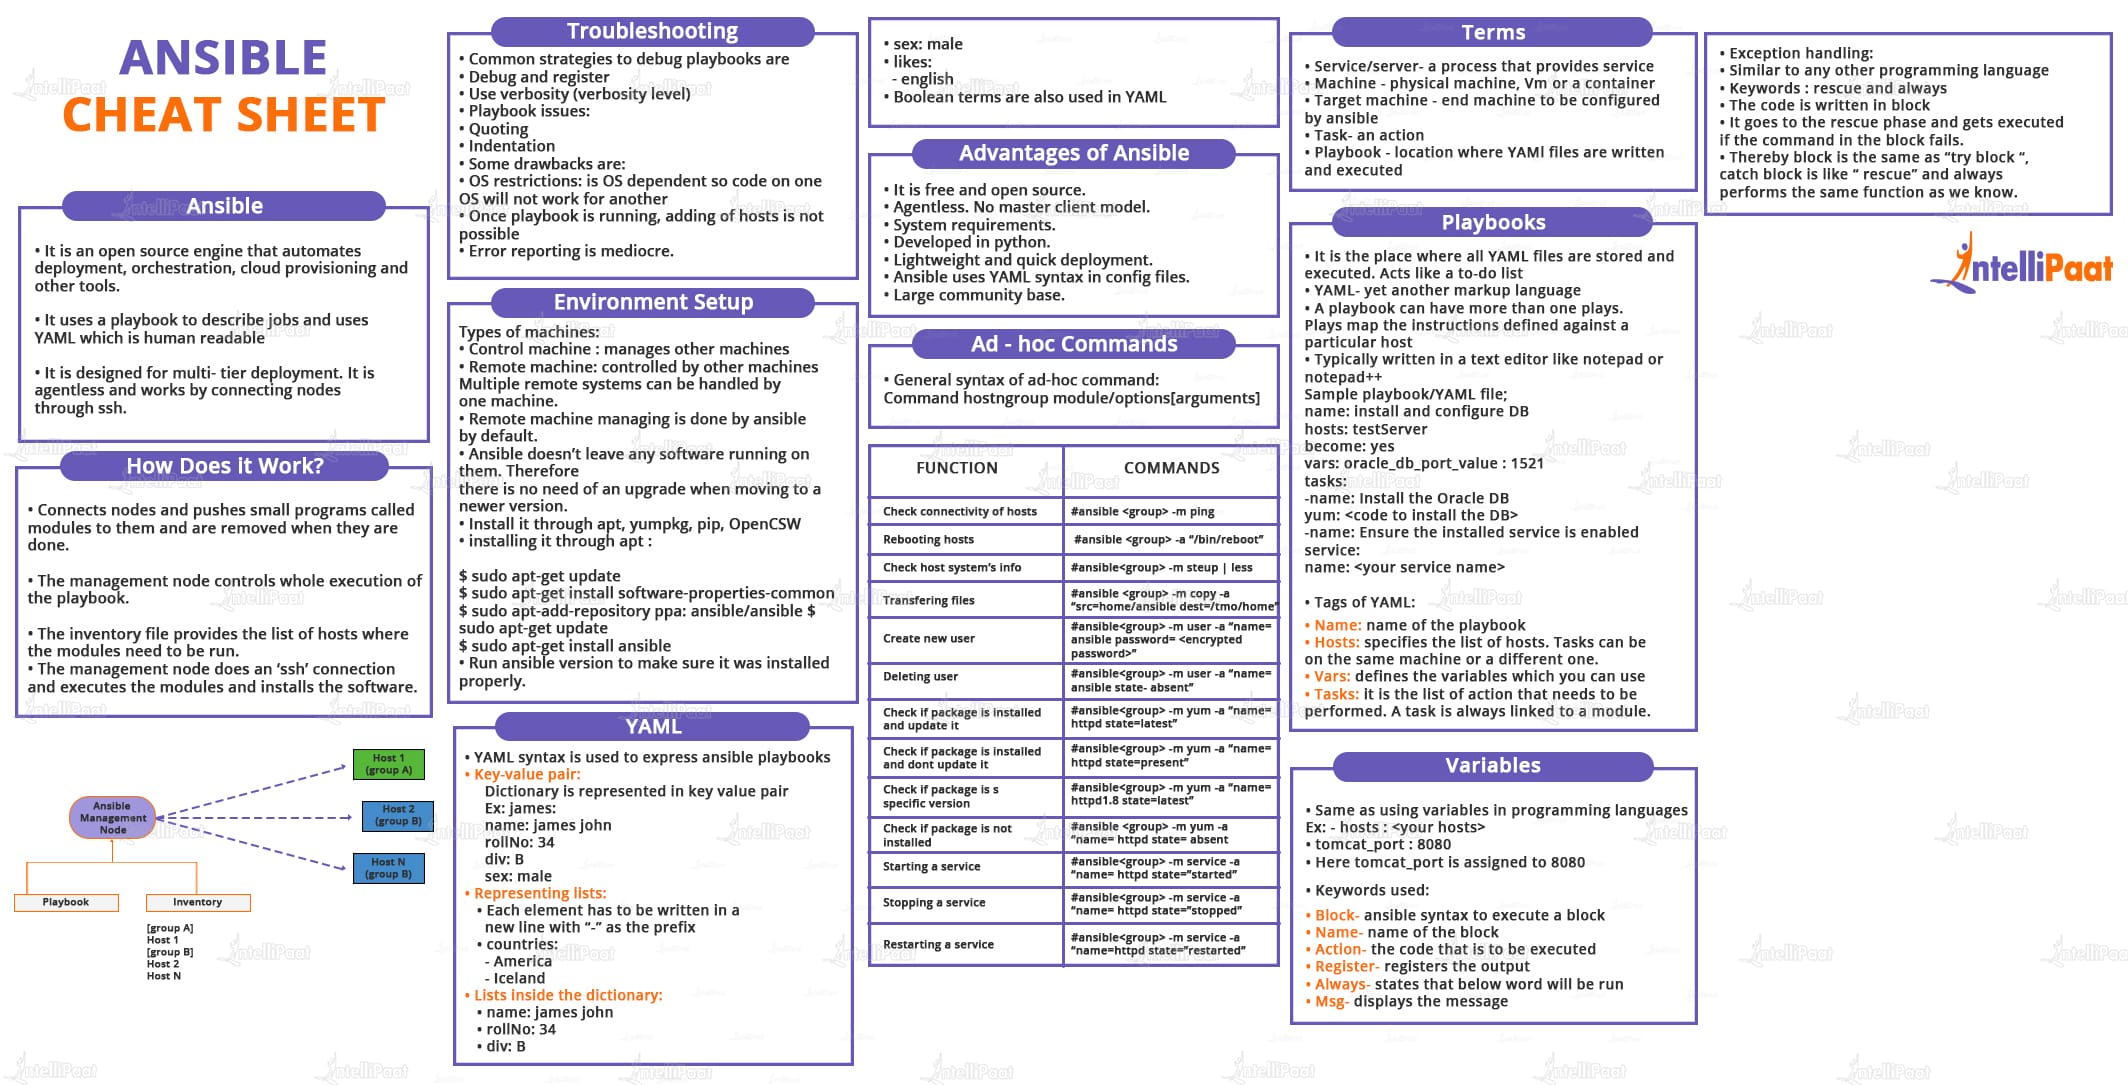
Ansible Cheat Sheet
I've been writing playbooks since before roles became the standard way to organize things, and the one thing that saves me every time is keeping a reference close by. Most people don't realize Ansible has a built-in cheat sheet you can pull up without leaving your terminal. Run ansible-doc --cheat and you get a printable list of modules, quick examples, and the most commonly used flags. It's not perfect, but it covers about eighty percent of what you hit in a typical week. When I first started using Ansible, I relied on long-form documentation for everything. That worked fine until I needed to check the exact syntax for the winrm connection strategy or figure out how become_method interacted with sudoers on a Debian box at 2 AM. The built-in cheat sheet pulled up in seconds, and the relevant section had the flag I needed without scrolling through ten pages of theory.
How to generate and print the cheat sheet
The simplest way to get a local copy is running ansible-doc --cheat > ansible-cheat-sheet.txt. That dumps everything into a plain text file you can grep, search, or print. If you want PDF, pipe it through man or use ansi2html to convert the terminal output to something readable in a browser. I keep mine in my dotfiles repo so it's version-controlled and stays current whenever I update Ansible. One thing the official cheat sheet doesn't show well is how ansible-galaxy collection paths override module resolution. If you install a collection from Galaxy, ansible-doc will pull examples from that collection instead of the core ones. I ran into this when migrating from a CentOS 7 playbook to a mixed RHEL 9 environment. The firewalld module examples in the cheat sheet showed the old state parameter format, but RHEL 9's firewalld version required the new permanent flag. I spent twenty minutes debugging before I realized the cheat sheet was showing me deprecated syntax from an older collection version.
Core playbook structure nobody explains right
Most tutorials start with a simple ping module example and call it a day. The real structure that matters is how vars_prompt, roles, and collections interact during execution order. Ansible resolves modules in this sequence: inventory variables, playbook variables, role variables, then defaults. If two of them set the same variable, the one declared last wins, and that usually trips people up when a role unexpectedly overrides a playbook-level setting. I found this out the hard way when a networking role kept changing my custom ntp_servers variable. The role's defaults were lower precedence than my playbook vars, but the role's task explicitly used include_vars with public: true, which bumped it above everything. The fix was renaming the variable in the role to something with a role-specific prefix, like myrole_ntp_servers, and mapping it internally.
Get the Full Details

Essential modules that aren't obvious
Beyond the obvious ones like ping, copy, and shell, there are modules people discover too late. ansible.builtin.debug with var and verbosity is far more useful than most realize. Setting verbosity: 3 means your debug output only shows when you run with -vvv, which keeps your normal playbook runs clean while giving you deep visibility during troubleshooting. ansible.builtin.assert is another one worth knowing. It validates conditions mid-playbook and fails fast with a custom message. I use it to check that a variable isn't empty before running a deployment task. It's cleaner than wrapping everything in when conditions and avoids running ten tasks that will fail anyway. The community.general.ini_file module handles INI-style configs better than the built-in template approach for simple cases. Writing a full Jinja2 template for a-line config file is overkill when ini_file lets you set individual keys directly. I switched an entire cluster configuration task from templating to ini_file and cut the runtime roughly in half because it only reads and writes changed sections instead of rendering and replacing whole files.
Connection and inventory gotchas
The ansible_ssh_common_args variable in your inventory lets you inject extra SSH options globally. This is how I handle jump hosts without cluttering every task. Setting it in group_vars/all.yml with -o ProxyJump=jumpbox.internal means the connection works everywhere without repeating the proxy configuration. ansible_become_method defaults to sudo on most systems, but on some minimal containers it falls back to su and fails silently if no password is set. I learned this when a playbook succeeded on every host in a K8s node pool except one, and the failure was buried in a become error that looked like a connectivity issue at first glance. Adding ansible_become: false to that host's vars exposed the real problem immediately.
Handling idempotency failures
Idempotency in Ansible is supposed to be automatic, but it breaks when modules report changed: true on every run even though nothing actually changed. This happens most often with command and shell modules, which always report changed unless you explicitly check the output. The workaround is wrapping those tasks in args with creates or removes flags, or using the changed_when keyword to override the default behavior. I encountered this with a deployment script that checked a service status and restarted it if the PID file was missing. The shell module reported changed on every run because the command itself executed successfully each time. Adding changed_when: result.rc == 0 and 'restarted' in result.stdout fixed it cleanly. The task only reported changed when it actually performed a restart, which made the playbook output meaningful again instead of noisy.
Roles versus plain playbooks
Roles are supposed to make reuse easier, but the directory structure is rigid and unforgiving if you deviate from it. A standard role needs tasks/, handlers/, vars/, defaults/, files/, templates/, and meta/ in specific locations. If you put a task file in the wrong subdirectory, Ansible won't find it and the playbook fails with a confusing path error. The counter-intuitive part is that for small projects, plain playbooks are faster to write and debug. Roles shine when you have ten or more playbooks sharing the same logic, but until then they add overhead without real benefit. I started a project that needed a role for logging configuration, spent an afternoon setting up the directory structure, and realized the entire role was twelve lines long. A single inline task block would have taken five minutes.
Performance tuning for large inventories
Fanout is the biggest performance bottleneck in Ansible. Running a playbook against five hundred hosts sequentially can take hours. Setting forks in your ansible.cfg controls parallelism, but the default of five is almost always too low. I run forks = 50 on my CI servers and see playbooks that used to take forty minutes finish in under eight. Beyond fifty forks, you start hitting resource limits on both the control node and the target machines, so the gains plateau. ansible-pull is another approach worth knowing about. Instead of pushing playbooks from a central server, each host pulls its own playbook from git on a schedule. This flips the architecture and removes the single point of failure, but it requires every host to have network access to your git server and makes tracking which host ran which version much harder. I use it for edge deployments where push connectivity is unreliable. If you're looking for a printable reference while you work, the built-in Ansible Cheat Sheet covers most of this already, but the edge cases and war stories don't show up in any documentation. The best resource is just running commands, breaking things, and checking the logs.