What Application Dependency Mapping Template Actually Looks Like in Practice
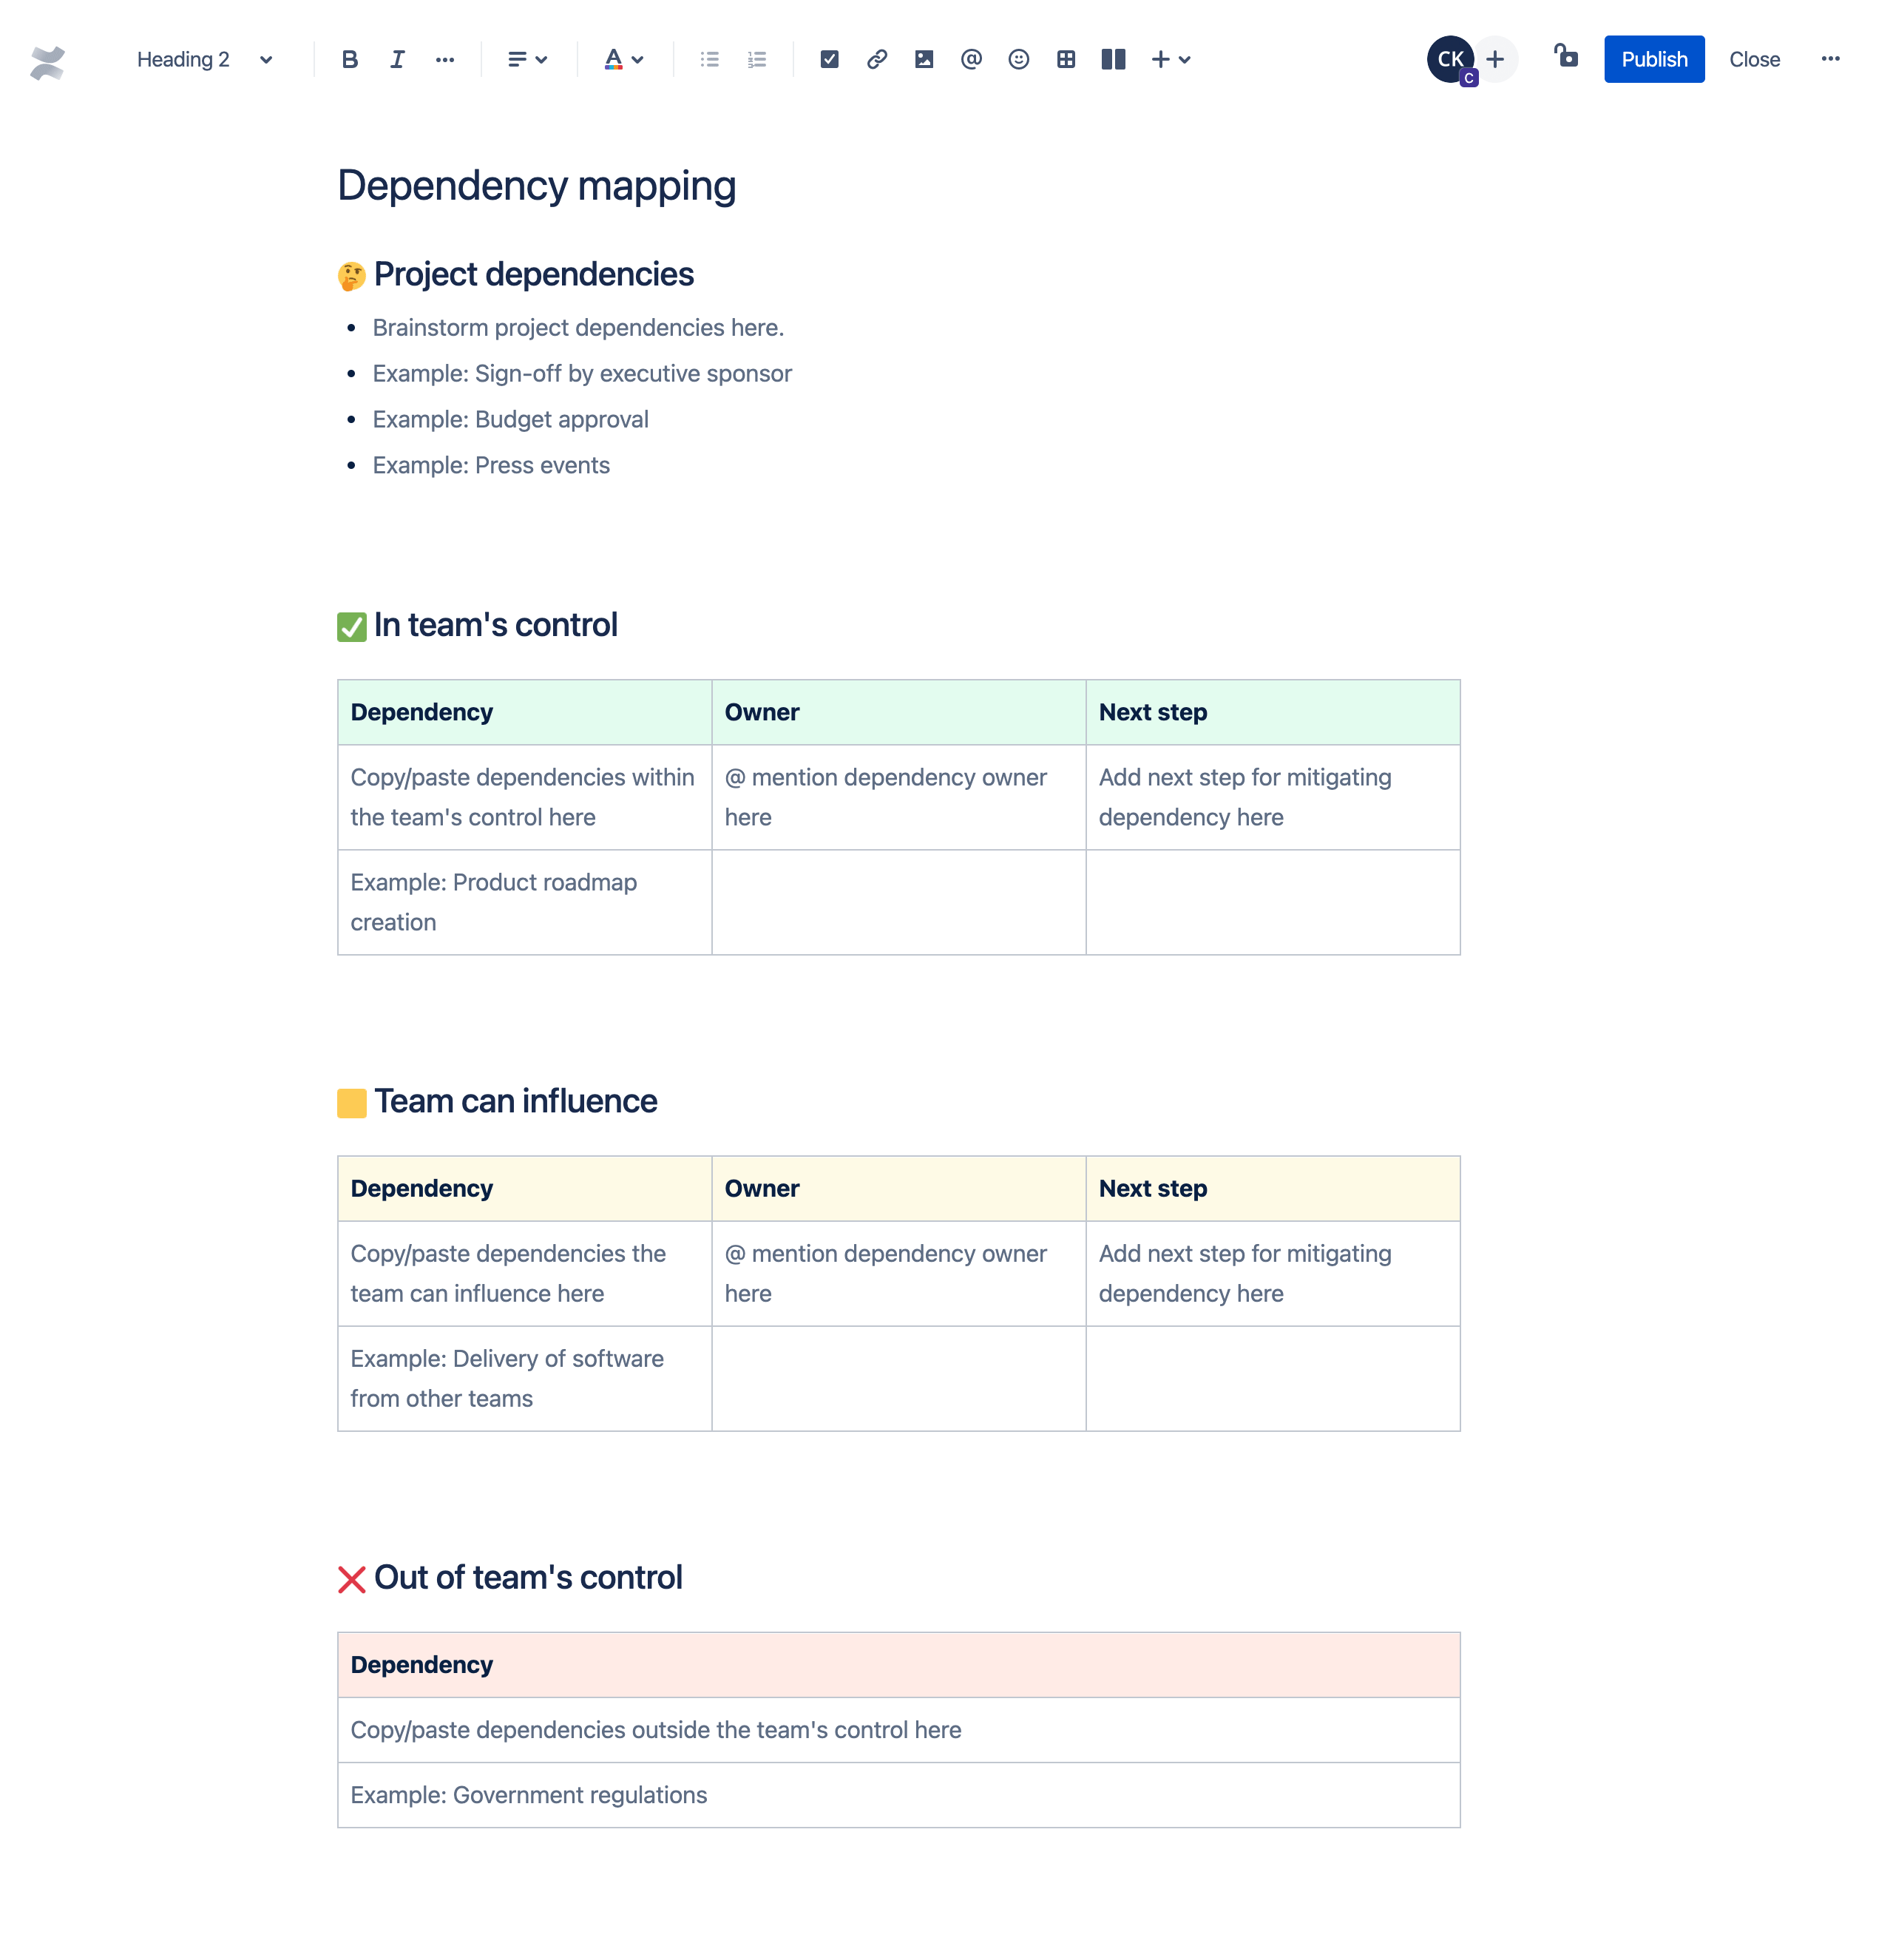
I've been mapping application dependencies across enterprise environments for over a decade, and I can tell you that most templates you find online are worthless. They're either too generic to be useful or they've been designed by people who've never actually had to track a broken dependency at 3am. I'm going to walk you through what works, what doesn't, and the one edge case that costs teams hours of frustration if they don't account for it. Start with the components. A proper template needs to capture four things: the application itself, what it depends on, what depends on it, and the nature of that dependency. That's it. Most people try to get fancy and add fields for risk scores, business criticality ratings, SLA tiers, and compliance flags all in the first pass. You're just going to abandon that spreadsheet within a week because nobody wants to fill out seventeen fields every time they document a relationship. Keep it simple. Add granularity later when you actually need it. The fields I always include are application name, version, owner, dependency type (API call, database connection, file transfer, message queue, shared library, etc.), target system, frequency of interaction, and a notes column. That's eight fields. Eight. I once worked with a team that had forty-two columns in their dependency tracker and couldn't get anyone to update it past quarter one. Don't be that team.
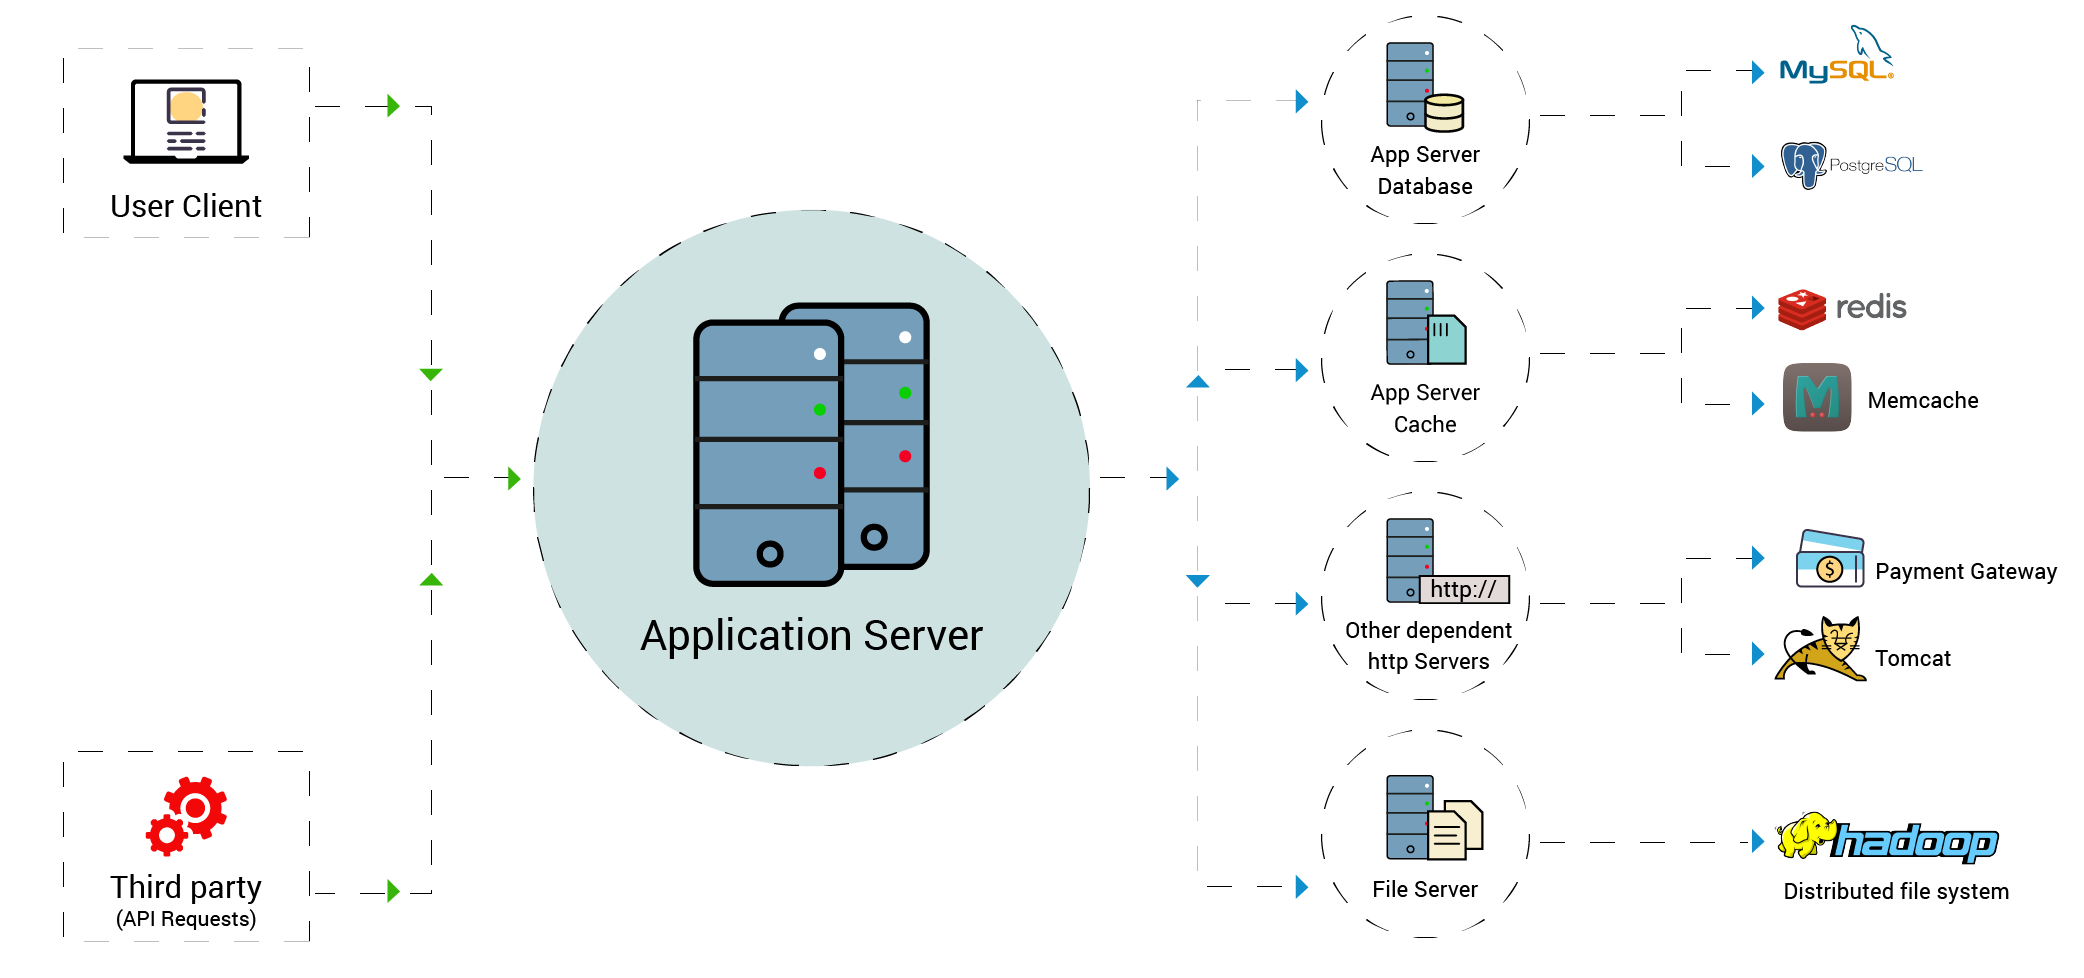
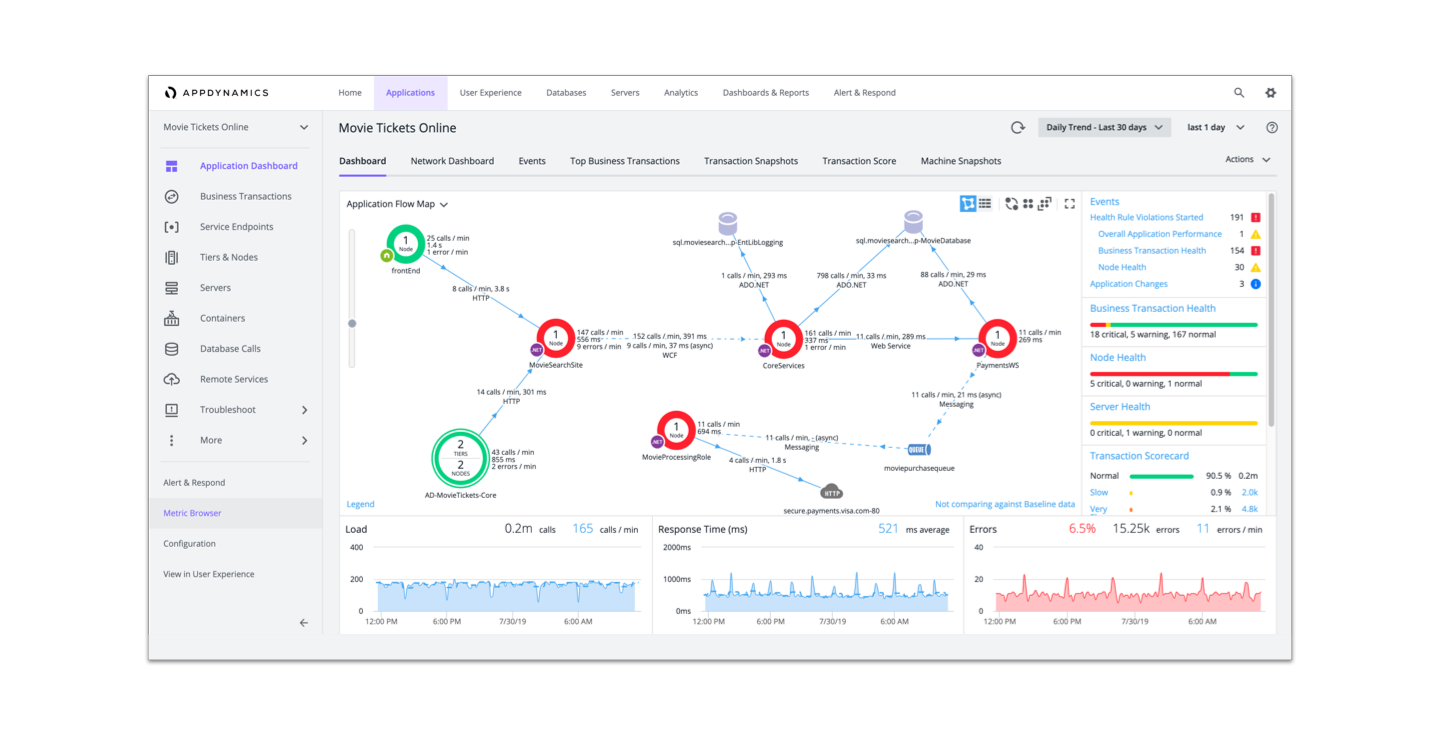
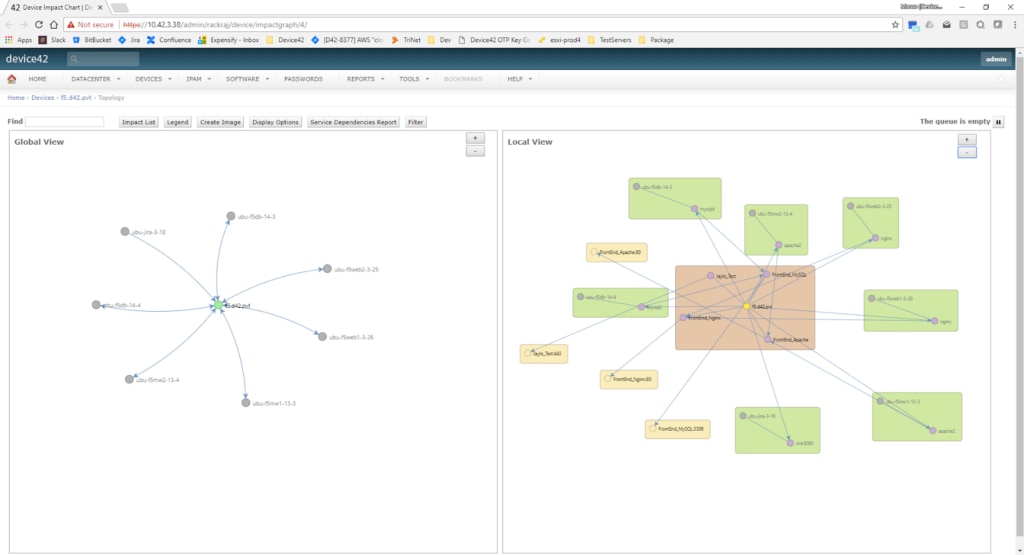
Here's something most people miss: the dependency type field is where everything falls apart. Beginners always group everything under "integration" and call it a day. That's useless when you're trying to understand blast radius. An API call has completely different failure characteristics than a nightly batch file transfer or a shared database table. If you're pulling data from a microservice via REST and that service goes down, your application fails immediately. If you're reading from a shared data warehouse that refreshes daily, you won't know anything is wrong until the next scheduled run. The dependency type tells you how fast and how loudly a break will surface. I also recommend adding a field for discovery method. How did you determine this dependency exists? Was it pulled from infrastructure monitoring, traced through code analysis, confirmed by the application owner, or guessed at based on organizational assumptions? This matters more than you think. When I was working on a migration project last year, we found that approximately forty percent of the dependencies documented in our team's shared tracker were stale. Not incorrect, just stale. They referenced systems that had been decommissioned two years prior or APIs that had been replaced. The dependencies that came from automated discovery tools were far more accurate than the ones people had filled in from memory during a planning session. The real headache comes with implicit dependencies. These are the connections nobody documents because nobody remembers them. A shared configuration file on a network drive. A cron job that reads from a specific database schema. An environmental variable that points to a resource management console you didn't know about. I spent three weeks troubleshooting a production issue where two unrelated applications were both writing to the same S3 bucket for audit logs, and neither team knew the other existed. The Application Dependency Mapping Template would have caught this if someone had bothered to fill in the notes column with that level of detail. Most people don't.
Building the Template Without Overcomplicating It
There are two approaches here. You can build it in a spreadsheet tool like Excel or Google Sheets, or you can use a dedicated CMDB or dependency mapping platform. I've done both and I'll tell you where each one breaks. Spreadsheets work fine if you have fewer than twenty applications and your environment is relatively static. The problem is scale. Once you hit fifty or sixty applications with bidirectional dependencies, you start running into issues with version control, conflicting edits, and the general chaos of trying to maintain a living document that ten different teams all think they own. I've seen teams maintain dependency maps in shared Excel files and end up with twelve copies floating around, each with slightly different data, and no one knowing which one was current. That's not a dependency map anymore. That's a liability. If you go the platform route, the main trap is letting the tool define the structure rather than your actual needs. Some tools push you toward overly complex taxonomies and rigid ontologies that take months to configure and still don't answer the questions you actually have. Keep the field count low. Force the tool to work for your workflow, not the other way around. I've watched engineers spend six weeks customizing their CMDB to match some idealized dependency model before realizing they could have gotten seventy percent of the value out of a simpler setup in two days.
Get the Full Details
Another thing people get wrong is thinking the template is a one-time setup task. It isn't. Your applications change. Services get decommissioned. New integrations ship. Dependencies get buried under technical debt. I recommend treating the template as a living artifact with a quarterly review cadence. Not annual. Quarterly. Every three months, have the application owners validate their listed dependencies. It takes maybe thirty minutes per person and it keeps the whole thing from becoming a museum piece. The field I see teams skip most often is the owner column. Put an actual person's name or a team alias there. "Unknown" or "TBD" is not an acceptable owner. When a dependency breaks at midnight and you're trying to figure out who to page, you need to know within thirty seconds, not after spending twenty minutes searching through Slack history and Confluence pages for who last touched this thing. This sounds obvious and most teams still get it wrong.
Common Application Dependency Mapping Template Mistakes
Mistake number one: documenting the happy path and nothing else. Your template should capture failure modes, not just active connections. How does the dependent application behave when the source goes down? Does it fail open or fail closed? Does it retry, queue, or throw an error? This information is critical for impact analysis and it's almost never in the templates I see. Mistake number two: treating internal services the same as external dependencies. They require different tracking. An internal microservice you control can be modified, redeployed, or taken offline with a change process. An external SaaS dependency you don't control has its own release cycle, its own outage history, its own vendor lock-in. Mix them together and your risk assessment becomes meaningless. Mistake number three: using the template as a reporting artifact instead of a working document. I've seen teams produce beautiful dependency maps for executive presentations and then never touch them again. The value is in the daily use, not the quarterly review. If your team isn't checking the template when they're building new integrations or decommissioning old ones, you've wasted your time.
There's also the issue of cross-team dependencies. These are the hardest to map because they cross organizational boundaries. Team A doesn't know about Team B's API. Team B doesn't document their consumers. The dependency exists and it matters, but it's invisible to both sides until something breaks. I've found that the only reliable way to surface these is through log correlation and network traffic analysis rather than relying on people to fill out forms. Technology can tell you what connections actually exist even when the humans involved don't know about them. One more thing: don't ignore the data quality of your sources. If you're pulling application names from five different systems that don't agree on naming conventions, your mapping will be garbage. Standardize on a single source of truth for application identity before you start building relationships. I saw a team try to merge dependency data from ServiceNow, Splunk, Datadog, and a bunch of spreadsheets without first establishing that "Payment Processing API" and "payment-api-prod" and "PAY-PROC" all referred to the same thing. They ended up with duplicate nodes and phantom dependencies that made the whole map unreliable. The template itself should be something you can download and adapt, not a prescription. Use it as a starting point and modify it for your environment. What matters isn't whether your fields match some industry standard exactly. What matters is that when the next outage hits, you can open the document and understand what's connected to what without needing a decoder ring. That's the only metric that counts.