Where Application Lifecycle Management Security Actually Breaks Down
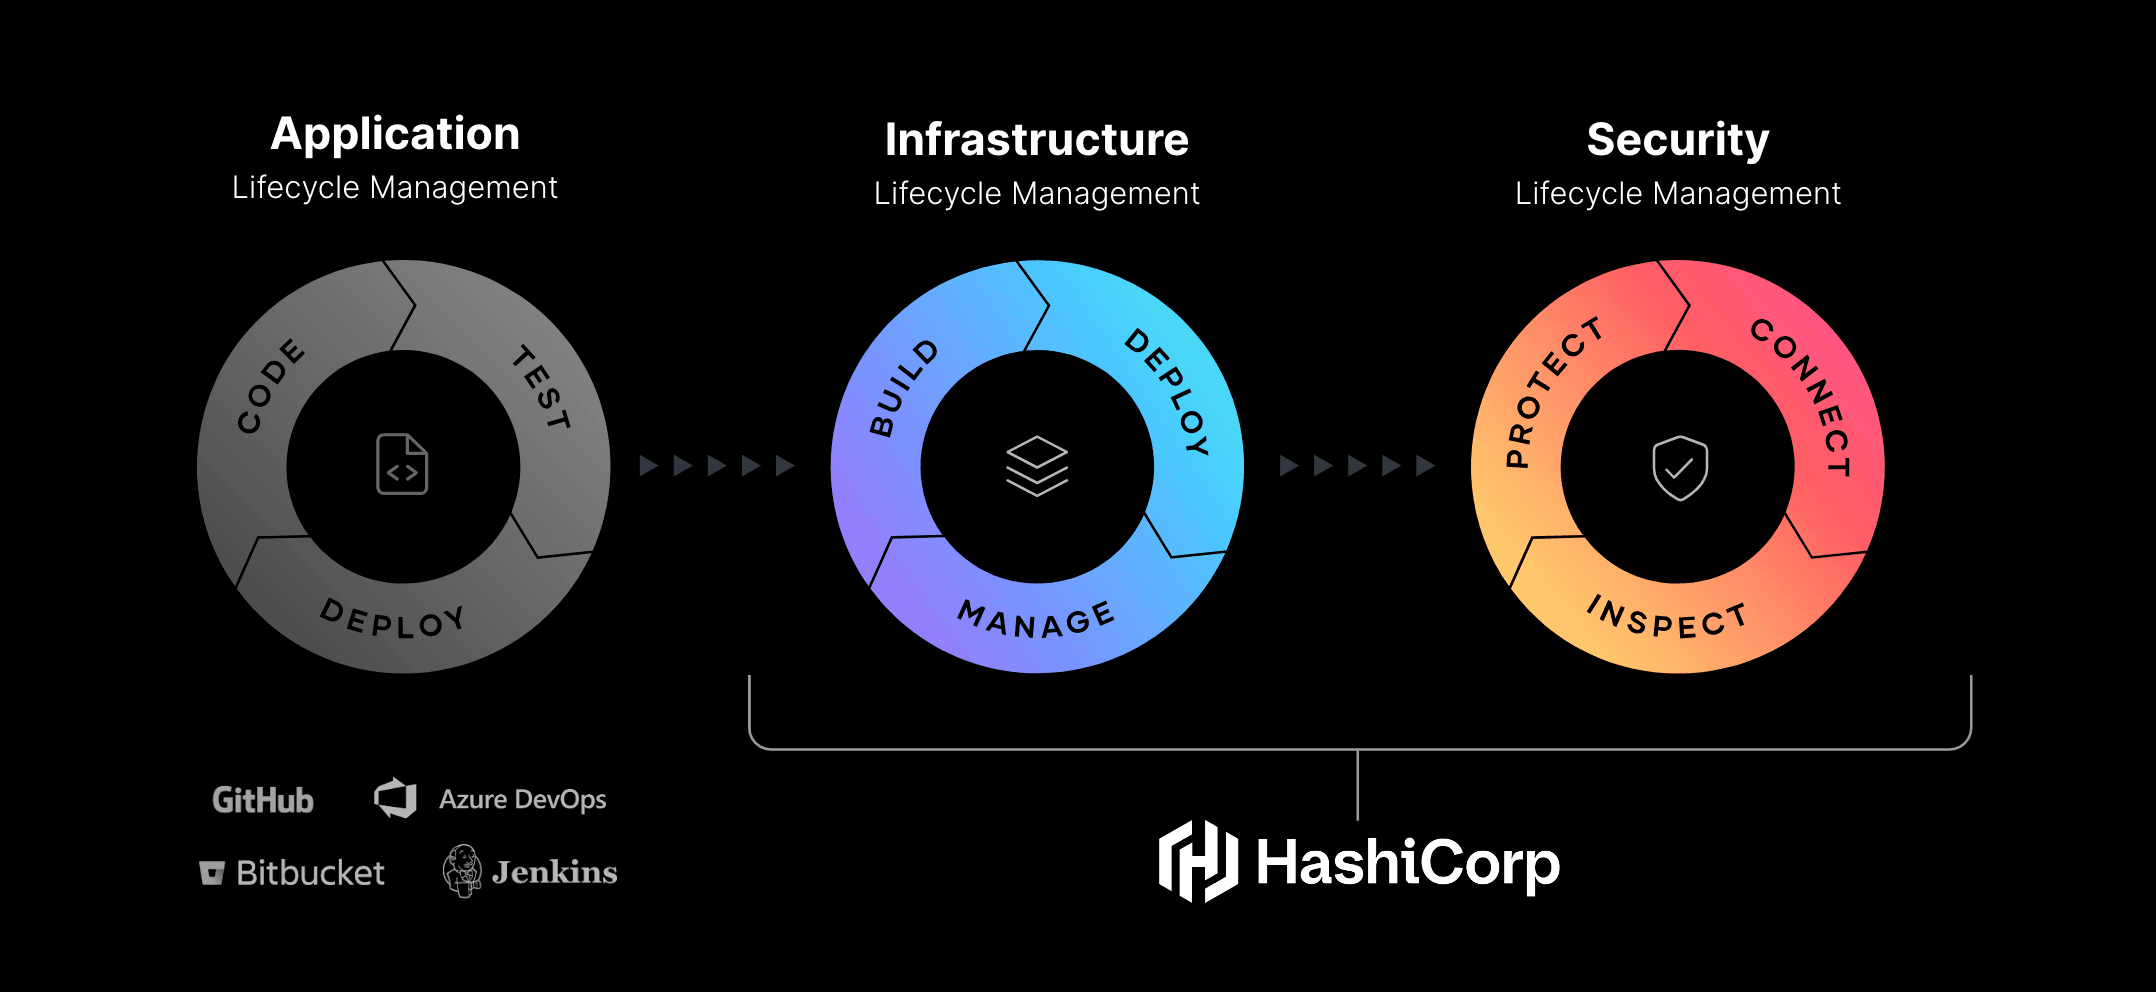
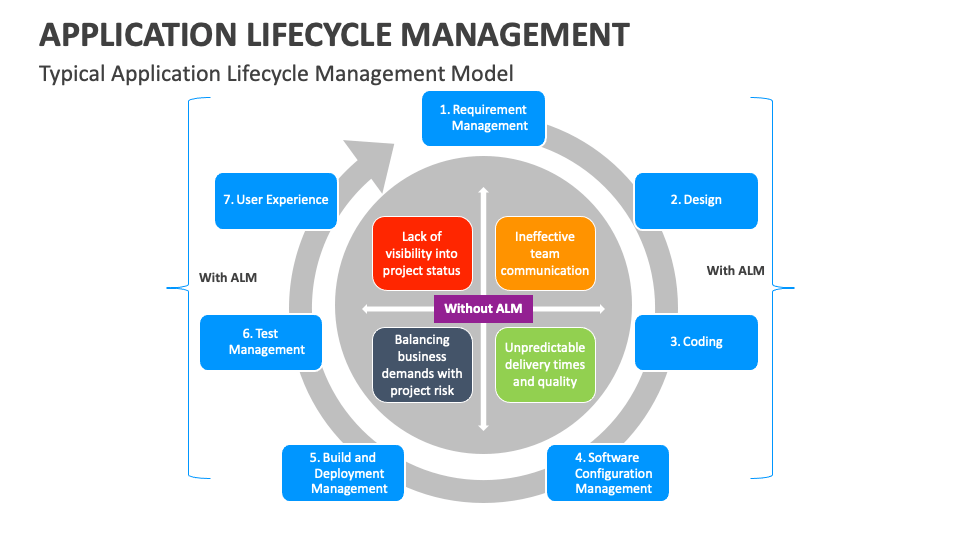
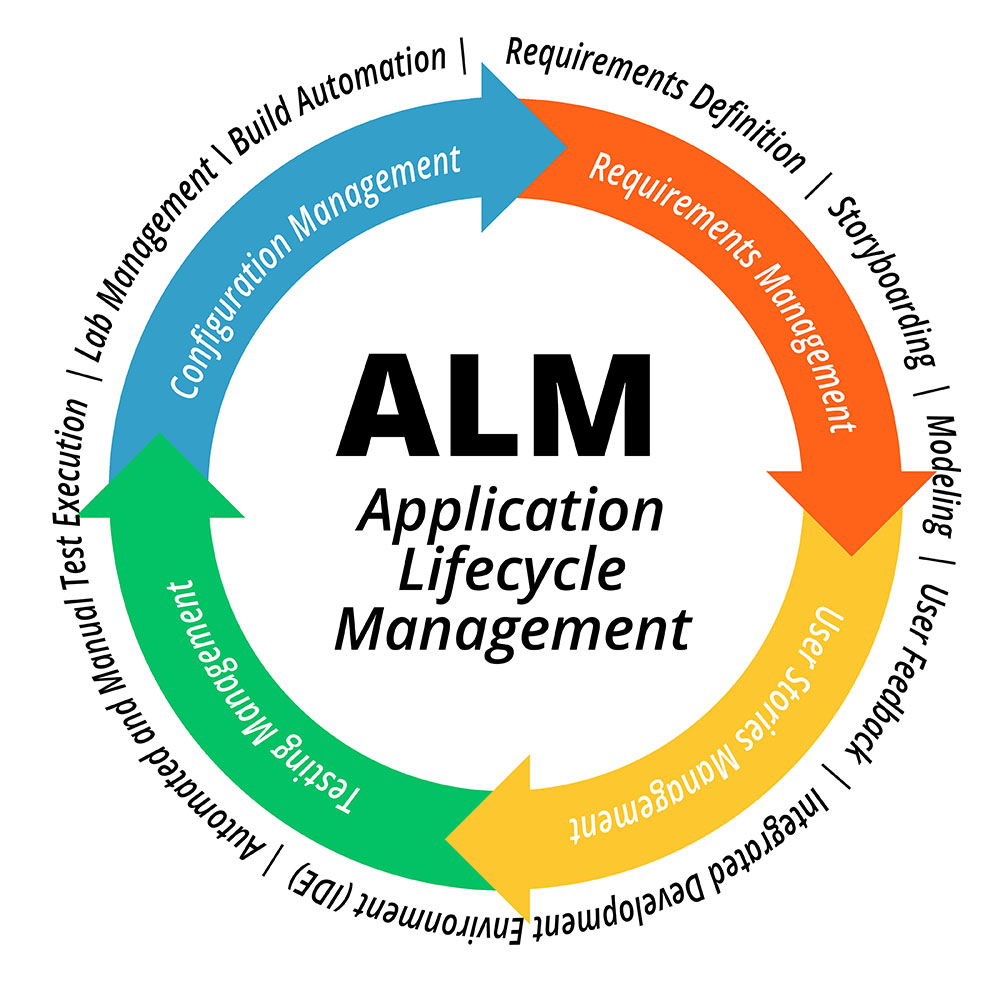
Most teams treat ALM security as a checklist you attach to a CI/CD pipeline after the code is already written. That approach leaves massive gaps. I spent three years managing release infrastructure for a mid-size fintech org, and the hardest part wasn't implementing tools—it was getting people to care about secrets scanning before merge rather than after deployment. Here's how the workflow actually works when it's done right. Application Lifecycle Management Security is the practice of embedding security controls into every phase of software development—from initial design through decommissioning—rather than bolting them on at the end. It covers secret detection in code repositories, vulnerability scanning of dependencies, runtime protection during staging, compliance checks before production release, and secure data handling when old environments are torn down. The goal is to catch issues when they're cheap to fix, not expensive to explain to an auditor. The reason this matters is simple: the cost of fixing a vulnerability scales exponentially the further it moves from discovery. A hardcoded API key in a config file costs nothing if your scanner catches it during a pull request. That same key in a production environment costs engineering hours, incident reports, and potentially regulatory fines.
The Core Pipeline: How Security Fits Into Each Phase
Start with the design phase. Before anyone writes a line of code, you need a threat model. Not a five-page document that gets shelved. A one-page map of what data flows where, which components touch sensitive inputs, and where trust boundaries exist. I used to run a twenty-minute threat modeling session per sprint using a shared Miro board with three colored stickers—one for each data sensitivity tier. Takes five minutes to set up, saves hours of rework later. Then comes the build phase. Every commit should trigger automated scanning. This includes static analysis for code patterns, dependency checking against known vulnerability databases, and secrets detection. Tools like Trivy for container scanning, Snyk or Dependabot for dependency issues, and Gitleaks for secret detection are standard. Configure them to block merges when critical findings appear. Not warn. Block. Warnings get ignored. Blocks force action. The testing phase needs both automated and manual work. Automated tests cover infrastructure-as-code scanning with tools like Checkov or tfsec, plus dynamic application security testing against your staging environment. Manual penetration testing should happen at least once per major release cycle. I've seen teams skip the manual portion entirely and still consider themselves secure. They weren't. Automated scanners miss business logic flaws. They miss authentication bypasses that only surface when you try to do something the system wasn't designed to prevent.
Deployment is where most ALM security programs fail. The gap between staging and production is a blind spot. Containers that passed scanning in staging may behave differently under production load. Database migrations can expose data to different access paths. Environment variable configurations shift. Run canary deployments with limited blast radius. Monitor closely. Roll back fast if something looks wrong. Post-deployment security isn't over. You need ongoing monitoring for new vulnerabilities in your dependencies, runtime anomaly detection, and incident response procedures that are actually tested—not just documented. Set up automated alerts for new CVEs affecting your stack. Integrate them into your existing ticketing system so findings surface in the same workflow developers already use.
Get the Full Details
The Secret Scanning Problem I Faced (And How I Fixed It)
Here's a specific problem I dealt with: our GitLab CI pipeline had Gitleaks configured to scan for secrets, but it was returning too many false positives from legacy configuration files and development test keys that everyone had committed months ago. The noise caused the security team to dismiss alerts entirely. Someone would see a notification, glance at five existing false positives, and close the ticket without investigation. The workaround was two-pronged. First, I created a .gitleaks.toml ignore list scoped to specific file paths for known-test-files only, with an expiration date built into the comment metadata. Second, I implemented a separate retrospective scan that identified previously committed secrets and generated individual remediation tickets routed directly to the committer with a hard deadline. The result wasn't pretty—thirty-two confirmed leaked credentials across six repositories—but it cleared the debt in two weeks instead of letting it fester indefinitely. The broader lesson: false positive fatigue kills security programs faster than any actual vulnerability. If your scanning tools generate more noise than signal, tune them aggressively. Better to miss one edge case than to make your team ignore all alerts.
Common Pitfalls That Beginners Miss
The biggest mistake I see is treating Application Lifecycle Management Security as a tooling problem rather than a process problem. Buying a $50,000 enterprise DAST license won't help if your developers are committing to main branch without review. Process precedes tooling. Every time. A second pitfall is ignoring the decommissioning phase. When you retire an old microservice or shut down a staging environment, data doesn't just disappear. Database snapshots, container images, CI/CD artifact caches, and backup tapes all retain information. I once audited a decommissioned analytics cluster and found customer PII in uncompressed PostgreSQL dump files sitting in an S3 bucket that hadn't been accessed in fourteen months. The service had been replaced six months prior. No one had cleaned up. Data retention policies need to be enforced at the infrastructure level, not remembered by whoever happens to own the service. Tag every resource with a retention policy at creation time. Automate deletion based on those tags. Manually auditing for orphaned data is a losing game.
Tooling That Actually Holds Up
For static analysis, Bandit for Python projects is solid and low-overhead. For Go and Rust repos, run gosec and rustfmt with security profiles enabled. Java projects should use Checkmarx or the open-source Semgrep ruleset. Each language ecosystem has different vulnerability patterns, so a one-size-fits-all scanner will miss domain-specific issues. Container security requires a layered approach. Scan the base image for known CVEs before building on top of it. Scan your final image after build. Scan again before pushing to a registry. These aren't redundant—they catch different things at different stages. A base image might have been patched after you started building, so scanning at each step catches regressions. For infrastructure-as-code, Checkov works across Terraform, CloudFormation, and Kubernetes manifests. It identifies misconfigurations like public S3 buckets, unencrypted RDS instances, and overly permissive IAM roles. Integrate it into your pre-commit hooks so violations surface before the code leaves your machine.
The monitoring piece often gets shortchanged. Set up a dashboard that tracks mean time to detection and mean time to remediation for security findings across your pipeline. Without these metrics, you're flying blind about whether your ALM security program is actually improving over time.
When ALM Security Won't Save You
I need to be straightforward about limitations. Automated scanning cannot detect social engineering vulnerabilities. It cannot identify whether your team is falling for phishing attacks that lead to credential compromise. It cannot replace the judgment call of a senior developer who recognizes an unusual API response pattern during code review. Tooling catches what rules can define. Human review catches what rules haven't anticipated. Similarly, ALM security tools assume your configuration is correct. If someone misconfigures a scanner to allow all findings or disables checks in a production stage to speed up releases, the tools provide zero protection. I've seen this happen more often than I'd like to admit. The scanner was technically in place, fully configured, and generating reports—just configured to report only informational findings with zero blocking rules. Compliance frameworks like SOC 2 or ISO 27001 will require evidence of Application Lifecycle Management Security implementation, but they don't guarantee security. Passing an audit and being secure are different things. I've seen companies with perfect audit scores suffer breaches from vulnerabilities their auditors never checked for.
A Realistic Implementation Timeline
If you're starting from scratch, don't attempt to implement everything at once. Here's what I've seen work in practice: Week one: Set up basic git hooks with secret detection. This catches the lowest-hanging fruit and builds habit. Most teams find three to eight leaked secrets in their first scan. It feels dramatic but it's the easiest win. Week two: Integrate dependency scanning into your CI pipeline. Configure it to report but not block yet. Let your team see what their dependencies look like before you start enforcing rules.
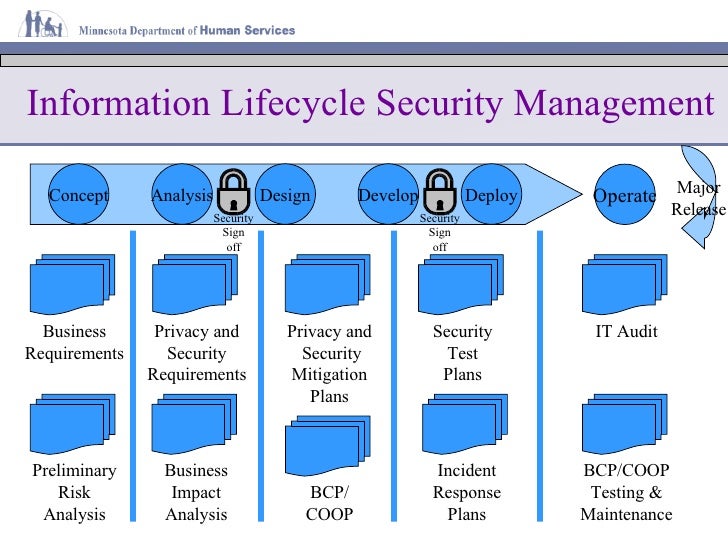
Week three: Add static analysis for your primary language. Set blocking rules for critical findings only. Start with a lenient posture and tighten over the following month. Month two: Implement container image scanning and infrastructure-as-code checks. By now your team has adjusted to the concept of security gates in the pipeline. Month three: Add dynamic testing against staging and configure runtime monitoring. Set up the metrics dashboard. Establish your mean time to remediation target.
This timeline assumes a team of five to fifteen developers with moderate existing DevOps maturity. Larger teams or regulated industries should compress some phases and expand others. The sequence matters more than the speed.
Application Lifecycle Management Security as a Continuous Practice
The framework isn't complete until you establish a regular review cadence. Monthly, audit your scanning rules to check for new CVE patterns in your stack. Quarterly, run a table-top exercise simulating a supply chain attack on your CI/CD pipeline. Annually, review whether your threat model still matches your actual architecture—this is where most teams fall behind. Security in the application lifecycle is not a destination. It's a series of decisions made under constraints, backed by tools that enforce the choices you've agreed on. The tools are easy. The enforcement is hard. That's where most programs stall out.