Application Of Decision Support System In Business
Verma
2025-09-30
How Decision Support Systems Actually Get Built And Deployed
Most people think a decision support system is some magical dashboard that appears overnight. It is not. I spent roughly eighteen months at a mid-size logistics company trying to get one working properly, and the first six months were spent entirely on data that existed in three different formats across two departments that refused to share a database schema with each other.
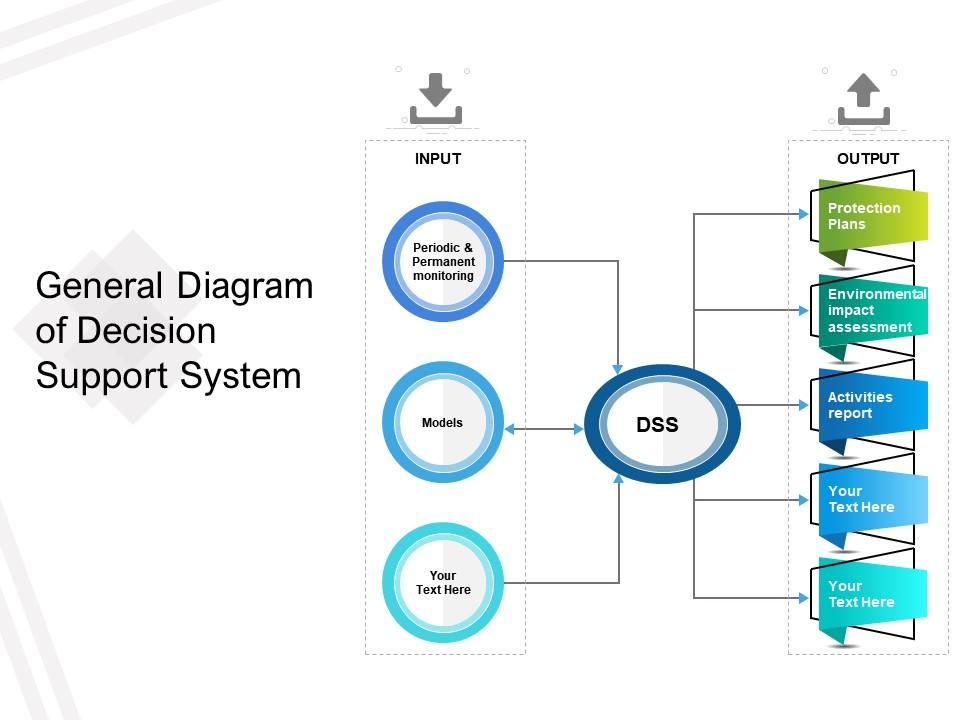
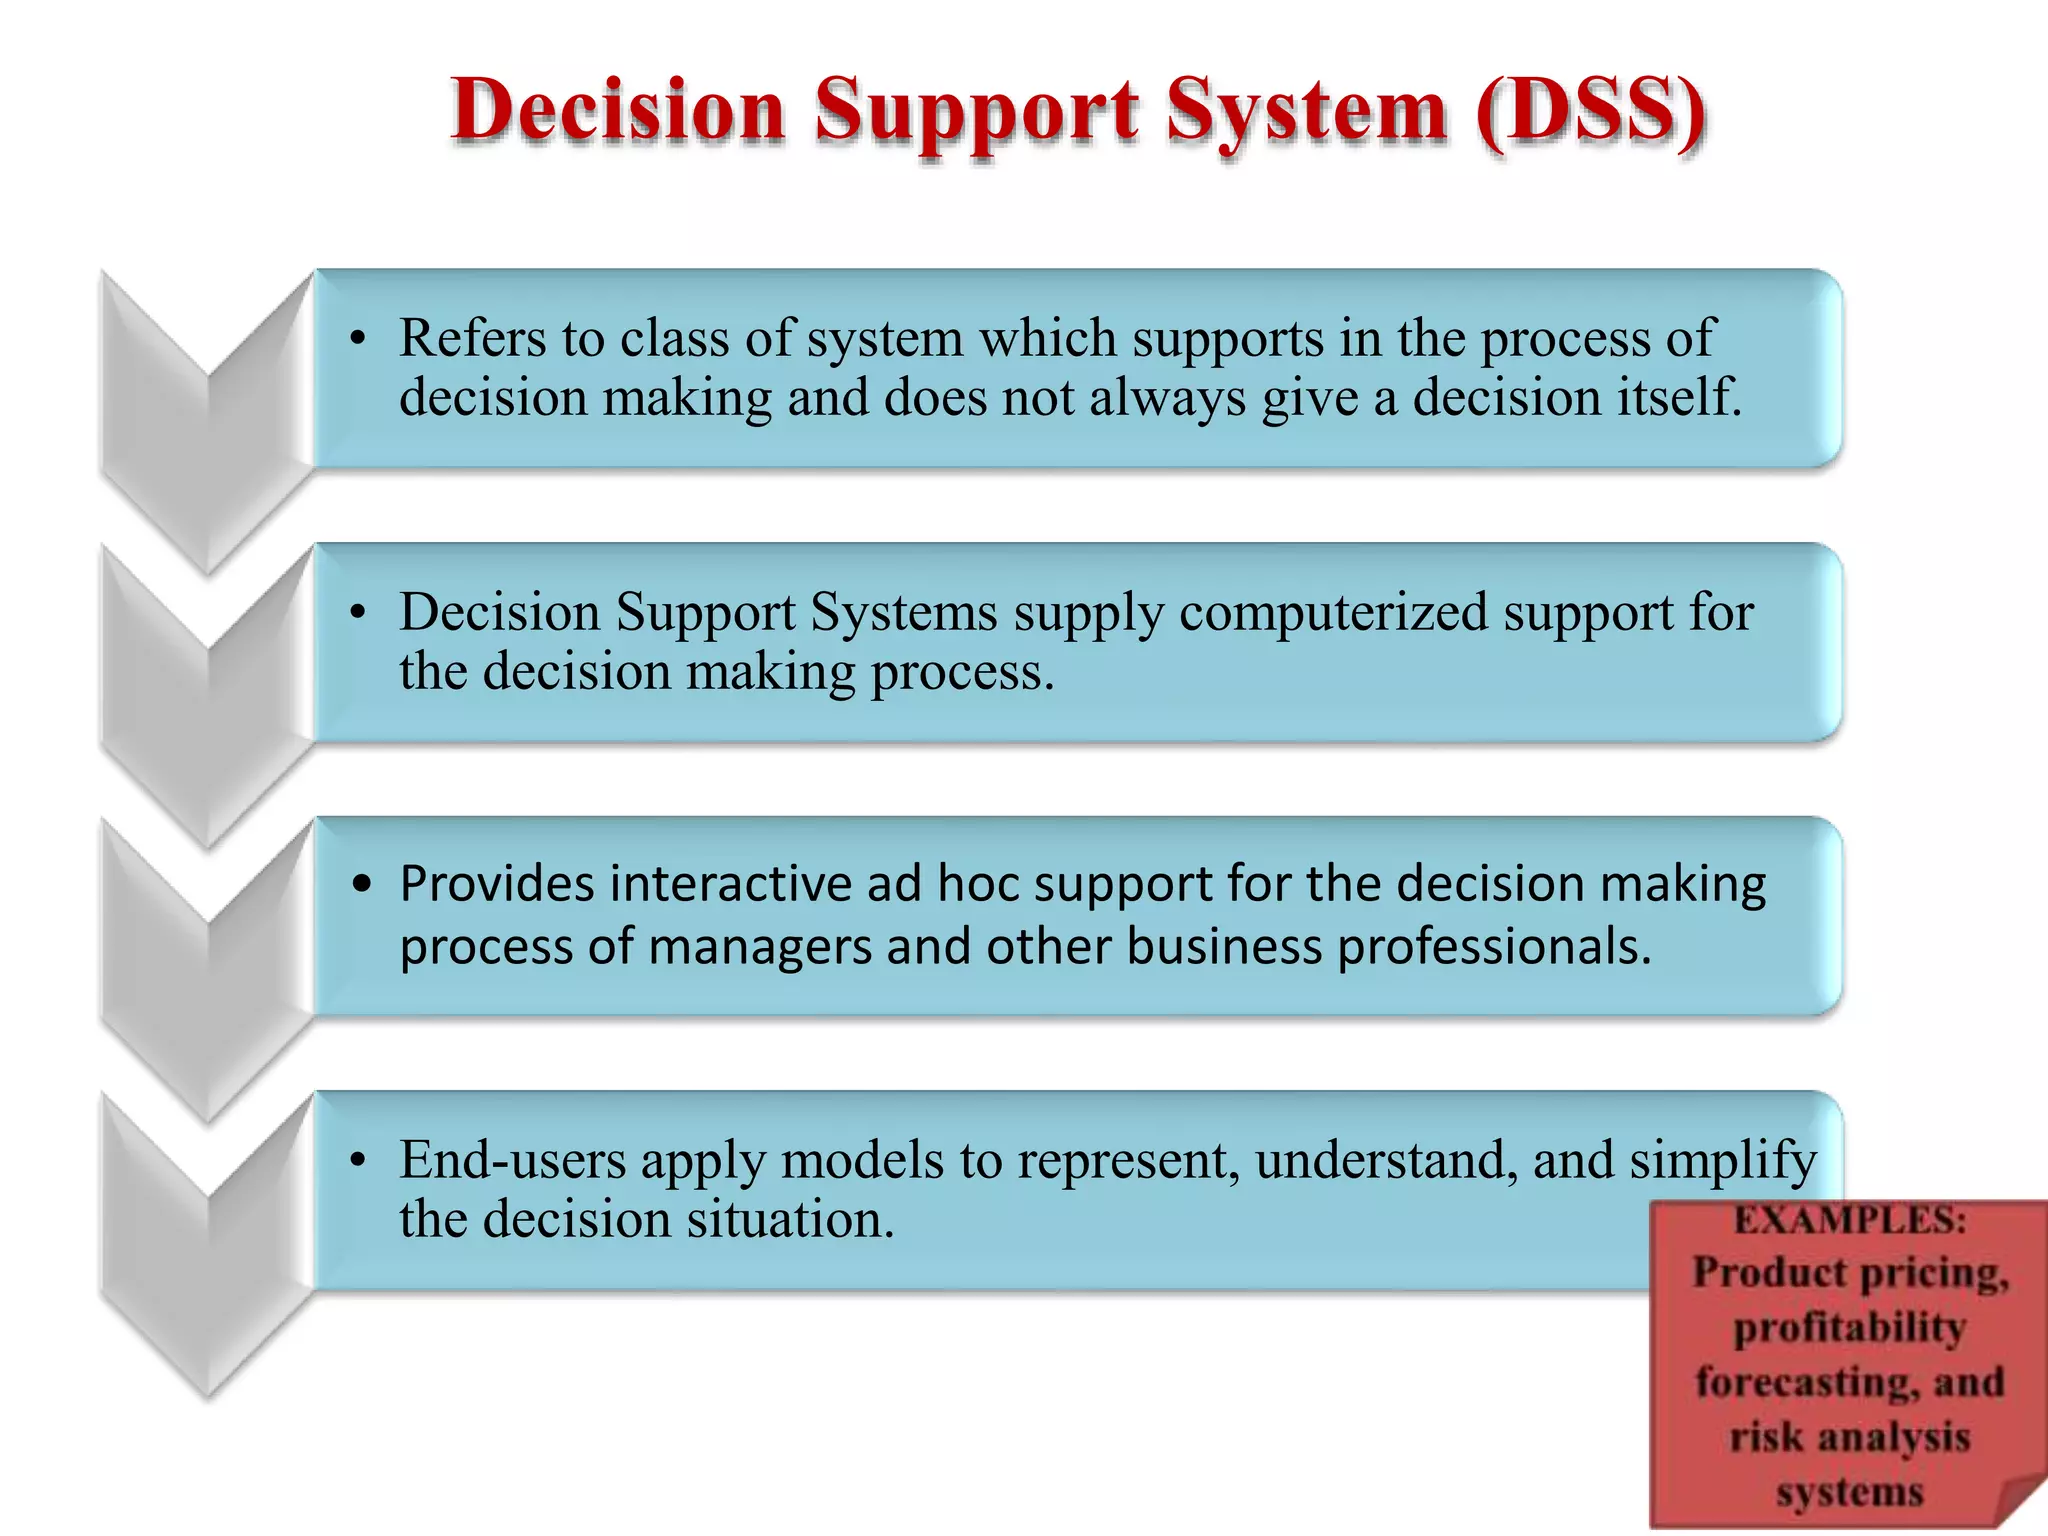
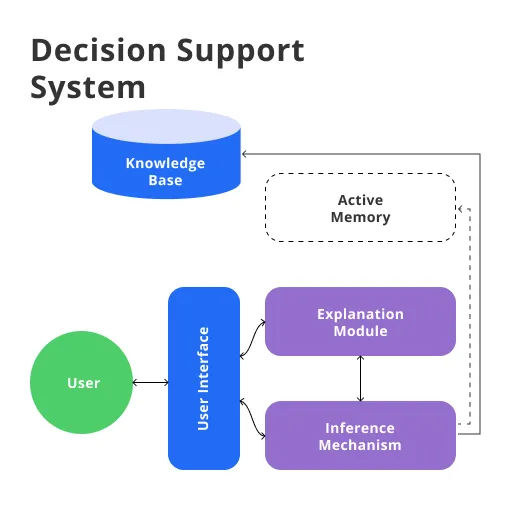
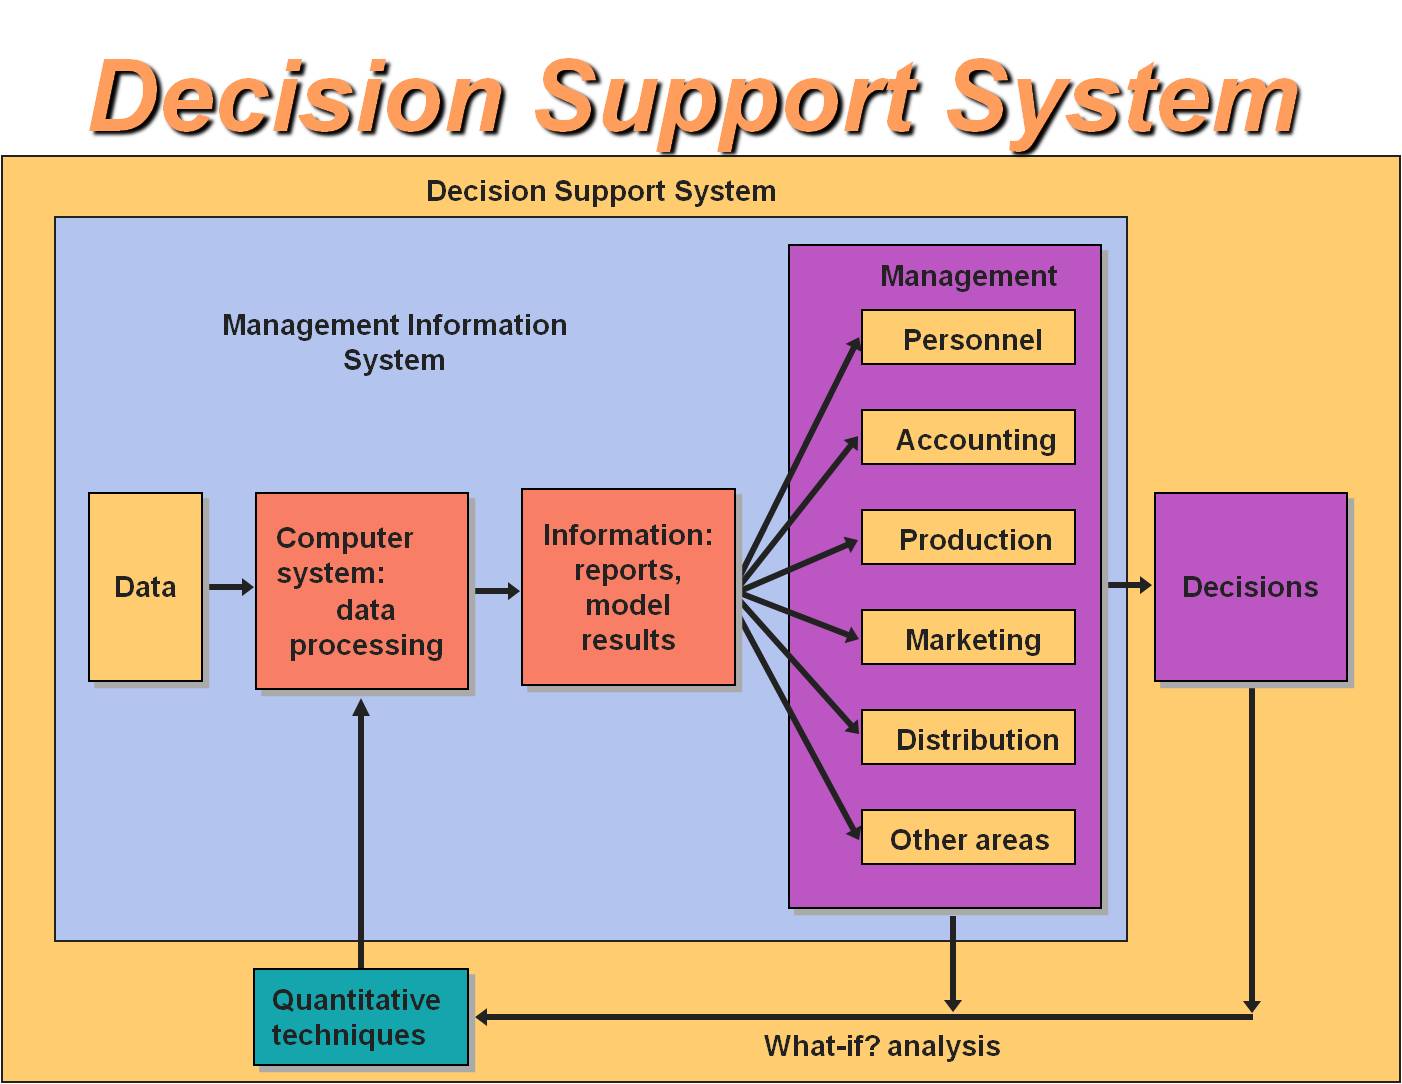
The core concept is straightforward enough. A decision support system takes raw data, runs it through models or analytical processes, and returns information that helps someone make a better choice. The trick is in the architecture, the data hygiene, and knowing when the output is actually usable versus when it is just pretty numbers that look convincing on a screen.
Setting Up Your Data Foundation Before Building Anything
You need a clean data pipeline before you touch any visualization tool or predictive model. I have seen too many teams skip this and go straight into flashy dashboards while their underlying data is built on incomplete feeds. The result is a system that makes decisions worse, not better, because the garbage gets amplified by sophisticated algorithms.
Start by mapping every data source your organization touches. ERP systems, spreadsheets that no one claims, API feeds from third parties, customer relationship management platforms. Document the refresh rates, the owners, and the known gaps. Then build an ETL or ELT pipeline that normalizes everything into a central warehouse or data lake. This is the unglamorous part where most projects stall.
I encountered a particularly nasty edge case involving order fulfillment forecasts at that logistics company. Our prediction model was pulling shipping volume data from the warehouse management system, which updated hourly, but the billing system only synced once per day at midnight. The decision support system was generating inventory recommendations that looked accurate in real time but were actually two steps behind financial reality. We ended up overstocking on items that had already been cancelled on paper.
The workaround was implementing a dual-cursor approach in the database, tracking both the operational timestamp and the financial timestamp for every transaction, then filtering recommendations based on which currency of data was relevant to the decision type. Inventory decisions used the operational feed. Cash flow decisions used the financial feed. It added complexity to the model layer but prevented us from making decisions on half-truths.
Choosing The Right Tools For Application Of Decision Support System In Business
The tool landscape is enormous and the marketing is aggressively misleading. You do not need the most expensive platform. You need something that can handle your data volume, integrate with your existing stack, and stay maintainable when the person who built it leaves.
Business Intelligence platforms like Tableau, Power BI, or Looker handle the visualization and reporting layer well. They are solid for descriptive analytics, showing what happened. But they are weak on predictive capabilities unless you layer additional tools on top. That is where things get messy.
For actual decision support—systems that tell you what might happen or what you should do—you typically need a combination of things. A relational database or data warehouse for storage, a scripting environment or orchestration layer for transforming data, and either a commercial optimization package or a self-built model running in Python or R. SQL Server Analysis Services, IBM Cognos, and SAS are the enterprise-grade options. For smaller operations, open-source stacks with PostgreSQL, Apache Airflow, and scikit-learn can get you remarkably far at a fraction of the cost.
The counter-intuitive insight here is that simpler models often outperform complex ones in production environments. A well-tuned linear regression with clean features will beat a black-box neural network nine times out of ten when your goal is actionable business decisions. Complex models require more data, more maintenance, and more debugging when they silently degrade. Simplicity is not a compromise; it is usually the correct engineering choice.
Building Models That Actually Drive Decisions
A decision support system is only as useful as the decisions it enables. If your model outputs a probability score but provides no guidance on what action to take, it is just a report with extra steps.
There are three main categories of decision support models. Predictive models forecast future outcomes based on historical patterns. Prescriptive models recommend specific actions given certain constraints and objectives. Diagnostic models explain why something happened by tracing causal pathways. Most business applications benefit most from a mix of all three, though predictive capabilities tend to be the easiest to implement first.
I learned this the hard way with a demand forecasting system. We built an excellent predictive model using ARIMA and XGBoost combinations, and the accuracy metrics looked great on paper. But when we presented the outputs to the supply chain team, they could not act on them. The model told them what demand would be but not what to do about capacity constraints, supplier lead times, or storage limits. We had to wrap the predictions in a linear programming optimizer that factored in all those real-world restrictions before the numbers were usable.
The optimization layer added maybe three weeks of development time but increased the actual decision quality by an order of magnitude. Raw predictions without context are noise dressed up in math.
Common Pitfalls That Kill Decision Support Projects
The biggest failure mode is building a system nobody uses. I have seen perfectly functional decision support platforms gather dust because the interface was designed by data engineers for data engineers, not by analysts or managers who actually needed to make decisions. The gap between technical correctness and practical usability is wider than most teams expect.
Another major issue is model drift. Your system might be accurate today, but if market conditions change, customer behavior shifts, or a new competitor enters the space, the models degrade silently. There is no error message when a predictive model slowly becomes less useful. It just keeps producing output that looks reasonable while steering decisions in the wrong direction over time.
You need scheduled retraining pipelines and performance monitoring dashboards that track model accuracy against actual outcomes. If your forecast error increases by more than a threshold percentage month over month, the system should flag itself for review. This is basic operational hygiene that most organizations skip.
Data quality remains the most persistent problem. A decision support system can process garbage data faster than a human can, but the output is still garbage. I worked on a project where the customer churn prediction model was achieving 89 percent accuracy until someone realized that the training data included customers who had died. The model learned to associate certain demographics with churn when the real signal was mortality. Cleaning that up dropped accuracy to 74 percent, which was the actual ceiling, but it also made the model honest.
Implementation Steps For A Working System
Start small. Pick one decision type, one data source, one user group. Build a prototype that takes under eight weeks to deliver. If you spend six months designing the perfect architecture before showing anything to a human being, you have already failed.
Define the specific decision your system will support. Not "improve operations" or "enhance analytics." Pick something concrete like "decide whether to expedite a shipment" or "determine reorder quantities for SKUs below safety stock." The narrower the scope, the faster you get working value and the easier it is to iterate.
Connect to reliable data sources. Validate the data before you trust it. Cross-reference at least two independent feeds for critical fields. Run sanity checks on ranges and distributions before feeding anything into a model.
Build the analytical layer. Start with simple statistical methods. Add complexity only when the simpler approach proves insufficient for the decision quality you need. Document every assumption, every transformation rule, and every threshold value. Someone replacing you will thank you.
Deploy a minimal interface. It does not need to be beautiful. It needs to show the right information to the right person at the right time. A plain web dashboard with clear inputs and outputs is more valuable than a gorgeous three-dimensional visualization nobody knows how to navigate.
Monitor continuously. Track model performance, user engagement, and decision outcomes. Set up alerts for anomalies. Schedule regular reviews of the system's recommendations against actual results. The work does not end at deployment; it just changes from building to maintaining.
The Application Of Decision Support System In Business is not about buying software and waiting for insights to appear. It is about constructing a pipeline from raw data to actionable recommendations, maintaining that pipeline, and accepting that imperfect information is always better than no information. Systems that acknowledge their own limitations and surface uncertainty rather than hiding it are the ones that survive past the first year.
Gallery Application Of Decision Support System In Business
Decision Support System For Business Intelligence PPT Slide
Examples Of Decision Support System – DDVLNE
Decision support system : Concept and application | PPTX
Examples Of Decision Support System – DDVLNE
How to Use Decision Support Systems to Make Better Business Decisions