Setting Up Optimization Problems That Actually Work
I spent three years teaching applied math at a community college before moving into operations consulting, and the thing I see over and over is students trying to force calculus and linear programming to live in the same spreadsheet without understanding where each tool actually applies. They write Lagrange multipliers into a problem that only needs a simplex method, or they set up a linear objective and then try to take derivatives everywhere because they don't know which technique fits what. Here is how you actually approach these problems when you are dealing with real constraints, not textbook edge cases that clean up perfectly.
Applied Calculus With Linear Programming: When to Use Which Tool
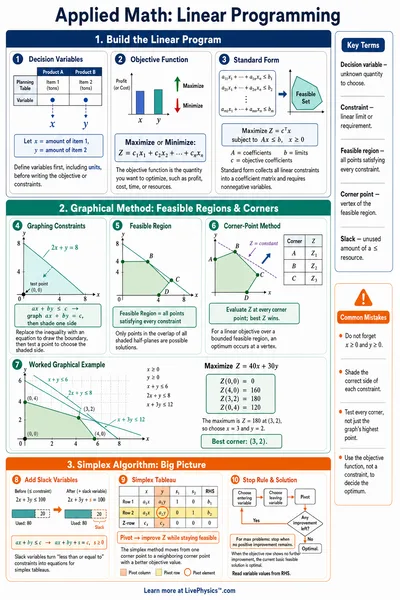
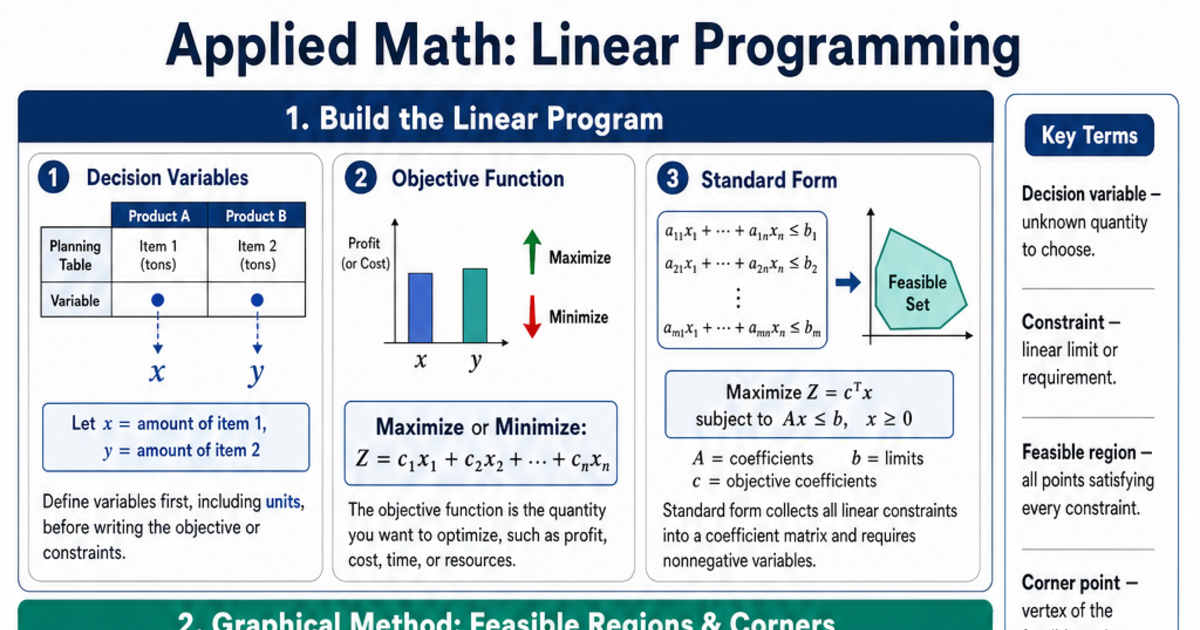
Calculus optimization works when your objective function is continuous and differentiable. Linear programming works when both your objective and your constraints are linear. The moment either one stops being linear, you switch methods. That sounds obvious until you are staring at a quadratic cost function and a bunch of linear resource constraints and wonder whether to differentiate or set up a tableau. The hybrid case is where people get stuck. Say you have a production problem where your revenue function is quadratic but your constraints on labor, materials, and shipping capacity are all linear inequalities. You can handle this with quadratic programming, which is essentially linear programming with a curved objective. Most solvers handle this without issue. The KKT conditions replace the simplex pivot rules here, and you get complementary slackness telling you which constraints are binding. I ran into a specific problem last year for a mid-size warehouse operator who was trying to minimize costs across three distribution centers. The cost function had a quadratic term representing congestion delays, which made sense because throughput bottlenecks aren't linear. But the facility capacity constraints were purely linear. I set this up as a quadratic program and fed it to CPLEX. The solver converged in under four seconds. What took me most of the afternoon was figuring out that the congestion coefficient needed to be calibrated from historical data rather than guessed. I pulled shipping records from the prior quarter, plotted delay time against load percentage, and fitted a second-order polynomial. That single step changed the optimal solution enough to shift which distribution center they should have used as their primary hub. Without that calibration, the model was optimizing a fiction.
Another practical detail most courses skip: sensitivity analysis. When you solve a linear program, the solver gives you shadow prices for each constraint. In calculus-based problems, the Lagrange multipliers serve the same purpose. Learning to read those values correctly saves you from running fifty iterations of what you already solved once you realize a single parameter shifted by ten percent.
Get the Full Details
Common Mistakes That Waste Hours
The biggest mistake I see is ignoring non-negativity constraints. In applied work, variables like production volume or shipment quantities cannot be negative, but standard derivative-based optimization doesn't enforce this automatically. If you set up a Lagrangian without the inequality constraints properly handled, your solution might suggest producing negative units of something. Projecting back to feasible space manually is ugly. Use a solver that handles bounds natively instead of deriving by hand and hoping you catch it. A second mistake is assuming differentiability everywhere. Real cost functions sometimes have kinks. A shipping cost model that switches carriers at a certain volume threshold creates a piecewise linear function. Taking a derivative through that point gives you garbage. I handle this by splitting the domain at the kink, solving each piece separately, and comparing results. It adds maybe twenty minutes to the setup but prevents spending the rest of the day debugging why the optimal solution sits right on the discontinuity. When you move to constrained optimization in multiple variables, checking the second derivative test is routine in textbooks. In practice, you usually don't need the Hessian determinant by hand if you are using a proper solver. But understanding what the test is actually checking helps you interpret failures. If the solver flags an indefinite Hessian, your critical point is a saddle, not a minimum. You then need to check the boundary constraints, not keep iterating around the same interior point.
Practical Setup for Mixed Problems
For problems combining calculus objectives with linear constraints, I use a structured approach. First, write the objective clearly in terms of decision variables. Second, list every constraint, including implicit ones like non-negativity and demand satisfaction. Third, classify: are all constraints linear? Is the objective linear? If yes to both, it is pure linear programming. If the objective is nonlinear but constraints are linear, it is nonlinear programming with linear constraints. If constraints are also nonlinear, you need general nonlinear programming, which is a harder class of problem. There is a free solver called HiGHS that handles linear, quadratic, and mixed-integer problems well. You can call it from Python using the highspy package or through OR-Tools. For small classroom problems, SciPy.optimize.minimize with the SLSQP method works fine and covers most cases where you have both differentiable objectives and linear or nonlinear constraints. The catch with SLSQP is that it requires good initial guesses. Feed it a poor starting point and it may converge to a local optimum that is nowhere near feasible or optimal. I always run at least three restarts from different initial points when the problem is small enough to tolerate that overhead. For larger instances, Gurobi and CPLEX are the standard, but they require licenses. A practical workaround for students and small operations is to use the open-source COIN-OR CBC solver through Pyomo. It handles linear and integer problems reliably. For quadratic objectives, you can reformulate as a mixed-integer linear problem using piecewise linear approximation if the solver doesn't support QP directly. The approximation adds variables and constraints, but for most applied work the trade-off is acceptable and the solution quality remains within a fraction of a percent of the true optimum.
If your problem has integer requirements, like deciding whether to open a facility or not, linear programming alone won't cut it. You need integer programming. The branch-and-bound algorithm solves these, but the computational cost grows fast. A problem with two hundred binary variables and three hundred linear constraints can take minutes to hours depending on the structure. Setting a time limit and accepting the best feasible solution found so far is standard practice rather than waiting for proven optimality.

Data Quality Matters More Than Method Choice
I have solved perfect models with perfect solvers that produced decisions worth less than the cost of implementing them because the input data was sloppy. Linear programming models are only as good as the constraint coefficients you feed them. If your resource availability numbers come from annual budget allocations rather than actual measurable capacity, your optimal schedule will be wrong. Similarly, cost coefficients that don't include hidden expenses like setup time or quality rejection rates will bias the solution toward options that look cheap on paper but are expensive in practice. The workaround I use is to add a five to ten percent buffer on every constraint that represents available capacity. This is conservative but prevents models from recommending schedules that leave zero slack for unexpected disruptions. Purely optimal solutions with zero slack break the moment anything goes wrong. A slightly suboptimal solution with reasonable slack survives real-world variance without requiring constant re-solving. One more thing worth noting: these methods assume static problems. Most real applications are dynamic, with constraints and objectives changing over time. Rolling horizon optimization solves this by re-solving at regular intervals with updated data. Each solve treats the current snapshot as a standalone problem, but the sequence of solutions guides the actual decisions forward. It is computationally cheaper than solving a full dynamic program and usually good enough for operational planning cycles of a week or longer.
If you need a working reference, the scipy.optimize documentation covers constrained minimization in detail, and the PuLP library provides a clean Python interface for linear and integer programming. Both are free and widely used in industry. The learning curve is moderate, and once you have the basic setup pattern memorized, most new problems take you under an hour to model and solve from scratch.