Reading Salary Data in Applied Computer Science
I spent three months pulling compensation data for applied computer science roles last year because the internal HR dashboard was returning inconsistent numbers across locations and seniority levels. The problem wasn't that the data didn't exist. It was that every compensation platform defines "applied computer science" differently, and the titles themselves overlap enough that your search results are garbage unless you know what filters to apply. If you're trying to figure out applied computer science salary ranges, the first thing most people get wrong is trusting a single source. Levels.fyi will show you one slice. Glassdoor will show another. Payscale will show a third, usually lower because it includes outdated self-reported entries from 2019. You need at least three data points before anything looks reliable.
Applied Computer Science Salary: What the Numbers Actually Mean
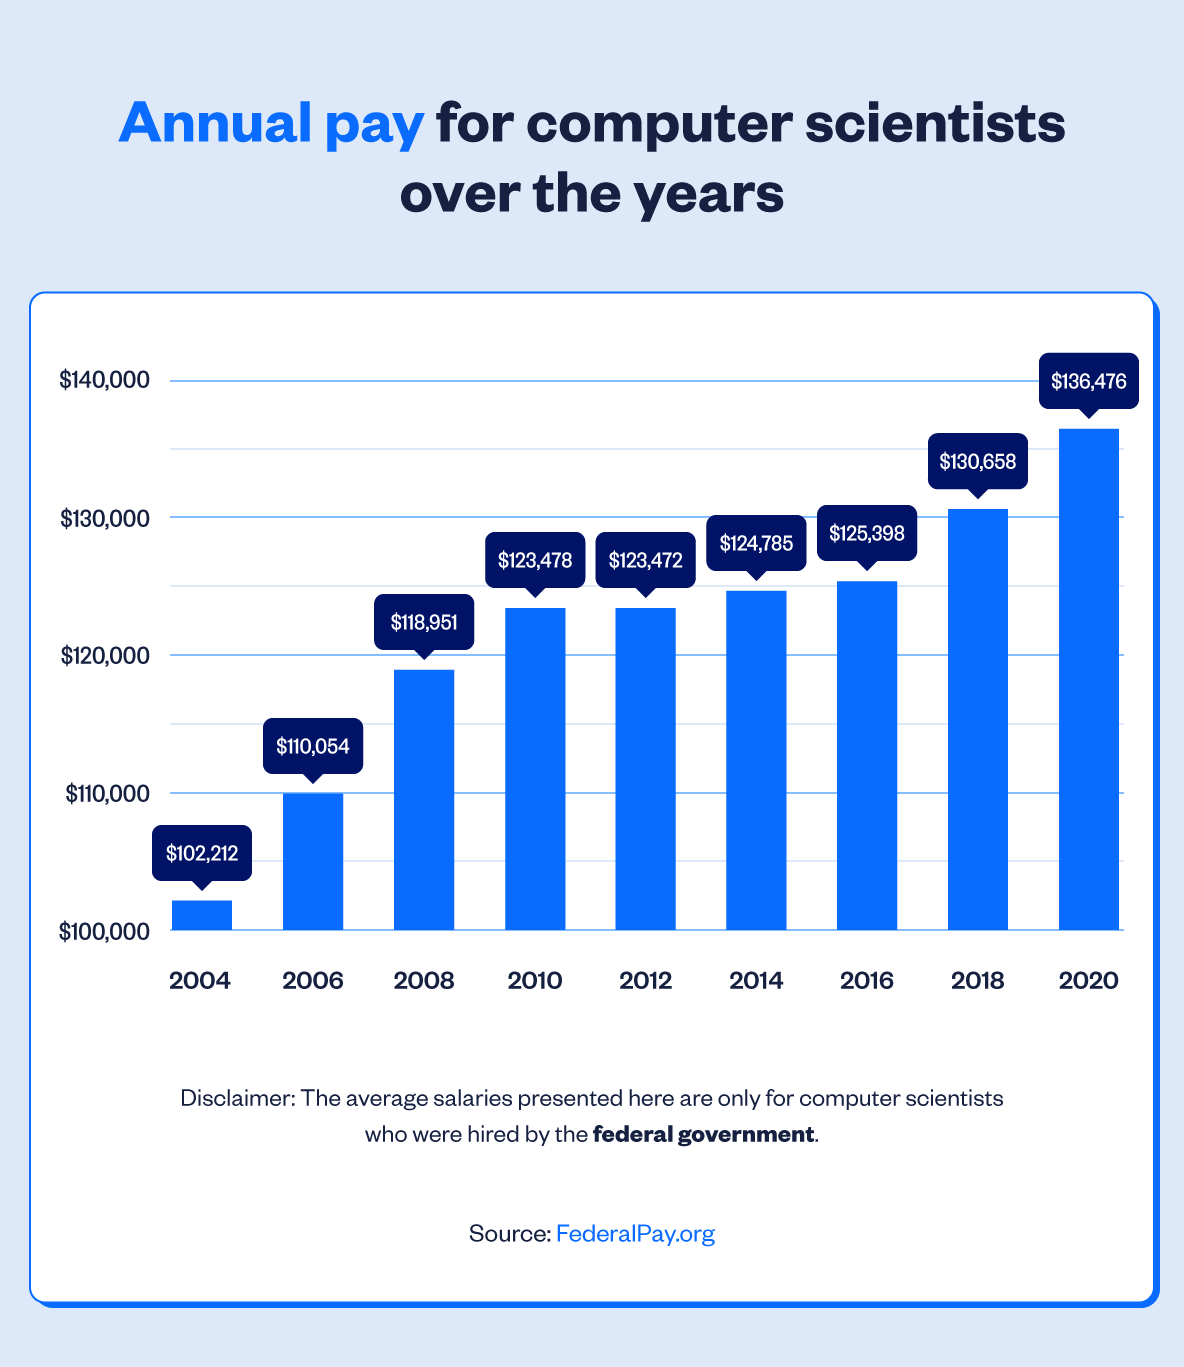
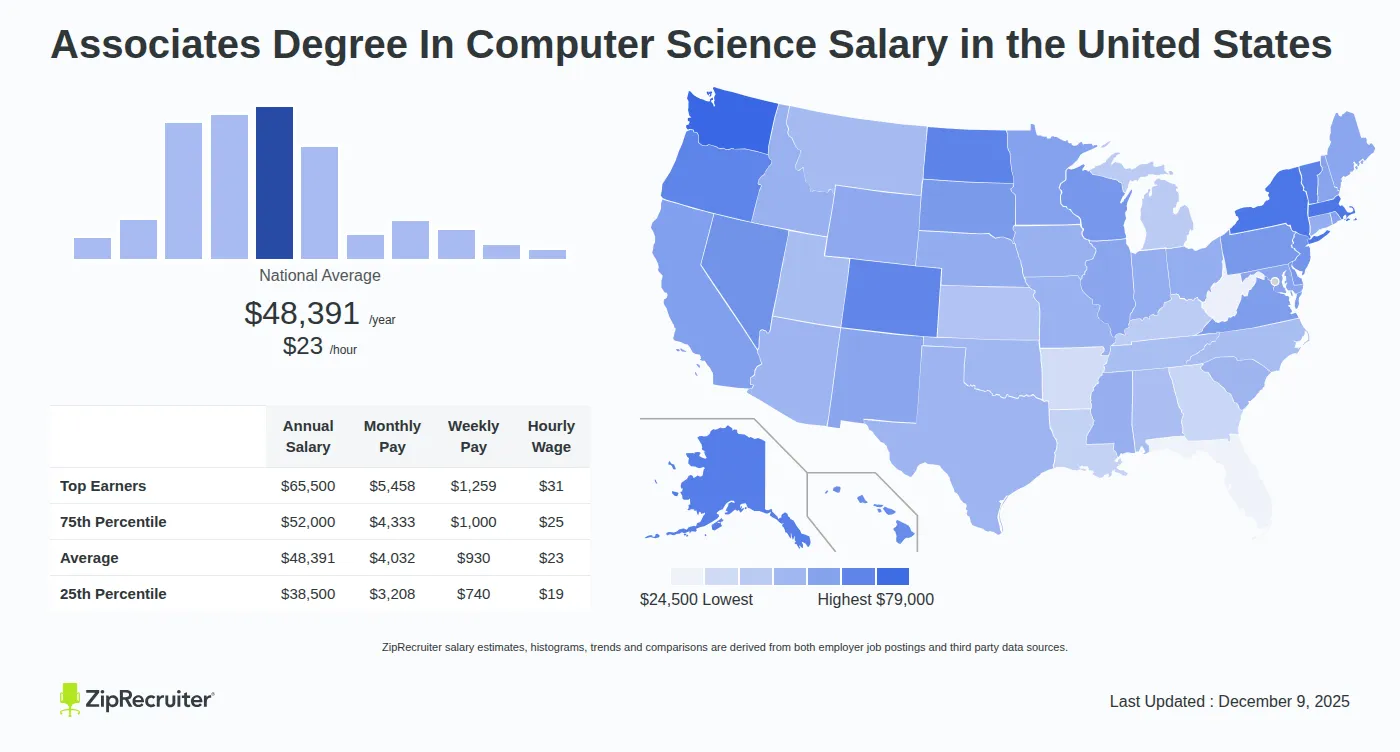
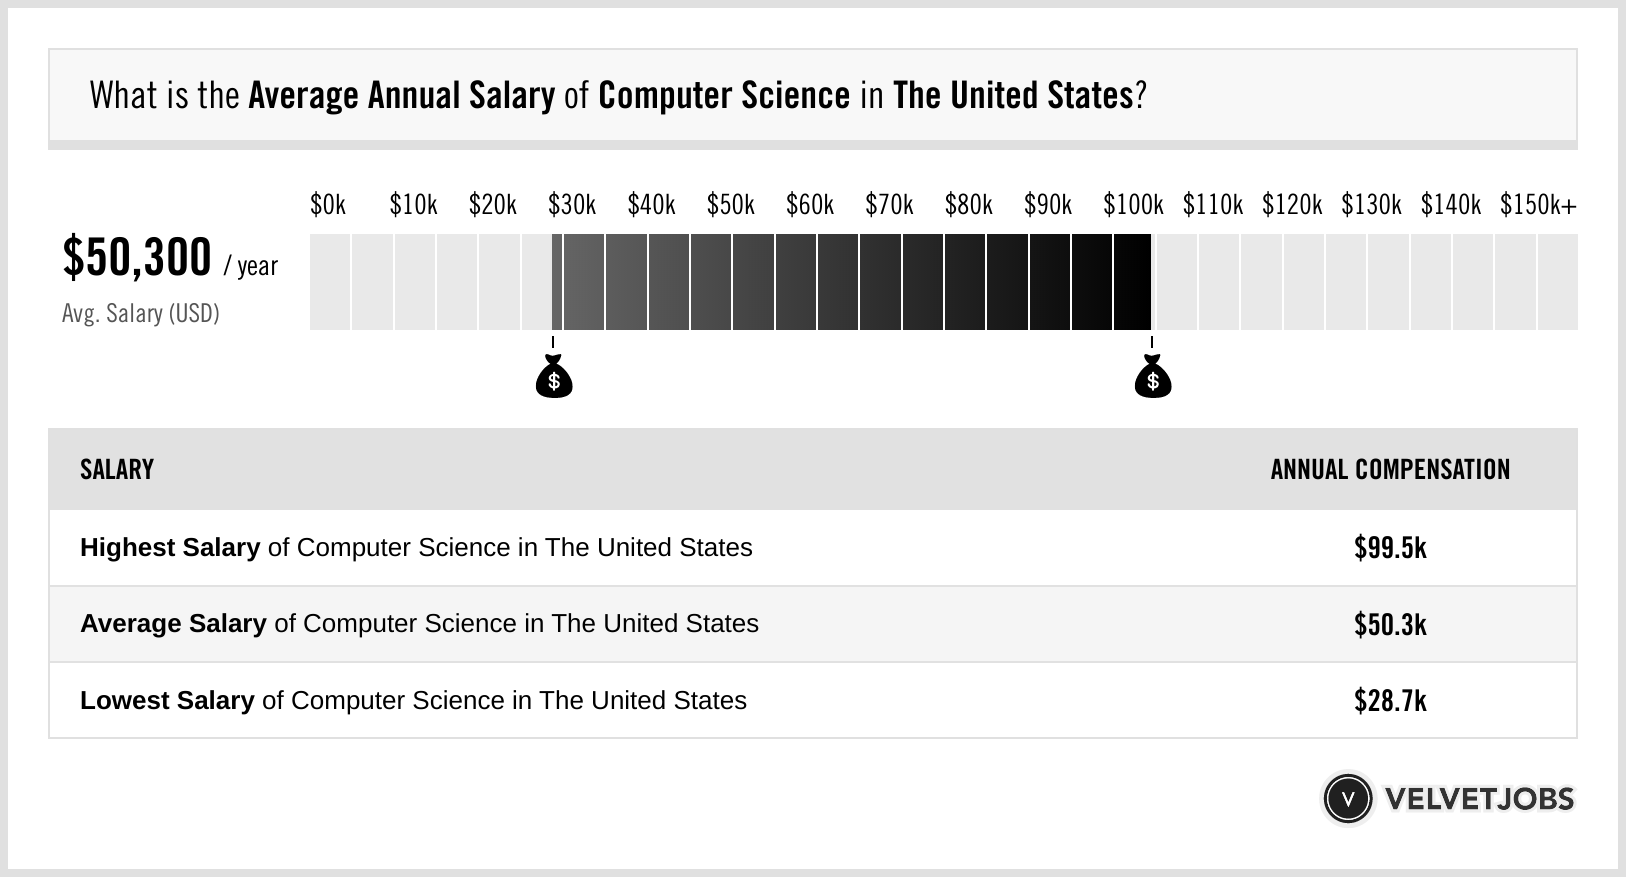
Applied computer science is not a job title. It's a category that spans roles like software engineer, data engineer, ML engineer, DevOps engineer, and systems programmer. That ambiguity is why raw median figures are almost always misleading. A single national median for "applied computer science" might read around 95k to 115k depending on the platform, but that range collapses fast once you separate base salary from total compensation and account for location. Here's what tends to happen in practice. Base salaries for entry-level applied CS roles in the US sit roughly between 70k and 95k outside major tech hubs. In San Francisco, Seattle, or New York, the same roles start closer to 95k to 125k base. Senior roles follow a different curve entirely, where stock and bonuses make up 30 to 50 percent of total comp at established companies, and sometimes more at startups with fresh option packages. I ran into a specific issue recently where a client needed a benchmark for an applied computer science salary report targeting mid-level roles in Austin, Texas. Every public dataset showed Austin salaries about 12 percent below national average, which looked reasonable until I cross-referenced actual posted job offers from local companies. The posted numbers were 8 to 10 percent below the national median, but the actual offers being extended were only 3 to 4 percent below. The gap existed because employers anchor publicly to the lower end and negotiate upward internally. This is a well-known pattern across the industry, but it makes any published median slightly conservative rather than accurate.
The workaround I used was straightforward. I pulled compensation data from three sources, then filtered each one to the exact job titles that map to applied CS work. I excluded pure research roles and academic positions. I excluded general IT support titles that often get lumped into broad searches. I took the 25th, 50th, and 75th percentiles from each source, then averaged those three percentile points across all sources. The resulting range gave a tighter and more realistic band than any single platform would. One counter-intuitive thing most people miss is that title inflation distorts salary data more than you'd expect. Companies post roles as "software engineer" when the actual work is more aligned with applied CS data engineering or backend infrastructure. The compensation ends up similar, but the title mapping skews your search results if you're not filtering by actual responsibilities. I've seen candidates adjust their expectations downward because they compared themselves to a pool that included unrelated job functions. Another pitfall is conflating total compensation with base salary. A job posting that says "130k package" might be 100k base, 15k annual bonus, and 15k in stock vesting over four years. That stock portion isn't liquid and may be worthless if the company is private or performs poorly. When you're negotiating or benchmarking, focus on base plus guaranteed bonus first. Treat equity as a separate conversation.
Get the Full Details

If you're building your own salary model, here's a method that actually works. Pull data from Levels.fyi for tech-forward companies, Glassdoor for broader industry coverage, and the Bureau of Labor Statistics for government-backed median figures. Filter to the specific metro area. Filter to 2 to 7 years of experience for mid-level bands. Then take the median of each dataset and report the spread between the lowest and highest. Don't round aggressively. A range of 88k to 124k means more than "roughly 100k." The main downside of this approach is that it requires manual effort. Automated salary tools promise fast results, but they typically rely on sparse or stale datasets and apply overly broad title mappings. The manual filtering takes about 45 minutes for a single metro area and role band, but the output is defensible and accurate enough to use in real negotiations or budget planning. Another limitation worth noting is that applied computer science salary data ages quickly. Market shifts from hiring freezes, layoffs, and demand changes for specific skills like machine learning or cloud infrastructure can move the numbers noticeably within a single year. Data from early 2023 is not the same as data from mid-2025. Always check the date range of the underlying reports before you cite them.
For people who need this data regularly, the practical alternative to manual pulling is setting up a simple script or spreadsheet that imports CSV exports from the major platforms on a quarterly basis. I built one using Python with pandas that merges the three sources, applies the title and location filters, and outputs a clean percentile table. It takes about five minutes to run each quarter and catches trends faster than you can notice them by eye. The numbers you land on will vary based on how strictly you define applied computer science. Keep your definitions narrow. Your results will be sharper.