Model Reduction with Antoulas's Approach — What Actually Works
If you're working with large-scale dynamical systems — say, finite element discretizations from fluid flow or structural mechanics with state matrices in the millions — you already know that simulating them at full order is impractical for control design, repeated optimization runs, or real-time applications. The Antoulas framework, as laid out in his SIAM monograph Approximation of Large-Scale Dynamical Systems, gives you a fairly clean set of tools. But the theory and the practice have a gap worth noting. At the core of Antoulas's approach is projection-based model reduction. You take a high-dimensional state-space system, project it onto a much lower-dimensional subspace, and get a reduced-order model that preserves key input-output behavior. The two main threads are balanced truncation and moment-matching via Krylov methods. He ties them together through the structure of the Hankel operator and singular values — the Hankel singular values tell you which states actually matter for the input-output map, and which you can safely discard. The practical workflow goes something like this. You start with a linear time-invariant system in the form dx/dt = Ax + Bu, y = Cx. You compute a factorization — either a balanced realization where the controllability and observability Gramians are equal and diagonal, or you build Krylov subspaces from the resolvent (sI - A)^{-1} at chosen expansion points. Then you truncate or project. The result should approximate the original transfer function H(s) = C(sI - A)^{-1}B in some norm, typically H-infinity or Hankel norm.
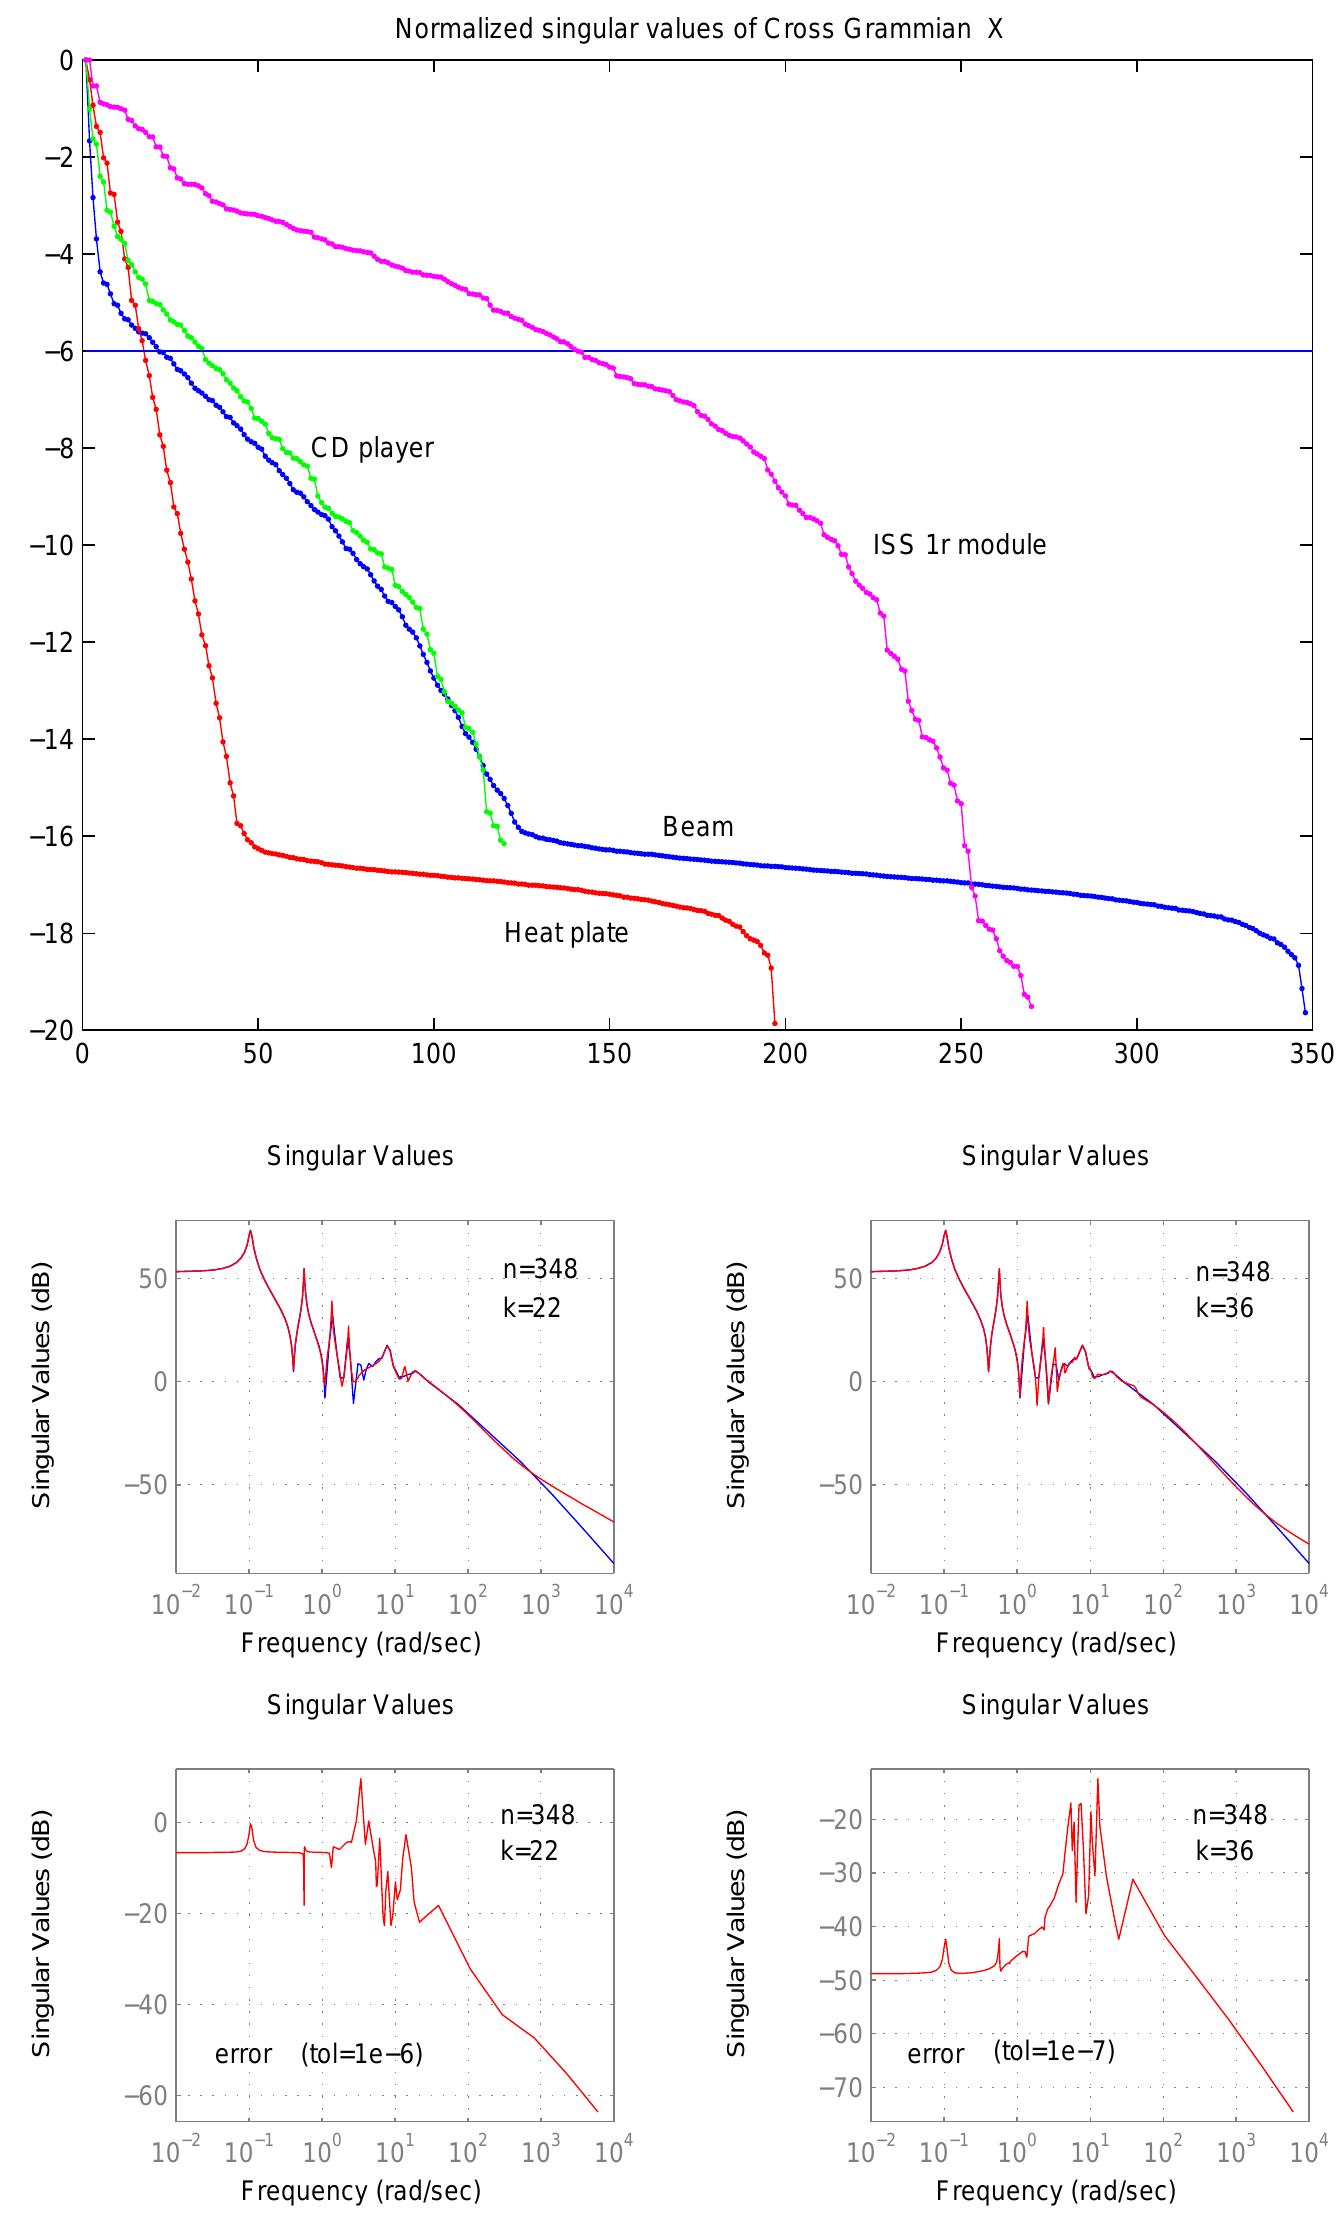
Here is where people run into trouble. Computing the full Gramians for a system with even a few hundred thousand states is basically impossible. The Lyapunov equations A X_c + X_c A^T + BB^T = 0 and A^T X_o + X_o A + C^T C = 0 require dense matrix operations that blow up in memory. Antoulas's book covers low-rank approaches and iterative solvers, but in practice you need to be selective. I spent about three weeks last year trying to reduce a 2.1-million-state model from a heat transfer simulation. The balanced truncation route was completely out — the Gramian factorization would have needed roughly 4 terabytes of RAM to store intermediate results, and the compute time was estimated in the hundreds of hours even on a decent cluster. What actually worked was the alternating minimal energy algorithm, sometimes called AltMin, which Antoulas and his coauthors developed. Instead of computing full Gramians, it iteratively refines low-rank factors of the controllability and observability Gramians. For my system, it converged in about 40 iterations and gave me a rank-800 factorization that was good enough to build a reduced model of order 600. The H-infinity error between the full and reduced transfer functions stayed under 2 percent across the frequency range that mattered for the controller I was designing. There are a few counter-intuitive things about this that aren't always obvious from the textbook treatment. First, balanced truncation does not always give you the best possible reduced model in the H-infinity sense. It guarantees a bound on the error — the sum of the neglected Hankel singular values — but the actual error can be much larger than that bound in practice. The bound is worst-case and often loose. If you need tight error bounds, moment matching with IRKA (Iterative Rational Krylov Algorithm) tends to perform better, even though it doesn't come with the same clean theoretical guarantee.
Second, the choice of expansion points in Krylov-based methods matters enormously. Picking them by hand using intuition about dominant poles is fragile. IRKA automates this by iteratively updating the expansion points to be the negative complex conjugates of the poles of the current reduced model. It usually converges in five to ten iterations, but if your system has clustered poles or a wide spread of time scales, it can stall or converge to a local minimum that is nowhere near optimal. I've seen cases where manually placing a handful of expansion points near the dominant dynamics, then running IRKA from that seed, produced a significantly better result than running IRKA cold from randomly chosen points. The MATLAB implementations you'll find are available through the LROM toolbox and the IRKA code that Antoulas and others have released. You can also look at the Model Reduction Toolbox for MATLAB. Neither of these handles systems larger than a few hundred thousand states without some heavy customization, so if your model is truly large-scale, you're probably looking at parallel or distributed implementations, or you're working with structure-preserving reductions that exploit sparsity. A limitation that isn't talked about enough: these methods assume your system is linear and time-invariant. If you have nonlinear dynamics, you need to either linearize around an operating point — which is fine if the system stays near that point — or use something like nonlinear balanced realization, which is far less mature and far more computationally expensive. I tried applying balanced truncation to a linearized Navier-Stokes model at one Reynolds number and then using the reduced model at a significantly different Reynolds number. The reduced model drifted into instability within a few seconds of simulation time because the linearization was only valid in a narrow region. That's not a failure of the reduction method itself; it's a failure of the underlying assumption that the system is LTI.
Get the Full Details

Another practical note: if your system has multiple inputs and outputs, the computational cost grows with the product of input and output dimensions in the Gramian computation. A SISO system is easy. An MIMO system with 50 inputs and 50 outputs is materially harder. The contour integral methods and randomization techniques that have emerged since Antoulas's book was published help here, but they add their own complexity to the pipeline. If you're just getting started, I'd recommend working through a small example first — something like a 1D diffusion equation discretized with 1,000 finite elements, giving you a 1,000-state system. Use the standard IRKA implementation and watch how the Hankel singular values decay. If they decay rapidly, which they usually do for well-behaved PDE discretizations, you can get an order-50 model that captures 99 percent of the input-output behavior. Then scale up and see where the bottlenecks appear. That's faster than diving straight into a million-state problem and hitting a wall. The book itself is dense and mathematical. It's more of a reference than a hands-on tutorial. The papers by Antoulas, Beattie, Gugercin, and Mehrmann that came out after the book was published in 2005 are where you'll find the practical algorithms. Look especially at the 2017 paper on the alternating minimal energy algorithm and the various IRKA variants. They fill in the gaps that the monograph leaves open.