Understanding Derivative Classification in Practice
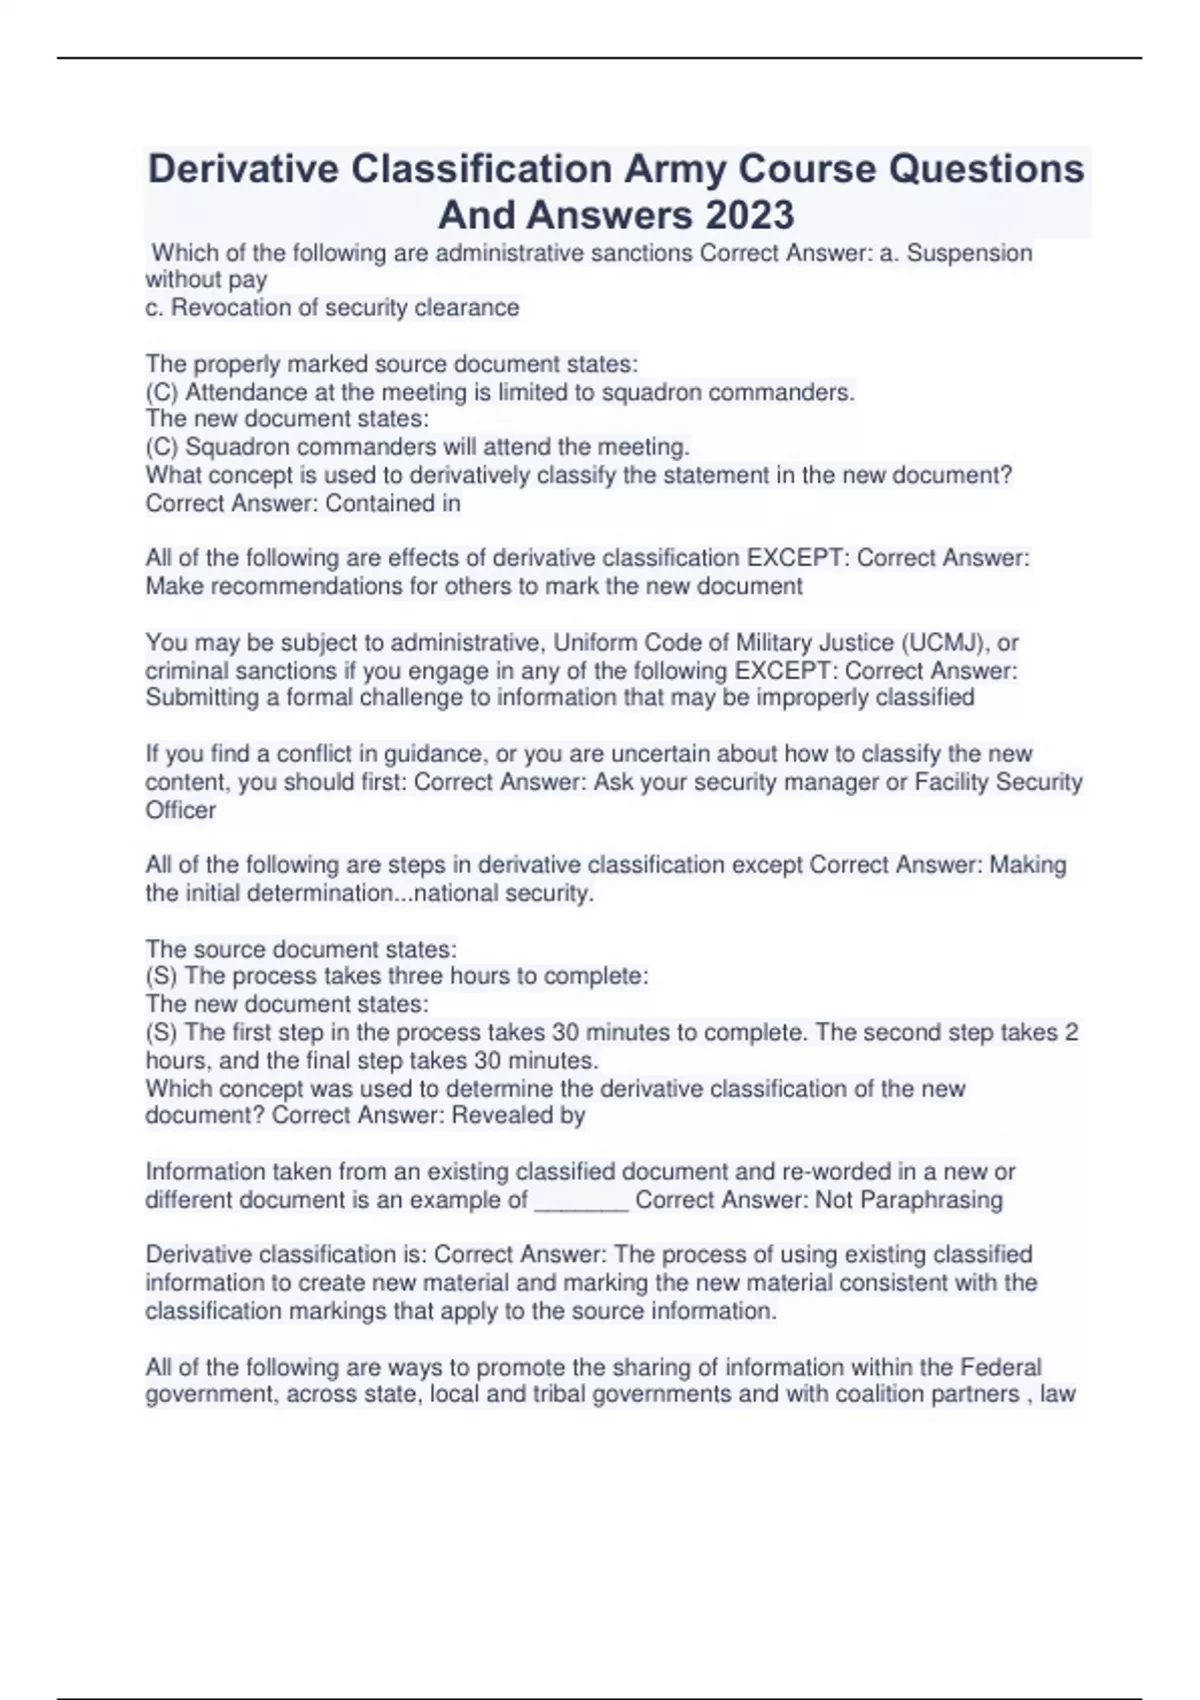
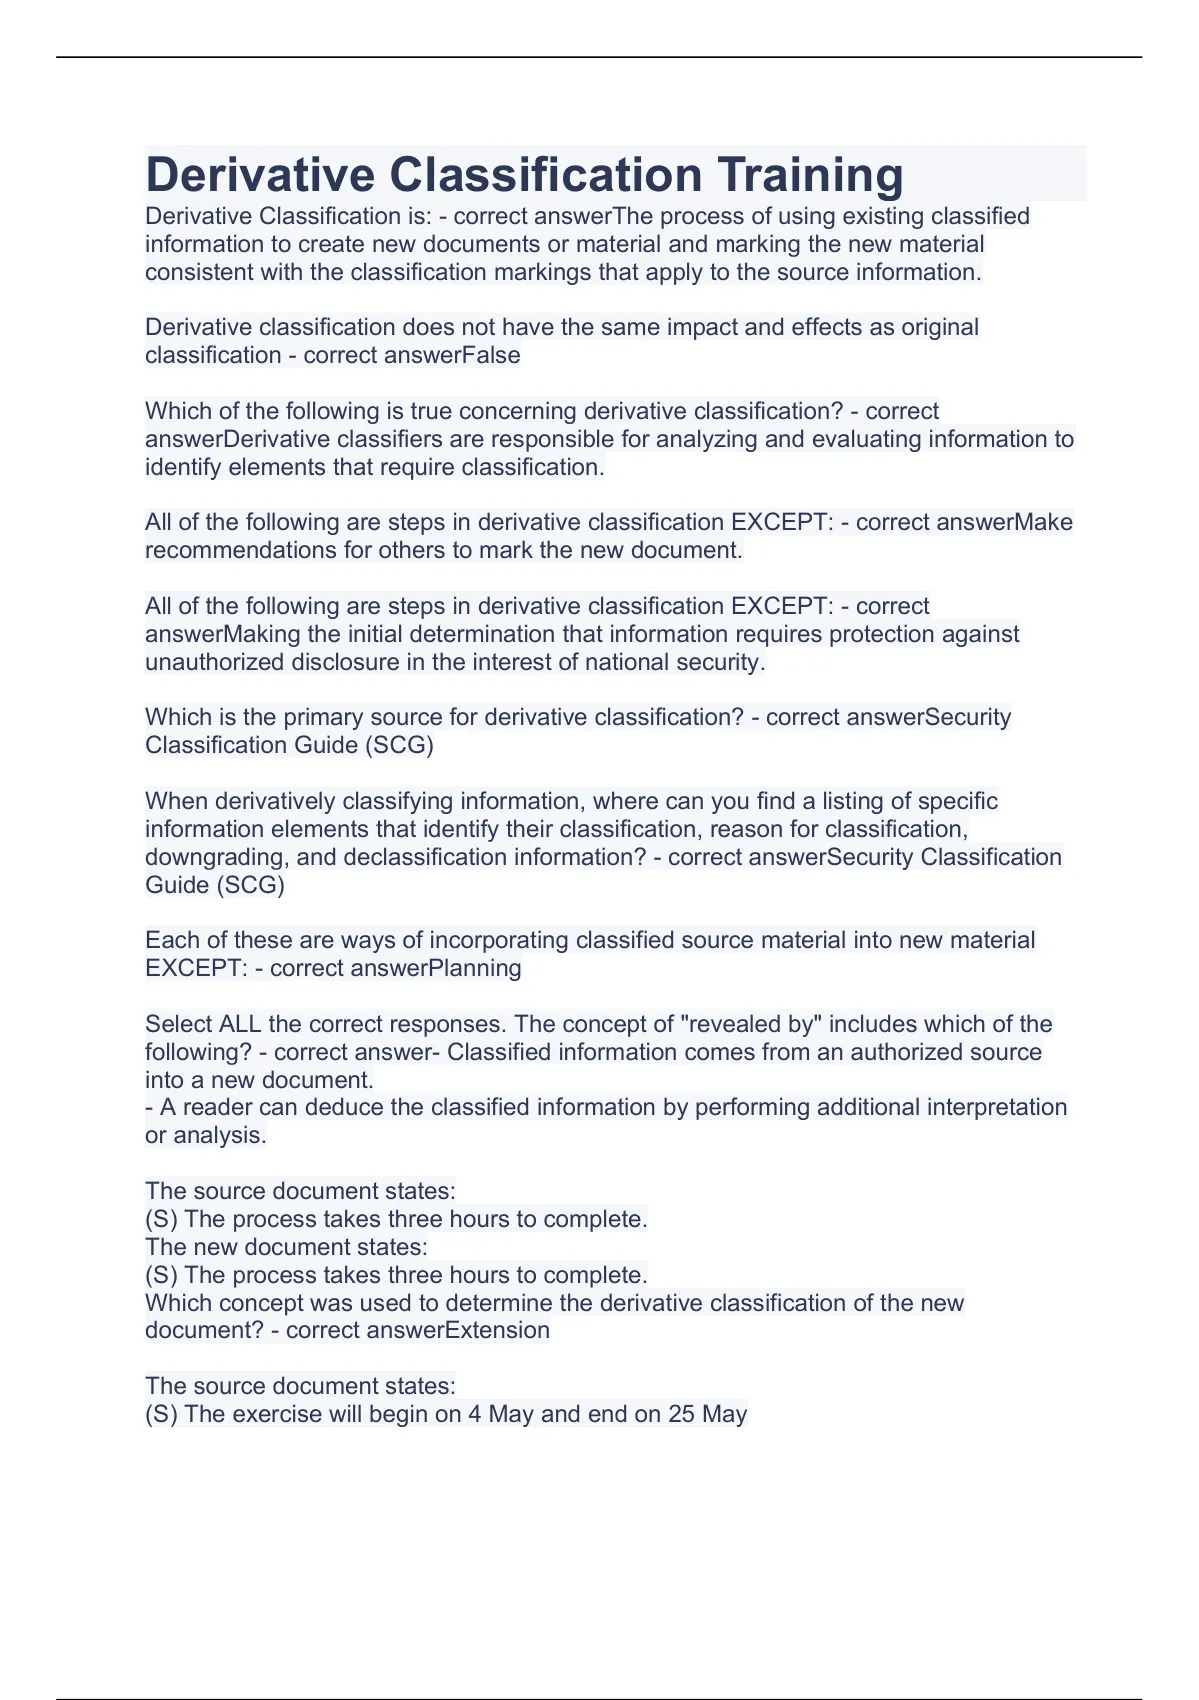
Most people encounter derivative classification when they are pulling together a brief, a report, or a slide deck and realize they need to mark something without having originated the classified information. It happens constantly in government contracting, defense research, and any environment where unclassified work touches classified source material. The process is straightforward in theory and annoying in execution. The training program you need is called the Army Derivative Classification Training, available through the Army Training Management and Planning System or directly via the Joint Video Teleconference network. It is roughly 90 minutes long, self-paced, and covers the basics of when you must classify, how to assign classification levels, and the markings you apply. You do not need a special security clearance to take it, but completing it is usually a prerequisite before you can be authorized to handle classified material in a work capacity. The real work starts after you pass the module. Derivative classification means taking source material that already carries a classification level and incorporating that information into a new document. You do not guess. You follow the source. The classification level of the new document is determined by the highest-level information you include, not by your own opinion of how sensitive the topic might be.
Here is where people get tripped up. The source citation has to be explicit. If you pull a paragraph from a classified memo and paste it into your briefing without writing out the classification source statement, the document is technically unclassifiable in a formal review, and whoever produced it gets a referral. I have seen entire packages sent back because someone wrote "CLASSIFIED SOURCE" as the citation instead of providing the actual document title, classification level, and source marking. A specific edge-case I ran into involved a technical report that referenced data from a classified contract deliverable. The deliverable had a SECRET classification but also carried a control marking that limited redistribution under a specific agency directive. I initially classified the derivative document at SECRET with a standard classification source statement, and then realized the control marking meant I needed to add the relevant control designation to the derivative document as well. The training module does not cover control markings in detail. I had to pull the DoD 5200.01-R manual and cross-reference the specific control marking provisions myself. The workaround was to attach the control marking directly below the classification level in the marking block and add a footnote in the document explaining the basis for the restriction. Another thing the training glosses over is the difference between derivative classification and original classification. Original classification is when someone with the authority makes the initial decision to classify information. That requires formal delegation under Executive Order 13526. Derivative classification has none of that authority requirement. You are just following instructions from existing sources. The moment you start making classification decisions that go beyond what the source material says, you are no longer doing derivative classification. You are doing original classification, which you likely are not authorized to do.
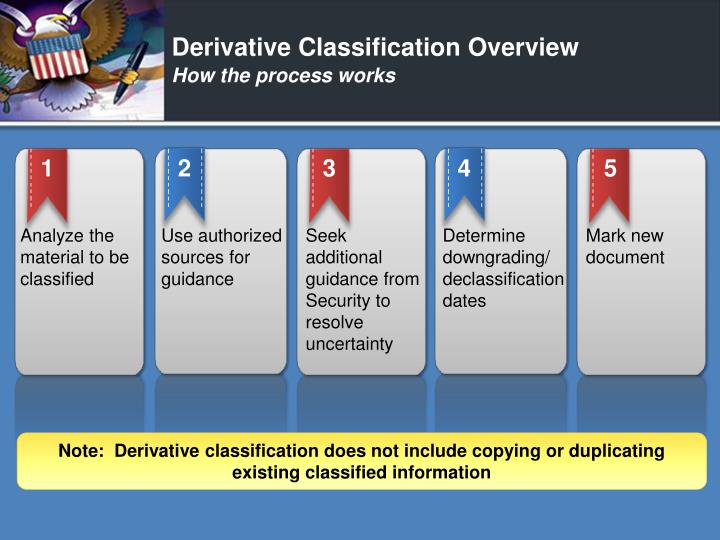
The classification decision process itself follows a specific sequence. You identify the source, determine the classification level of the source information, apply the appropriate classification markings, and then verify that all required marking elements are present. The required elements include the classification level, the classification authority, the declassification date or event, and the downgrade guidance if applicable. Leave one of those out and the document is marked improperly, which is just as bad as misclassifying it in the first place. There is also the issue of derivative classification in digital environments. If you are working in a system like the Army's Automated Work Control System or a shared drive with classified content, the classification markings do not always carry over properly when you copy and paste. I have seen documents where the body text was properly marked but the header and footer were left blank because the source template did not include them. In those cases you manually insert the marking block at the top and bottom of every page. It takes about five minutes per document and prevents a marking deficiency on review. The training also mentions the concept of compartmentation, but does not spend enough time on it. Compartmentation is separate from classification level. Information can be SECRET and still be in different compartments with different access requirements. Derivative classification does not automatically grant access to compartments. If your source material comes from a specific compartment, you need to note that in your classification source statement and ensure the recipient has the appropriate compartment access before releasing the document.
Get the Full Details

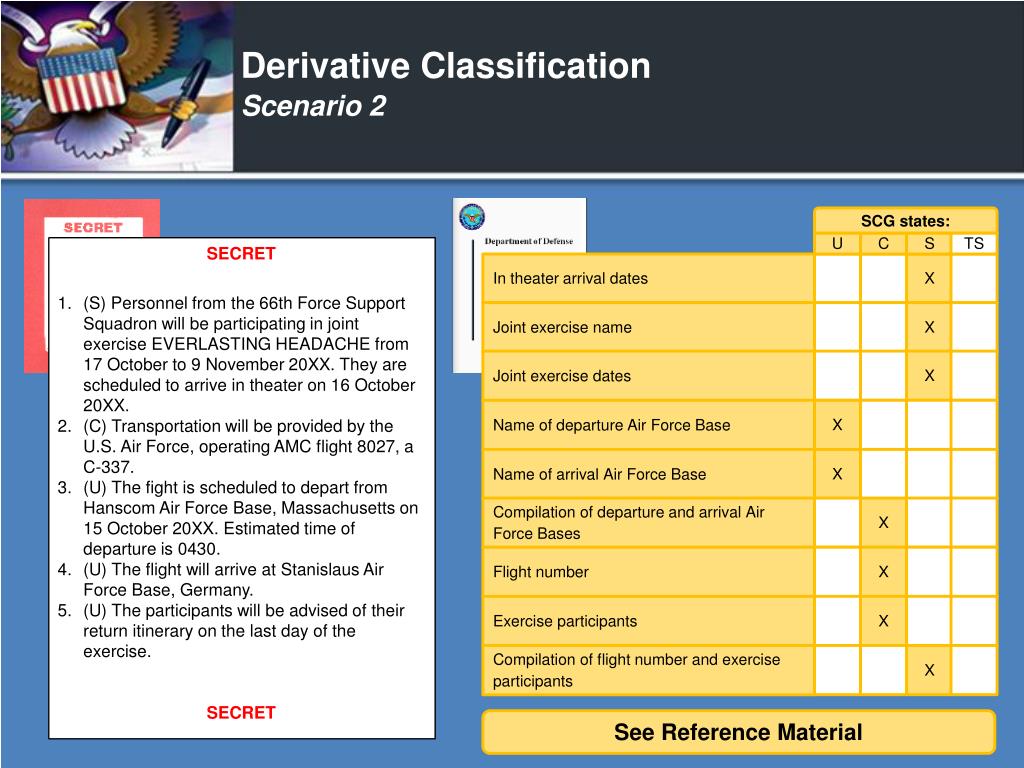
One counter-intuitive point that people miss is that derivative classification can actually raise the classification level of a document even if no single piece of source information is highly classified. This is called aggregation. Two or more pieces of LOW CONFIDENTIAL information, when combined, can reveal something that warrants SECRET classification. The training mentions this but the examples are thin. In practice, you have to be careful when compiling multiple lower-level sources because the aggregate effect can trigger a higher classification than any individual source. Declassification is the other side of the equation. Derivative information retains the declassification date of the source. If the source is marked to declassify on a specific date, your derivative document inherits that same date. If the source does not have a specific date and instead uses automatic declassification under section 3.3 of Executive Order 13526, you apply the automatic declassification rules based on the classification level. A SECRET document with automatic declassification declassifies ten years from the date of origin. That means you need to track the origin date of your source material carefully, not just the publication date. The main bottleneck in derivative classification is sourcing. When you cannot locate the original classification source, you cannot properly derivative classify. This happens more often than you would think. Contractors often work from legacy documents where the original classification authority has left the organization, or the source document has been redacted so heavily that the classification markings are incomplete. In those situations, you cannot guess. You must contact the originating organization or the designated classification authority for a ruling. There is no shortcut. Attempting to classify without a source is a violation.
Another practical limitation is that derivative classification training is not a one-time requirement in most Army contexts. Refresher training is typically required every two years, and some commands mandate annual updates. The online module has not changed substantively in years, which means the training can feel disconnected from the actual problems you face. The gaps between what the training covers and what you encounter in daily work are where mistakes happen. If you need to take the training, the primary avenue is through the Defense Technical Information Center portal or your command's training office. The DTIC course catalog lists it under the information assurance and security training section. You can also find related materials through the Information Security Policy Division website, though that is more reference material than formal training. Some commands run live sessions through JVN that include Q and A, which is significantly more useful than the self-paced online version because you can ask about specific scenarios. The documentation you should keep alongside your training record includes your certificate of completion, a copy of the classification source statements you used on your most complex derivative documents, and any correspondence with the classification authority where you requested guidance on ambiguous sources. That last piece is important because it creates a paper trail showing that you attempted to follow proper procedure when the source material was unclear.
For anyone doing this work regularly, the practical takeaway is that derivative classification is mostly about documentation discipline rather than technical knowledge. The rules are simple. The hard part is making sure every piece of incorporated information has a proper source citation, that the marking blocks are complete on every page, and that you are not inadvertently aggregating information into a higher classification level without recognizing it. The training gets you to the starting line. The rest is attention to detail.