Why This Textbook Still Shows Up on Every AI Syllabus
Artificial Intelligence by Elaine Rich and Kevin Knight is a dense, reference-heavy book that covers more territory than most single volumes should. It was originally written for undergraduate and graduate courses, but the way it structures material makes it useful differently than a casual read. I picked it up years ago looking for a quick refresher on search algorithms and spent three weekends going through chapters I already thought I understood. The book doesn't hold your hand. That is by design. Rich and Knight organize content around problem spaces, state representations, and algorithmic guarantees rather than building intuition first. You will find yourself re-reading sections on production systems or first-order logic multiple times before something clicks. This is normal. It happens to everyone who uses this as a primary reference.
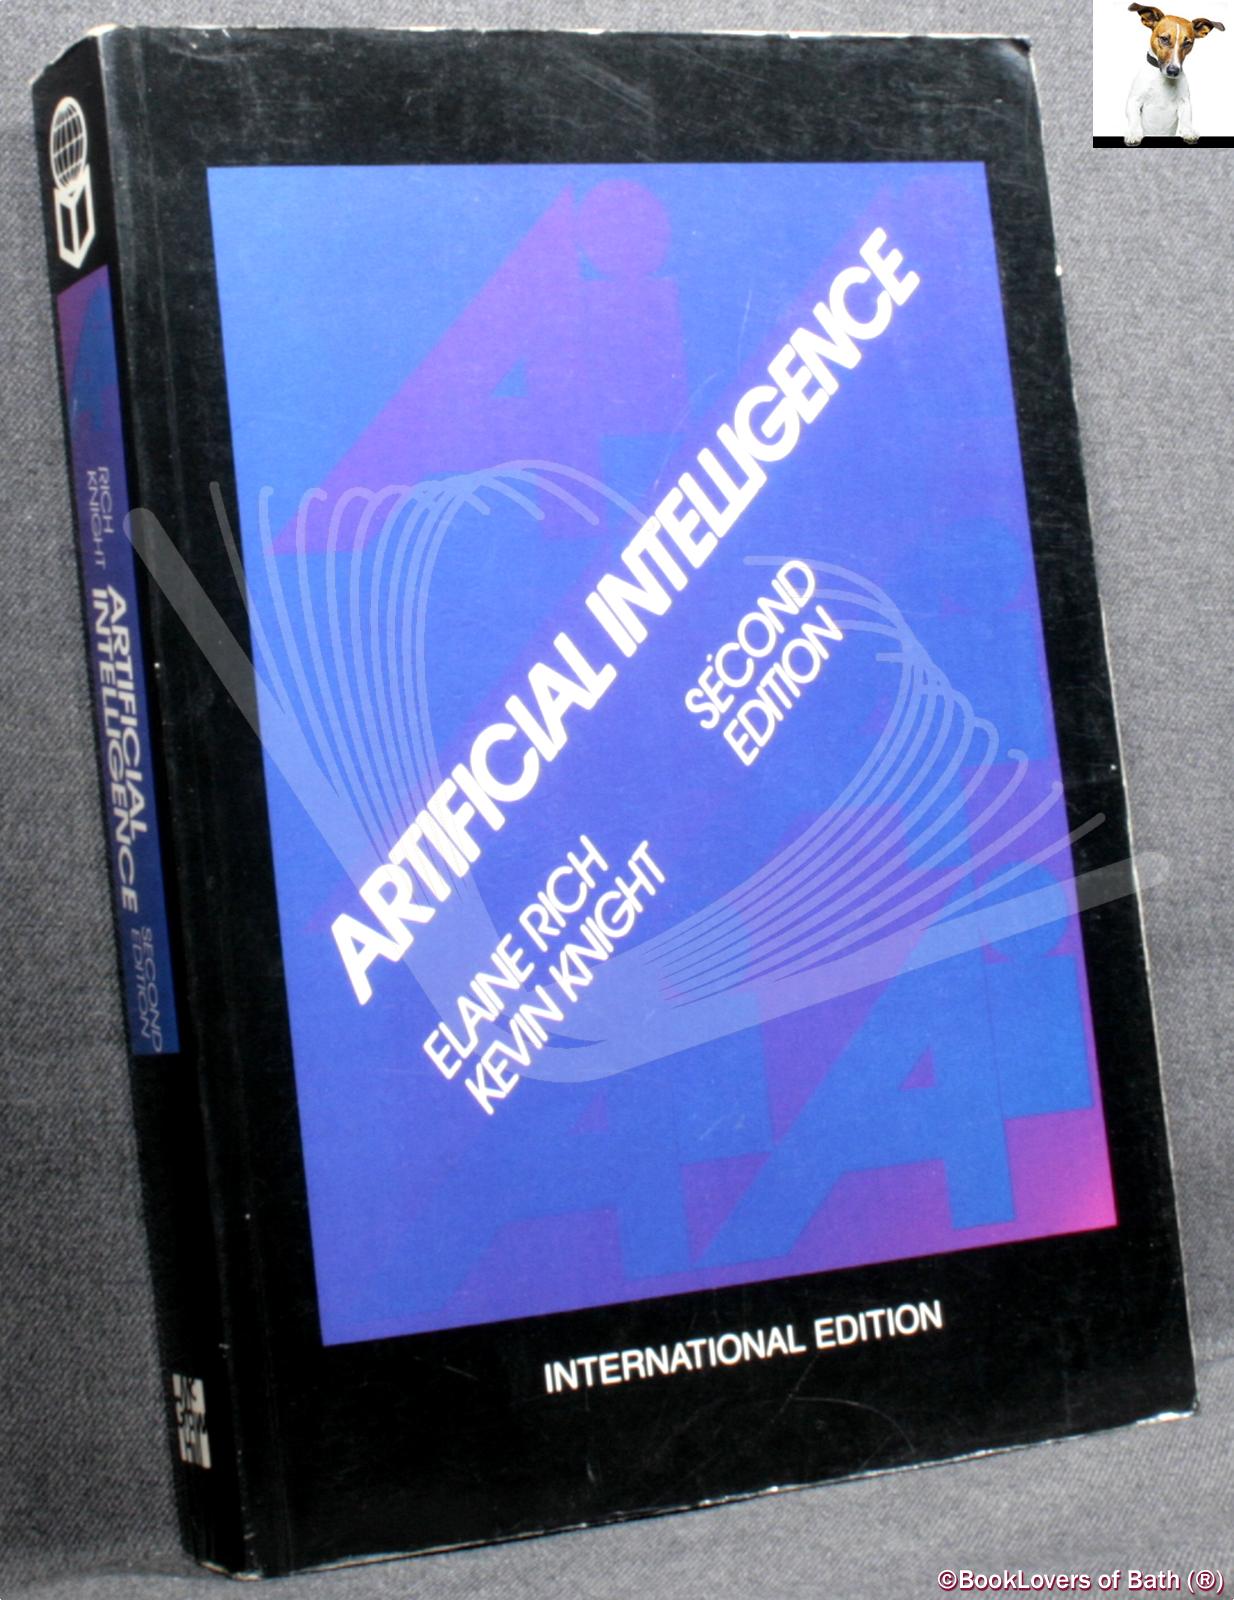
Artificial Intelligence Elaine Rich Kevin Knight
The third edition, which is the one most people end up with, splits the material into distinct domains. Search and constraint satisfaction occupy the early chapters. Knowledge representation and reasoning move into predicate logic, description logics, and ontologies. Machine learning gets a section but it is comparatively light relative to dedicated ML textbooks. The planning and probabilistic reasoning chapters are where the book tends to shine. What makes this text different from newer AI books is its emphasis on classical approaches. Neural networks and deep learning are not central here. If you are looking for a modern transformer tutorial, this is not the book. What you get instead is a thorough grounding in symbol manipulation, theorem proving, and state-space search. That foundation matters if you ever need to debug why a rule-based system behaves unpredictably or understand the assumptions behind knowledge graph reasoning.
How to Actually Use This Book Without Losing Your Mind
Reading cover to cover is inefficient. The chapters are long and the examples range from simple to abstract without much scaffolding. I found it more effective to treat the book as a lookup resource paired with targeted study sessions. Pick one topic, work through the examples on paper, then check your understanding against the end-of-chapter exercises. The exercises are where the actual learning happens. For search algorithms, start with Chapter 3. Work through breadth-first search, uniform cost search, and A* until you can derive the admissibility condition from memory. The pseudocode in the book is dense but accurate. Write it out yourself. When you actually type or handwrite the algorithms, the differences between informed and uninformed search become clear in a way that skimming never achieves. The logic chapters, particularly around resolution and unification, are where most students stall. I encountered this myself when working on a small theorem proving project. The textbook explains the unification algorithm well, but the worked examples skip steps that turn out to be critical. I got stuck trying to unify expressions with overlapping variables across nested terms. The workaround was to trace the occurs check manually on scratch paper using a substitution mapping table. It added time initially but eliminated hours of confusion later.
Get the Full Details
What the Book Gets Right
The treatment of production systems and forward versus backward chaining is still one of the clearest explanations available in any single source. The distinction between data-driven and goal-driven inference is laid out without unnecessary abstraction. If you have ever tried to explain why a particular expert system chose one rule over another, this chapter gives you the vocabulary to do it precisely. The coverage of constraint satisfaction problems deserves attention too. The book walks through arc consistency, backtracking with heuristics, and minimal remaining value ordering in a sequence that mirrors how you would actually implement a solver. The examples use concrete domains like map coloring and scheduling. You can implement these directly after reading. Prompt logic and description logics get less coverage than they probably deserve, but the treatment of Horn clauses and definite clauses is sufficient for understanding the foundations of Prolog-style systems. This matters more now than it used to because modern knowledge-based systems still rest on these representation choices, even when wrapped in neural interfaces.
Where the Book Falls Short
The machine learning sections are the weakest part. They cover perceptrons, decision trees, and basic Bayesian networks but skip gradient-based methods entirely. If your goal is to understand backpropagation or reinforcement learning, you will need supplementary material. The probabilistic reasoning chapters are better but still assume a comfort level with conditional probability that not every reader brings to the text. Another limitation is the age of the editions in circulation. The third edition predates the deep learning boom. References to connectionist approaches feel dated. You will not find coverage of attention mechanisms, graph neural networks, or large language models here. The classical AI framework is solid, but the field has moved significantly. Treat this book as covering the architecture of intelligence rather than its current frontier implementations. The exercise solutions are not included in the book itself. You will need to seek out instructor resources or work through problems without verification. This can slow your progress, especially when debugging an implementation that behaves incorrectly. I recommend pairing this text with online lecture notes that walk through selected problem solutions. Stanford and MIT have archives that complement the material well.
Who Should Read This and How
If you are entering AI research or engineering and need to understand what comes before neural networks, this book is worth the effort. It teaches you to think about problems as state spaces, to represent knowledge explicitly, and to reason about algorithmic correctness. Those skills transfer even when the specific techniques become outdated. Casual readers may find the pacing harsh. The authors assume mathematical maturity and logical reasoning comfort. If you encounter notation you do not recognize, pause and look it up rather than pushing forward. The book rewards careful reading but punishes skimming. I keep a copy on my desk primarily for the search and logic chapters. When I need to explain to a colleague why a certain optimization strategy fails on a specific class of problems, Rich and Knight's treatment of heuristic design and local optimality gives me a reliable framework. That is the practical value of this text. It is not entertainment. It is reference material that compounds in usefulness the more often you return to it with fresh context.