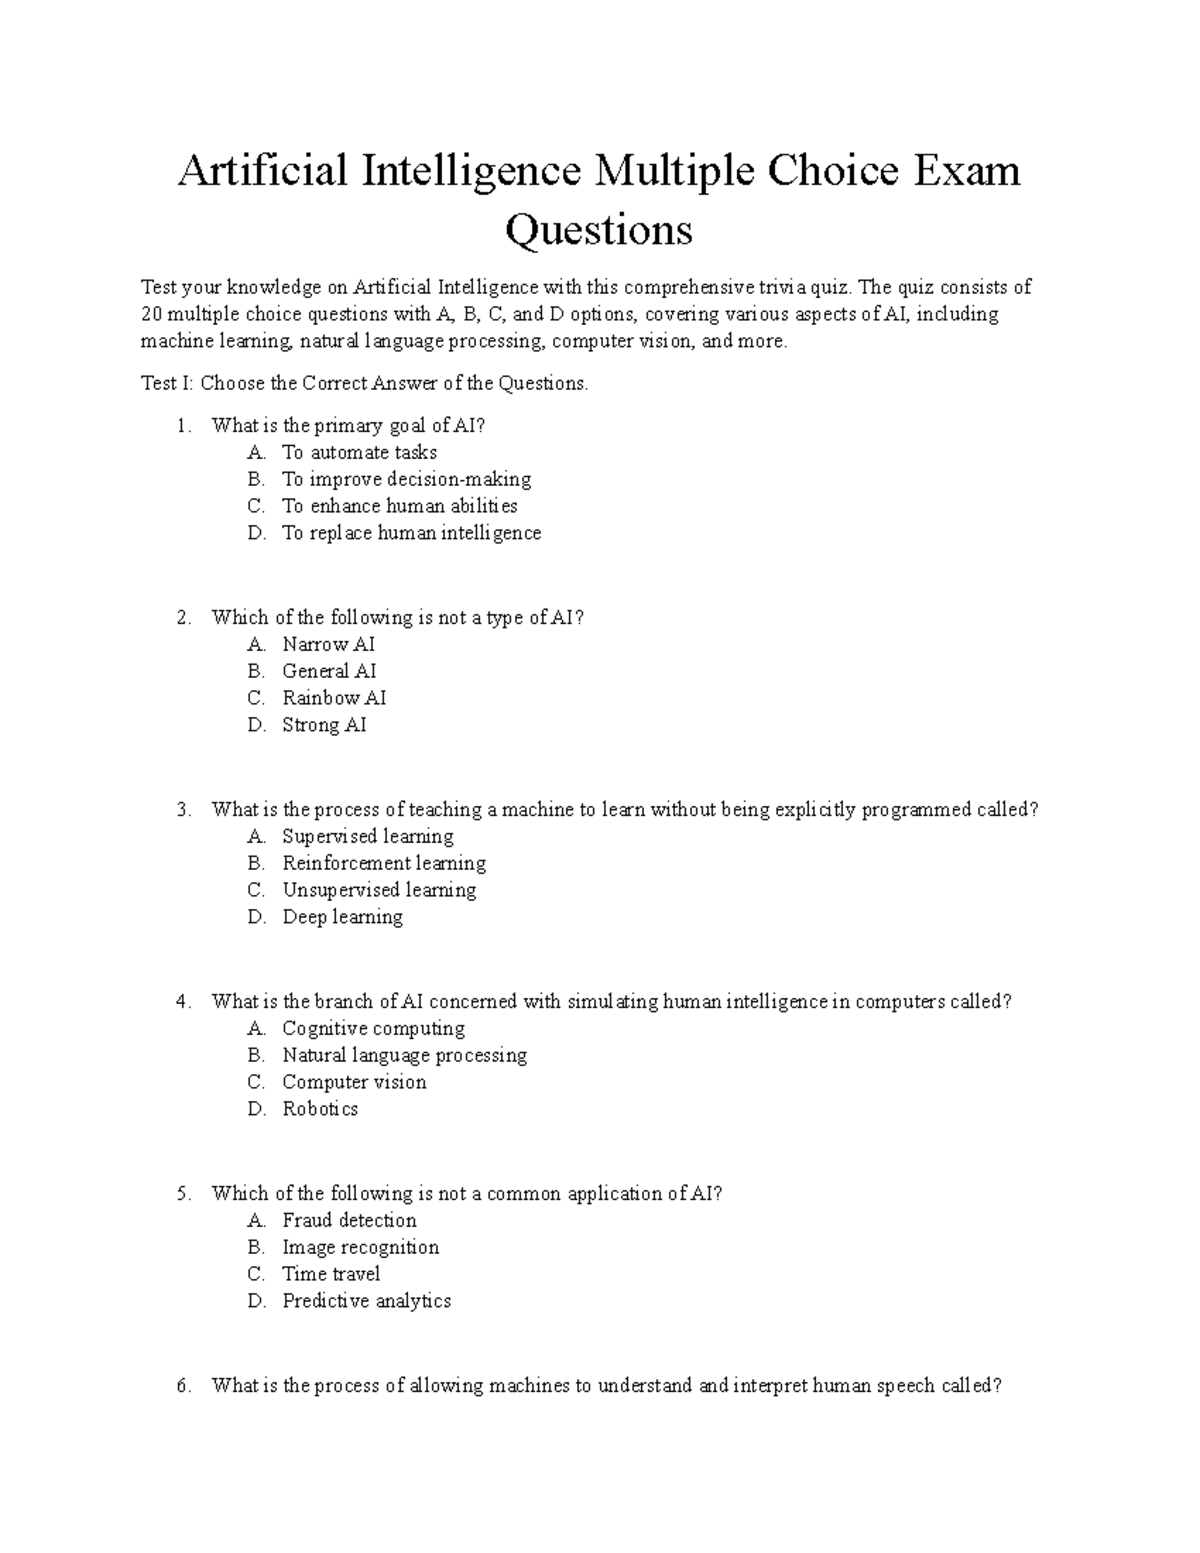
Preparing for an AI exam is less about memorization and more about understanding how these systems actually fail
I spent three years proctoring and writing exams for university-level artificial intelligence courses before I stopped caring about curve grades and just wanted students to survive the industry. The questions that show up on real exams — especially the ones used by tech companies for hiring — tend to follow patterns that don't always reflect what you'd do on the job. That's the first thing you need to accept before you start studying. Most AI exam questions fall into three buckets: theoretical knowledge about algorithms and their trade-offs, mathematical derivations involving probability and linear algebra, and applied problems where you have to design or debug a system. The theoretical ones are straightforward if you've read the material. The math ones trip people up because they test whether you can manipulate equations under time pressure, not whether you understand the concept. The applied ones are the only ones that matter after the exam is over.
Common Artificial Intelligence Exam Questions and How to Approach Them
Let me walk through some of the question types you'll actually encounter and what they're really testing. Bayesian reasoning questions show up constantly. You'll get a problem like: "A test for a disease has 95% sensitivity and 90% specificity. The disease prevalence is 1%. What is the probability that a person who tests positive actually has the disease?" The answer is approximately 8.7%, not 95%. Most students write 95% because they confuse sensitivity with positive predictive value. The exam is testing whether you understand base rate neglect and can apply Bayes' theorem correctly. Write out the full formula before plugging in numbers. Show P(Disease|Positive) = P(Positive|Disease) × P(Disease) / P(Positive). That alone gets you partial credit even if your arithmetic is wrong. Search algorithm comparisons are another staple. You'll be asked to compare BFS, DFS, uniform cost search, A*, and iterative deepening across dimensions like completeness, optimality, time complexity, and space complexity. The trick is that no single algorithm is best across all criteria. A* is optimal and complete given an admissible heuristic, but it requires O(b^d) space. DFS uses minimal memory but isn't complete in infinite-depth spaces. When they ask which algorithm to use for a specific scenario, the answer always depends on the constraints. If memory is limited and the tree is shallow, DFS or iterative deepening wins. If you need the shortest path and have memory, A* is your answer. I've seen candidates lose points for saying A* is "the best algorithm" without qualifying the conditions.
Machine learning overfitting questions tend to be subtle. A typical question will describe a neural network with high training accuracy but low validation accuracy and ask what's happening and how to fix it. The expected answer involves overfitting, regularization techniques like dropout or L2 penalties, and possibly early stopping. But here's what most exam guides miss: sometimes the problem isn't overfitting at all. It could be a data leakage issue in your training split, or a distribution shift between training and validation sets. During one exam I wrote, the correct answer was that the validation set was accidentally drawn from a different population than the training set, making the low validation accuracy a preprocessing problem, not a model capacity problem. Students who only memorized "overfitting = regularization" scored poorly on that question. Gradient descent variants generate a lot of questions. You'll compare vanilla SGD, momentum, RMSprop, and Adam. You need to know that Adam combines the benefits of both RMSprop and momentum but isn't always the best choice. In practice, I've found that for certain reinforcement learning problems, plain SGD with a good learning rate schedule outperforms Adam. Exams rarely test this nuance though. They want you to know Adam's update rules and why it was developed. Memorize the equations. Know that Adam maintains first and second moment estimates of the gradients with exponential moving averages. Probability and statistics questions are where students who skipped math prerequisites fall apart. Expect questions on conditional independence, Markov blankets in Bayesian networks, and the naive Bayes classifier assumption. A deceptively simple question might ask: "Why does naive Bayes work well in practice despite the strong independence assumption being almost never true?" The answer involves the fact that classification decisions depend on relative probabilities, not absolute values, and the independence assumption often preserves the correct ranking even when the probabilities themselves are inaccurate. This came up in a 2019 Google ML engineer interview exam and caught out half the candidates who had only studied the textbook definition without understanding the intuition.
Get the Full Details
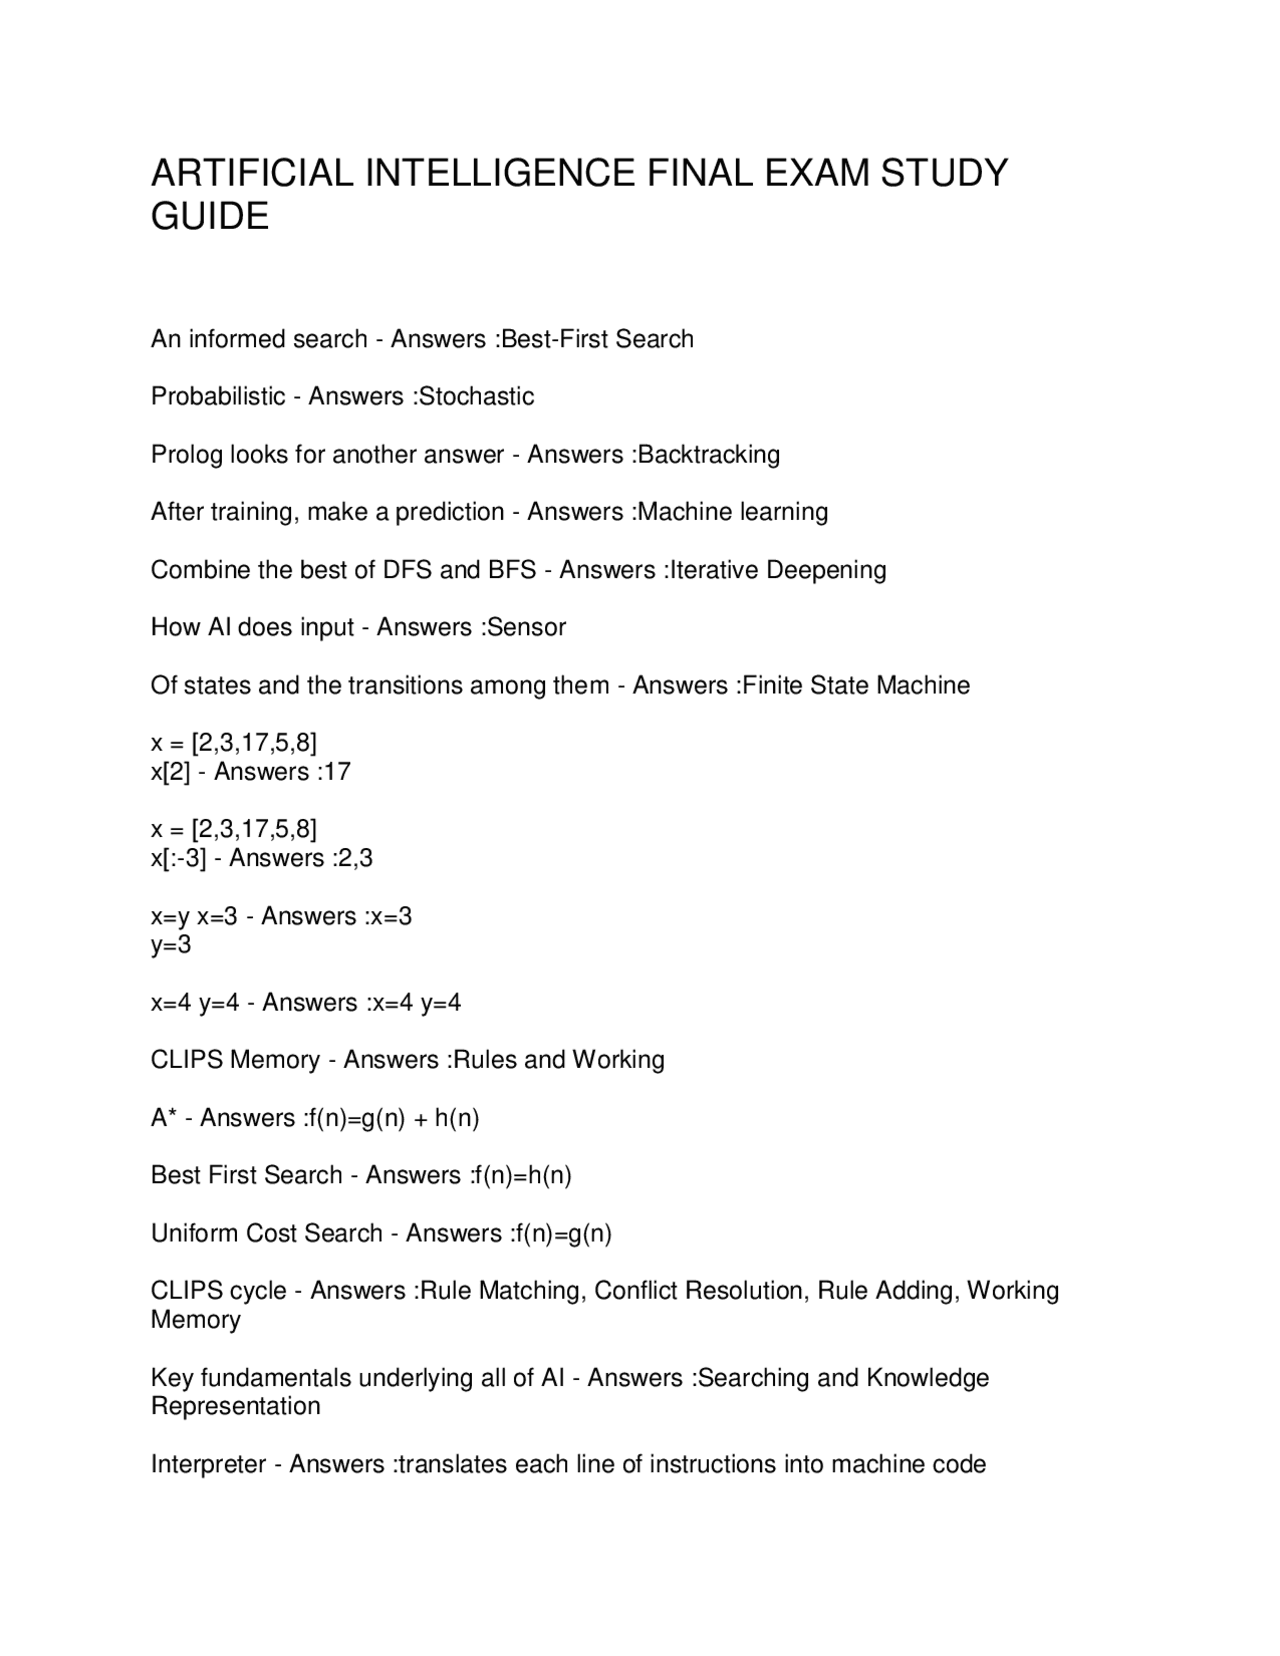
For deep learning architecture questions, you need to understand why specific design choices exist. Why does ReLU work better than sigmoid in hidden layers? Because sigmoid saturates and causes vanishing gradients. Why do residual connections help? They provide gradient highways that allow training of very deep networks. Why use batch normalization? It reduces internal covariate shift and allows higher learning rates. These seem like trivia, but they're the foundation for the applied questions that follow. One practical tip that isn't in any study guide: when you encounter a question about an algorithm you've never seen, don't panic. These questions are almost always designed to test whether you can apply first principles rather than recall facts. If they ask about a novel optimization method, the answer usually involves reasoning from the basics of gradient descent and the specific problem the method claims to solve. Show your reasoning steps clearly even if you're unsure of the final answer. Partial credit is substantial on these exams. The material I recommend for preparation varies by exam type. For academic exams, Russell and Norvig's "Artificial Intelligence: A Modern Approach" covers the breadth, though it's dense. For applied ML exams, "Pattern Recognition and Machine Learning" by Bishop is better for the mathematical depth. For technical interview-style exams, "Deep Learning" by Goodfellow, Bengio, and Courville is essential, especially the chapters on regularization and optimization. Practice under timed conditions. The difference between knowing the material and performing well on an exam is often just the ability to work quickly under pressure.
If you're preparing for a specific certification or company exam, find actual past questions if possible. The patterns are consistent within each organization. Amazon's ML exams emphasize practical deployment scenarios. Meta's focus heavily on recommendation systems and large-scale training. Academic programs vary by professor but consistently test fundamentals heavily. Spend more time on the fundamentals than on the latest papers. The exam won't ask about the most recent transformer variant, but it will absolutely ask whether you understand attention mechanisms at a mathematical level. I've watched people pass these exams with minimal preparation and others fail despite strong practical experience. The gap usually comes down to one thing: whether they've practiced translating their knowledge into the specific format these exams expect. Real work involves iteration and tooling. Exams involve constrained problem-solving with limited information. Adjust your study approach accordingly and you'll likely score higher than most people who just read through the material once.