Why Most People Get Artificial Intelligence Programming Language Wrong
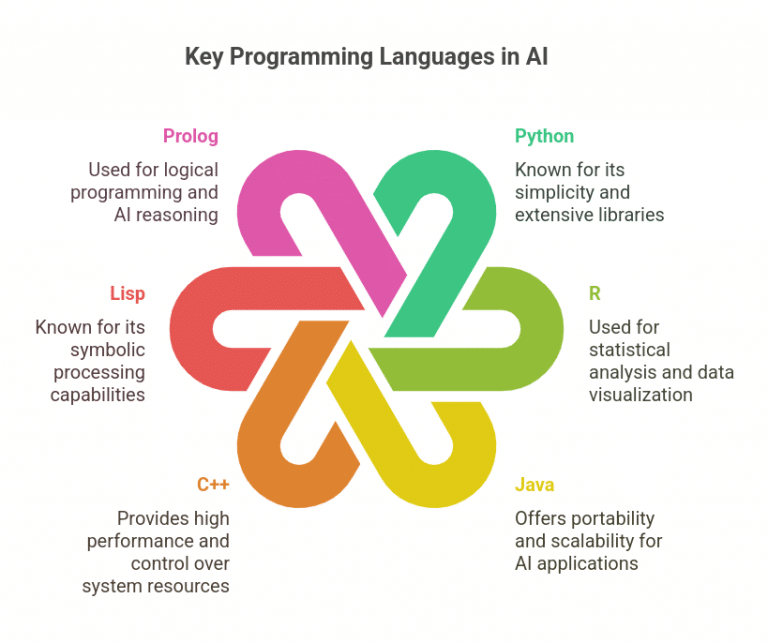
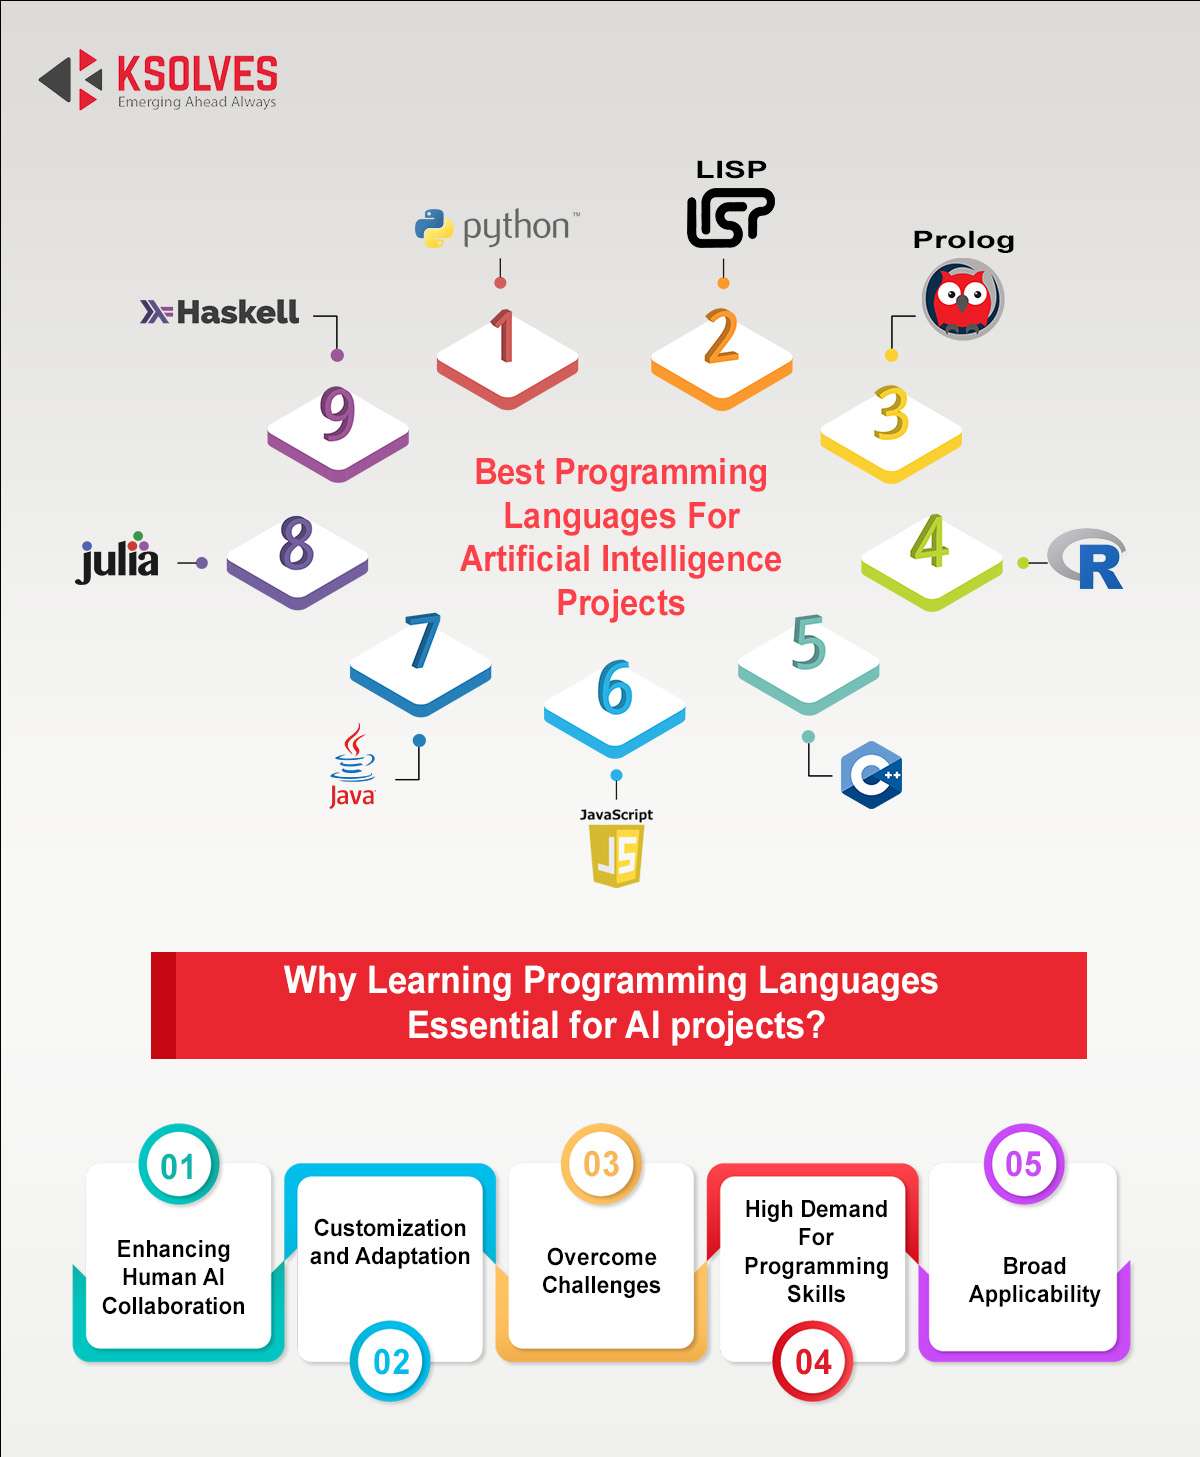
I spent about two years working with various AI programming frameworks before realizing that the language itself isn't really the bottleneck. The bottleneck is understanding what the models can and can't do in practice. Most beginners treat it like a normal programming task where you write code and it compiles. That mental model is exactly why projects fail. It's not a single language. Python dominates because of its ecosystem - TensorFlow, PyTorch, Hugging Face transformers, LangChain. But the actual programming involves multiple components: prompt engineering, API integration, data preprocessing pipelines, evaluation frameworks, and deployment infrastructure. When someone says they're building in an AI programming language, they usually mean they're writing Python scripts that call models through APIs or run inference locally. The confusing part is that the "programming" has shifted from deterministic logic to probabilistic behavior. You can write perfect code and still get garbage output because the model hallucinated. That's a fundamental difference from traditional software development that most tutorials don't emphasize early enough.
I remember running a production pipeline for a legal document review system using GPT-4 through the API. The prompts worked flawlessly in staging - we got clean, structured JSON outputs with 94% accuracy on our test set. Then we deployed it and the model started returning truncated responses that violated our schema. The issue wasn't the prompt. It was context window fragmentation. When documents exceeded 8,000 tokens after tokenization overhead, the model would silently drop the middle section and generate from whatever remained. The fix was implementing a chunking strategy with overlap windows and using a summary-pass approach where I'd extract key entities from each chunk before the final synthesis call. That added maybe 40% more API cost but eliminated the schema violations entirely.
Setting Up Your First Environment
Start with Python 3.10 or 3.11. Don't use 3.12 yet if you're relying on certain ML libraries - support is improving but you'll hit incompatibilities. Create a virtual environment immediately. I'd recommend uv instead of pip for dependency resolution if you're starting fresh, it's significantly faster. Install these as a baseline: torch (CPU version is fine to start), transformers, langchain, langchain-community, openai, python-dotenv, pandas, and pytest. That covers about 80% of beginner projects. For local model inference, add ollama and run it locally - it handles the downloading and serving of models like Llama 3, Mistral, and Qwen without you managing CUDA setups manually.
Get the Full Details
How Prompt Engineering Actually Works
Prompt engineering isn't about finding magical phrases. It's about structuring information so the model has the context it needs to retrieve the right patterns from its training data. The single most impactful thing you can do is provide few-shot examples. Two or three complete input-output pairs in your prompt typically improves structured output consistency by 30-50% compared to zero-shot prompts, regardless of which model you're using. Chain-of-thought prompting works but has a real cost. Asking models to "think step by step" increases token usage by roughly 3x and adds latency. For simple classification tasks it's overkill. For mathematical reasoning or multi-step logic, it's often necessary. The tradeoff is real. You should benchmark both approaches on your specific task before committing to one. One thing nobody tells you: temperature settings matter less than you'd expect for most applications. Setting temperature to 0.2 versus 0.7 rarely changes the structural quality of outputs. What actually changes the output diversity is top_p and frequency penalty. I've seen people spend hours tuning temperature while the real issue was their frequency penalty was set to 0, causing the model to repeat entire paragraphs in long-form generation tasks.
Data Pipeline Realities
You can't skip this section. Every project I've seen fail did so because of poor data handling, not because of bad prompts or wrong model choices. You need to clean, normalize, and structure your input data before it ever reaches a model. Garbage in, expensive garbage out. Use pandas for tabular preprocessing and keep your pipelines modular. I write every data transformation as a separate function that takes a DataFrame and returns a DataFrame. This makes testing trivial and lets you swap preprocessing steps without touching the model integration code. If your preprocessing is a single 400-line function, you will regret that decision by iteration three. Token counting is another thing that bites people. Your text isn't going through character count. The OpenAI tokenizer splits text differently than gRPC or REST boundaries. A sentence that looks like 100 characters might be 140 tokens. Budget accordingly. I use tiktoken to count tokens during development rather than guessing, and it saves you from unexpected billing shocks.
Evaluation Beyond Accuracy
Accuracy is a misleading metric for AI projects. You need to measure hallucination rate, response latency, format compliance, and cost per query. A model might be 97% accurate but hallucinate critical facts in the 3% of cases that matter most. I track hallucinations separately by having a secondary model or rule-based validator check outputs against source documents. It adds cost but catches the failure modes that silently degrade user trust. Late binding is a concept worth understanding. Don't hardcode model names or versions into your application logic. Use configuration files and dependency injection. When you need to swap from GPT-4o to Claude 3.5 Sonnet for cost reasons, or when a newer model beats your current one on benchmark tests, you should be able to change a config value rather than refactor code.
When AI Programming Isn't the Answer
Rule-based systems, regular expressions, and traditional databases solve a lot of problems that people try to force into AI pipelines. I've seen teams build expensive RAG systems for questions that could have been answered with a proper search index and Elasticsearch. AI should be the last resort, not the first tool you reach for. If your problem involves strict logic, fixed schemas, or deterministic outcomes, don't use a probabilistic model. The cost per query will be 100 to 1000 times higher than a database lookup, and the results will be less reliable. Reserve AI for tasks that require natural language understanding, pattern recognition in unstructured data, or creative generation. Everything else is usually overkill.
Common Pitfalls
Model drift is real but different from what traditional ML engineers expect. Your fine-tuned model doesn't degrade because your training data becomes stale. It degrades because the base model's capabilities change when providers update it. The API you called last month may return qualitatively different results today even with identical prompts. Version your prompt configurations and test against a regression suite before deploying any infrastructure change. Another issue is silent context truncation. Models don't always tell you when they've hit token limits. They just generate from what they have and the output degrades. Set your max_tokens explicitly, monitor completion ratios, and add logging for context length warnings. Your error tracking will thank you later. The biggest mistake I see is treating AI output as ground truth. It isn't. It's a statistically plausible continuation of your prompt based on patterns in training data. Build validation layers, implement human-in-the-loop checkpoints for high-stakes applications, and never fully automate decisions without an override mechanism. The technology moves fast but the fundamentals of reliable software engineering haven't changed.