Why We Keep Doing Assessments (And Why Most Of Them Are Worthless)
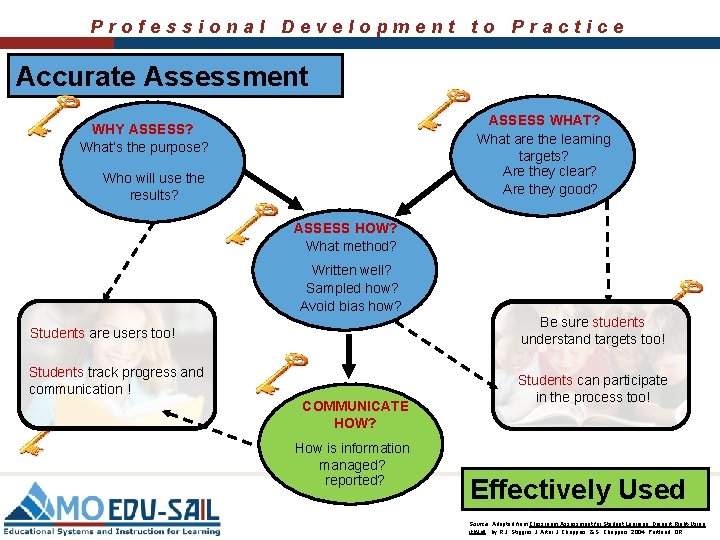
I have sat through too many post-mortem meetings where someone pulled up a four-page assessment document and we all just nodded along while knowing full well it had not predicted any of the problems that actually came up. The gap between what assessments claim to surface and what actually matters on the floor is a persistent annoyance in my work. I am not here to tell you assessments are useless, because they are not. But the people who get value out of them do it differently than the people who treat them as compliance checkboxes. The term gets bandied around a lot, usually by teams looking for some structured way to improve, and what it should actually mean is just this: use evaluations as input, not as verdicts. The moment you use an assessment to grade people rather than to stress-test assumptions, you are doing it wrong. That is the baseline. Everything else is tuning around that. In practice, I run assessments that cover three things: technical debt indicators, process friction points, and team capacity mismatch. The first one I handle by running static analysis and reading the PR history for the past ninety days. The second one I handle by asking people to log where their day got eaten for a single sprint. The third one I handle by comparing committed story points against actual carried-over work across the last three sprints. Those three data points, when you look at them together, tell you something that a generic rubric never will.
Here is the part most guides skip. The assessment itself is not the valuable thing. The follow-up is. I once worked with a team that did an assessment every two weeks for six months and never once changed their habits. Their scores got better on paper because they optimized for the scoring mechanism instead of the outcomes the scoring mechanism was supposed to represent. That is called Goodhart's Law, and it is the most expensive failure mode in this space. You will see it happen faster if your assessment has numeric scores attached to individual engineers. Never do that unless you want your team to game the numbers and lose trust in the process. The workflow I use is deliberately short and slightly uncomfortable. I pick one focus area per month. I collect data for a week. I spend thirty minutes mapping the data against a simple cause-effect diagram. I write three concrete changes. I implement two of them for four weeks. I reassess only that same focus area. The third change gets dropped or deferred. This keeps the loop tight enough that people stay engaged and loose enough that you are not drowning in documentation. I ran into a specific edge case last year that made me rethink how I handle codebase assessments. We were evaluating a legacy Python service that had no tests and a tangled dependency graph. The standard metrics—cyclomatic complexity, test coverage, static analysis warnings—produced noise rather than signal. The highest-complexity modules were actually fine because they were simple loops written poorly by the metric. The real problems were in two small utility files that imported seven different libraries each and had implicit coupling to the database layer. My workaround was to stop relying on complexity metrics entirely for that assessment and switch to a call-graph analysis instead. I used a dependency visualization tool to trace which functions were imported across multiple unrelated modules. That revealed the hidden coupling, and the remediation plan for those two files took a third of the effort compared to the original plan based on the complexity reports.
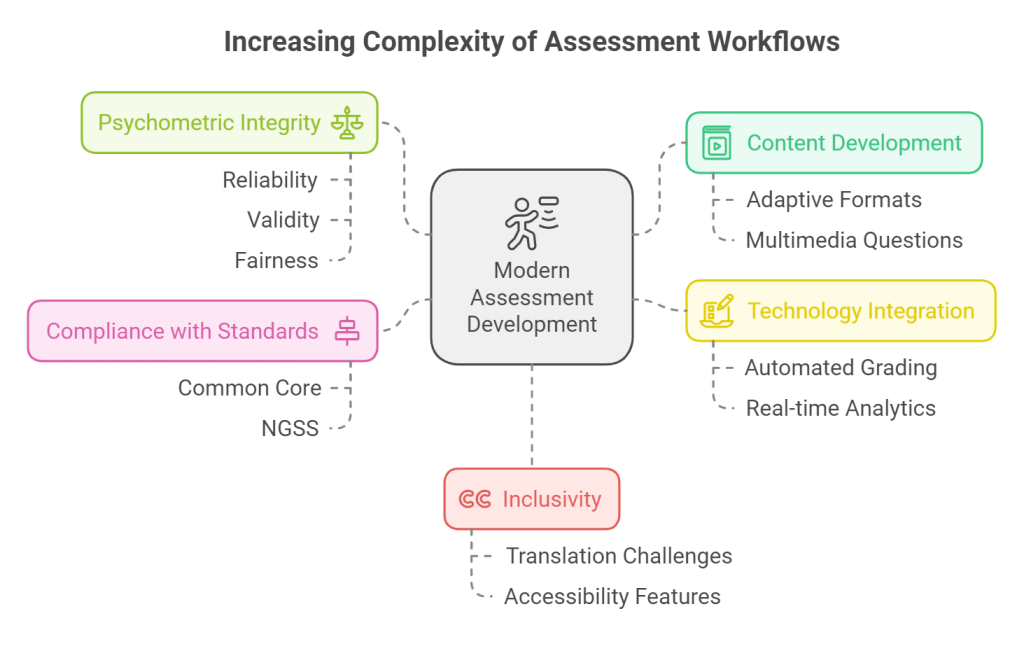
There are structural weaknesses to this approach that nobody likes to admit. Assessments bias toward what can be measured. Your most important problems are often the ones you cannot measure well, like team morale, context switching, or architectural drift that has not yet surfaced as bugs. You will never get a clean read on those from a scoring sheet. Another problem is time cost. A decent assessment cycle for a medium-sized project takes about twelve hours of engineering time spread across a couple of weeks. If your team is already underwater, you will either skip it or rush it, and rushed assessments are worse than no assessments because they give you false confidence. If you are on a tiny team with less than six engineers and a single product line, formal assessments are often overkill. You can get the same results by running a weekly fifteen-minute retro that asks two questions: what broke, and what almost broke. The data quality is lower, but the feedback loop is fast enough to catch problems before they compound. That alternative is worth more than a polished assessment deck produced annually. The tools matter less than the discipline. I have used basic spreadsheets, lightweight dashboards, and fully integrated project management platforms for this. The result depends on whether you actually act on what you find, not on which tool you use. One thing that helps significantly is making the raw data visible to everyone before you interpret it. When people can see the numbers themselves, they raise different observations than they would if you presented conclusions without the underlying evidence. That alone prevents about half the misreads I have seen over the years.
Get the Full Details
If you want to start, pick one recent failure or delay and run an assessment backward from it. Map what you know, what you guessed, and what you missed. The gaps between those three columns tell you what kind of assessment process you actually need, instead of what some template says you need. That exercise usually takes an afternoon and it will save you from building a process that looks good and does very little.