Why your regression keeps lying to you
I ran into this problem about three years ago on a project for a logistics company. They wanted to predict delivery times based on distance alone. The R-squared was 0.87, which looked incredible on paper. But when I checked the residuals, they formed a clear fan shape — variance grew with distance. The model was confident, and completely wrong for long-haul routes. That moment taught me that assumptions matter more than coefficients. Simple linear regression is one of the first techniques people learn in statistics, but it comes with baggage. If you skip the diagnostic checks, you are not doing statistics, you are doing theater. The assumptions are not decorative. They determine whether your estimates are trustworthy or just expensive noise.
What Are the Assumptions Of Simple Regression
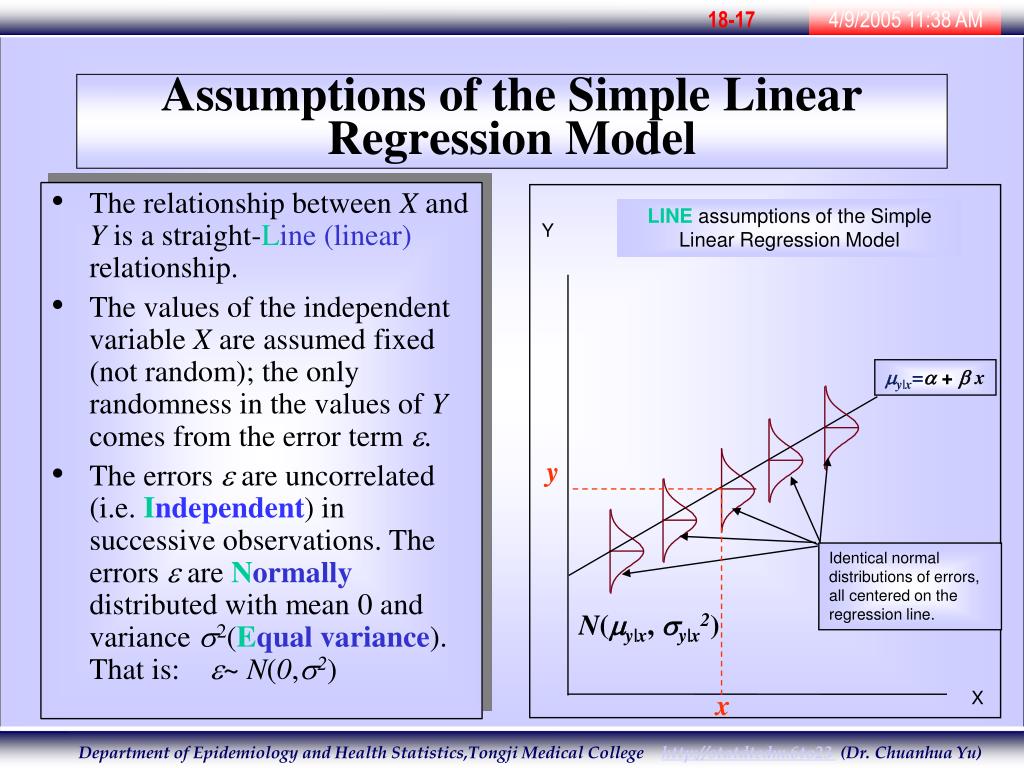
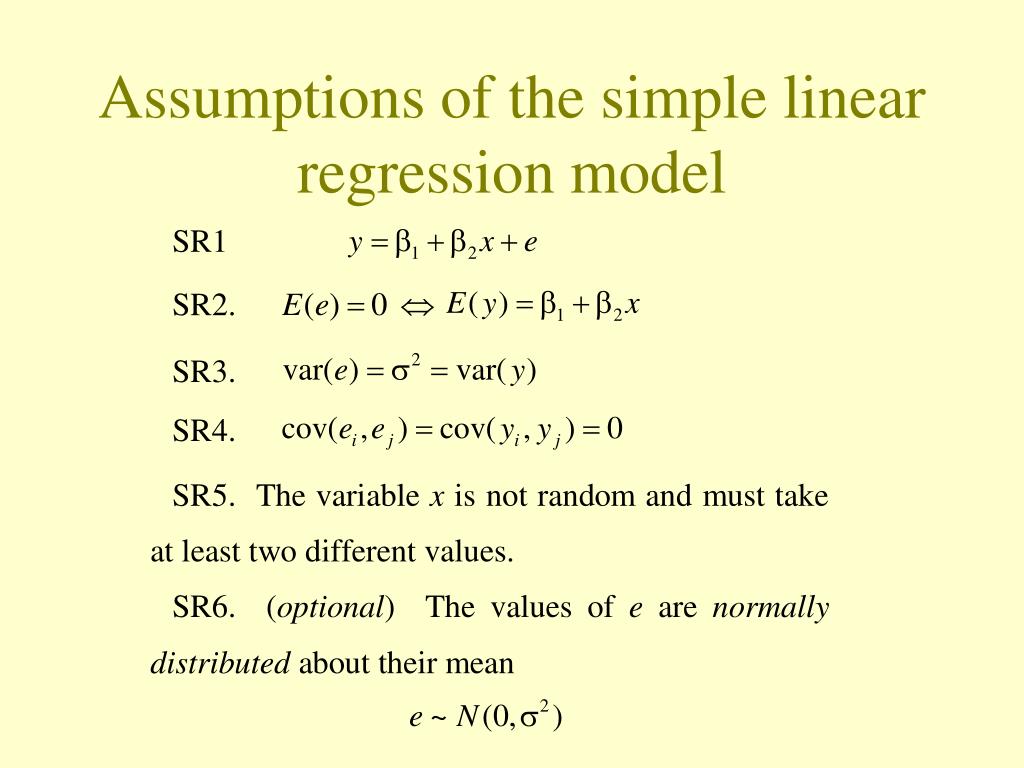
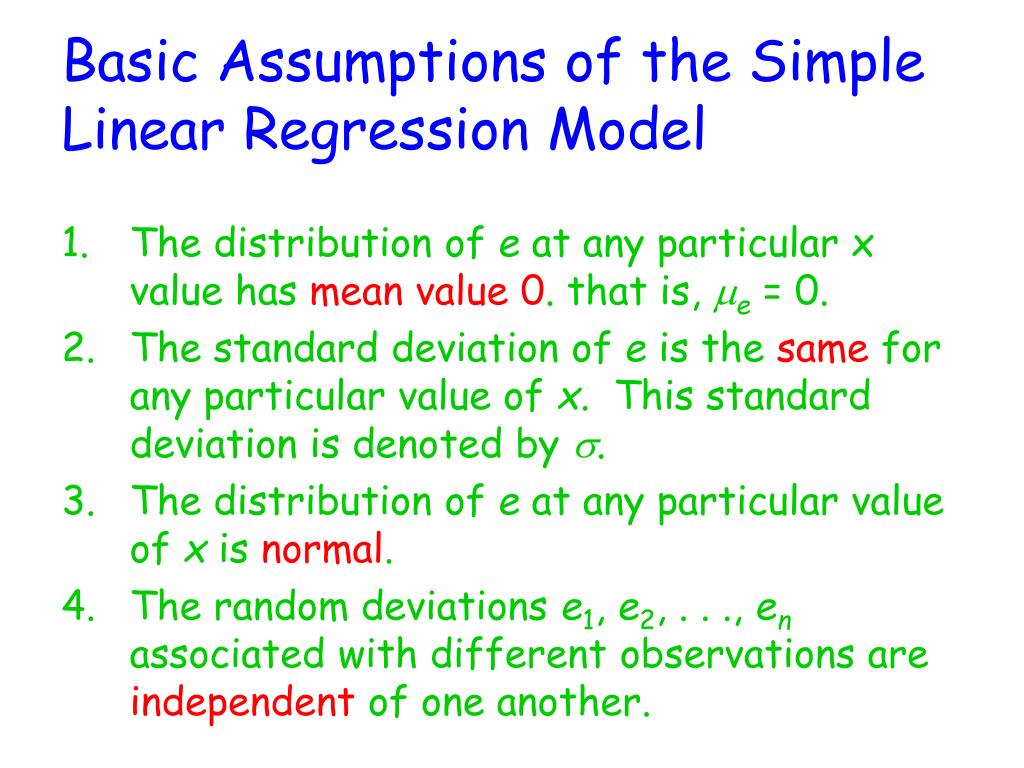
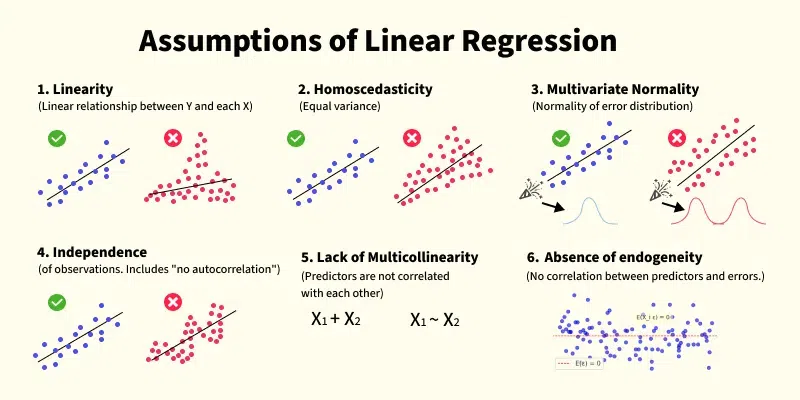
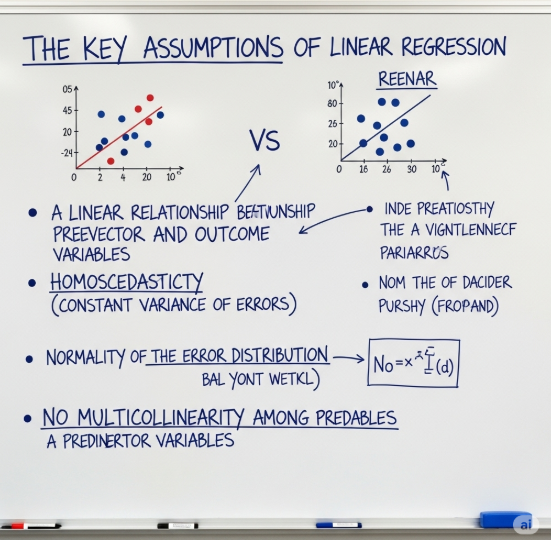
Before we go further, let me lay out the five core assumptions and explain why each one exists. Linear regression assumes that the relationship between your predictor and outcome is linear, that errors are normally distributed, that errors have constant variance, that errors are independent, and that your predictor is measured without error. Miss any one of these, and your confidence intervals become fiction. This is the most basic one. Your data should follow a straight line, not a curve. In practice, I have seen people force linear models onto relationships that are clearly exponential. The fix is usually a transformation. Logarithms help with exponential growth. Square roots work for Poisson-type counts. I once had a dataset where the relationship between advertising spend and sales was linear only up to a threshold, then flatlined. A piecewise linear model handled it better than any transformation. To check linearity, plot your residuals against your predictor. If you see a pattern, you have a problem. A scatterplot of the raw data helps too. Look for curvature. If the dots bend, your model is misspecified.
Normality of residuals
Your errors should follow a normal distribution. This matters most for confidence intervals and hypothesis tests. Without normality, your p-values are unreliable. The good news is that regression is fairly robust to moderate violations, especially with large samples sizes. The central limit theorem kicks in around n = 30, though some practitioners prefer n = 50 or higher for safety. To check this, use a Q-Q plot. If the points follow a straight diagonal line, you are good. If they curve at the ends, you have heavy tails or outliers. I remember working with income data once where the residuals were heavily right-skewed. A log transformation of the outcome variable fixed it almost immediately.
Get the Full Details

Homoscedasticity
This is the constant variance assumption. Your errors should have the same spread across all levels of your predictor. When variance changes, statisticians call it heteroscedasticity. The classic sign is a fan or funnel shape in the residual plot. This problem shows up constantly in economics and social science data, where larger values tend to have larger variance. When heteroscedasticity appears, your standard errors are biased, which means your t-tests and confidence intervals are wrong. The workaround is straightforward. Use robust standard errors, also called Huber-White or sandwich estimators. These adjust for changing variance without requiring you to transform your data. In R, the vcovHC() function from the clubSandwich package does this. In Python, statsmodels has cov_type='HC1' as an option. These usually take about two minutes to implement and save you from drawing wrong conclusions.
Independence of residuals
Each error should be independent of every other error. This assumption breaks down constantly with time series data, spatial data, or clustered observations. If your data points are correlated, your standard errors will be too small, and you will find spurious significance. The Durbin-Watson test checks for autocorrelation in time series. Values below 1.5 or above 2.5 usually signal a problem. I worked on a project involving patient recovery times in a hospital. Patients were grouped by doctor, and patients under the same doctor had similar outcomes. Ignoring this clustering gave me p-values that were far too optimistic. Switching to a mixed-effects model with a random intercept for doctor solved it. The process took about ten minutes in lme4 in R, compared to the hour I spent debugging why the standard regression kept giving false positives.
No measurement error in the predictor
This assumption is often ignored because it is hard to check. It says your X variable is measured perfectly, without error. In reality, most survey data and observational measurements contain noise. When your predictor has error, your slope coefficient gets attenuated toward zero. This is called attenuation bias, and it is one of the most common problems in applied research. The fix depends on your situation. If you have replicate measurements, you can estimate the reliability and correct the bias. Instruments like sem packages in R or lavaan handle this. If you do not have that luxury, you are stuck with a biased estimate. Being honest about it is better than pretending the result is precise.
When simple regression fails completely
Linear regression is not a universal tool. It fails badly with binary outcomes, count data with many zeros, or heavily censored data. If your outcome is yes or no, use logistic regression. If your outcome is a count, try Poisson or negative binomial regression. I have seen people run linear regression on percentage data bounded between zero and one, which produces impossible predictions outside that range. It looks simple, but it is fundamentally wrong. Another limitation is sensitivity to outliers. A single influential point can pull your regression line toward it and completely change your conclusions. Check for leverage and influence using Cook's distance. Points with values above 1 are suspicious. Values above 4/n are dangerous. Remove or investigate them, but never delete data just to make the model look better.
A practical workflow
Here is how I approach simple regression now, after years of making mistakes. First, I plot the data. Always. A scatterplot reveals problems that diagnostic tests miss. Second, I fit the model and check residuals immediately. Third, I run the diagnostic tests: Q-Q plot, scale-location plot, residuals versus fitted values. Fourth, I consider transformations or alternative models if assumptions are violated. Fifth, I report everything, including the failures. Reporting failures is important. If your residuals are non-normal, say so. If you used robust standard errors, explain why. Transparency builds trust with your audience and protects you from criticism. People respect honest analysis more than perfect results.
The bottom line
Assumptions Of Simple Regression are not suggestions. They are the foundation that makes your inference valid. Check them before you trust your results. Use diagnostics, not just intuition. Apply corrections when needed. And when the data simply does not fit a linear model, switch tools rather than forcing a square peg into a round hole. I still think about that logistics project sometimes. The model was wrong, but the diagnostic plots taught me more than any textbook ever did. That is the value of paying attention to assumptions. They reveal what the data is actually telling you.