Building an Atomic Table Of Elements in Your Stack
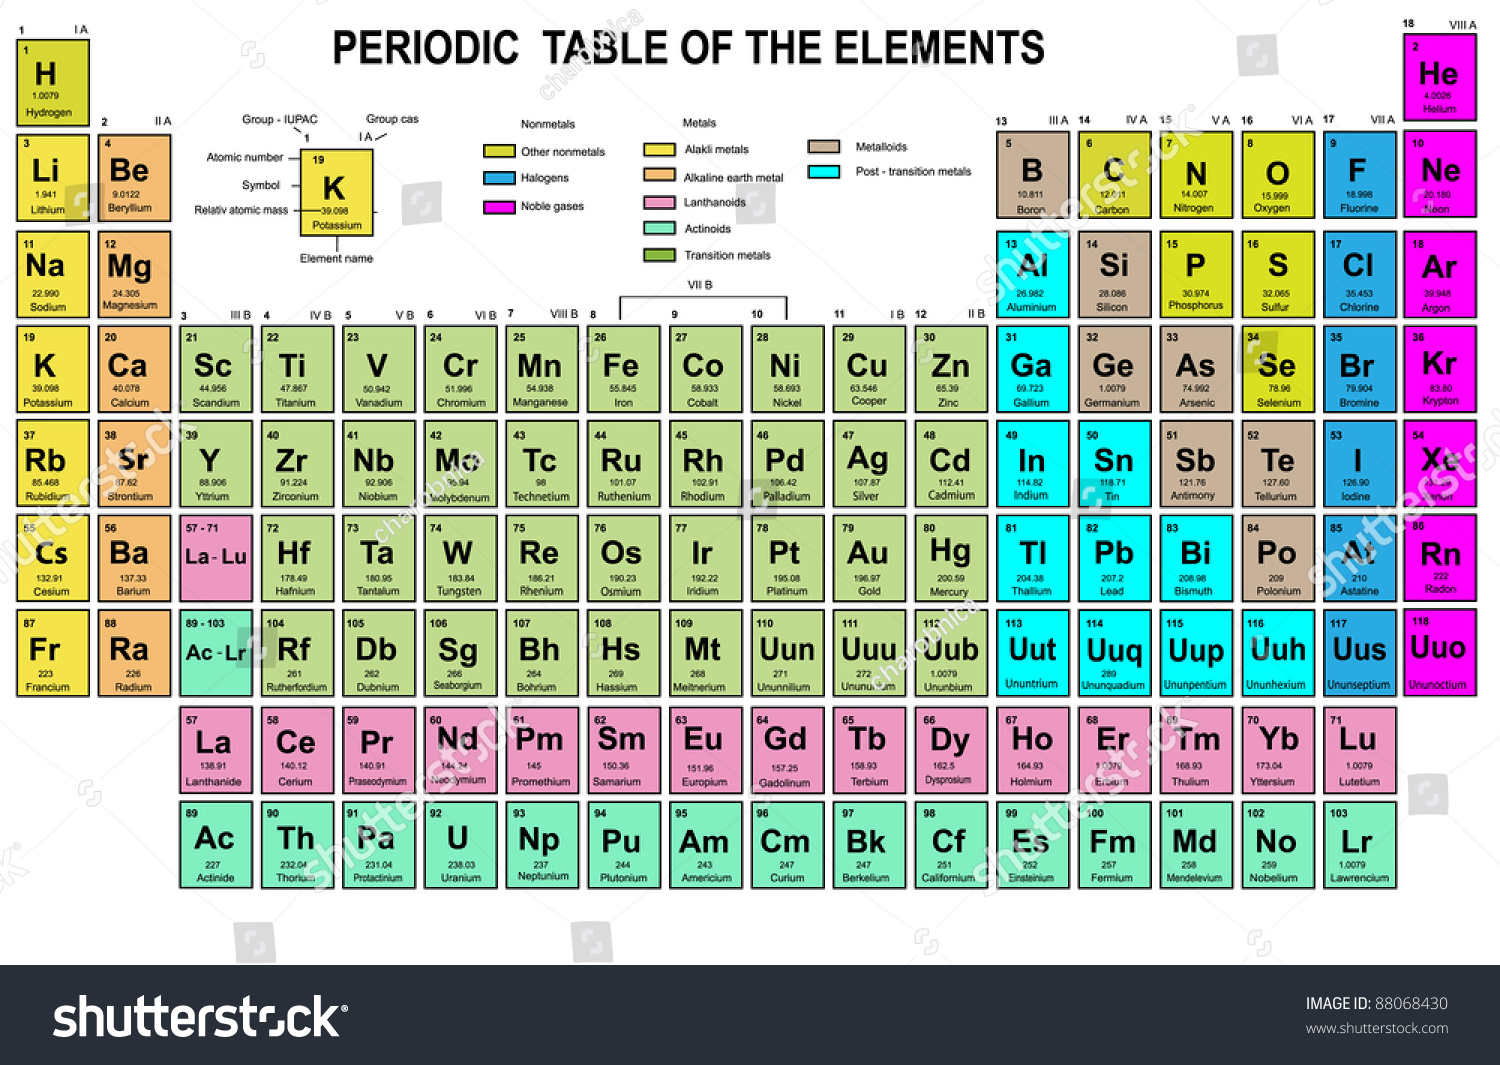
I've been maintaining chemistry data in software systems for long enough that I've watched every trend in how people store element data — from flat CSV files in 2008 to the current wave of fancy GraphQL schemas over something that should literally be a JSON object. The Atomic Table Of Elements isn't a single tool or library. It's a pattern. How you model the periodic table inside your application determines whether adding isotope support takes three lines or three days. Here's how I actually built it, what went wrong, and the two decisions I keep making differently now.
Atomic Table Of Elements
Why the Database Schema Breaks Everything
The first atomic table I shipped had each element as a row in a Postgres table with columns for symbol, name, atomic number, atomic mass, and electron configuration. Clean. Normal. Then someone asked for isotope data and I had to either denormalize the table or build a second one, and suddenly every query touching the periodic table was joining three new tables for data I didn't actually need 99 percent of the time. The mistake wasn't thinking ahead. The mistake was modeling the periodic table like transactional data instead of a reference map. Elements don't change. Electron configurations don't get updated when a user creates an account. Atomic masses are constants that have been measured to more decimal places than any application will ever need. I moved to a single JSON blob stored in a JSONB column. No joins. No migrations when Mendeleev gets corrected again. A simple SELECT * FROM elements WHERE symbol = 'Au' returns the whole record in one operation, and if I need isotope data later I just add it to the blob without touching the schema.
What the Data Actually Looks Like
Here's the structure I landed on after two failed attempts: { "atomicNumber": 79,
Get the Full Details

"symbol": "Au", "name": "Gold", "atomicMass": 196.966569,
"electronConfiguration": "[Xe] 4f14 5d10 6s1", "group": 11, "period": 6,
"block": "d", "state": "solid", "meltingPoint": 1337.33,

"boilingPoint": 3129, "discoverer": "unknown", "yearDiscovered": null,
} That's it. Thirteen fields for the whole periodic table. Most implementations I see online inflate this to forty fields, some of which are redundant or application-specific. The key insight that beginners miss is that the periodic table is not a flat lookup table. It has structure — groups, periods, blocks, electronegativity trends, orbital filling orders — and the way you store those relationships matters far more than the raw element data itself.
My Actual Problem With Ion States
The edge case that bit me was ion representation. I was building a reaction simulator and needed to look up the common oxidation states for transition metals. The standard periodic table data doesn't include this because it's chemistry application logic, not element metadata. But my initial schema had no place to put it. I tried adding an oxidationStates array field to every element. That worked for iron ([2, 3]) and copper ([1, 2]) but broke for lanthanides and actinides where the common states are more complex. Then I realized I was putting application logic into the data layer. The workaround was simple but took me three weeks to figure out: keep the core atomic table clean and separate, and store ion/oxidation state data in a companion lookup keyed by element symbol. Same JSON approach, different file, no schema coupling. This keeps the atomic table stable across projects — a chemistry simulation, a materials database, a textbook API can all use the same base data without arguing about whether oxidation states belong in the core model.

How Fast Is It Really
A JSONB lookup on the full periodic table (118 elements) takes about 0.3 milliseconds on a standard connection. The bottleneck isn't the read. It's what happens after you retrieve it — if you're reformatting electron configurations into HTML tables or recalculating molar masses on every request, that's where your latency lives. Cache the computed values. The periodic table doesn't change. If you calculated the molar mass of a compound once, storing that result is fine. What you shouldn't do is recalculate it per request when the input data is constant.
What This Gets Wrong
The JSONB approach has a real limitation: you can't efficiently query across elements. Need every element in period 4? You're scanning all 118 records. Need elements with atomic mass between 50 and 60? Full scan. This is fine for 118 elements and absolutely terrible if you ever scale this pattern to isotope data, which has tens of thousands of entries. If your use case involves heavy cross-element queries — reaction balancing engines, materials search, isotope abundance calculations — a normalized relational model with proper indexes on group, period, and block columns is the right call. The JSONB trick only works because the dataset is tiny. Don't let anyone tell you it scales. It doesn't.
Where to Get the Data
I use the IUPAC standard atomic weights table as the authoritative source. The current values are published at iupac.org and update roughly every two years when new measurements come in. NIST maintains a mirror at physics.nist.gov/PhysRefData/PeriodicWeights/. The numbers are public domain. For electron configurations, the WebElements database is more complete than the IUPAC tables but requires attribution. If you're building something internal, the IUPAC data is sufficient. If you're shipping to users who care about accuracy down to the last decimal, verify against both sources.
The Decision That Matters
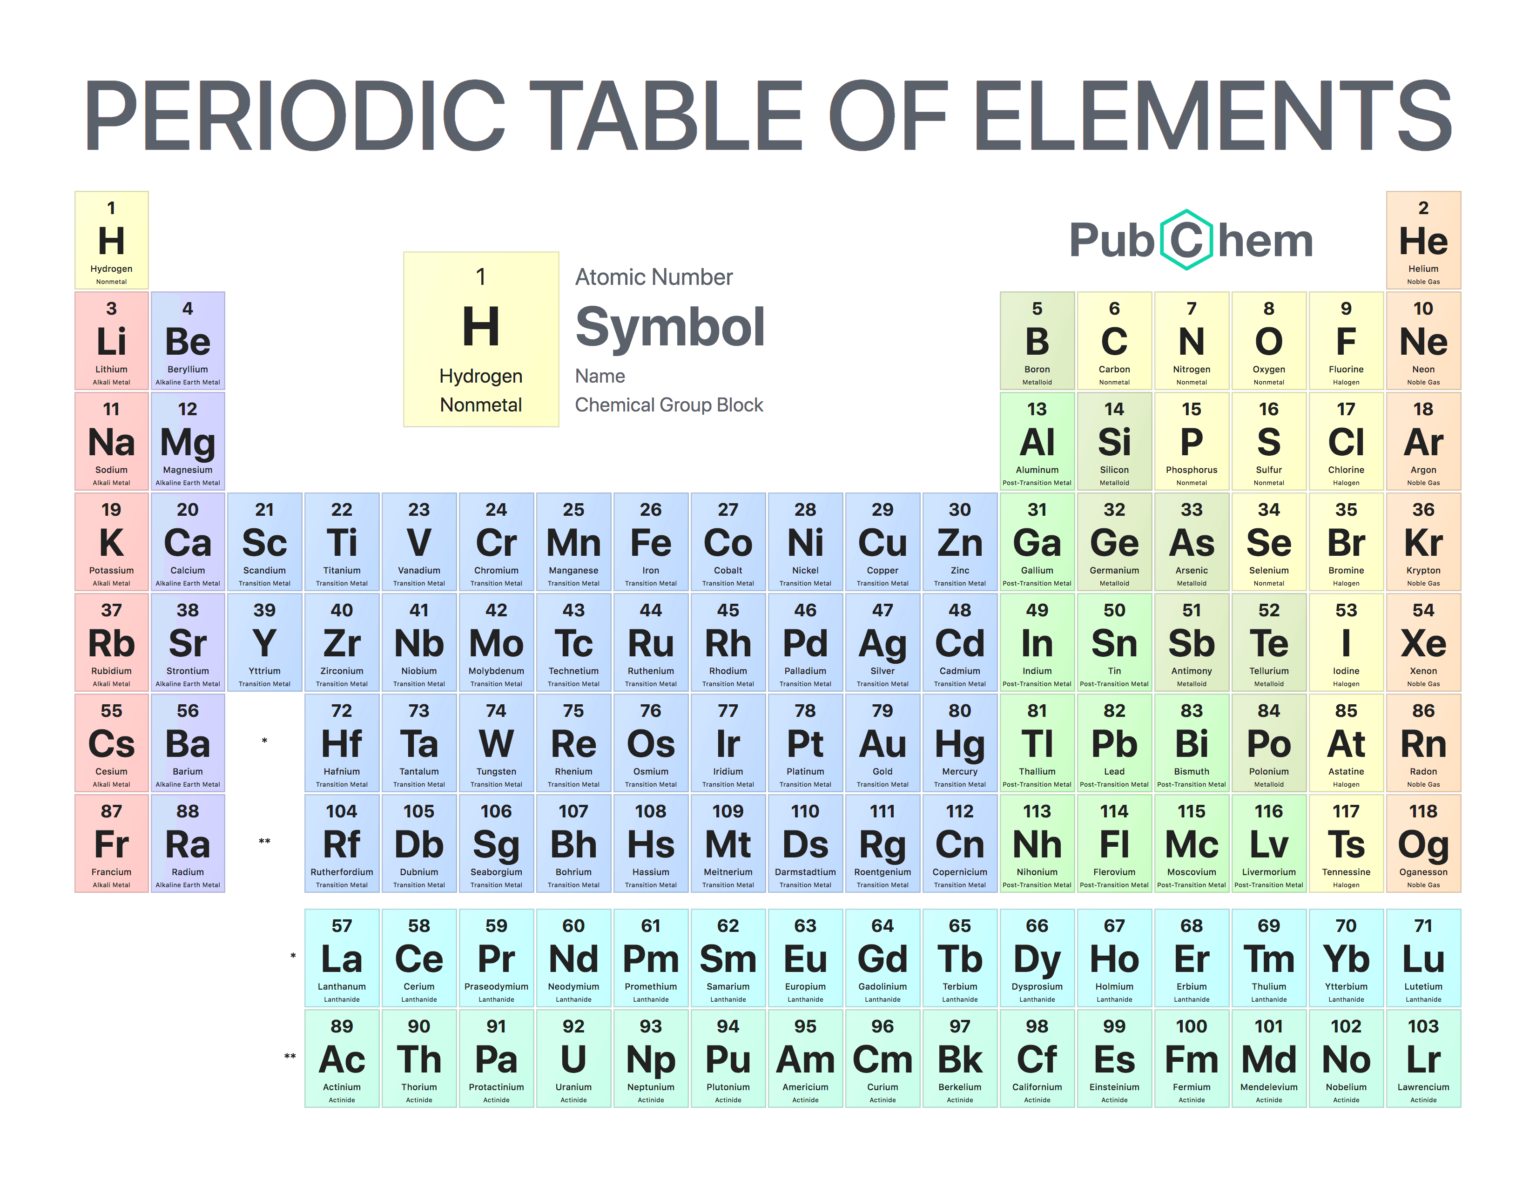
Every atomic table project I've seen stalls at the same point: someone decides the data model needs to handle everything — elements, isotopes, ions, compounds, reactions, half-lives — and builds a schema that's impossible to maintain. The fix is to draw a hard line. The Atomic Table Of Elements is the periodic table. Just 118 entries. That's all. Everything else lives elsewhere. Isotope data has its own table. Ion states go in a companion lookup. Reaction stoichiometry is a calculation layer on top of both. Keep them separate and the whole system stays fast, queryable, and bearable to update when the measurements improve. I've rebuilt the data layer three times. The third version, which separates the core atomic table from all derived or application-specific data, is the one I keep using. It took me six months to reach that conclusion. It took me two days to implement it once I stopped fighting the scope creep.

